Tag: sql server

  • Risk Analysis

    I saw a post recently that talked about disaster recovery being an important part of your company’s systems and that you needed to be sure that you could recover everything in the event of a disaster. That’s a common perception we all have, but I noticed that another person had replied that we shouldn’t necessarily make DR a huge priority. Our DR spending ought to be inline with the risk of a disaster, and the actual costs, or losses, resulting from downtime.

    The decision on what to spend for DR can be answered by the classic DBA response, “it depends,” but I thought this Friday I might ask anyway.

    What do you spend on DR?

    I am asking as a percentage of your budget, or even the cost of running your large systems. Do you know what is spent? Do you know how to find out?

    I’m curious how involved many of you are in the DR process? Do you consider it a part of the application development? Do you think about the failure when the system is being put together and ensure that the setup or rebuild is easier in the future?

    This is an area that I think many companies ignore and count on things going their way. That’s not a great strategy, but it works for many companies. Most of us never have major disasters, and can usually fumble through small ones.

    I think that over time there will be less tolerance for the bumbling, keystone cops efforts of most IT shops. Our systems are  more integrated into businesses and there’s less possibility of even rolling back to non-computerizes systems in many cases.

    Thinking about DR earlier, and making the investment to ensure some level of DR is in place is the sign of a more mature business. And a more mature IT professional.

    Steve Jones
  • Are There That Many GUIDs?

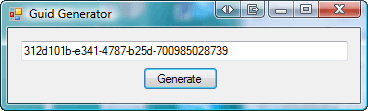
    Do a lot of people actually use GUIDs as Primary Keys? I haven’t used them much, and I would have thought that more people chose identity keys. It seems that most of the demos and examples I see from bloggers and speakers are constantly using identities.

    However an informal survey from Peter Bromberg showed that four times as many people actually had GUIDs as their primary keys. The blog actually says that GUIDs are not a good choice, but I’m not sure I agree with that. You can use sequential GUIDs, and you can avoid making them the clustered key, so I think they can work as well as anything.

    There’s nothing inherently wrong with GUIDs, and they should be unique across all of your rows. There have been some reported cases of duplicates, but for most practical purposes, especially in database work, you ought to be able to count on a GUID as unique. They even have the nice capability of being generated by clients, removing the need for an extra round trip when a client needs to insert multiple rows.

    I typically don’t use them because they’re long, hard to remember and type, and hard to view on the screen. I can’t easily compare rows in multiple tables, and it’s easier for me to work with integers.  I don’t recommend them, but if you are going to use them, be sure you understand the pros and cons, and use them appropriately.

    Steve Jones

  • Downtime

    Someone sent me a note recently asking about how to handle unexpected downtime. In an editorial I mentioned that a 7TB database isn’t that large, and this person told me that they had an issue with a 1TB database and running DBCC resulted in a 4 hours of unexpected downtime. The person asked if small businesses needed to accept downtime for serious maintenance.

    I think that it’s rare you run into DBCC issues that require downtime, but when you do, then that downtime is needed. I’m not sure what else you can do since DBCC repair issues often indicate some fundamental hardware issue. I suppose that you could move to new hardware, but you still need to ensure that your database is intact and working.

    A restore from backup might be quicker in these situations, but that will requires some downtime, and it’s something that you have to live with. We still have systems that will fail and need rebuilding, and probably always will.

    I know some companies can afford redundant hardware and failover to secondary systems when they need to check their primary servers. A second copy of the database may or may not allow you to continue to function if you had corrupt pages on your primary, depending on how the data is moved over.

    Most of us, however, just have to live with downtime. If anyone has other ideas or stories on dealing with unexpected maintenance downtime, I would be interested in hearing them in the discussion below.

    Steve Jones

  • Are there that many GUIDs?

    Do a lot of people actually use GUIDs as Primary Keys? I haven’t used them much, and I would have thought that more people chose identity keys. It seems that most of the demos and examples I see from bloggers and speakers are constantly using identities.

    However an informal survey from Peter Bromberg showed that four times as many people actually had GUIDs as their primary keys. The blog actually says that GUIDs are not a good choice, but I’m not sure I agree with that. You can use sequential GUIDs, and you can avoid making them the clustered key, so I think they can work as well as anything.

    There’s nothing inherently wrong with GUIDs, and they should be unique across all of your rows. There have been some reported cases of duplicates, but for most practical purposes, especially in database work, you ought to be able to count on a GUID as unique. They even have the nice capability of being generated by clients, removing the need for an extra round trip when a client needs to insert multiple rows.

    I typically don’t use them because they’re long, hard to remember and type, and hard to view on the screen. I can’t easily compare rows in multiple tables, and it’s easier for me to work with integers.  I don’t recommend them, but if you are going to use them, be sure you understand the pros and cons, and use them appropriately.

    Steve Jones