Tag: SQLNewBlogger

  • Moving One File Across Git Branches: #SQLNewBlogger

    I was working on some branching and merging with a customer and they wanted to move a file from one branch to another without taking the entire commit. I had to dig in a bit and see how to cherry pick a file, and not a commit. This post looks at how this can work.

    I’ll do this in the git CLI. I’m sure it works in many clients, but when I do something strange or new, I like looking at the CLI. Mostly because when I make a mistake, the clients send me to the CLI often anyway, so I get comfortable there.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers. You can see all posts on Git as well.

    A Simple Setup

    First, grab a repo. In this case, I had a branching/merging repo I use with customers to show some things. I’ll use the repo at: https://github.com/way0utwest/BranchMerge

    For me, I have a main branch, as well as a dev and qa branches. There are likely some feature ones as well.

    To start with, let’s check main. Everything is up to date (I pulled already):

    2024- 08_ 0059

    Let’s also check QA. Same thing.

    2024- 08_ 0060

    I’ll now make some changes on QA, adding a file and changing two others. Once I do this, here is my status, pre-commit.

    2024- 08_ 0061

    If I don’t commit, these files don’t exist, and I could change branches and add them there. However, once I commit, I might want to move them in a certain way. I’ll commit and my status is clean.

    2024- 08_ 0062

    Now, I could switch to main and do this to move one file:

    git checkout qa -- README.md

    However, I’m just doing that without review. So, I wouldn’t do that and you shouldn’t either. Instead, let’s create a PR.

    Using a Branch for Peer Review

    A PR is a pull request, but it also means we ask for some peer review. In my case, I’ll use this code to create a new branch and then pull in two changes: my modified readme and one of the other changes.

    git checkout -b r9-qa

    git checkout qa -- README.md

    git checkout qa -- "V6__create proc gettwo.sql"

    Ignore my typos, but I’ve run 4 commands: checkout 3 times and status once.

    2024- 08_ 0063

    Now I’ll commit and push these changes to my r9-qa branch.

    2024- 08_ 0064

    Once I do that, Github detects a push and asks me to create PR. I do, and I see the PR with these changes.

    2024- 08_ 0065

    Now I can proceed with my flow, and my cherry picked changes are captured.

    There is a git cherrypick command, but often I find I need random files from multiple commits, while ignoring others in the commit. This works well for database releases.

    A few references:

    SQL New Blogger

    This post took my about 20 minutes to write. However the learning and experimentation took over an hour as I read various links and dug into the docs and various posts.

    This is a very useful skill, and one you can discuss in an interview. Write a similar post and you’ll be prepared for this type of question in an interview.

  • Deleting Old Local Git Branches–#SQLNewBlogger

    I had a lot of local branches for a repo (actually a few repos). I know these are old and not used anymore, so how do I delete them? This post shows how to do that on Windows.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers. You can see all posts on Git as well.

    The Problem

    As I’ve been making changes for various SQL Saturday events

    I saw this SO post, which was a good starting point. I grabbed this code, which I’ll explain below.

    git fetch -p && git branch -vv | awk '/: gone]/{print $1}' | xargs git branch -d

    The problem is this doesn’t work on Windows.

    2024-06-23 10_24_52-cmd

    Running This on Windows

    I assume most of you installed Git and have Git Bash. The xargs and awk commands are Unix/Linux ones, so you need a bask shell to tun them

    The solution for me, was to open a bash shell in the repo with the right click menu on Windows.

    2024-06-23 10_33_35-sqlsatwebsite

    Then run the code:

    2024-06-23 10_24_44-MINGW64__e_Documents_git_sqlsatwebsite

    Local branches removed. Well, almost; read the next section.

    Additions

    Note that in the first execution, I had two errors noting that there were some unmerged branches. When I look at these, I see they were old branches, ones that haven’t been used in years. I’m guessing either I was fixing something for someone, or they fixed something in another branch.

    So, I forced delete by re-running the command a capital D.

    How this Works

    This code uses some Unix based utilities that I haven’t used in a long time. The flow of this is similar to how PowerShell, or even VBScript works, but on a single line. In this case, this code:

    • Gets a list of branches from the remote with git fetch after pruning the references for local branches that don’t exist on te remote.
    • Run the branch command with the verbose output. Could be –verbose as well
    • Take the output if the previous step and pipe that through awk. This command will parse text, looking for “gone” in a line and then printing the branch name.
    • This text is then taking with xargs and passing it to the git branch command with the delete option.

    Note this doesn’t force delete branches.

    SQL New Blogger

    This post took about 20 minutes to write. I spent about 5 minutes checking a few code examples online, and then tried one after I’d killed branches from GitHub. I don’t have a great solution there, but I don’t do this often and I can click a few buttons to manage this.

    I then structured this post with a few screenshots and spent 15 minutes working on it. I’d actually sketched it in 5 minutes with the major sections and a sentence in each and realized this would be quick to write, so I just filled it in on a Sunday morning.

    You could do this as well and give an interviewer something to ask you in the next interview. This might catch their eye. I’d also suggest (and I will) do a few posts on awk and xargs. Those are good skills to have and you might spent 20 minutes experimenting and having fun with them.

  • Resetting Git and Abandoning Changes–#SQLNewBlogger

    I recently had an issue in one of my Git repos, and decided to drop all my local changes and just pull down from the remote. This post looks at what I did.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers. You can see all posts on Git as well.

    A Bad State

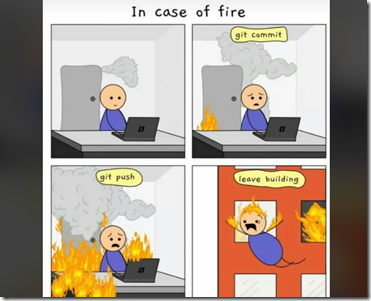
    The old cartoon looks like this:

    2024-06-17 16_35_56-Never forget _ r_git

    In my case, I hadn’t done this. I didn’t have a fire, but I did leave the building.

    Actually, what I’d done was made a few changes at home and hadn’t committed them. I was in between trips and in a hurry, and walked away. On the road, I made similar changes and did commit/push them. When I got home, I couldn’t git pull because of the conflict.

    What’s worse, these were binary (Excel) files.

    I could have tried to sort things out, but in this case, I knew the remote copy was likely more up to date in place and I could easily re-enter the data I’d saved but not committed.

    The way to do this for me, for tracked changes, was git reset.

    In my case, I wasn’t trying to reset to a particular commit, I just wanted to whack all changes I’d made. This was just one file for me, so I issued:

    git reset -–hard

    The -–hard discards changes to any tracked files. Changes to untracked files aren’t affected. I’ll write about that in another post.

    This cleaned my local repo back to the last time I’d had a git pull. From here, I could just get changes from the remote and work on.

    SQL New Blogger

    This post took about 5 minutes, literally, to write. Some of that is I’m a good typist, some is this is a simple story. Any tech pro ought to be able to do this in 5 minutes as well. If not, learn to type or to structure a short story.

    This shows a little tech knowledge, but also an explanation of a situation.

  • Writing Parquet Files – #SQLNewBlogger

    Recently I’ve been looking at archiving some data at SQL Saturday, possibly querying it, and perhaps building a data warehouse of sorts. The modern view of data warehousing seems to be built on using a Lakehouse architecture where data moves through different phases, but much of the data is stored in text files, often parquet files.

    As a start to this I decided to try and move data to parquet. This post looks at writing parquet files.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    Writing Parquet Files

    In a previous post I looked at reading in JSON data, which is how some of my data is archived. I also talked about importing modules. There is a module, called pyarrow, that allows me to work with various parts of Apache Arrow.

    One of the submodules in pyarrow is the parquet module, which lets me read and write parquet files. So, let’s get those modules.

    import pyarrow as pa
    import pyarrow.parquet as pq

    I am giving these show names so I can refer to them in code. Now, let’s skip the code from the previous article and assume I’ve got a dataframe with my sessions in it. How do I get a parquet file?

    Fortunately, I don’t need to know anything about the physical structure, as I can use the write_table() function from the parquet module to do that. I’ll also use the pyarrow.Table.from_pandas() function to get data from the dataframe into this module. This code does that (with some setup for a filename).

        outputFilename = f + '.parquet'
        outputFile = join(outPath, outputFilename)
        pqtable = pa.Table.from_pandas(df)
    # Write Arrow Table to Parquet file
        pq.write_table(pqtable, outputFile)

    Note: I don’t know the technical differences between how pandas dataframes and the pyarrow tables work. I found a few notes online and it looks like pyarrow tables can handle more complex data structures.

    Once this code is added to the code from the previous article (it’s already indented), this will write .parquet files to the bronze folder underneath the location from where it is run. In essence, this takes data from the raw folder and writes it to bronze in a new format.

    Summary

    This post shows how to write parquet files out from JSON data. Take the previous article and this one and you can move data from JSON to parquet.

    This code isn’t perfect. In fact, it needs work. I am only moving session data, so only a portion of the JSON data. This code should be enhanced, or the file names changed to reflect that, but for now, this is a quick example of producing parquet data.

    SQL New Blogger

    This post took about 10 minutes to write once I had the code working. In fact, adding these functions to the code from the last article only took a few minutes. I had to debug a few things to get the files into the correct folder, but it took longer to get these words down than get code working.

    Not a lot longer, but longer.

    You can do this. If you want to work in modern technologies, learn them. Learn how to work with parquet, which is being used a lot in data warehousing, and then write about it. Prove you can get things done and your current employer, or your next one, might give you a project to actually do this work.