Tag: SQLNewBlogger

  • Reading JSON Data with Python

    Recently I’ve been looking at archiving some data at SQL Saturday. As a start, I needed to read some of the archive data I have in Python. This post looks at the basics of reading in JSON data in Python, one of the more versatile languages for working with data.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    Reading JSON Files in Python

    I have some data in the SQL Saturday repo in JSON format. This is schedule information, which is exported from Sessionize. I also have XML data, but I decided not to mess with that for now.

    Getting this data into a dataset is actually easy in Python. Here are the basics. First, we need to import a few modules. In Python, lots of functionality is from various modules, which aren’t available until added to your workspace. However, they are easy to import.

    We need a few modules:

    • json – used to work with json data
    • os – used to work with files and call OS functions.
    • pandas – used for creating dataframes
    • chardet – functions to detect encoding

    I’ll import these, though from os I’ll only get a few things.

    # Basic import of a JSON file

    import json
    import chardet
    import pandas as pd
    import os

    Once I’ve done this, I can use these modules in my code.

    Now for the code. The first thing is to find my files. I’ve stored json files in a “raw” folder, which I assume is below the place where I’m running the code. In this case, I have two files.

    2024-05-06 14_11_40

    Here’s a little setup code that sets the path (which could be an argument to the file), but creates a path to the files and starts a loop:

    mypath = '.\\raw'
    onlyfiles = [f for f in os.listdir(mypath) if os.path.isfile(os.path.join(mypath, f)) and f.endswith('.json') ]
    # loop through the files
    for f in onlyfiles:

    In Python, once I want to create a set of code in a loop, I need to indent it, so the next few lines are indented below the for statement above. I’ll repeat that for clarity.

    In the loop, I want to do a few things. First, I get a path to the file with the os.path.join  command, which builds me a path that works in various functions. Next, I want to use the chardet module to detect the encoding of the file. They should all be the same, but I had some issues when expecting the default encoding (this post helped). This ensures I get the correct encoding for the file.

    Lastly, I’ll open the file.

    # loop through the files
    for f in onlyfiles:
    
        currentfile = os.path.join(mypath,f)
    
        enc=chardet.detect(open(currentfile,'rb').read())['encoding']
    
    with open(currentfile,'r', encoding=enc) as json_data:

    Again, I have a with statement and want to run other code, so I’ll indent the next line. The next line reads in the file using the json module, which has a load() function. This function knows how to parse a json file so that we can work with it.

    Lastly, outside of the with command, I’ll return to the for loop be de-indenting one level and calling a pandas function to take a portion of the JSON file and load it into a dataframe. Think of a dataframe like a resultset in SQL or a datatable in C#. In this case, I’ll take the “sessions” structure. I print the first five rows with the head() function.

    The entire code structure looks like this:

    # Basic import of a JSON file
    import json
    import chardet
    import pandas as pd
    import os
    
    mypath = '.\\raw'
    onlyfiles = [f for f in os.listdir(mypath) if os.path.isfile(os.path.join(mypath, f)) and f.endswith('.json') ]
    
    # loop through the files
    for f in onlyfiles:
        currentfile = os.path.join(mypath,f)
        enc=chardet.detect(open(currentfile,'rb').read())['encoding']
        with open(currentfile,'r', encoding=enc) as json_data:
            data = json.load(json_data)
        # get session data from json
        df = pd.DataFrame(data['sessions'])
    
        # print the head
        print(df.head())
    

    The results look like the image below. I’m not covering how to run Python or anything else, but you can see the first five rows with the session title and a couple other elements.

    2024-05-06 14_20_09

    The raw JSON looks like this for the first file with the sessions element.

    2024-05-06 14_21_21

    Now I can work with the data and query, transform, rewrite, store in a database, whatever. I’ll cover how to move this data in another post.

    SQL New Blogger

    This post took me about 15 minutes to write, mostly because of looking up some links. The code itself was for something I was already doing, so after getting the code working, I wrote this post using it.

    This is a good example of something you could write to show that you are building some data warehouse skills, which are valuable for many employers.
  • Deleting Stale Local Database Git Branches with SSMS–#SQLNewBlogger

    I wrote a post recently about pruning branches in git. That’s part of the job, but the other part is removing local branches. This post looks at one way to do that in a semi-manual fashion.

    This could be automated, but it took seconds, so I did a quick manual thing. I’ll work on an automated way, but since I do this rarely, manual is fine for me.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers. You can see all posts on Git as well.

    Getting a List of Branches to Delete

    In the last post I showed how to get a list of branches with dry run. This was the image I showed of branches. If I re-run that without the dry run, the branches are removed.

    2024-04-11 10_51_57-cmd

    The output is similar, but either set of output works. Once we have a list of branches, what do we do? Let’s use SSMS to help.

    SSMS Makes This Easy

    If I highlight the results of my git prune, I can copy/paste those into SSMS. You can see below I’ve done this, and then held the ALT+Shift key to select a bunch of text in a box. This is all the text apart from the branch names.

    2024-04-11 10_54_39-SQLQuery4.sql - not connected_ - Microsoft SQL Server Management Studio

    Once I’ve done this, I can let go of those keys and type “git branch –d “, which will replace the text on every line. You can see this below.

    2024-04-11 10_54_52-SQLQuery4.sql - not connected_ - Microsoft SQL Server Management Studio

    This is a great technique, and while it works in VSCode and some other editors, I usually have SSMS open and it works very well here. I then select all this text, paste it back into the CMD window, accept the note that this is a multi-line paste, and all my deletes run.

    2024-04-11 10_55_27-cmd

    Voila, all remote branches deleted are removed from my local git install. A few of these were already removed manually as I experimented.

    SQL New Blogger

    As I mentioned in the previous post, version control skills (especially git) are core for most technology pros. DBA, developers, sysadmin, anyone working with modern software development or administration likely needs to know about version control.

    This post was about 10 minutes. You could write this in 15 and showcase your tech skills to a future employer.

  • Using Git Prune–#SQLNewBlogger

    As I’ve been working with SQL Saturday and managing changes to events, I’ve accumulated a lot of branches. Even though I’m a solo developer, I decided to use branches, as I expect others to share this load in the future. This post looks at how to start cleaning those up.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers. You can see all posts on Git as well.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    Finding Old Branches

    When I ran the git branch command, I saw this. There are a lot of old branches in there.

    2024-04-11 10_44_53-cmd

    I decided that I should reduce this number. After all, even removing stale branches means I have a lot of events in flight.

    We use GitHub, and when I go on the site, I see lots of branches, some of which date back to last year. Those events are done, so I decided to delete some branches. In the image below, there are three branches. To the right, there are delete icons on the bottom two as I’ve already pressed the one to delete the remote branch on the top one.

    2024-04-11 10_51_00-Branches · sqlsaturday_sqlsatwebsite — Mozilla Firefox

    Now, how do I delete the local branch? Let’s start by removing it.

    Git Prune

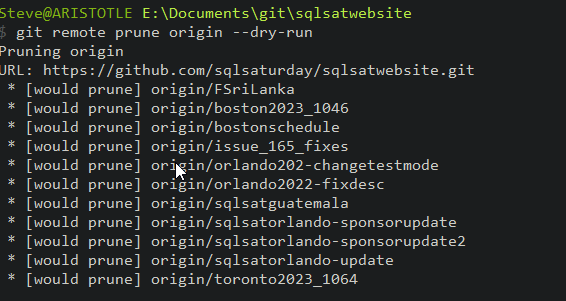
    There is a command to remove references to remote branches that are deleted: git prune. I deleted a few older branches, and then ran git prune for remotes, with the –dry-run option. This tells me what would happen. As you can see, a number of branch references would be deleted.

    2024-04-11 10_51_57-cmd

    Nothing in here I’m worried about or that is active. I’ve deleted these on GitHub, so I’ll re-run the command without dry run. This removes the references.

    Unfortunately, the local branches still exist. We don’t remove these, as it’s possible I have work on a local branch not sent to the remote, so doing this automatically, even if I do it, is dangerous.

    I’ll do another post on removing the local branches.

    Automating the Removal of Remote references

    I might want to remove local references for branches that get deleted on the remote. This is useful if you delete branches on merge. I don’t in this case, as I’m often using the same branch for multiple changes for an event, rather than a new branch for every one.

    One way to do this is to change the config with this:

    git config remote.origin.prune true

    This will then run the prune on each fetch or full. This helps keep things cleaner, though local branches still exist. However, if I commit to a local branch and push, I’ll get an error that I need to configure the upstream. That helps with me being aware of what’s active or not.

    SQL New Blogger

    Using version control is a core skill for anyone in technology. Even database people. You could write posts on how you use or learn about git (or something else) and showcase your skills.

    This post took me about 15 minutes to write, even with screen shots.

  • The Basics of TRY CATCH Blocks–#SQLNewBlogger

    I was working with a customer and discussing how to do error handling. This is a short post that looks at how you can start adding TRY.. CATCH blocks to your code.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    TRY CATCH

    This is a common error handling technique in other languages. C# uses it, as does Java, while Python has TRY EXCEPT. There are other examples, but these are good habits to get into when you don’t know how code will behave or if there is something in your data or environment that could cause an issue.

    In SQL, I think many of us get used to writing one statement in a query and forget to do error handling, or transactions. However, this can be a good habit as your code might grow and people might add more statements that should execute.

    A classic example of code is someone writing this:

    DECLARE
       @id INT = 2
    , @name VARCHAR(20) = 'Voice od the DBA'
    , @stat INT = 1;
    BEGIN TRAN;
    INSERT dbo.Customer
       (CustomerID, CustomerName, status)
    VALUES
       (@id, @name, @stat);
    IF @@ERROR = 0
       COMMIT;
    ELSE
       ROLLBACK;


    Note that this does look for an error and then decide what to do. However, we could be better, especially if we wanted to possibly add a second insert or other work. We could do this:

    DECLARE
       @id INT = 2
    , @name VARCHAR(20) = 'Voice od the DBA'
    , @stat INT = 1;
    BEGIN TRY
         BEGIN TRAN;
         INSERT dbo.Customer
         (CustomerID, CustomerName, status)
         VALUES
         (@id, @name, @stat);
         COMMIT
    END TRY
    BEGIN CATCH
         ROLLBACK 
    END CATCH


    It doesn’t look like much, but this code could easily be enhanced with a better pattern. We can capture the various error messages like this:

    DECLARE
       @id INT = 2
    , @name VARCHAR(20) = 'Voice od the DBA'
    , @stat INT = 1;
    BEGIN TRY
         BEGIN TRAN;
         INSERT dbo.Customer
         (CustomerID, CustomerName, status)
         VALUES
         (@id, @name, @stat);
         COMMIT
    END TRY
    BEGIN CATCH
        DECLARE @ErrorMessage NVARCHAR(4000);
        DECLARE @ErrorSeverity INT;
        DECLARE @ErrorState INT;
    
        SELECT 
            @ErrorMessage = ERROR_MESSAGE(),
            @ErrorSeverity = ERROR_SEVERITY(),
            @ErrorState = ERROR_STATE();
    
        RAISERROR (@ErrorMessage, -- Message text.
                   @ErrorSeverity, -- Severity.
                   @ErrorState -- State.
                   );
    
        WHILE @@TRANCOUNT > 0
        BEGIN
            ROLLBACK TRANSACTION;
        END 
    END CATCH


    In this case, we have a few statements that work with the error, in this case using RAISERROR to raise this. We could also use THROW or add something else. If we had more inserts, like to a child table, we could encapsulate them all here. What’s more, if we had logging, we could log this before the rollback to another system if our logging were not transaction dependent.

    Using TRY CATCH is really just structuring your code differently. Ideally, using something a snippet in SQL Prompt so your developers have an easy way to standardize error handling.

    SQL New Blogger

    This post took me about 15 minutes to structure and test. I looked at a few patterns, and I liked the one in this Stack Overflow answer as a good way to generically implement this structure.

    You could write a similar post showing your next boss how you implement error handling, transactions, anything. Give it a try.