Tag: syndicated

  • Creating a Database Snapshot

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    I’ve rarely dealt with database snapshots, outside of lab experimentation. They didn’t exist when I did most of my DBA work, and since then we haven’t seen the need for them at SQLServerCentral, though, I may suggest we add them to our deployment process since we can quickly roll back if something breaks.

    However, I created one recently for a test and realized that I’d forgotten the syntax. Unlike the quick "create database xx" syntax I often use, with a snapshot I need to be more specific.

    The big item that I must specify is the location of the snapshot file. This is the file that gets written to with the copy-on-write process that ensures the original state of the pages when the snapshot is created are still available.

    You do need to give the database a logical name as well, which can be anything, but the reference below has suggestions. I’d say that this is bad:

    CREATE DATABASE sandbox_snapshot
    ON (NAME = MySnap
    , FILENAME = ‘h:\SQL Server\MySnap.ss’
    )
    AS SNAPSHOT OF Sandbox

    But this is better

    CREATE DATABASE sandbox_snapshot_20150122_1345
    ON (NAME = SandBox_Snap_20150122
    , FILENAME = ‘h:\SQL Server\MySnap.ss’
    )
    AS SNAPSHOT OF Sandbox

    Because the snapshot is based on an existing database, at a particular point in time, it’s useful to specify the time when the snapshot was created, if possible. While you can get this from metadata, if you have people that look to multiple snapshots for information, it can be handy to know when each is from.

    However if you are providing this on a schedule, like daily, for people to report from, you might need to have the same name every day. Think about this, as you cannot rename a snapshot once it’s created.

    SQLNewBlogger

    When I realized I had to lookup the syntax, I took a few notes and captured code, which meant I combined this writing (< 10 minutes) with other work I was doing.

    You should do the same. When you tackle something new, take screenshots, save code, and drop it in a OneNote/EverNote/etc notebook for your weekly blog writing.

    Reference

    The references I used:

  • Push Button Deployments

    I worked in an Agile team in 2000 and we deployed changes to our web platform every Wednesday for over 18 months. That was about the length of time I was involved before the small startup failed, but not for lack of technology. In fact, I managed a few weeks extra pay by helping sell and deploy our IP to another company.

    Deploying regularly and often, to meet business needs and get features into the hands of customers is important. For most businesses, this is something the CTO and CEO want. It can work, and there’s a case study with Nmbrs, a Redgate customer, that has used DLM with this quote:

    “The productivity of the team has improved dramatically. We were doing one database update a week, which took almost a full day. Now it takes ten minutes. We can spend the extra time we’ve gained developing new features.”

    That’s been my experience with tooling and automation. If you get things setup, as I did with my startup, then you gain confidence in deployments, are willing to make them more often, and get these small chunks of software to customers on a regular basis. It’s not just customers, as we found we could make some fundamental changes in databases and applications that helped smooth development later without affecting customers.

    I know I’m paid by Redgate to talk about DLM, but the concept, the idea, the processes really do work well. They’ll help you get features to customers quicker (and feedback to developers faster) as well as give you confidence that you can release, if you find an issue with your application.

  • Advent of Code–Day 2

    I’ve continued working along, and while I found Day 2 to be straightforward in Python and PowerShell, I thought it was tricky in SQL I decided this one was worth a post, since I had to futz around a few times to solve it, and I managed a slightly different way than some others.

    If you haven’t solved it, then try. Come back here later and compare solutions, but give it a try first.


    Solution coming below, so don’t scroll if you don’t need the solution.


    But first,


    Missteps

    I had a misstep in this one. I loaded the entire list of packages as separate lines into separate rows into a single column table. My challenge to myself was not to use ETL work to break this apart, or updates. I wanted a simple solution, thinking I didn’t want to take up extra space in the database.

    As a result, I wanted a single query from a single string column that had the package size stored as one column, ‘2x3x4’ as an example.

    My first attempt used the Moden Splitter function, which seemed to work well. I got three rows for each package. I then used a WIndow function to grab that data, order by the sizes, and then start performing calculations. When I didn’t get the right result, I started digging in.

    One of the first things I saw was that I had multple packages with the same sizes. So I had two 22x3x1 packages, and when I used a partition based on the dimensions, I had calculation problems. That’s because the window partition doesn’t know that three rows are one package and three are another.

    I could have fixed this with some other value to capture the package, maybe a row_number even, but I decided not to go down this route.


    My Solution

    I decided to break this down, and I used a series of CTEs to do this. I haven’t gone back to optimize things, or combine CTEs, which is possible, but instead left the CTEs as I wrote them to solve parts of the puzzle. Multiple CTEs are east, and they help examine the problem in pieces.

    My first step was to parse the string. I don’t love this solution as it is limited to a three dimension package, but it does seem to be the easiest way to break down the dimensions of the package. My query looks to find the string positions for:

    • end of the first dimension
    • start of the second dimension
    • start of the third dimension.

    This gives me the simple query:

    with cteSplit (d, el, sw, sh)
    as
    (
    select
       dimensions
    , endlength = charindex(‘x’, dimensions) – 1
    , startwidth = charindex(‘x’, substring(dimensions, charindex(‘x’, dimensions),20)) + charindex(‘x’, dimensions)
    , startheight = len(dimensions) – charindex(‘x’, reverse(dimensions))  + 2
    from day2_wrappingpresents d
    )

    Once I had these values, a little math gives me the length, width, and height.

    , cteDimensions
    as
    (select
       d
       , l = cast(substring(d, 1, el) as int)
       , w = cast(substring(d, sw, sh-sw-1) as int)
       , h = cast(substring(d, sh, len(d)) as int)
    from cteSplit d
    )

    Now I’m in business. These two queries were fairly simple, despite all the nested functions. I’ve got integers with the dimensions of each package.

    Now the tricky part. I want these ordered. They’re columns, not rows, and I can’t put an ORDER BY in the CTE, so I need to use some comparisons.

    , cteOrder
    as
    ( select
       d
    , small = case
                when l <= w and l <= h then l
                when w <= l and w <= h then w
                when h <= l and h <= w then h
            end
    , middle = case
                when (l >= w and l <= h) or (l <= w and l >= h) then l
                when (w >= l and w <= h) or (w <= l and w >= h) then w
                when (h >= l and h <= w) or (h <= l and h >= w) then h
            end
    , large = case
                when l >= w and l >= h then l
                when w >= l and w >= h then w
                when h >= l and h >= w then h
            end
      from cteDimensions
    )

    Not the prettiest code, and perhaps there are better ways to determine this, but this passed all my tests, and seemed to work.

    I could have put the next part in the final query, but I decided to make this a separate CTE to easily read the math. I know some people don’t like lots of CTEs, but in this case, I think they make the query very readable. I should look back at this in six months and see what I think.

    , cteFinal
    as
    (
    select
      d
      , area = (2 * small * middle) +
               (2 * small * large) +
               (2 * middle * large)
      , slack = (small * middle)
    from cteOrder
    )

    Now I use a final outer query to sum things up.

    select
    sum(area + slack)
    from cteFinal

    The other thing I noticed here is that when I needed to solve the second part, I only had to change the math in the cteFinal to get the new values. It took longer to re-read the second part than to change the code and solve it.

    I looked over how Wayne Sheffield and Andy Warren solved this in T-SQL, and I thought their approaches were interesting. I didn’t want to PIVOT or UNPIVOT anywhere, nor did I look at performance here. This runs so quickly, I’m not sure it matters, though I wonder if we were calculating across 1mm rows, would one be better?

    I may look, but for now, I’ll leave that to someone else.

  • Disabling SQL Server Network Protocols

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    I ran across a question on network protocols recently, which is something I rarely deal with. Often the default setup for SQL Server is fine, but there are certainly times you should add or remove network connectivity according to your environment.

    Here’s a short post on turning off (or on) a network protocol for SQL Sever.

    What’s Enabled?

    The easiest way to verify what’s enabled is to use the SQL Server Configuration Manager. You’ll need administrative permissions on the host to run this, but it’s easy to find.

    2016-01-13 14_59_40-Start

    Once you open it, typically you’ll have a list of the items that can be configured.

    2016-01-13 15_02_09-Photos

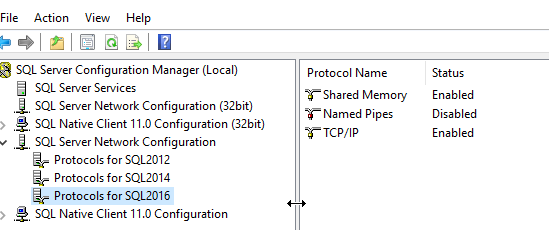
    We want the SQL Server Network Configuration, which is the server level configuration for this host. The Client configurations are for the host being used a client to connect to a SQL Server.

    2016-01-13 15_02_31-Photos

    As you can see here, I have Shared Memory and TCP/IP enabled for this instance, but Named Pipes disabled.

    Disabling a Protocol

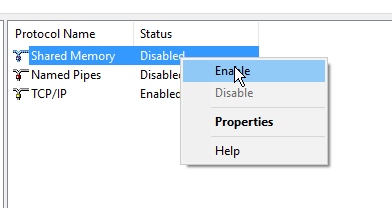
    As you might expect, this is easy. I right click on a protocol, and I can change the status. In this case, I’ll disable Shared Memory

    2016-01-13 15_03_50-Photos

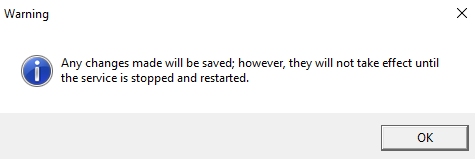
    Once I do that, the protocol is disabled. However not on the instance. I’ll get this message.

    2016-01-13 15_04_56-Photos

    I need to restart the server. Once that’s done, no one will be able to use Shared Memory on the host.

    I can fix this

    2016-01-13 15_04_49-Photos

    Of course, I need to restart my instance again.

    Checking the Log

    When SQL Server starts, quite a bit of configuration information is written into the log. This is useful for troubleshooting in many cases. One of the things you’ll find is the network listeners, as shown here.

    2016-01-13 15_08_14-Log File Viewer - JollyGreenGiant_SQL2016

    This is usually after the database startup information, so if you look, you can see I have some local pipes and some TCP/IP settings here.

    SQLNewBlogger

    After reading a question, this was less than 10 minutes to write, with making screenshots. However I’ve done this before. If this was your first time, then it might take you longer to research and write, but I bet most DBAs could do this in 30-45 minutes.