Tag: syndicated

  • Enabling Compression? Update your baseline

    I wrote recently about capacity planning, with an item near the end about disk usage. Someone pointed out to me that compression can dramatically affect your baseline, and as you implement it, or de-implement it, you need to update your baseline.

    That’s an important point, and if you make changes, you want to do one of two things.

    • Recalculate the old numbers to be in line with the new ones
    • Make a note in your documentation somewhere

    Whether you restate the history is up to you, but I wouldn’t. I hate changing the old values, but I can see someone not being aware of changes and perhaps getting confused. If that is a problem, and you are sure you’ll keep compression around, then you can run a quick test of compressed and uncompressed backups, get a rough idea of the ratio, and then alter your old numbers.

    For me, I prefer to make a documentation note, and update everyone to be aware of the change, perhaps even adding filters to my extrapolation routines to not use the older data.

  • Insert multiple rows from one INSERT statement

    One of the things that has been annoying for a long time in SQL Server is adding lots of data for testing. Personally I use Data Generator, and I recommend that, but for a quick few rows of data, do you want to do this:

    CREATE TABLE SalesOrders
    ( OrderID INT IDENTITY(1,1)
    , OrderDate DATETIME
    , CustomerID INT
    , OrderAmount NUMERIC(10, 4)
    )
    GO
    INSERT SalesOrders (OrderDate, CustomerID, OrderAmount)
      SELECT '1982-05-19 06:31:48.950', 1,           579040.5070
    INSERT SalesOrders (OrderDate, CustomerID, OrderAmount)
      SELECT '1994-11-27 17:14:41.790', 2,           348808.5860
    INSERT SalesOrders (OrderDate, CustomerID, OrderAmount)
      SELECT '1972-11-08 17:40:01.170', 3,           758992.3650
    INSERT SalesOrders (OrderDate, CustomerID, OrderAmount)
      SELECT '1972-05-31 01:19:05.530', 4,           779853.1990
    INSERT SalesOrders (OrderDate, CustomerID, OrderAmount)
      SELECT '1994-12-22 10:40:57.410', 5,           666173.8040

    There’s a lot of INSERT typing, even with copy/paste functionality and editing the various rows gets to be cumbersome of you actually get some sample data like this that you want to convert (say from someone’s blog post of results:

    1, 12/1/2011, 3, 123

    2, 12/2/2011, 4, 2

    3, 12/1/2011, 3, 123

    You could do the UNION thing, like this:

    INSERT SalesOrders (OrderDate, CustomerID, OrderAmount)
      SELECT '1982-05-19 06:31:48.950', 1,           579040.5070
    UNION ALL
      SELECT '1994-11-27 17:14:41.790', 2,           348808.5860
    UNION ALL
      SELECT '1972-11-08 17:40:01.170', 3,           758992.3650
    UNION ALL
      SELECT '1972-05-31 01:19:05.530', 4,           779853.1990
    UNION ALL
      SELECT '1994-12-22 10:40:57.410', 5,           666173.8040

    That works, but it’s still a little cumbersome.

    In SQL Server 2008, there’s a better way. You can now include multiple sets of data in your insert, like this:

    INSERT SalesOrders (OrderDate, CustomerID, OrderAmount)
    VALUES 
    (           '1982-05-19 06:31:48.950', 1,           579040.5070),
    (           '1994-11-27 17:14:41.790', 2,           348808.5860),
    (           '1972-11-08 17:40:01.170', 3,           758992.3650),
    (           '1972-05-31 01:19:05.530', 4,           779853.1990),
    (           '1994-12-22 10:40:57.410', 5,           666173.8040)

    Just put brackets around each set of data, and you can easily insert multiple rows.
  • RECONFIGURE can flush the procedure cache

    I ran across this KB article the other day, which lists a few ways in which performance is affected by various maintenance or administrative type operations.

    In KB article 917818, it notes that some operations cause a performance issue. Some of the operations make sense (offline/online, restores, etc), but there were a few that surprised me. For example, did you know that Autoclose flushes the cache? Might not be a big deal, but it also might mean that your apps based on Express might end up running slowly each time the user accesses the databases.

    There are also a number of items which are implemented by a RECONFIGURE that will flush the cache. These are listed in the KB and are:

    • cross db ownership chaining
    • index create memory (KB)
    • remote query timeout (s)
    • user options
    • max text repl size (B)
    • cost threshold for parallelism
    • max degree of parallelism
    • min memory per query (KB)
    • query wait (s)
    • min server memory (MB)
    • max server memory (MB)
    • query governor cost limit

    Also, changing a filegroup to read-only will flush the cache.

    This is by design, and I wouldn’t expect it to change anytime soon. Since these options can affect query plans, it might make sense to flush the cache, but if you don’t agree, file a CONNECT item and stump for votes.

  • Blackout

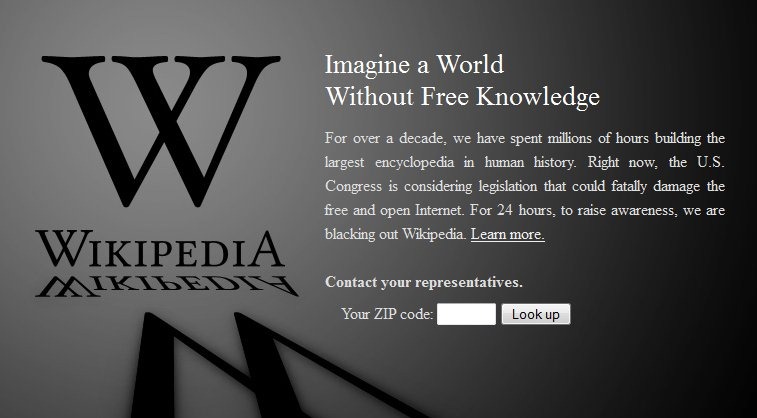
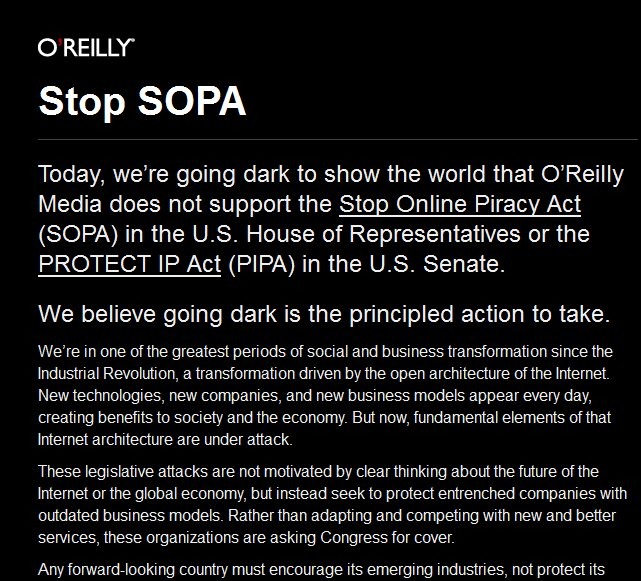
    It’s anti-SOPA/PIPA day, and a number of sites have shut down for the day. O’Reilly closed their page, and of course, Wikipedia shut down.

    oeillysopa

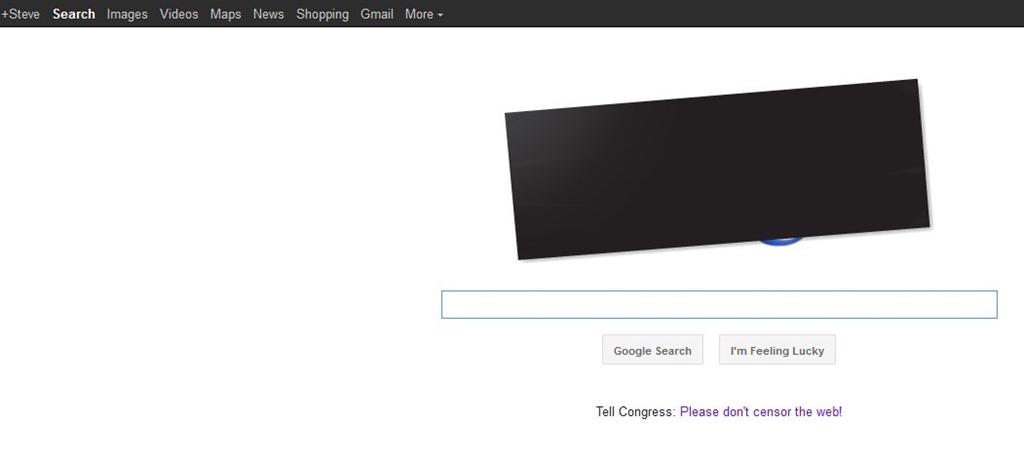
    Google didn’t do the blackout I was hoping for, but they have hidden their logo:

    blackout

    I like the Wikipedia closure, which appeared seconds after hitting a page. It has a great effect on me.

    wikipedia

    I debated about shutting down this site, but for a WordPress hosted site, I didn’t see an easy way to do it.

    To be clear

    I am not against copyright legislation, nor IP protections. We should ensure that content creators have some recourse and ability to control the way their content is used.

    I think SOPA / PIPA are gross, overreaching ways of doing this that are designed to help a few large companies, and potentially hurt many small ones, and will have no impact on foreign sites. These laws simple cut the US off; they do not affect the operation of the foreign site.

    We can come up with better ways to protect content, while also preserving fair use and personal liberties, and limiting copyright.

    My personal stance is that the original 14 years + 14 year extension for copyright is plenty. If you cannot earn money in those 28 years, let someone else build on your work.