Tag: T-SQL Tuesday

  • T-SQL Tuesday #66 – Monitoring SQL Server

    tsqltuesdayThis is a T-SQL Tuesday that not only makes me smile, but makes my boss happy. In fact, I’m sure that quite a few people at Redgate Software, my employer, are thrilled with this topic since we have a product that helps you here: SQL Monitor.

    T-SQL Tuesday #66 has the theme of monitoring, hosted by Catherine Wilhelmsen. Anything having to do with monitoring is fair game. Custom scripts, home grown applications, even third party software.

    If you’re a #SQLNewBlogger, this is a great chance to keep going with a new post. If you can’t write now, come back and publish something later. If you post something on May 12, 2015, you’ll get included in Catherine’s roundup. However if you can’t make it, you’re still a T-SQL Tuesday writer.

    Either way, follow #tsql2sday and learn a few things.

    Self Monitoring

    My post is going to be more of a philosophical one, with a little code.

    Most of the time I’ve worked with SQL Server, I’d had some responsibility for a production instance. Even when I was writing code and building software, I’d still find myself as the backup, if not the primary, accidental DBA. I learned early on that I needed to have some way to track what was happening on an instance.

    One of the ways in which I did this was by ensuring each instance could monitor itself. I’d found far too many times that having a process connect remotely to the instance and gather data was a way to lose data. Too often something would get missed. The exact time that a process connected was the time things didn’t work.

    As a result, I decided to keep some monitoring on the local instance. Even though I usually had a central server roll up information, if that instance dropped off the network (or my monitoring server died), I’d still know what was going on. This was especially important when I worked in the financial industry or was bound by ISO 9000 standards.

    Note: These days I don’t bother to manage monitoring software of my own on an instance. I use SQL Monitor because I work for Red Gate, but no matter who my employer might be, I’d buy software because it’s worth the cost. I don’t have the time to worry about maintaining my own software for most monitoring tasks.

    DBAAdmin

    I had a setup routine that I used to use on every instance. It did a few things, the first of which was create a DBAAdmin database. This was the place I could put anything I needed to monitor my instance. I tried to keep all the code the same between instances, and tried to write idempotent code so that re-running the install wouldn’t cause issues.

    Once I had the database, I’d add tables and procedures for various purposes. For example, one of the things that needed to be tracked each day was the backups for the databases. So I created a table called DBBackups.

    CREATE TABLE DBBackups ( BackupID INT IDENTITY(1,1) , Backupdate DATETIME , DatabaseName VARCHAR(2000) , BackupType CHAR(1) , Filename VARCHAR(2000) , sizeGB NUMERIC(15,2) ) ;

    This table had a corresponding procedure that was designed to scan the filesystem and report back on the latest backups written to the file system. The details of each file are recorded here.

    Why? If there’s a problem with monitoring, the local machine still has the information about backups. What’s more, I can usually get more details here than I’m capturing in a monitoring system that’s looking at the last backup date or just getting full backups. If msdb history is wiped, I have a second copy here.

    However I also need to remove data over time, so this solution usually has three parts.

    • Table for data storage
    • Procedure(s) for gathering data
    • Procedure and job to remove data older than xx days

    That’s simple, but it’s a decent amount of work. However I only use this for certain areas. I used to really care about backups, but SQL Monitor captures that for me. However I might care about sp_configure settings. While SQL Monitor can alert me if there are changes, how do I know what changed? I’ve used a process like this to keep the last week’s worth of sp_configure information, captured every day to let me look back.

    As I noted above, I wouldn’t rebuild a monitoring solution for overall checking of a database, but I might capture specific information using this process, with the table and procedures tailored to the specific information I care about.

  • T-SQL Tuesday #65 – Learning Computed Columns for XML

    It’s T-SQL Tuesday time again, and this month the invite comes from Mike Donnelly (@sqlmd). The topic is Teach Something New and it’s a good one.

    I try to learn something all the time, and this post is about something I ran into recently with a submission from a user that I needed to check. I had to dig in a bit and see how XML worked in computed columns and I decided to write about it for this month’s entry.

    T-SQL Tuesday is a monthly event on the second Tuesday of each month. There’s a new invite each month, and you need to watch Twitter and the #tsql2sday tag to find the next one. I keep a running list of past topics, and feel free to write on any of them and post something.

    Learn Something New

    I haven’t done a lot of work with computed columns or XML in my career. At least not in SQL Server. I do remember using VB and traverse XML documents and pull out nodes, but that was years ago.

    Recently I had to verify how XML computed columns work and that required me to dig in a bit to the rules for both. This post looks at the way in which I learned how to return part of an XML column from a table.

    Imagine that we have a table storing some XML data inside it. For my demo, I have a table storing profile information for users. I’ve actually seen a table like this, grabbing information for a website and then shredding it later if there are changes needed in the database. Here’s the setup of the table with a row of data inserted.

    CREATE TABLE UserProfile ( UserID INT IDENTITY(1,1) , profile XML ); GO INSERT INTO dbo.UserProfile ( profile ) VALUES ( N'<user> <username>way0utwest</username> <history> <pageurl>/default</pageurl> <pageurl>/scripts/</pageurl> <pageurl>/scripts/id/2433</pageurl> </history> <points> <forums>32432</forums> <qotd>1123</qotd> </points> </user>' );

    If I want the username from this table, I can use this query:

    SELECT profile.value('(/user/username)[1]', 'varchar(max)') FROM dbo.UserProfile AS up;

    That will return this data:

    xmlshred_a

    However, suppose I don’t want to use that code in all my queries in the application. Certainly it’s not bad for stored procedures, but I don’t want to repeat that over and over either.

    Instead I want to use a computed column. I’d think that we could do something like this:

    ALTER TABLE dbo.UserProfile ADD Username AS (profile.value('(/user/username)[1]', 'varchar(max)'));

    However that doesn’t work. I get this error:

    Msg 435, Level 16, State 16, Line 1

    Xml data type methods are not supported in computed column definitions. Create a scalar user-defined function to wrap the method invocation. The error occurred at column "Username2", table "UserProfile", in the ALTER TABLE statement.

    I haven’t seen this documented in Books Online, but it’s a restriction. However, there is a specific document on using XML in computed columns, which gives a workaround. The way to do this is to use a user-defined function. I need to build a function with my query:

    CREATE FUNCTION UserProfile_XML_UserName(@xml xml) RETURNS varchar(200) AS BEGIN RETURN @xml.value('(/user/username)[1]', 'varchar(max)') END ; GO

    Now, I can use my function in the computed column

    ALTER TABLE dbo.UserProfile ADD Username AS (dbo.UserProfile_XML_UserName(profile));

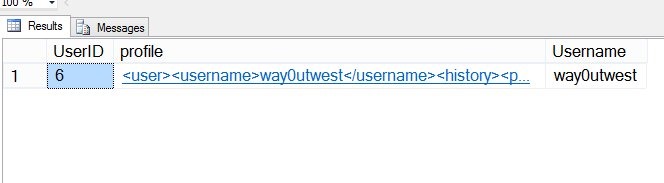
    Now when I query the table, I have a new column with the username:

    SELECT top 10 * FROM dbo.UserProfile AS up

    Here are my results

    xmlshred_b

    That’s what I learned in the last month in working with T-SQL. This came from a user submission, and it required me to dig into BOL and find out how I could make this work.

    References

    Here are the references I used to learn about this:

  • T-SQL Tuesday #63 – Security

    tsqltuesdayIt’s T-SQL Tuesday time again and this month we look at security. Kenneth Fisher has chosen this as his topic for February and you can read his invite here. There are lots of choices on what you write about, and I’m looking forward to reading what people choose.

    You can join in, by writing a post today and publishing it with a link in Kenneth’s invite. Or you can write later and just put your own thoughts down on the subject.

    T-SQL Tuesday is the idea of Adam Machanic (b/t) , and it’s a monthly party where everyone writes on a specific topic. The first Tuesday of the month usually has a new invitation issues, and you have to watch for it. I’d recommend putting a reminder in your calendar. The second Tuesday of the month is when we publish posts.

    If you’d like to host, contact Adam.

    Security Across Environments

    At one point in my career, I worked with a startup company. We had a number of experienced people working in development, and we wanted to set up a series of environments early on to perform agile development. When I arrived, the application we built had been running for about 4 months, and we were looking to improve our data handling and development processes.

    At the time, we had a production server and a development server. There were accounts for the web application and the initial security had been to grant security on tables as appropriate for the web application. Any tables that existed for administrative use were limited to sysadmin access.

    This wasn’t a bad plan, but as we implemented a test environment, I knew this would be an issue. We didn’t want to give testers (or developers), access to the production AD account that was used by the web application. We also didn’t want any problems during deployment.

    Moving to Roles

    It can be hard to change security around on an existing application. Fortunately we had limited numbers of objects and applications accessing our SQL Server database, so I could easily determine if refactoring was going to break anything.

    My first refactor was to create two groups in each environment. I used code similar to this in Development, QA, and Production

    CREATE ROLE WebAppUser;

    CREATE ROLE WebAppAdmin;

    By creating these roles in each environment, we had a consistent place to set security for objects. We proceeded to assign generic read/write/execute security to objects to these roles as needed. The WebAppAdmin role accesses all objects (essentially as datareader/datawriter). to grant rights to the WebAppUser role for specific objects, we scripted out the rights assigned to the current WebUser user and then granted those rights to the role.

    The last step was adding the WebUser to WebAppUser. Once this was done, we essentially had duplicated permissions for the user, WebUser, through the user account and the role.

    Our test procedure for the change was to begin removing the rights granted to the user in the QA environment. Once we verified the web application still functioned, we made one final change.

    In the Development environment, we created a new user, WebAppUserDev and put this user in the WebAppUser role. We then changed IIS to use this user account. From this point forward, development was separated from production. The Windows admin changed the WebUser password and development was locked out of production. We did the same thing in QA and created a new account there.

    Once everything was done, we removed all direct object rights from the WebUser account in production. This was a scary day, as we were counting on our role having all the correct rights. Fortunately our process had worked, and the application continued to function.

    That was a lot of work, but a refactoring that doesn’t break anything can take some time. There will be multiple steps and it can take days or weeks to implement.

    Moving Forward

    From this point forward, development proceeded without problems. All of our object code now included one, or both, of these lines at the bottom of the script.

    GRANT EXECUTE on MySP to WebAppUser;

    GRANT EXECUTE on MySP to WebAppAdmin;

    We migrated object code between environments, but not security. Security for each environment was handled separately, with separate accounts added to these roles. Our deployments became much easier.

    When we needed a new role (for client auditors that could access specific tables), we added the role as a part of our deployment and assigned security to the role. The role deployment was handled separately from application deployment with a new role being deployed in a script, but a different user added in production by the sysadmin to AD and the role. Later deployments had permissions grants for the role that were the same in development, QA, and production.

    When we added a Staging environment, it was as simple as restoring the production database, deleting the orphaned WebAppUser user from SQL Server and creating a new user for that environment.

    Consistency

    One of the big issues with deployments not proceeding smoothly comes when one environment is not set up the same as others, and the scripts run in one environment do not execute on another. When users are included in all environments, you have a security hole, but when different users get different security, you create scripts that must be edited, and potentially mid-edited.

    The more you can abstract away portions of your application, whether this is through roles, synonyms, linked servers, or other items that can be named consistently, but configured differently in separate environments, the smoother your deployments will be.

    There are certainly challenges with deploying new items across environments, but that’s a discussion for another day. For security purposes, I think that roles are an important way to ensure that security is maintained, but deployments are not impacted.

  • T-SQL Tuesday #62 – Healthy SQL

    tsqltuesdayThe invitation for T-SQL Tuesday this month comes from Robert Pearl. It’s called HealthySQL and it’s a topic I like. I’ve spent a lot of time in my career being proactive with SQL Server databases, and keeping them healthy is important.

    If you’d like to participate in the party, just write a blog post and publish it on the second Tuesday of the month.

    However, if you’d just like to participate, take the topic anytime and write your post.

    Healthy SQL Server

    I would guess most of us would prefer to be healthy over being sick. While it’s hard to be extremely strict in taking care of ourselves, many of us do make efforts to eat better, exercise, etc. to maintain our physical health. If we don’t, then we get sick and are usually miserable.

    The same thing can happen to our SQL Server instances, and if they get sick, many of us are miserable as well. Mostly because we might be working late, working overnight, or being yelled at by managers.

    I learned a long time ago that no matter how well I take care of myself, I’ll get sick at some point. And no matter what I do for my SQL Servers, at some point they’ll have issues. However if the issues could have been easily prevented, it’s embarrassing and it calls into question my capabilities as a DBA.

    I’ve got lots of stories of how I’ve prevented issues by keeping my servers healthy, but there are really a few simple things I’ve set up and worked on. I included these in my Avoiding a DBA’s Worst Days with Monitoring talk. I need to blog about these in more detail, but here they are with a few notes.

    Backups

    The core of any data system is the backup. If you have the data in a backup (and the backup is good), then you can recover from any other issues. As a result, I’ve tried to be sure that I have backups setup, monitoring on the backup jobs, and a process to make a copy of the backup somewhere else.

    Space

    Running out of disk space is one of the simplest things to avoid and one of the most embarrassing to deal with. I’ve written about placeholders, but you should be monitoring space, have placeholders available, and proactively look for more space as you get low.

    Security

    Security is important, and we read about issues all the time. However apart from hackers, loose security often means that users, developers, or anyone else can cause issues in your database. Tight security can be a pain, but it really prevents a lot of issues.

    Resources

    Resources refer to the hardware and software that allow your systems to function. If you don’t have enough resources for your workload, no one is happy and you are listening to complaints. Being proactive, looking to tune queries, reduce fragmentation, add indexes, reindex, update stats, and more are important here.

    Deployment

    Face it, we’ll always be changing our systems with new patches, code, etc. Building a decent test routine is important as we want to prevent deployments that will make our servers unhealthy. However having a plan to deal with issues (because you will have issues) means thinking about rollbacks or other methods of undoing problems.