Tag: T-SQL Tuesday

  • Poor Data Modeling – T-SQL Tuesday #72

    tsqltuesdayThis month Mickey Stuewe hosts the T-SQL Tuesday and she has a great topic. Data Modeling is something few people seem to do, especially developers, and it often can go wrong. That’s the topic, and I have a short story.

    T-SQL Tuesday is a monthly blog party, on the second Tuesday of the month. The rules are on Mickey’s blog, and you can read them there, but essentially you write a post every month.

    Or later.

    The Aging Model

    I once worked at company that shall rename nameless. We had a system built before my time which had a hierarchical set of entities. I can’t disclose the exact industry, but imagine that we had a list of items like this:

    • Manufacturers of products
    • Distributors of products
    • Warehouse holding products
    • Vendors selling products.

    In this structure, we have a strict linkage where each item below the next is contained in the item above it. In other words, a manufacturer works with specific distributors and only those distributors. Distributors don’t work with other manufacturers.

    I know this sounds contrived, and it is for a supply chain. However not for the industry in which I worked. So imagine we’re 100 years ago when power was more concentrated with supply chains.

    This resulted in tables like this:

    CREATE TABLE Manufacturers ( manufacturerid INT IDENTITY(1, 1) CONSTRAINT manufacturer_PK PRIMARY KEY ( manufacturerid ) , manufacturername VARCHAR(200) , primarycontactid INT -- ... ); GO CREATE TABLE Distributors ( distributorid INT IDENTITY(1, 1) CONSTRAINT distributor_PK PRIMARY KEY ( distributorid ) , manufacturerid INT CONSTRAINT Distributor_Manufacturer_FK FOREIGN KEY REFERENCES dbo.Manufacturers ( manufacturerid ) , manufacturername VARCHAR(200) , PrimarySalesPersonid INT -- ... ); GO CREATE TABLE Warehouses ( warehouseid INT IDENTITY(1, 1) CONSTRAINT warehouse_PK PRIMARY KEY ( distributorid ) , distributorid INT CONSTRAINT Warehouse_Distributor_FK FOREIGN KEY REFERENCES dbo.Distributors ( distributorid ) , warehouse VARCHAR(200) , regionid INT -- ... ); GO


    Each of these links to the item above it. This means that I might have a Manufacturer  table like this:

    manufacturerid  manufacturername   …

    ————–  —————-  

    1               Acme

    2               Big Product Corp

    With warehouses linked as shown.

    warehouseid  manufacturerid warehousename   …

    ———–  ————– ————-  

    1            1              Denver Central

    2            1              Kansas City East

    3            2              Santa Fe

    4            1              Billings Depot

    This would mean that I used distributors that worked with a warehouse, and their data would be.

    distributorid warehouseid distributorname  …

    ————- ———– ————-  

    1            1            Denver City

    2            1            Denver South

    3            1            Aurora

    4            2            Kansas City Distributors

    5            3            New Mexico Wholesale

    If I wanted to get a list of the distributors that carried a manufacturer’s products, I’d have to join through the warehouse table.

    SELECT manufacturerid , ... FROM dbo.Manufacturers AS m INNER JOIN dbo.Distributors AS d ON d.manufacturerid = m.manufacturerid INNER JOIN dbo.Warehouses AS w ON w.distributorid = d.distributorid ...

    Not a big deal, but we had 5 levels of this appear over time. Which means that queries that might need a higher level had to cross tables in between to join data. These also weren’t narrow tables, with a decent amount of meta data for each entity. Indexing helped, but certainly we needed better rollups of data, and performance suffered as the amount of legacy data grew.

    What’s more, over time, we learned that business changes. A warehouse might start to work with multiple distributors, and our model couldn’t cope.

    Eventually we embarked upon a project that set of link tables between entities, so that we had just IDs in a table that showed linkages where appropriate. This was ongoing when I left, but it was a major disruption and problem for the company.

    I’ve tried to avoid embedding hard relationships based on business contracts in my models. Certainly some FKs make sense, like order details linked to a specific order, but many other relationships aren’t as tightly bound, and it is possible that they will change. It doesn’t cost me a lot in modeling to treat suspect relationships as many:many, and if application development does this from the start, it’s an easy architecture to incorporate in their development.

    Data modeling is always a struggle as we often work with incomplete information because an organization will morph over time. It is, however, worth taking some time to think about the possible ways in which things might change in the future and allow for some flexibility in your model where possible.
  • T-SQL Tuesday #70 – The Enterprise

    tsqltuesdayIt’s hard to believe this is the 70th edition of T-SQL Tuesday. I haven’t missed many, and I’ve enjoyed them all. I hope more of you are participating in this monthly blog party started by Adam Machanic (b / t). Whether you write today, or you write at some time in the future, T-SQL Tuesday topics are good ways to showcase your knowledge.

    This month’s invitation comes from Jen McCown, of Midnight DBA. Jen asks us to write about managing an Enterprise of SQL Servers. That’s a good topic, since many of us struggle to manage multiple instances. Whether you have 5 or 500, there are some good ideas that you might implement in any environment, and I’m looking forward to reading what people have to say.

    Decoupled Consistency

    A long time ago I was thrust into the role of managing hundreds of SQL Server instances at a large company. I’d managed dozens of machines before, but this was a whole new level of scale. What’s more, the majority of machines were set up completely independently of each other, with no concerns other than a mandate to try and keep versions close to each other. That was a challenge in and of itself.

    The only common tool in use was Patrol, which was mainly used to monitor performance counters, but we didn’t have the SQL Server specifics, so we really could only get general performance counters, and even those were difficult to access when thousands of hosts were being monitored.

    I brought an idea with me from a previous job that had served me well with a handful of disparate instances. We’d consistently set up each instance, both installation, configuration, and monitoring, however we’d decouple each instance from others. Our goal was each machine capable of operating independently from all the others.

    We had found that central servers go down, that we had no good way of tracking the status from machines when this happened, and most importantly, there are always exceptions.

    With this in mind, we

    • built a procedure to install SQL Server, but included a number of scripts for post installation that would standardize settings. This allowed our server build people to easily handle SQL Server installation as part of their job. These days I’d use something like FineBuild to make this easy.
    • set up a DBA database on each instance that monitored jobs and other important status for the instance. If the instance was up and SQL Agent running, we’d know the status of that instance.
    • Performed basic monitoring of some key performance counters for a quick trend of the latest performance over the last week, similar to what SQL Monitor shows. Getting a quick snapshot was quicker than accessing central monitoring, especially in a crisis.
    • Assembled a report for the instance each day, calling out exceptions at the top, and leaving expected data below. We needed documentation for our ISO certification, and our auditors loved this.
    • We did use a central server to assemble the reports from all instances and compile them for the DBAs to review. All exceptions were at the top, and we used a left join to compare the list of instances with current reports. If any were missing, we bubbled that to the top as an exception.

    These were all good, simple ideas that allowed a team of 3 DBAs to manage 400-500 instances of SQL Server. We were flexible enough to handle the needs of mission critical Finance instances as well as often changing development machines. Our data was simple and always available for us to give to clients when they had questions.

    Most importantly, we built a system that allowed us to deal with exceptions, but not review the mundane stuff. Our time was precious, and that’s the case in any enterprise situation. You need to focus on the 10-20% of systems that really need regular attention while ensuring the other 80-90% of them are still being maintained.

  • Catch up with T-SQL Tuesday

    T-SQL Tuesday is a monthly blog party where we get an invitation the first week of the month to write on a specific topic for the second Tuesday of that month. Adam Machanic came up with the idea and he chooses the hosts.

    If you’re interested in hosting, contact him.

    While there’s a sense of community and participation here, and certainly the chance to showcase some of your knowledge for others, it’s also got another benefit.

    It’s the chance for you to learn something.

    Not by reading other’s posts, but by writing your own. This is your opportunity to bolster your own skills, and teach yourself something new.

    Don’t Worry About Timing

    I know many of you are worried about the pressure of producing something good. I know many of you will find that the first weekend of the month is really busy and you can’t write.

    That’s fine.

    I’ve got a list of all previous invitations and topics. Go back and pick one of them and write your own post today. Start working on it, teach yourself something, and put some thoughts down. Research what others have done by looking through the roundups. Get a friend to review the work and see if it’s readable and makes sense.

    Do that ten times. It might take you ten months, but I’m sure you can write something down about SQL Server once a month.

    When you get ten, start a blog and publish them. Use the T-SQL Tuesday tag, but I’d also encourage you to use the #SQLNewBlogger tag as well. Start showing your boss that you’re improving your skills. Be ready to impress you potential next new boss with a series of posts on SQL topics.

    Your career will be better off, and the world will start to see better software being written.

    Start improving your skills this weekend, or start documenting the learning you already do. Either way, start building a better brand for your career.

  • T-SQL Tuesday #69–Encryption

    TSQL2sDay150x150This is a good T-SQL Tuesday topic for me. This month Ken Wilson asks everyone to write on encryption, which is a topic I’ve presented on quite a few times.

    You can participate, too. Take a few hours, learn something, and tell us what you learned. Let everyone know how you view this topic and grow your blog with a little new knowledge.

    T-SQL Tuesday is a great chance to force you to write a post on a specific topic. Your post needs to publish on the second Tuesday of the month, Aug 11 this month, to be included in the roundup from the host. However feel free to write about this topic anytime, and even include the T-SQL Tuesday title.

    CASTing Results

    A short post this month, as I’m a bit buried in a few things, but this is one of those encryption notes that I didn’t see well documented when I started working with the subject, and I’m hoping I can save you a few minutes of frustration.

    If you encrypt your data, it will be stored as a binary type. This is because encrypted data is supposed to be random, and not easily decrypted.

    Let’s imagine I have some simple setup like the code below. I’ll create a key, open it, and use it to encrypt some data that I’ll insert into a table.

    CREATE TABLE MyEncryptionTest( intsource INT, charsource VARCHAR(50), intencrypt VARBINARY(max), charencrypt VARBINARY(max));
    CREATE SYMMETRIC KEY Mykey WITH    ALGORITHM = AES_128 ENCRYPTION BY PASSWORD = 'M$test78';
    GO
    OPEN SYMMETRIC KEY MyKey DECRYPTION BY PASSWORD = 'M$test78';
    
    INSERT dbo.MyEncryptionTest
            ( intsource ,
              charsource ,
              intencrypt ,
              charencrypt
            )
    VALUES  ( 7, 
              'Spike' , 
              ENCRYPTBYKEY(KEY_GUID('MyKey'), CAST(7 AS VARCHAR(10))) ,
              ENCRYPTBYKEY(KEY_GUID('MyKey'), 'Spike')
            );
    
    SELECT top 20
     * FROM dbo.MyEncryptionTest;


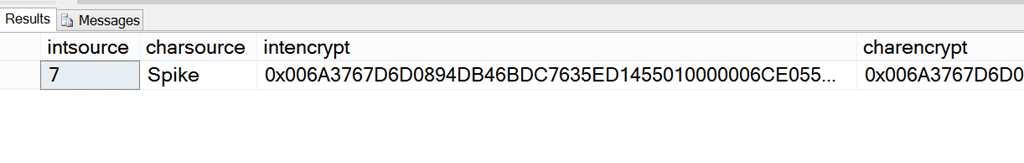
    The results of this are that I get binary data:

    2015-08-04 22_10_22-SQLQuery1.sql - ARISTOTLE.sandbox (ARISTOTLE_Steve (76))_ - Microsoft SQL Server

    Now, the decryption routine for T-SQL doesn’t need to specify the key. That means instead of a *, I can use the DECRYPTBYKEY function and pass in the column.

    SELECT TOP 20
            intdecrypt = DECRYPTBYKEY(intencrypt),
            chardecrypt = DECRYPTBYKEY(charencrypt) ,
            intencrypt ,
            charencrypt
    FROM    dbo.MyEncryptionTest;


    This gives me this:

    2015-08-04 22_12_22-SQLQuery1.sql - ARISTOTLE.sandbox (ARISTOTLE_Steve (76))_ - Microsoft SQL Server

    Not quite what I want. What if I cast this back to an integer? After all, the output of the function is listed as an nvarchar.

    SELECT TOP 20
            intdecrypt = CAST(DECRYPTBYKEY(intencrypt) AS INT),
            chardecrypt = DECRYPTBYKEY(charencrypt) ,
            intencrypt ,
            charencrypt
    FROM    dbo.MyEncryptionTest;


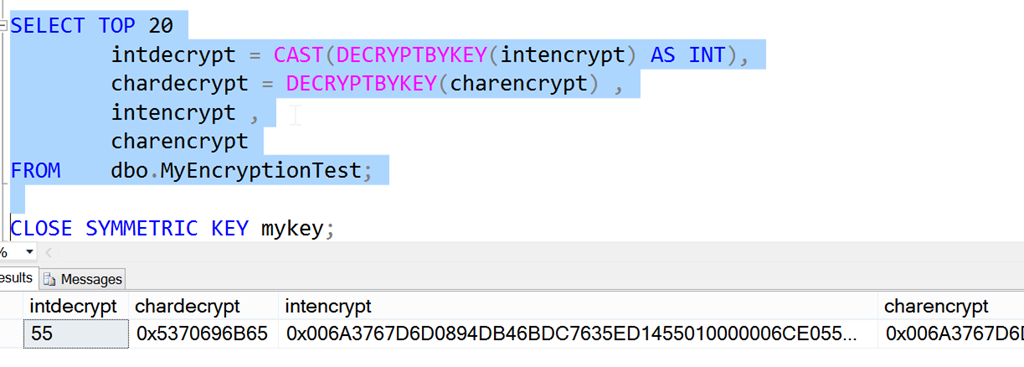
    I see:

    2015-08-04 22_18_10-SQLQuery1.sql - ARISTOTLE.sandbox (ARISTOTLE_Steve (76))_ - Microsoft SQL Server

    Again, not what I wanted. However, since I know something about conversions, I realize the output is close to what I want. In fact, what I need to do is perform a different CAST before I perform my final one. Here I’ll decrypt the results as NVARCHAR first, then as an INT.

    SELECT TOP 20
            intdecrypt = CAST(CAST(DECRYPTBYKEY(intencrypt) AS NVARCHAR(30)) AS INT),
            chardecrypt = DECRYPTBYKEY(charencrypt) ,
            intencrypt ,
            charencrypt
    FROM    dbo.MyEncryptionTest;


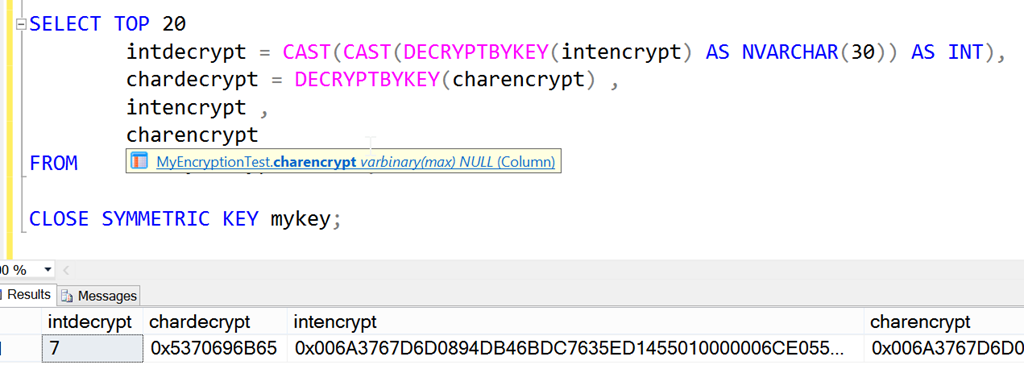
    Now I see:

    2015-08-04 22_15_29-SQLQuery1.sql - ARISTOTLE.sandbox (ARISTOTLE_Steve (76))_ - Microsoft SQL Server

    If I do the same for the character column:

    SELECT TOP 20
            intdecrypt = CAST(CAST(DECRYPTBYKEY(intencrypt) AS NVARCHAR(30)) AS INT),
            chardecrypt = CAST( DECRYPTBYKEY(charencrypt) AS VARCHAR(50)) ,
            intencrypt ,
            charencrypt
    FROM    dbo.MyEncryptionTest;


    I’ll get the correct results.

    2015-08-04 22_17_11-SQLQuery1.sql - ARISTOTLE.sandbox (ARISTOTLE_Steve (76))_ - Microsoft SQL Server

    Note that if I take the character column and cast to nvarchar, I’ll get something different. Try it and see.

    And don’t forget to close your key.

    CLOSE SYMMETRIC KEY mykey;