Tag: T-SQL
-
The Devil’s in the Details
This week I was scanning through a number of SQL Server posts (in between working on April Fool’s Jokes) and a couple of them caught my eye. They dealt with simple subjects, but subjects whose details are important. I’ve often found people have had performance issues in SQL Server because of simple misunderstandings of how the system works, or because not enough weight is given to the impact of small details.Kimberly Tripp (of SQLskills) wrote a basic post on parameters, variables, and literals, which would think most programmers would understand. However I realize more and more that lots of people that write code in the world taught themselves. That’s amazing, but it does mean that people have many different holes in their knowledge. What I might consider basic or common knowledge might be something that another person never had been exposed to. In any case, Kimberly does a fantastic job of laying out the differences in these three concepts, how they work side by side, and how the choice can dramatically impact performance of your code. Read this one.The other post this week was a fairly simple post on data conversions by Rob Sheldon. Again, precedence and conversions are something I dealt with when writing C code, and you do not want to get things wrong there. However many people might not have the same background and wouldn’t understand by varchar and nvarchar wouldn’t be a basic, simple conversion with little cost. Or why the type of conversion might result in far different results than you expect. Since we often test with one set of data and our application work with a (much) wider set of data, this one is a must read as well.There are so many things you should consider when writing code it’s really a constant and regular effort to improve your skills in this business. You won’t learn everything, or learn something every day, but pick things up and practice with them. Learn to build better code, one technique at a time, and cement that knowledge with actual implementation in your work.You’ve got at least two new things to look at this week, so pick one and try to ensure your code next week considers these details.Steve Jones -
Large Chunks of Data
This editorial was originally published on Sept 17, 2010. It is being re-run as Steve is on vacation.
I saw a post recently where someone talked about trying to get better performance from a report. They were selecting 5mm rows from a table and wanted to see if there was a more efficient way to chunk out this data so that the instance would not report memory errors.
My first question is what kind of report has 5mm rows of data? That’s just too much data.
How long can a report be?
From your experience, talking with people, looking at what they analyze, how big is a report? How much data can you really display on a report and make it useful for users?
I’m thinking here in terms of the raw data you show. A pivot table can summarize millions of records, but realistically I thin kit becomes hard to examine more than a few hundred data points on a page. Whether they are raw data or aggregates of other data, it seems there’s some limit to what a report should provide.
After all, that’s why we have drill-down 🙂
Let us know this Friday what you think; what you have observed? Maybe we’ll help others to build better reports that are more practical and useful to end users, as well as easier to develop.
-
New Blogger Challenge 1 – Adding a Primary Key
The April Blogger Challenge is from Ed Leighton-Dick and aimed at new bloggers, but anyone is welcome. I’m trying to motivate and cheer people on.
Primary Keys
I firmly believe that every table should have a primary key. At least until you have a reason not to have one. If you have a reason, fine, but if you can’t explain it or convince me, then just add a primary key.
I have tended to build tables like this:
CREATE TABLE Users ( MyID int IDENTITY(1, 1) , firstname varchar(250) , lastname varchar(250) , gender char(1) , postalcode varchar(12) , contactphone varchar(12) ); GO ALTER TABLE Users ADD PRIMARY KEY (MyID);
Lately I’ve not liked that as my primary key now has a name like [PK__Users__7131A74146D2BBC1]. I’d rather have a more organized database with a touch more effort.
The better way to add the key later is like this:
ALTER TABLE dbo.Users ADD CONSTRAINT pkUsers PRIMARY KEY (MyID);
This way I can name the key, and I specifically note this is a constraint, and with the PRIMARY KEY option, it’s a unique constraint.
References
A few places I searched around to double check myself.
- https://msdn.microsoft.com/en-us/library/ms189039.aspx
- http://stackoverflow.com/questions/11794659/add-primary-key-to-existing-table
Quick and Easy Blogging
This post occurred to me while I was writing some code. I mocked up a table in about 2 minutes, and then ran a quick search on the Internet. Reading a few links was about 10 minutes and then testing the code (including dropping the table and recreating it a few times) was less than 5 minutes. All told, I solidified some knowledge and completed this in about 20 minutes. I also have drafts and ideas from this post for 2 other posts that cover this same topic in a similar way.
Look for the other posts in the April challenge.
-
tSQLt with TRY..CATCH
Someone asked me the question recently about how tSQLt works with TRY..CATCH blocks and the exceptions that we might test for. It works fine, just as it would with other code, but you need to understand that a CATCH still needs to re-throw an exception.
Here’s a short example. I’ve got this query, which has issues.
SELECT TOP 10
cs.CustomerID
, cs.LastSale
, cs.Salesman
, CAST(cs.SaleValue AS NUMERIC)
FROM
dbo.CustomerSales AS cs;If I run it, I get this:
Msg 8115, Level 16, State 6, Line 1
Arithmetic overflow error converting varbinary to data type numeric.The CAST here has issues, but that’s fine. Perhaps it’s a data issue, perhaps something else. I can test for that, but for now, I want to be sure I handle these errors correctly.
Now, I embed that in a TRY..CATCH block.
BEGIN TRY
SELECT TOP 10
cs.CustomerID
, cs.LastSale
, cs.Salesman
, CAST(cs.SaleValue AS NUMERIC)
FROM
dbo.CustomerSales AS cs;
END TRY
BEGIN CATCH
SELECT @@ERROR
, ‘A CASTing Error has occurred.’
;END CATCH;
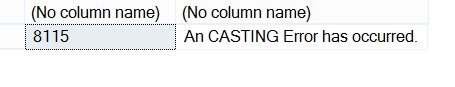
If I do this, and in the CATCH block I "handle" the error, I’m not really error handling. I’m error swallowing. Here are my results.
EXEC spGetCommission 12
I could log this, or try to return some data with a new query, maybe alter something that ensures the client gets results, but what I really need to do is give an error back, but one I’m aware of.
We could delve into error handling, but I won’t do that here. Instead, I want to be sure the application gets an error, when we have an error. It can then decide what the user does or sees.
If I write this test:
ALTER PROCEDURE [misc procs].[test spGetCommission Exceptions]
AS
BEGIN— Assemble
EXEC tsqlt.ExpectException;— ACT
EXEC dbo.spGetCommission @userid = 0 — int— Assert
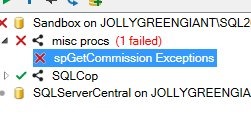
END;Now I can run it, but it fails. I see the failure
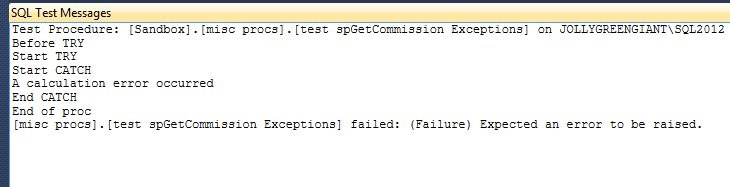
and I see this in the results
What I should have is something more like this:
BEGIN CATCH
THROW 51001, ‘An CASTING Error has occurred.’, 1;
END CATCH;Then my test should be looking for that message.
ALTER PROCEDURE [misc procs].[test spGetCommission Exceptions]
AS
BEGIN— Assemble
EXEC tsqlt.ExpectException
@ExpectedMessage = ‘An CASTING Error has occurred.’
, @ExpectedErrorNumber = 51001
;— ACT
EXEC dbo.spGetCommission @userid = 0 — int— Assert
END;If I do that, things work well. The error is handled, but also re-thrown, and my test passes.