Tag: T-SQL

  • Why Test Table MetaData Tests with tSQLt

    I wrote at SQLServerCentral about using tSQLt to check table metadata. In essence we are testing the API of our table. However, since the table could change, and may need to, what’s the value of having a test fail if the table changes?

    In my mind, I don’t necessarily want to have table structure tests for all my tables. After all, developers need to have flexibility to work with and change tables in our applications. If it’s a pain for a developer to change every table, because a test fails and they have to go change the test, that’s an issue.

    There’s also the problems of a developer changing a table, changing the test, and then having everything pass, without passing along information that a schema change was made.

    I would limit the API tests for a metadata to those tables that are important, with the caveat that anytime someone fails a metadata test, they need to inform the team.

    But Steve, isn’t every table important?

    Yes and no. Certainly all tables should be important to the application in some way, but really many of them are contained in the application. If changes are made, it’s not necessarily a problem to change other objects to catch up to the table change. However, some tables may cross teams or applications and they are an issue.

    As an example, I have lots of tables in the SQLServerCentral database.
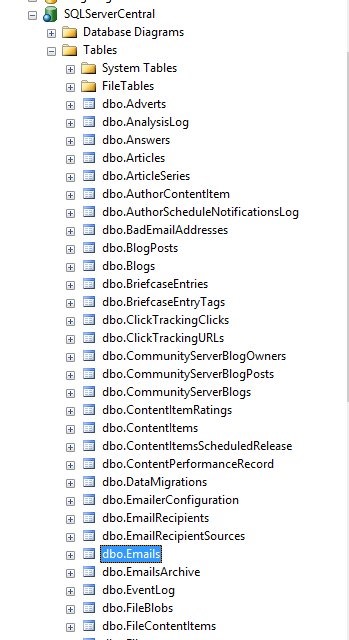
    tablemetadata_1

    If the Blogs table, or the Articles table changes, then we need to alter stored procedures and possible ASP.NET code for our application. In fact, in this list, pretty much all of these tables could be changed by a developer without a large impact, assuming they’re going to look at the other objects or code affected.

    However the table highlighted, the emails table, along with a few others, are important. These tables not only support SQLServerCentral, the web app, they are also called by our emailer process, which is a completely separate application. In essence, these tables are the opposite of a microservice. They’re shared.

    If someone wants to change the Emails table, I want to be sure that others are informed. In fact, I might choose to include a note in the test header that various groups need to be informed or that the table affects another application. In that case, before a developer went to change the test, they might at least have a chance or noting this has far reaching implications.
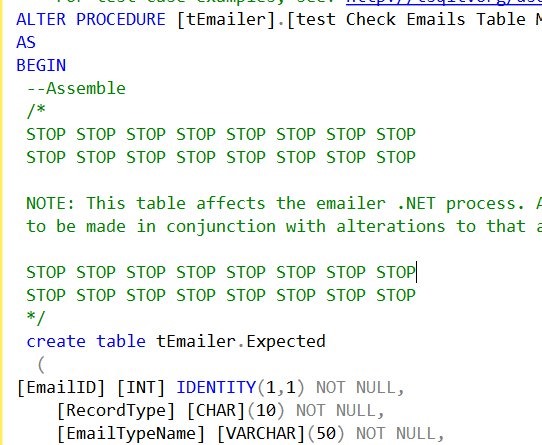
    tablemetadata_2

    It’s not a perfect solution, but it does help. The other thing I could do is limit access to metadata tests for various tables/views and merely call these tests in a CI, or other automated, process. That way failures would be public, and a variety of people could be informed, preventing a developer from making changes without a discussion.

    As I mentioned, I wouldn’t do this for all tables. In fact, I’d limit this to particularly sensitive tables that might require lots of rework if they were changed. We want to speed development, and ensure code works, not slow developers down.

  • Getting Database Properties – DatabasePropertyEx()

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    I had someone ask me a question about security recently, and while working through the answer, I ran across something I didn’t know well: databasepropertyex(). Here’s a few notes.

    Each database in SQL Server has all sorts of options and settings. Most people (including me) get in the habit of checking here for the information. First we right click the database (after starting SSMS if it isn’t running)

    dbproperty

    Then you get this dialog, with lots of stuff.

    dbproperty2

    And more on the other tabs.

    dbproperty4

    Time consuming, and error prone. As I get older, I find that trying to decide which selection is set for which option becomes harder. I find my finger tracing across the screen. It’s entirely possible I’d make a mistake when glancing at this to check the ArithAbort setting.

    Use T-SQL

    Scripting and querying is usually better. Not the sp_configure scripting where you get a whole list of options, but looking for a particular item. That’s where DatabasePropertyEx() comes in. This lets you query for a database property.

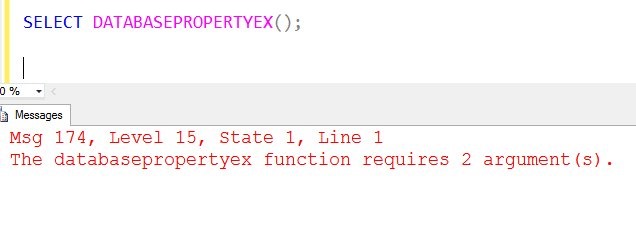
    The problem comes in when you run it. If you run the function, you get little information.

    dbprop_a

    Certainly you can go look at BOL to get more data, but that’s annoying. If I run sp_configure, I get data. However here, nothing. Even if I do what I think would be helpful, with a NULL parameter, I don’t get a list of stuff. SQL Prompt alerted me to the fact that the first parameter is the database, and the second is the property, but that doesn’t work.

    dbprop_b

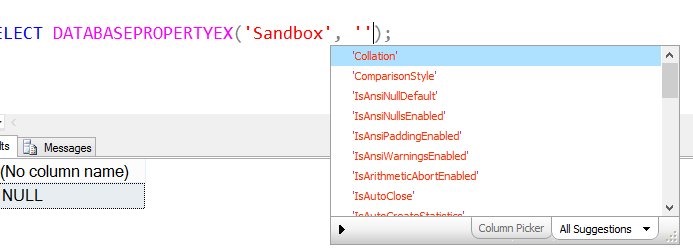
    Fortunately, I have SQL Prompt, so I get this when I put in quotes for the second parameter.

    dbprop_c

    As you can see, the parameters don’t map to the properties, though you can figure out what they mean if you see them. They tend to follow the conventions that most application programmers use (IsAutoClose).

    That’s fine, and it just means you need to have a reference handy for properties to query. I wish MS would give all properties with a NULL parameter, or a link to BOL.

    Writing

    This one took a bit longer to write. Once I realized I didn’t know databasepropertyex() very well, I had to read about it (5 minutes) and experiment a bit. I took some screen shots, which is always cumbersome. As I wrote this, I had to change the wording and ordering a few times to try and convey a simple message. I was originally going to look at more details, but decided to keep this simple and talk about just querying properties.

    This was about 30-40 minutes for me.

    You can do this. Join the #SQLNewBlogger group and start documenting your career. You can see all my posts that fall into this area by looking through the SQLNewBlogger tag here.

    References

  • Reframing to Overcome Filtered Index Limitations

    I’m continuing on with the Blogger’s challenge in this post.

    Turning the Problem Around

    In the last post, I wrote about limitations in filtered indexes. I proposed that my table had lots of data with NULL or blank spaces in the gender column, and I wanted to avoid indexing those rows. I tried this code

    CREATE INDEX Users_Gender_Filtered2
     ON Users (gender)
      WHERE (gender IS NOT NULL OR gender = ' ');


    However, that failed. I can’t use two sets of criteria in the filtered index. But I can use one, so I need to re-frame the problem.

    If I look at the data, I have four choices: ‘M’, ‘F’, NULL, ‘ ‘. I can group two of those choices together, looking for a positive (matching) set of data rather than a negative (non-matching set. The easy way to do that is with an IN clause.

    CREATE INDEX Users_Gender_Filtered2
     ON Users (gender)
      WHERE gender IN ('M', 'F');


    This works, and I’ve got a filtered index. In the real world, I’d actually drop the first index (gender is not null), and only go with this one.

    References

    A few places I used to research this post.

    Quick and Easy Blogging

    This post occurred to me as I was writing the other post. I almost added a note on turning the index around, but realized this is a separate topic, and it makes a nice, second post. This post required < 10 minutes.

    This post continues the April Blogger Challenge is from Ed Leighton-Dick, aimed at new bloggers, but anyone is welcome. I’m trying to motivate and cheer people on.

  • Idempotent

    I ran into the word idempotent in the Stairway to Integration Services. I had heard the word, but I hadn’t really considered how important it can be for a DBA or developer until that time. It’s a term used in computer science, as well as other sciences, but I think it’s one that many of us don’t consider when we’re writing code, especially code used to deploy software to other systems.

    Most of us have written scripts like this:

    if exists (select object_id from sys.objects where name = 'uspGetSales')
      drop procedure uspGetSales;
    create procedure uspGetSales
    as
    ...

    At the end of running this code, we have the system in a state. If we run this over and over, we’ll regularly return to the same state, which is often exactly what we want to occur. That works great when deploying code, but what about this:

    insert into states select 'CO', 'Colorado';

    If I run that multiple times, what will happen? Either I’ll get errors if one of these fields is a PK, or I’ll get multiple inserts. If I’m running this as part of a software deployment, do I want either of those conditions? Do I want my end user to experience either one?

    No, I don’t. Certainly if I’m manually making changes to systems I can probably avoid issues, but that’s not what I want to do. Maybe you do, but I don’t. I’d like to be able to restart my deployment if something fails, without causing other issues. I’d like idempotent code, like this:

    if not exists (select abbrev from states where abbrev = 'CO')
      insert into states select 'CO', 'Colorado';

    That way if I happen to run this code twice, or ten times, I arrive in the same place.

    I realize that building scripts and deployment processes that are idempotent is a pain. It’s work, but it’s also scriptable and repeatable work that is easy to automate over time with a few patterns. I also realize that a little extra work to prevent issues is often an investment that’s worth making for both my customers, and my reputation.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.1MB) podcast or subscribe to the feed at iTunes and LibSyn. feed