Author: way0utwest

  • Finding Sysadmins with dba tools–GetDbaRoleMember

    I really like the dbatools project. This is a series of PowerShell cmdlets that are built by the community and incredibly useful for migrations between SQL Servers, but also for various administrative actions. I have a short series on these items.

    I’ve been wandering through the dbatools set of cmdlets, trying to see where various cmdlets are useful, and also practicing some PoSh skills.

    Recently I noticed there was a Get-DbaRoleMember cmdlet to use. Of course, when I tried to check it, I found an issue. I didn’t have the cmdlet in my system. Autocomplete didn’t find it and running the cmdlet returned an error. I assumed that there had been a dbatools update, and I hadn’t gotten it.

    I run into this before, and a quick query to @sqlvariant helped me realize I needed to run update-module, not re-run import-module. I did that and it worked smoothly (I did need to be an administrator to update this).
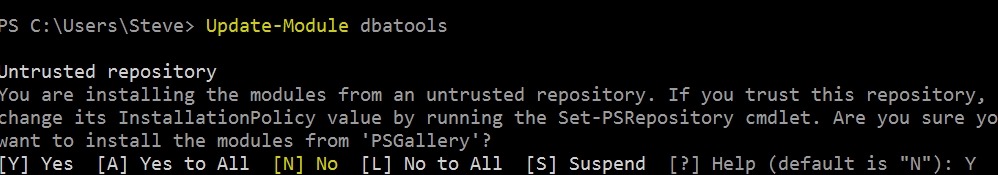
    2017-01-20 09_09_12-cmd - powershell (Admin)

    One I did this, I could run the cmdlet and get data.

    2017-01-20 09_09_55-cmd - powershell (Admin)

    Interesting, but this doesn’t seem incredibly useful. After all, I can easily query this in T-SQL, and my monitoring software will check to see if roles change.

    However, perhaps I am actually going to write something that checks to see if we have consistent sysadmins on all instances. Or perhaps we’re looking to add a sysadmin to an instance where he/she doesn’t exist. In any case, PoSh is a way to easily connect to multiple instances on many machines in a way that’s more cumbersome in T-SQL or SQLCMD.

    I can get the server level roles with –IncludeServerLevel parameter. When I do that, I see my roles and members.

    2017-01-20 09_51_34-Atlas Home Lab .201 - VMware Workstation

    I can also connect to remote servers and get this:

    2017-01-20 09_52_25-Atlas Home Lab .201 - VMware Workstation

    How can I do this in bulk? Well, I can certainly run this multiple times with a list of instances. Let’s make a quick list. I’ll make a quick array:

    $instances=”.\SQL2016″,”Atlas”,”Atlas\SQL2016″

    Now I’ll use that in a foreach loop, sending the server name to the cmdlet and looking for sysadmins.

    2017-01-20 09_56_36-Atlas Home Lab .201 - VMware Workstation

    And I have the sysadmins on all of my instances. Certainly this isn’t terribly useful by itself, but I can easily add more programming that looks for a user, maybe checks for which machines have a sysadmin, maybe add (or remove) a sysadmin from instances that are out of sync with what I need.

    This isn’t one of the cmdlets I’d use the most often, but I can see it being handy when trying to automate some of the permissions checks across multiple machines that I need to keep in sync. At the very least, this could be helpful in comparing permissions between primary and secondary (or DR) nodes.

    Note: I haven’t tried it, but I suspect that the migration cmdlets at dbatools would be better for keeping primary and secondaries in sync.

  • How Much Code Can You Review?

    When I was in college, I mostly wrote my own code for assignments (and fun), turning it in when I thought it was done. At some point I had a class that started to adopt more software engineering practices, and I was forced to get my code reviewed by a peer before handing it in. This was an interruption to my workflow (and more work since I had to review other code), but it did allow find mistakes I had made and seemed to improve my grade.

    In one of my first development positions, I had to get two people to review my code before I could submit it for deployment. A humbling and painful process at first, but over time I became used to the idea. I’m not sure the quality of code improved, but it was more readable, more in-line with everyone else’s code, and as we learned techniques that worked well, all developers adopted them quickly.

    These days as I talk with various customers and clients, I find that code reviews are handled very inconsistently. Some companies require them, some have automated processes, some have ad hoc reviews, and everyone has ways to circumvent the system. Certainly emergency patches need to be made at times, often with little review, but I will say that it seems the more common a set process and practice is, the less issues a customer has.

    If you review code, or have your own code reviewed, on a regular basis, I have question for you.

    How much code can you review for a deployment?

    The question I’m asking is about your process and habits. Is it worth reviewing every bit of code? Perhaps there are objects that you don’t worry about as much as others, or certain developers that receive more (or less) review of their code. Perhaps seniority makes a difference as to the level of scrutiny. If there are problems found in QA and changes made, is there a way to re-review code? I’m wondering today about your process. Share what you can, and if you want to do it anonymously, please feel free to send me a note at sjones (at this domain).

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 5.0MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • What’s a Database Encryption Key (DEK) in TDE

    The encryption mechanisms in SQL Server are interesting, and they work well, but they are somewhat poorly named. I ran across a few people struggling to understand, so I decided to cover the concepts in a series of posts. This one looks at the Database Encryption Key (DEK).

    The Purpose of the DEK

    The DEK is designed to actually encrypt and decrypt the data in your mdf/ldf/ndf/backup files when you use TDE. This key is passed to the AES algorithm and allows SQL Server read a block of encrypted text from disk and decrypt it before placing it in memory. This same process is reversed, with data from memory being encrypted before being written to disk.

    The DEK is created in a database, specifically for use with TDE and isn’t used in any other encryption process. The DEK also cannot be backed up, or restored, except with a database restore.

    Protecting the DEK

    The DEK is protected with a certificate. This can be a purchased or self-signed certificate, but in either case, the certificate must reside in the master database of the instance hosting the TDE encrypted database.

    When a DEK is created, the DDL requires that either a certificate or asymmetric key is specified as protecting the DEK. SQL Server will use this certificate (or asymmetric key) to decrypt the DEK when the database is first opened and then uses the DEK to encrypt and decrypt all data.

    Without the certificate that has encrypted the DEK, the SQL Server instance cannot access any data encrypted by the DEK.

    That’s about it. The DEK simply provides encryption for TDE, and exists only inside of a particular database that will use TDE.

  • The New SQL Server 2016 Edition Limits

    I was thrilled with SQL Server 2016 SP1. I’ve been asking for all features to be in all editions for a long time, and now we have most of the features available. There are still a few enterprise only items, but these are based on speed and scale, and not programming, and I can live with those. While I’d still like some “in between” edition that had higher limits than Standard, or even some sort of core/RAM add-ons, I recognize there’s a complexity in doing this that might not be worth undertaking.

    That changes in SP1 that allow features like snapshots, CDC, Columnstore indexes, and more mean there are some other changes that are important to understand. The SQL Server Tiger Team recently posted a note about some of the limit changes in SQL Server, showing how some of the memory limits have been raised with the new Service Pack.

    In the last few versions, SQL Server Standard Edition (SE) has been limited to 128GB of RAM in a server. While that might not be a lot to some of you, I’ve rarely had servers with more memory, so that’s been a good edition for me. However, when considering using Columnstore or Memory-Optimized tables, I could see why there could be some concern over memory shortages. After all, SQL Server really, really likes lots of memory.

    There still is a 128GB limit for the buffer pool cache in SE, but this is separate from the Columnstore cache and memory-optimized data stores. For Columnstore cache, you get an additional 32GB of RAM that can be used per instance. That means that if I use Columnstore indexes, I could use 160GB for caching data (128 + 32). What’s more, if I decide I need to use In-Memory OLTP tables, I get an additional 32GB per database to use here. If I have a single database with both features, that means I can use 192GB of RAM for data. If I have two databases, I could get 224GB of data in RAM. Of course, things aren’t quite this simple, and certainly, running out of RAM with In-Memory OLTP tables is bad.

    While these changes might not mean much for some people, I bet lots of customers will appreciate the chance to use these features, and not take any existing RAM away from their SE server. Of course, if you only bought a server with 128GB, you might want to get a little more before you start playing with Columnstore or In-Memory OLTP tables. And if you really need lots of RAM, Enterprise Edition now supports 24TB of RAM. I can’t wait to read a post when someone publishes their experiences on that system.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 6.9MB) podcast or subscribe to the feed at iTunes and Libsyn.