Author: way0utwest

  • Default Data Masking

    Dynamic Data Masking is a neat new feature in SQL Server 2016. I didn’t think much of it when it was introduced in Azure SQL Database, but since then I realize there is some value here. Even if it’s just making life simpler for developers.

    I’ve been experimenting with this a bit, learning how it works, and one of the options we have for masking data is to use the default option. However, what seems misleading to me here is that this doesn’t use a default from the column. Instead it replaces the values with

    • 4 x’s (xxxx) if the column size is > 4 characters (same for numerals)
    • the number of x’s that fit in the column if the size is < 4.
    • 0 for numbers

    This makes some sense, but not completely. I think I’d prefer to set a default mask for all types, so that I don’t disclose a value is a number or string (or date or anything).  I also see that NULLs are disclosed, another potential area I’d prefer to keep hidden.

    I also think the name is misleading. I’ d prefer to see this called something like xmask, or defaultmask, not default.

    If you want to learn more, you can look at a piece I’ve written to cover how this works, details on the default mask, or check out our list of resources at SQLServerCentral.

  • Do Less

    When I read this blog post, I was transported back to simpler times, when I learned to develop applications on 8088 processors. Back then, to make the system go faster, we learned to do less. It’s certainly true that the less work a system performs, the faster it can complete the limited set of things it must do. Working within C code, most programmers I knew back then tried to optimize algorithms by reducing the amount of work that our CPUs needed to perform.

    In T-SQL, we don’t have the low level of control we might have in other languages. In fact, our language has a relatively small number of instructions that we we use to build queries and applications, though that number continues to grow and expand over time. I am grateful for that, but also realize this brings with it additional chances for developers to write code that does more work than necessary.

    For much of our work, optimization consists of finding ways to group our operations together. Building a set-based solution takes advantage of the way in which SQL Server most efficiently processes instructions. Far too often there are developers that write inefficient code because they apply techniques they’ve learned from programming applications in some other language, or even from some other relational database.

    For a given system, there is a known amount of work that can be done in a period of time. There are also restrictions on the various resources involved (disk, CPU, network, etc). Reducing the load for each of these resources, especially in multi-user systems, can dramatically increase the performance of your system. SQL Server is built to manage concurrency in a variety of ways, but poorly written code is a great way to overwhelm the system.

    Do less. Get more performance.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.5MB) podcast or subscribe to the feed at iTunes and LibSyn. 

  • The OUPUT Clause in an INSERT–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    I got asked a question about the OUTPUT clause recently and realized I didn’t remember the syntax. I’ve rarely used this, so I had to look it up and thought this would be a good basic post.

    The idea with OUTPUT is that the data from the inserted and deleted tables can be output from the INSERT statement, outside of your triggers. This is the same data, but you can access it in the insert.

    The format is

    INSERT xxx OUTPUT yyyy INTO @zzz VALUES (or SELECT) mmmm

    The xxx is your normal insert target, table or view. The yyyy from the OUTPUT clause is a list of items to output. These is a comma separated list of fields in the format of inserted.col1, inserted.col2.

    The @zzz is a table variable. No inserts into scalar variables. This has to work with the set based nature of T-SQL. This means you’ll need to declare this variable. The mmmm is your normal insert stuff.

    Example

    Here’s a quick, short example. Let’s say  I have this table:

    CREATE TABLE MyCustomers
    (
    MyID INT IDENTITY(1, 1)
    , MyCustomer VARCHAR(200)
    , Active TINYINT
    );
    GO
    INSERT dbo.MyCustomers
    VALUES (‘Acme’, 1), (‘Roadrunner’, 0), (‘Bugs’, 1)

    I want to insert data into the table, and capture the identity value of MyID  as well as the name, separately from the insert. Note, I might really have a TRY..CATCH in production to deal with issues.

    If I add a new row, the identity should be 4. I want to capture this. I’ll first declare my OUTPUT variable.

    DECLARE @customers( id int, customer varchar(200);

    I don’t have to make this match the entire table, I can use a subset.

    Next, let’s build the INSERT. I want to capture the two fields from the inserted table, so we’ll include those.

    INSERT dbo.MyCustomers
    OUTPUT Inserted.MyID
    , Inserted.MyCustomer
    INTO @customers
    VALUES
    (‘Wile E Corp’, 1);

    I also need to output my table variable

    SELECT
    *
    FROM
    @customers;

    If I run this, I’ll see this:
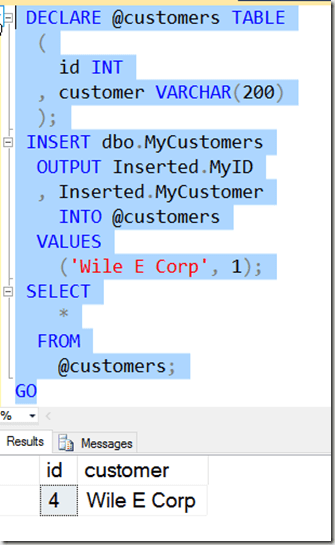
    2016-03-11 14_19_28-Settings

    Of course, I can do other processing with my table variable, using the output elsewhere in code.

    SQLNewBlogger

    This is a quick look at how you can use the OUPUT clause. This took me about 10 minutes to play with and remember the syntax, and 10 more minutes to write.

    I’d encourage you to play with this and write your own blogs. What can you discover about this construct?

    Reference

    OUTPUT – https://msdn.microsoft.com/en-us/library/ms177564.aspx
  • SQLBits in Space

    It’s coming in May. The official UK SQL Server 2016 launch event is SQL Bits and the conference returns to Liverpool on May 4-7.  With a fun theme.

    Check out the launch video here: SQLBits XV

    Update (Mar 24): The agenda is live. I’m speaking Saturday at 2:30pm.

    There are two days of pre-cons, packed with some great sessions, as well as two additional days of fantastic content and a fun party Friday night. You can register today, and I’ll see you there.

    Now, to find something to wear…