Author: way0utwest

  • Advent of Code

    I ran across this site after reading a post from Jeremiah Peschka. It’s an interesting idea, and since I’m trying to improve my development skills in between the rest of my work, I thought this would be fun.

    Advent of Code is a site that has a neat idea. A series of puzzles, two a day, that are released each day leading up to Christmas. Since we’re within the 25 days, I’m late (and so are you), but you can join in anytime.  It’s also cool since it’s a fixed font, console looking site.
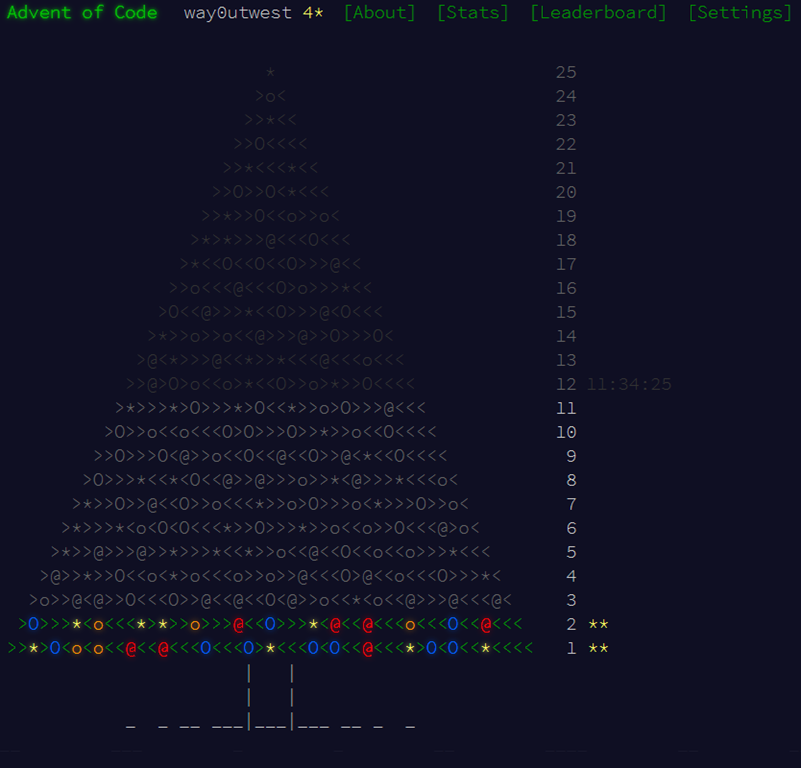
    2015-12-11 10_25_46-Jump List for SQL Server 2014 Management Studio

    The idea is that you get requirements for a puzzle, that you must code to solve. The inputs are too long to do by hand, though I suppose if you wanted, you could solve them in Excel. If you solve the first, you get the second.

    You can solve them however you’d like. I started doing some in Python, and also then re-solved them in Powershell. It’s mostly to just get some practice coding, and these are good excuses. I have been doing Python first, but I may switch to Powershell first, just to practice. If I get time, I’d like to redo them in C# as well.

    If you are looking to do some programming on the side, and practice something, this is a good way to focus on a particular problem and have fun. If you get stuck, there is even a subreddit with people posting questions and answers in a wide variety of languages.

  • How Much Eventual Consistency Do You Have?

    There’s a never ending debate about NoSQL v RDBMS systems that seems to polarize the people that prefer one technology over the other. In fact, it seems that every time I talk to someone that dislikes NoSQL technology in general, the topic of eventual consistency comes up. The idea that not all data in our system might be up to date seems to be one of the concepts that scares many DBAs most of all.

    I was chatting with some people recently about complex SQL Server configurations, and the topic of replication came up. While this is a technology with so much potential, it seems that replication has been a bit neglected by Microsoft and is both amazing and brittle in its implementation. However, if you think about it, replication results in data that isn’t consistent across the systems.

    I’m sure many would argue that this isn’t an issue, but how many of you have businesses that make decisions or have processes built on data in replicated databases? I’m sure plenty of you, and most of the time, the data is consistent enough for use by our clients.

    There are plenty of ways in which we implement data movement across our databases that results in potentially inconsistent results for our clients. In fact, I’ve had no shortage of discussions with clients that can’t understand why two reports run minutes apart show different results.

    Today I’m curious how many of you have systems that your businesses depend on where the data is eventually consistent because of some technology that moves information from one database to another. Perhaps you might even share some of the tricks you use to ensure that delays or problems in your transfer process are detected and fixed before your clients realize just how inconsistent their data might be.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.8MB) podcast or subscribe to the feed at iTunes and LibSyn.

  • Are We Engineers?

    This is probably a topic that is regularly debated in programming forums, but it’s still one that I think is worth revisiting regularly as our industry evolves. For those of us that write code, that develop software, are we engineers?

    That’s the topic of a piece in the more mainstream media. It’s a bit of an attack on the software industry in general, noting that engineers are typically certified and regulated. They are subject to continuing education and apprenticeship. While certainly many of us continue to learn, it’s very informal, and not structured. Our education certainly isn’t certified in any meaningful way, though we often aren’t even really liable for our work. The cost of bad code is usually a job, with another one often easily found.

    Engineering is defined as:  the work of designing and creating large structures (such as roads and bridges) or new products or systems by using scientific methods. By that definition, I think we are engineers. We use scientific methods, primarily the hypothesis, test, (usually) fail, change the hypothesis. The hypothesis we use are lines of code, which are often wrong and need work to get fixed. A additional definition includes: the design and manufacture of complex products <software engineering>. That’s us. Even the most trivial application today is likely seen as complex by layman. If most of us bothered to dig into the libraries we use, we might see them as very complex.

    We certainly aren’t engineers in terms of the formal knowledge and liability that exists in our profession. There is little, often because we can fix problems quickly. Or maybe because even if our systems fail, issues can be undone by additional work. That’s not always true, but it does seem as though those systems which are costly when they fail (medical, financial systems), have some recourse available to those affected. Not always, but there isn’t always recourse in the analog world.

    I wonder if we’ll get to the point where we require some evaluation or measurement of skills (or code) from software engineers for certain disciplines. My guess is not, as the world of software changes too quickly, and allows for too many different scales of acceptable performance to really certify anything. My guess is the world will continue to struggle with determining the liability and responsibility of software failure as we depend more and more on computing infrastructure in our world.

    Likely this is an argument that will never end.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.1MB) podcast or subscribe to the feed at iTunes and LibSyn.

  • Open Live Writer

    I’m writing this post from the Open Live Writer project software. I’ve used Live Writer for years, but it’s shown its age. Not the least of which is doens’t support OAuth2, so I haven’t been able to use it with my Blogger blogs.

    That should change, but we’ll see. Scott Hanselman noted there’s an open source fork of the software. I downloaded it today, and it’s slightly different, but not much. Mostly fonts from what I see.

    I may clone the project and see if I can fix things myself. There are some nagging items for me. However you should get the latest version and keep an eye on the project if you want a better blogging software tool.