Author: way0utwest

  • Idempotent

    I ran into the word idempotent in the Stairway to Integration Services. I had heard the word, but I hadn’t really considered how important it can be for a DBA or developer until that time. It’s a term used in computer science, as well as other sciences, but I think it’s one that many of us don’t consider when we’re writing code, especially code used to deploy software to other systems.

    Most of us have written scripts like this:

    if exists (select object_id from sys.objects where name = 'uspGetSales')
      drop procedure uspGetSales;
    create procedure uspGetSales
    as
    ...

    At the end of running this code, we have the system in a state. If we run this over and over, we’ll regularly return to the same state, which is often exactly what we want to occur. That works great when deploying code, but what about this:

    insert into states select 'CO', 'Colorado';

    If I run that multiple times, what will happen? Either I’ll get errors if one of these fields is a PK, or I’ll get multiple inserts. If I’m running this as part of a software deployment, do I want either of those conditions? Do I want my end user to experience either one?

    No, I don’t. Certainly if I’m manually making changes to systems I can probably avoid issues, but that’s not what I want to do. Maybe you do, but I don’t. I’d like to be able to restart my deployment if something fails, without causing other issues. I’d like idempotent code, like this:

    if not exists (select abbrev from states where abbrev = 'CO')
      insert into states select 'CO', 'Colorado';

    That way if I happen to run this code twice, or ten times, I arrive in the same place.

    I realize that building scripts and deployment processes that are idempotent is a pain. It’s work, but it’s also scriptable and repeatable work that is easy to automate over time with a few patterns. I also realize that a little extra work to prevent issues is often an investment that’s worth making for both my customers, and my reputation.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.1MB) podcast or subscribe to the feed at iTunes and LibSyn. feed

  • Can Auditing Fail?

    I saw someone’s list of requirements for a SQL Server auditing system recently that included many of the standard items most of us would want. DDL changes should be captured, along with configuration alterations. The performance impact should be low, and all versions of SQL Server must be supported. However, there was one requirement that surprised me. This person noted that the auditing must be asynchronous and the application should not be dependent on the auditing. If auditing failed, the application shouldn’t have any of its transactions limited or rolled back.

    I’m sure there are use cases where this is important, and where the auditing might not be critical, but the auditing data is available for informational purposes to troubleshoot any issues that relate to the database. However in many places where auditors review information, or the data is part of a legal record, the auditing cannot fail. If it does, then the application needs to stop working. If an audit is truly an audit of activity, then all activity must be audited.

    The C2 audit mode in SQL Server has been deprecated. Probably for multiple reasons, but It did seem that the idea that a failure in auditing could stop the database wasn’t a setting many people were willing to implement. To me, this means that auditing isn’t as important as having the system continue to process data. If that’s the case, then is auditing that important?

    I know auditing data can be overwhelming. I know that the management of audit data, including archival, is complex. I also know that most of the data isn’t very useful and will never be examined. However when we need audit data, we really, really, need accurate audit data. I really wish that Microsoft would integrate auditing better into SQL Server to ensure the data can be easily managed, compressed, and archived in an automated fashion.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.5MB) podcast or subscribe to the feed at iTunes and LibSyn.

  • Complete Definitions

    I saw a script from a user recently that looked like this:

        Create db x on file =
        go
        alter db set compatbility = 120
        go
        alter db set containment = none
        go
        ...
        alter db set service_broker off
        go
    

    That’s interesting because most of the code I see looks more like this

        create database x;
        go
    

    That’s it. At first I thought this was overkill, but then I wondered. If we are actually creating a new database for an application, shouldn’t we set the options the way that our application needs them rather than rely on defaults? I know that often many of us work with defaults on our instances and databases, but should we expect all configuration options to just be at their defaults? I know I certainly have been burned in the past with default changes.

    I’ve seen similar scripts for code, with SET ANSI_NULLS and other settings in the script. While I sometimes think that code gets in the way, I know that the script contains the settings that work for the code I’ve written and tested. If I remove those settings, it’s entirely possible that my code might not work. Do you know all the ways in which the various SET parameters for code affect your code? I’m sure that many of us don’t think about these changes when we’re writing code, assuming that the dev, test, and production servers will be the same as our database. In most cases they are, but not always.

    There’s a trend towards explicitly declaring the settings for an environment and then letting the system ensure that it maintains those settings when it’s built, or perhaps every so often. If that’s the case, and someone makes a mistake, say on ANSI_PADDING, do we really want to assume none of our code was compiled with those settings? I’m not sure I do, and I suspect that we should be explicitly putting all our settings at the top of scripts to ensure code behaves as we expect.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.6MB) podcast or subscribe to the feed at iTunes and LibSyn.

  • VMware and DBAs

    Disclosure: I’m a VMware fan and run it on my laptop. I definitely prefer it to other hypervisors. This workshop and all travel expenses was also paid for entirely by VMware.

    I was fortunate and grateful to be invited out to VMware recently for a multi-day workshop for SQL Server on VMware. Michael Corey wrote about the workshop here, which was an interesting way for VMware to reach out to the SQL Community and both talk to us about what they’re doing as well as get feedback from us on how SQL Server performs and interacts with the VMware platform. They will do more in the future, so if you’re active in the community or a heavy user, read Michael’s post and see if you can get yourself nominated.

    The week was full of speakers from both VMware and Tintri, a storage vendor doing interesting things. We had quite a few executives talking about their plans to make SQL Server run better, and we (as a group) provided lots of feedback. Certainly I think we helped to ensure executives understand that a database server is fundamentally different from a file server, mail server, or other workload.

    Of course, it wasn’t all work.

    Mrdenney

    I can’t talk about lots of what we discussed, as much is under NDA, but I will say that you should keep an eye on how VMware is going to improve their interaction with SQL Server. Hopefully we’ll see more products, information, and help at some of the SQL Saturdays and other SQL Server specific events.

    We also got a night out at ATT Park in San Francisco where the various attendees and speakers could interact in a casual atmosphere. An exciting game, with two of the best pitchers in the game throwing that night (Kershaw and Bumgarner).
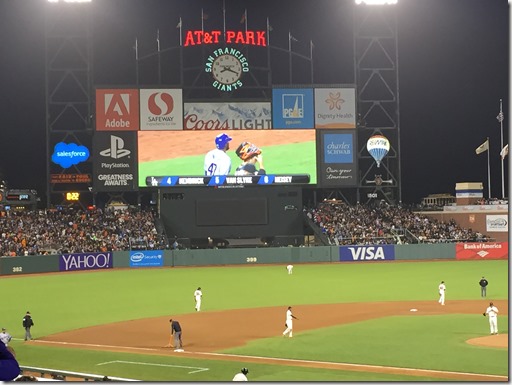
    Photo Apr 22, 8 19 09 PM

    I’d never been there, so it was a treat for me. I walked around and enjoyed the baseball game, the first one I’ve seen live in a couple years.

    Photo Apr 22, 8 26 19 PM

    Overall it was a very interesting time, with lots of points raised by everyone that I hadn’t considered or thought of. The more I hear about what the ESX platform does and handles, as well as hearing about how people have set up the platform. There are truly some powerful instances being run in a virtualized environment and I’m not sure there are many workloads that couldn’t be run successfully on VMware.

    I’m sure that there are hardware and budget restrictions for many people, but the issues aren’t VMware or virtualization, they’re the setup. In the labs we worked on, quite a few of the systems pressed a SQL Server instance hard, and the hypervisor and storage system kept up nicely.

    Photo Apr 22, 10 27 32 AM

    Not to disparage Hyper-V, but I haven’t had the experience there. I suspect both hypervisors could be tuned to a high level. Both also have some holes and places where the system might not run as smoothly as you’d like, but at least I think VMware is more aware of what we, as SQL Server professionals, see as problems.

    Tintri

    I have to admit that I have mostly though of storage as a utility. It needs to work and respond fast, but beyond that, I don’t care about it. It’s like a water faucet. I turn it on and it works.

    Tintri was the guest storage vendor that provided appliances for us to use. I didn’t’ think much of them on Tuesday morning, but by the time their founder had talked with us, I was very intrigued. I still don’t really care about storage other than needing it to work, but I was very intrigued by how this particular product works.

    Most storage is presented as a LUN to a host, which may or may not share that among guests running on a box. Tintri changes that, with what they call VM aware storage, with VM level QOS. Essentially, the storage box is aware of each guest connected as a VM. It manages the storage response and bandwidth on a VM basis, with separate FIFO queues for each drive in the VM. Essentially each VM is treated separately and the storage capabilities (min and max IOPS) can be managed separately.

    It seems as though VMs get better response from the appliance this way, with less dependency on heavy management by storage admins. They also use a lot of flash memory (SSDs) with disks to ensure fast responses. They do 100% write to flash for speed and tune the systems to aim for 99% reads from flash. Because the device is aware of VMs, it can move blocks around from flash to disk to ensure that the heavily used data is quickly available.

    If you have heavy needs, check them out. If you’re looking for a SAN, I’d look at them as well. Not sure what the pricing is, but I bet it’s competitive with other SAN devices.

    We also got a lecture about low level storage technologies from a VMware exec. The talk looked at the advances taking place in storage, which seem to be finally leaping forward. With the price of SSDs crashing, and the research into 3D flash, it seems that though more and more of us might move to flash based SAN storage quicker than we expect. Fascinating stuff, and I suspect that database systems will start to see better performance from hardware upgrades across the next 6-7 years.

    A Break

    It was nice to get away and learn something without any pressure to work on much else. This was a short workshop, close to home, and in an area that had me concentrating and paying attention in ways that sometimes don’t happen at SQL Server events. I enjoyed it, and I learned quite a few things.

    Photo Apr 22, 10 27 27 AM

    I’m not sure how much I’ll use this stuff moving forward, but I am thinking that I’d like to play around with an ESX server at home and use that to experiment with SQL Server features and especially setup. I’m looking forward to trying to get a system ready that can build a new SQL Server instance in minutes.