Author: way0utwest

  • Pausing the Learning for March

    In my last update, I was disappointed with my February progress. Busy with life and work, I didn’t do much reading or practicing. The latter is really the important part.

    I started March thinking I’d do a bit more, but I realize that won’t happen. I tried a little over the weekend, but with coaching responsibilities and family items, I just couldn’t really focus.

    March is a busy month for me outside of work. I have 3 major weekend volleyball tournaments with my daughter and my team, some travel for work, and still family commitments. In addition, I’ve started authoring a course with Packt, so my nights will be busy.

    As a result, I’m going to pause learning for March. Once I get past a few of these deadlines, I’ll go ahead and start reading again. For now, March will be heads down with SQL Server 2019.

  • Common Data Challenges

    Working with data has proven to be a challenge for most of my career. It’s been fun, and certainly fulfilling, but there are constant challenges involved. Let’s take away the hardware and admin challenges of keeping systems running, backed up, and performing well. I’m thinking today of the struggles of just data.

    There is a short article that talks about three common data issues, and these are some of the same ones I’ve struggled with for most of my career. Are these challenges any different than they were 20 or 30 years ago? I’m not sure, and I was working with databases and software nearly 30 years ago.

    ETL is a constant challenge, even today with tools like SSIS and Biml that make it much easier to build flows that migrate data from one database to another. ETL is such a challenge that many people make a very comfortable living helping organizations meet their every changing needs to move and prepare information for end users.

    The other challenges noted in the article are getting a complete data picture because of missing data and not trusting or believing in data. The latter hasn’t been as much of a problem for me.  I might describe it differently as more often we aren’t sure what weight to place on certain data. The world is messy, and often we collect data that we think might be valuable only to realize later that it doesn’t mean what we thought or our our hypothesis was incorrect in the first place.

    I think the challenges are part of what makes this work interesting. Our employers and clients might view the effort and time involved as frustrating, and I wish I had solutions to make our process quicker and smoother. Actually, I do think that advances like SSIS have made things quicker, but the world has grown more complex. We deal with more data from more systems, in the still chaotic, messy formats of the world.

    What are your challenges with data today? Are they getting better, worse, or still the same as they always were?

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.4MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • Pushing SQL Change Automation Code to Azure DevOps

    Making changes on your own system for a SQL Change Automation project is great, but if you’re the only one using the project, it might feel like a lot of overhead. I’d argue it isn’t and it’s a better way of building software, but that’s a separate discussion.

    For most of us, we need to get a good copy (and backup of code) as well as share this with others. In the previous article, I was making changes in my own SQL Change Automation project. I was committing these to a local git repo and now I want to put them into another place. This article will look at moving my repo to the cloud.

    Enter Azure DevOps

    I love Azure DevOps as a software development platform. It has everything I need, hundreds of extensions, and I can easily replace parts of it with other technology if I want. I could use my own git repo locally (or at BitBucket) and still build/release with Azure DevOps. I could use the Azure DevOps repos and build my software with Team City. Or release it with Octopus Deploy.

    I have flexibility.

    For me, I’m going to stick with Azure DevOps in this series, and I’ll show you how to add a project to Azure DevOps.

    Sign In to Visual Studio

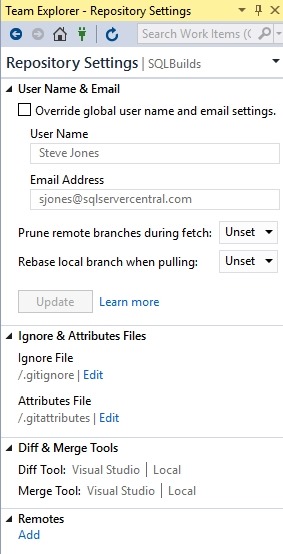
    When I created this project, I used a git repo as the default from Visual Studio. However, as you can see, I didn’t add any remotes.
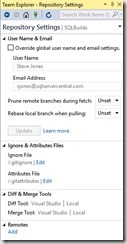
    2019-02-28 16_11_35-SQLBuilds - Microsoft Visual Studio

    I did log into Visual Studio at some point when I started it, and since I’ve used this before, I have a number of connections to different services. You can see below my connections in Team Explorer.

    2019-02-28 16_12_31-SQLBuilds - Microsoft Visual Studio

    If you go to dev.azure.com/name, you can see your organization. For me, this is https://dev.azure.com/SteveJonesRedgate/. When I log in, I see my organization, and a list of projects.
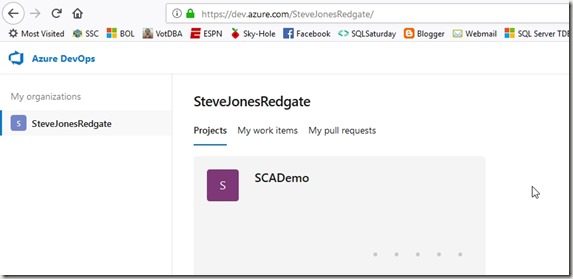
    2019-02-28 16_18_38-Projects - Home

    In the upper right is a “create project” button, and I’ll click that. When I do, I get a blade to enter some data. I can do that, and I’ll make this public, so anyone can see it.

    2019-02-28 16_19_25-Projects - Home

    The project is created, and I get a welcome screen. For now, let me ignore this and go back to Visual Studio. If I click the Sync item in Team Explorer, I’ll see this:

    2019-02-28 16_22_46-SQLBuilds - Microsoft Visual Studio

    VS sees my account. If I click advanced, I can see the projects, and I’ll select the one I just created.
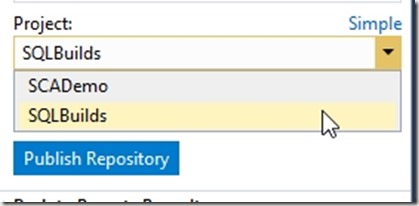
    2019-02-28 16_23_10-SQLBuilds - Microsoft Visual Studio

    When I click publish, this moves the repo up to the web. If I return to my project online, I can click “Repos” and see the code.

    2019-02-28 16_24_19-SQLBuilds - Repos

    This is the structure as my local VS project. If I had make a screen shot of the before, this would be an empty space online, with instructions for connecting local repos, adding files, and more.

    A Backup Copy

    From here, I can continue to do local development and push/pull as necessary between my local project and the online repo at Azure DevOps. I can set up branches and do more. This is also my backup in case my local storage crashes. From here I can pull down copies of my code if needed.

    In the next article, we’ll look at how we get code from this repository onto another machine.
  • The Data Incident

    I was reading a Google whitepaper and I think this was the first time I’d seen a potential loss of data referred to as a data incident. The paper deals with the response from the Google Cloud team if there are potential data loss issues, outlining a four part process for responding and ensuring the customer can get back to work. Azure has a similar plan, though AWS seems to expect the customer to do more of the work.

    This is the first public disclosure of a process, and it’s a good one. In fact, everyone should use this or have something similar in their organization. The way that the world seems to be moving, it’s likely that most of us will suffer a breach at some point, and we ought to know how to respond. Without some plan, it’s easy to have a situation spiral out of control.

    I’ve had formalized DR plans as well as incident responses for events such as a DDOS or virus attack, but the issues with data are somewhat different and probably deserve a dedicated plan of some sort. While I’ve often seen these handled under the security team response, that might not be enough for data services, especially when you have responsibility for data that is different than managing a software system or service.

    Data security is becoming a more important part of the data professional’s job, with legislation and best practices starting to require that we recognize a shared interest in sensitive data that extends beyond our organization. Whether this is something you like or dislike, it is becoming a part of our work.

    Personally I like having a crafted plan that is available for use in crisis situations. It can be hard to remember all the possible issues, and certainly crisis seem to occur when our best people aren’t available. Even more important, a plan means we have something we can practice to be sure that everyone understands how to react, limit the exposure of data, and even ensure that we can get services back up and running as soon as possible.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.4MB) podcast or subscribe to the feed at iTunes and Libsyn.