Author: way0utwest

  • Rolling Back Migrations

    I happen to be a fan of database migrations as a way of making and deploying database changes. This is an approach that tracks each of the scripts run by developers in their working environments and the replays these scripts in production to deploy the changes. It works really well, and is the most bulletproof method I know of for ensuring the changes will work in production. That’s not to say there aren’t issues, but it’s the approach I favor. It’s a part of what SQL Change Automation from Redgate Software does, and it’s also what Microsoft and other companies see as the future of database deployments.

    This is in contrast to making changes in development and then using some technology such as SQL Compare or Schema Compare in SSDT to create a script and use that to deploy changes. That works very well for many people, but I do find that most customers outgrow the technology with certain changes that don’t lend themselves to this state or model based method of script generation.

    In either case, rollbacks are a concern for many DBAs and developers. After all, the database is a stateful service, as our data must be maintained over time and there are certain changes that are difficult to rollback. While many developers that might have renamed an entity or added a column might be tempted to just reverse the change, this isn’t always easy to automate, especially in most of the tools we use. Often we depend on the skill of a particular individual to manually execute the reversing DDL, and possibly determine what to do with any data that was changed.

    I ran across another developer that things migrations are a better way, and that in a year of development, they never had to roll back any changes. While I agree that migrations is a more reliable process, I do think that assuming you’ll never roll back a deployment is highly optimistic. I’ve had tales of application developers being out of sync, of other applications not working with a new version of the database, and more. Some of these might be fixed with a quick roll forward, but ultimately I think that there needs to be an easy way to make rollbacks normal.

    The one downside of migrations is that the reversing transactions can be complex, since each migration script might make complex changes moving forward. There isn’t much help from most migrations tools, whether that’s SQL Change Automation, FlywayDB, Entity Framework migrations, and more. These tools can certainly generate reversing code for simple changes, but any sort of complex alteration requires custom code.

    My view is that a few simple rules govern how I view rollbacks. For views, procs, functions, I’d grab the previous version from our VCS and re-deploy that. I might try to run through a DevOps pipeline, but if I were in a hurry, I’d grab the code and run it. I’d also then recommit the old version as the latest one. For tables, we should write reversing migration scripts for any entities that are risky. Risky meaning this might affect my employment status. I’d be sure I had a second deployment pipeline that I could use to run these scripts in QA, staging/pre-prod, etc. after we’d verified the code we were deploying. I’d then have checks to ensure we really were reversing the changes.

    The last rule I have is that I use time to make deployments easier. I would never add new columns and drop old ones in the same deployment. If I move or change data, I’d always ensure the old versions of data remained. That way I could reverse changes without problems. I can always do cleanup in a later deployment that just removes objects or data, but I want to be sure that old data is really no longer needed. That means I need to be organized and have a good calendar system to scheduling future cleanup work as well.

    Migrations are really a better way to do database deployment, whether you’re working in a relational system, or you might be altering documents in a NoSQL system. Replay the changes you’ve made in development, that you are sure worked on “your” machine. You’ll be more confident they’ll work on another machine.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 6.4MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • Data Classification in SQL Server 2019

    One of the areas that Redgate is working on is making data classification easier. Microsoft added some capabilities to SSMS 17.5 and Redgate has an EAP out for the next version of our data catalog tool.

    Azure SQL Database has had some advanced options they were building into the database engine, and we get our first look in the on-premises version with SQL Server 2019 CTP 2.0.

    The ADD SENSITIVITY CLASSIFICATION and DROP SENSITIVITY CLASSIFICATION DDL is now available, and here are few examples of how this works.

    Let’s look at a database that has some potential data to classify. I’ve got a sample database with a few tables. In fact, if I look at the data classification suggestions in SSMS, I see 7 columns.

    2018-10-23 11_56_48-Data Classification - SimpleTalkDev_Steve - Microsoft SQL Server Management Stud

    I can accept any of these, but if I do, these are written to extended properties, which isn’t the best way of storing this data.

    However, the ADD SENSITIVITY CLASSIFICATION syntax works well. If I take that dbo.Contacts.Email column and decide this is Confidential according to the GDPR, I can do this:

    ADD SENSITIVITY CLASSIFICATION TO
      dbo.Contacts.Email
      WITH (LABEL = 'Confidential - GDPR')

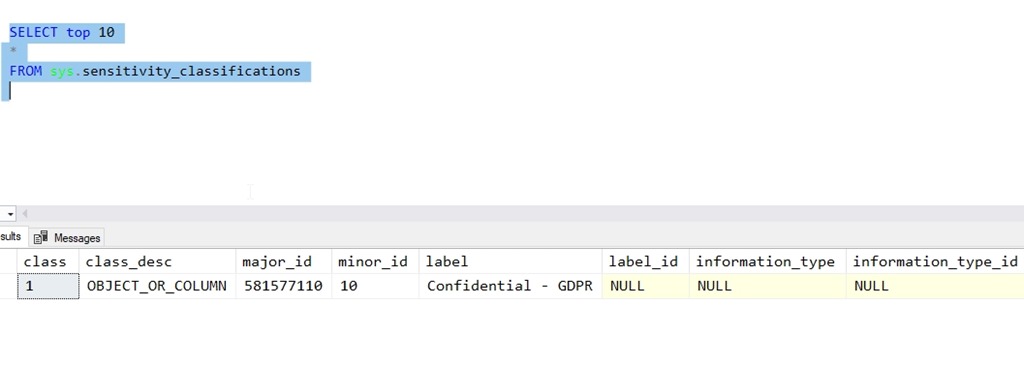
    If I then query my meta data table, I’ll see this:

    2018-10-23 12_01_04-SQLQuery4.sql - Plato_SQL2019.SimpleTalkDev_Steve (PLATO_Steve (61))_ - Microsof

    There are other items I can add, such as the information type and then IDs for the label and type. I can, however, update that data like this:

    ADD SENSITIVITY CLASSIFICATION TO
       dbo.Contacts.Email
       WITH (INFORMATION_TYPE = 'Contact', INFORMATION_TYPE_ID = '5BFAE3B8-4549-4989-BEB6-F9BF6434DAD1')

    Note I still haven’t given the Label_ID a value, but that’s OK. This allows me to add human readable metadata to columns, as well as add IDs that I might get from some external auditing system.

    2018-10-23 12_04_01-SQLQuery4.sql - Plato_SQL2019.SimpleTalkDev_Steve (PLATO_Steve (61))_ - Microsof

    This feels primitive, but it’s slightly better than extended properties, and it’s somewhat built into the engine, so we can code this as a part of development and ensure classification is added to our sensitive data.

    If this is an area you’re interested in, we’d love to have you try the Redgate tool and give us feedback. We’re working on this problem and trying to find ways that are both useful and sustainable over time.

  • Webinar: The end of support for SQL Server 2008

    Coeo is a partner with Redgate Software. Tomorrow they are hosting a webinar on what your position will be if you are still running SQL Server 2008 or R2 now. Extended support ends next year and now is the time to start your preparations.

    Register now and tune in tomorrow, or whenever you have time.

  • Better Keyboard Extensions in Azure Data Studio

    I used to use ALT+X to execute queries in SSMS. I spent years with this shortcut, but as I started to present more, CTRL+E felt more natural. I’ve now grown used to that, so when I typed CTRL+E in Azure Data Studio (ADS), I was less than pleased.

    2018-10-19 17_06_57-● SQLQuery1 - Azure Data Studio

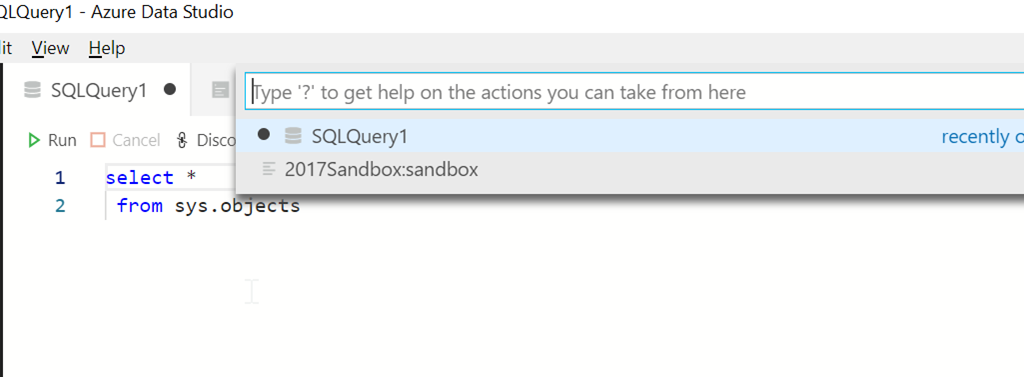
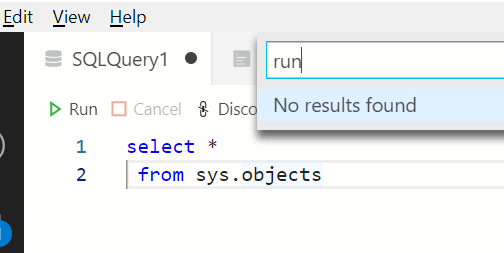
    Even trying to get help here didn’t help.

    2018-10-19 17_07_18-● SQLQuery1 - Azure Data Studio

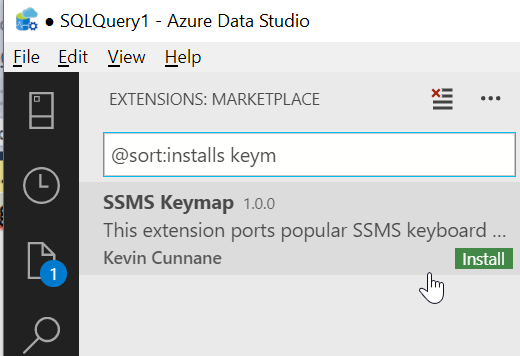
    I actually had a conversation with Kevin Cunnane when this was SOS and he pointed me to the keymap extension.  You can get this by clicking the extensions icon on the left side of ADS:

    2018-10-19 17_12_50-● SQLQuery1 - Azure Data Studio

    Once you do this, search for keymap, and you’ll see Kevin’s extension.

    2018-10-19 17_13_03-● SQLQuery1 - Azure Data Studio

    You can see details for the extension on the right.

    2018-10-19 17_18_34-Extension_ SSMS Keymap - Azure Data Studio

    When you click “Install”, you’ll go to Kevin’s repo on Github. Click the link to download the VSIS extension. This gets saved in your Downloads folder (or wherever you have downloads going).

    Go back to ADS and use the File menu to find the VSIS installer.

    2018-10-19 17_18_28-Extension_ SSMS Keymap - Azure Data Studio

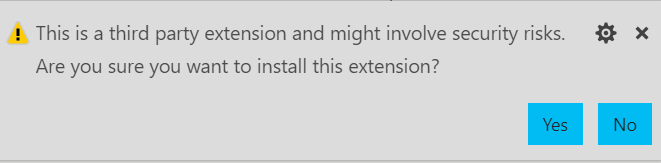
    Browse and double click the VSIX file you downloaded. You’ll see a message in the lower right of ADS.

    2018-10-19 17_19_48-Extension_ SSMS Keymap - Azure Data Studio

    Click Yes, or no, but if you click No, this won’t install. In a few seconds, if you clicked Yes, you’ll see this:

    2018-10-19 17_19_57-Extension_ SSMS Keymap - Azure Data Studio

    Click Reload, and ADS will close and reopen. Your query window should still be there, and CTRL+E will pop the connection dialog, since the connection closed. Once you connect, the query will run with CTRL+E

    2018-10-19 17_20_10-● SQLQuery1 - Azure Data Studio

    The full list of key mappings is available on the repo or in the package.json file.