Author: way0utwest

  • Data Has a Dollar Value

    It seems that every year we see new ways of analyzing information that companies are adopting. In this era of Big Data, with the challenges of real time BI analysis of (often) streaming sets of data, companies search for ways to handle the load. We had map-reduce methods to process bits a few years back and lately there has been a growing popularity of machine learning (and deep learning) used to gain insights from the massive data sets we have.

    The problem is that in trying to analyze data, we find that we often don’t have enough data in many cases. While some parts of our organizations face a surplus of data, others trying to provide an analysis might face a shortage, at least for some types of data. This might be especially true when business people want to engage in a new type of business or a new way of working with customers.

    The last couple years have given rise to a number of companies that actually are gathering and selling labeled data, or even generating synthetic data that can be used to build and train models for analysis. As we look to let machines learn to solve some problems on their own, we need to provide them lots of data, which has become big business. I have heard of companies paying six or seven figures a year to get data sets for their data scientists.

    In some sense, as noted in this keynote, data is the more valuable part of these systems. Staff matters, and certainly the software and models are important, but the data is key. Good data, with lots of features, can produce a better trained system than poor data. Many of us that work in traditional software know this as well. If we use poor data sets in development, with limited values, and not in the skew and selectivity that we’ll see in the live system, we often build lower quality software with more bugs.

    In some sense, I think that our data is more valuable than we realize, and far too many developers don’t take advantage of using the data our organizaition does have to build features and properly test them. Actually, too few of us actually test things well, but certainly we often can’t without a good set of data. I’ve been disappointed with random generators, though they are useful in that they can find unexpected issues from the random values, including NULLs, that will creep into systems. I really wish we had better subsetting tools that would help us use a portion of our production data. Redgate is working on tooling, but I’d think this was a problem we’d have gotten better at solving, between software people and database staff.

    I’ve had a nice career working with data, and I’m glad that the recognition of the value of data has continued to grow through the years. Now I’d like to see us actually start to emphasize the importance of producing and using more useful data sets when we build software, whether in traditional means or using machine learning techniques. My guess is we’ll get more useful and better quality software if we do.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 4.0MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • The Best Days

    I recently asked about the worst days in your career, so today let’s turn it around. What are the best days of your career? If you can give us a list of 2 or 3 days, projects, accomplishments, etc., it might be fun to read.

    Throughout my career, I have lots of little successes where I accomplish something that a client needs. Those add up, and they’re good, but by nature there are so many and the numbers tend to blur the lines in my mind. Unfortunately, the mistakes I’ve made tend to be more memorable and stick in my mind. I really have to think about what I would consider the best days.

    There are a couple software deployments that I consider to be successes, though none overly memorable. Getting my code into production is great, but rarely is a change a huge win. Instead, it takes time for clients to use the code, to understand the impact, and for me to be sure that the code works as expected.

    I remember getting our first automated deployment done, almost twenty years ago, when we had moved from a manual process of collecting scripts and trying to ensure they were correctly ordered and contained all the changes we needed. After weeks of working on an automated process to collect, order, and execute scripts, we tested things in QA. Then a day later in production. Overall this was a non-event, with the deployment taking minutes. The change from constantly checking scripts, results, and manually executing code was amazing and the reduction of time spent getting ready was notable.

    I also remember a great day as a DBA, when we experienced a server crash and had to rebuild new hardware. I was away with family, but I knew my backup and restore procedures were ready. I walked a manager through restoring a database, using a script to automatically build the log restore scripts, and then executing those scripts. While driving with my family, completely hands off, I helped recover a database.

    I hope you have some good memories of your career, and can share one or two today.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.0MB) podcast or subscribe to the feed at iTunes and Libsyn.


  • Format a Partial Script with #SQLPrompt

    SQL Prompt is amazing and it’s my favorite tool. It’s actually what many people want first from Redgate because it makes coding much easier. One of the most used features is the reformat feature (CTRL+K,Y), since formatting really matters to developers.

    One of the neat features of SQL Prompt is that you can format just a portionof your script. That means if you’re working on a large script and want to reformat just a part of it, you can.

    Here’s how:

    • Highlight the code
    • Hit CTRL+K,Y

    promptformat

  • Getting the Role Permissions–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    If you are wondering what permissions a role has, and don’t want to spend time searching and digging through Books Online, there are a few system procedures that can help. These will give you the permissions for a role, or all roles.

    Let’s see how to use these.

    Server Role Permissions

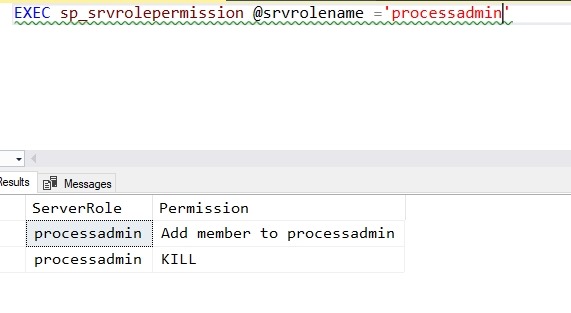
    Let’s say that you are wondering what a Processadmin can do. There is a procedure, sp_srvrrolepermission, that you can use to get the list of permissions. This can be run with no parameters, in which case you’ll get all roles and all permissions.

    2018-07-03 14_46_01-SQLQuery9.sql - (local)_SQL2016.EmptyFileTest (PLATO_Steve (74))_ - Microsoft SQ

    However, often you’ll want a more manageable set of data that a person can understand. Let’s see what processadmin can do.

    2018-07-03 14_45_47-SQLQuery9.sql - (local)_SQL2016.EmptyFileTest (PLATO_Steve (74))_ - Microsoft SQ

    Only two permissions here, so I can see that granting this isn’t going to affect security or databases.

    Database Roles

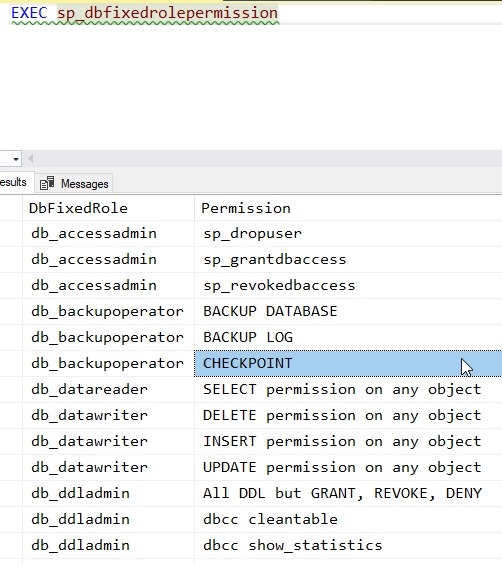
    The database has a related procedure, sp_dbfixedrolepermission, that looks for database roles. This can again be run without any parameters, as shown here.

    2018-07-03 14_50_24-SQLQuery9.sql - (local)_SQL2016.EmptyFileTest (PLATO_Steve (74))_ - Microsoft SQ

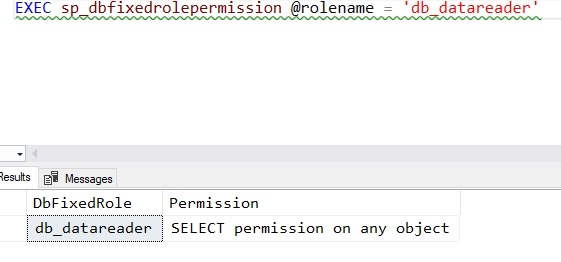
    If we include a role, we see just those permissions.

    2018-07-03 14_50_51-SQLQuery9.sql - (local)_SQL2016.EmptyFileTest (PLATO_Steve (74))_ - Microsoft SQ

    SQLNewBlogger

    This is a short post, really about 5 minutes, based on my need to solve another issue. However, this is something a DBA should know, and it’s something I’ll likely use again.