Author: way0utwest

  • The Age of Multiple Databases

    I can still remember learning to store data in files, reading one record at a time, testing for end of lines and end of files. It was slow and cumbersome, but for a teenager, it was amazing. We built applications that could help run Dungeon and Dragons games, and the ability to store information about our games was amazing. I even adapted some of these routines to store data about various chemistry experiments in school, making my report writing (and data fudging) must easier.

    In time I stumbled upon the basic database structure of dBase, thinking this was vastly superior. I could control the structure of each table, but have the power of quick access and indexes. Of course, I learned to make sure I opened all the indexes with the data file, otherwise I might “lose” some data over time.

    Those first database structures felt great, and even superior to SQL Server when it was just one person. Initial queries were much quicker under dBase type applications (Clipper, FoxPro, etc) than under SQL Server, though that quickly changed as the number of users grew. For the last two decades, I’ve been entranced and thrilled with the power of relational systems. They solve many problems well, and I find them fairly easy to develop against.

    Not everyone feels the same, and there have been many different types of data stores built in the last decade, each designed to solve different types of problems. I ran across a post about the different specialty databases available in AWS from Werner Vogels, Amazon’s CTO. The piece is interesting as he notes that one type of database can’t meet all the needs of modern applications, at least, it can’t meet the needs of very large scale systems like Amazon’s eCommerce site. Instead, there are situations and problems better solved by specialty systems.

    Amazon built a key-value, extremely fast database to back a system that mostly needed those types of simple lookups. Over the years, in response to their needs or those of their customers, they’ve added other types of databases in their AWS cloud. Mr. Vogels lists six databases in AWS, including relational stores. He talks a bit about where each can be used. He also cites some customers that have had success in different applications with different data stores.

    Microsoft has done similar things in Azure and their data platform. Most of us know SQL Server as the relational engine, but we have an in-memory component and with 2017, we also get graph capabilities, albeit rudimentary ones. In Azure, they have CosmosDB, which include a number of different types of data stores (key-value, document, graph, etc.). I know Google has multiple databases available as well.

    As we build larger systems that reach out to more people, I wonder sometimes if we ought to be architecting to use multiple data stores from the beginning, choosing the type that works best for the problem and not choosing to just use one database for all parts of an application. I already have some customers that supplement their SQL Server with Redis, Elastisearch, AWS or Azure queues, cloud storage buckets/containers, and more.

    I’m a practical person, who likes to pick the solution that works well for the problem I need to solve. I have no issue with using multiple technologies, and as my career as advanced, I think it’s easier than ever to do so. If you haven’t considered other data stores, perhaps you want to learn a bit about them and see if they could help improve your system. Keeping an open mind and considering alternatives is good, and I recommend it. What I don’t think you should do is choose another technology because you like it or are interested in learning more about it. Pick the solution that works best.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 4.8MB) podcast or subscribe to the feed at iTunes and Libsyn.
  • Solving Ken’s FizzBuzz 3D–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    I like the FizzBuzz test. It’s cute and fun, and I’ve had my kids solve it, just to think about what it means to structure a simple problem. It’s not a great test of whether you’re a good programmer, but if you can’t solve this, you probably aren’t.

    Ken Fisher set up a challenge to solve FizzBuzz with SQL, but in a 3D manner. He added a few challenge to this, like no modulus operator. I don’t know why you’d deliberately avoid using this, but it’s a programming exercise, so why not. I took the challenges because, well, Ken asked me do.

    SQLNewBlogger

    I’m putting this part first, because this is a good exercise, and a great post for your blog. Solve this yourself first, and write about it. Then you can read my code.

    The coding part of this probably took me 20-25 minutes to do. I worked on it in a few stages, pausing to do other work and let the solution simmer a bit. I realized a few times that I was making it harder, so the breaks were helpful.

    Writing this up was about 30 minutes, but it made me think about what I’d done.

    Building a Solution

    My first thought with this is I need a tally table. Of course, I’m building a set of coordinates from 1 to 100. I started here.

    WITH myTally (n)
    AS
    -- SQL Prompt formatting off
    (SELECT n = ROW_NUMBER() OVER (ORDER BY (SELECT null))
      FROM (VALUES (1), (2), (3), (4), (5), (6), (7), (8), (9), (10)) a(n)
       CROSS JOIN (VALUES (1), (2), (3), (4), (5), (6), (7), (8), (9), (10)) b(n)
    )
    , cteCoordinates (x, y, z)
    -- SQL Prompt formatting on
    AS
    (
    SELECT a.n ,
            b.n ,
            c.n
    FROM myTally AS a
         CROSS JOIN myTally AS b
         CROSS JOIN myTally AS c
    )
    SELECT x, y, z
    FROM cteCoordinates;

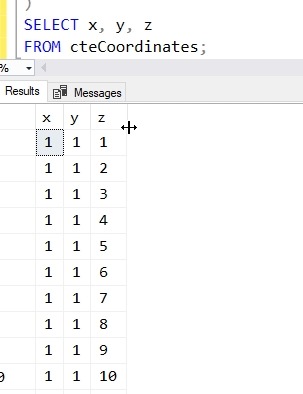
    This gave me my list of numbers.

    2018-07-02 14_40_48-SQLQuery4.sql - (local)_SQL2016.sandbox (vstsbuild (53))_ - Microsoft SQL Server

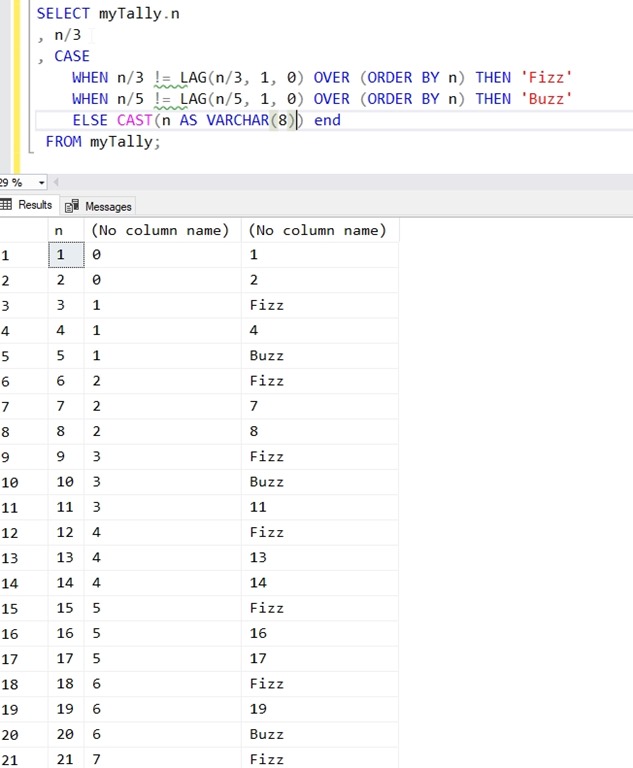
    My next step was to think about the FizzBuzz test. I can’t use Modulo, so how can I determine if I am evenly divisible by 3? I decided to look at the simple division operator. I got these results, but notice anything?

    2018-07-02 14_42_55-SQLQuery4.sql - (local)_SQL2016.sandbox (vstsbuild (53))_ - Microsoft SQL Server

    I get a new number every time the division changes. Immediately I think of window functions here. So I decided to do some checking here. Since I’m looking for a change, I went with a LAG function.

    If the LAG isn’t equal to the current value, I’ve had a change. Therefore, a Fizz.

    2018-07-02 14_45_44-SQLQuery4.sql - (local)_SQL2016.sandbox (vstsbuild (53))_ - Microsoft SQL Server

    Let’s clean this up to show Fizz and add the Buzz with a 5.

    2018-07-02 14_47_27-SQLQuery4.sql - (local)_SQL2016.sandbox (vstsbuild (53))_ - Microsoft SQL Server

    I’m getting there, but what about FizzBuzz? Well, the CASE will execute in order, so let’s add that one at the top.

    2018-07-02 14_49_00-SQLQuery4.sql - (local)_SQL2016.sandbox (vstsbuild (53))_ - Microsoft SQL Server

    I’ve mostly solved this, so let’s put this in my query. I’ll substitute the CASE in for each item of the cross join. I get this:

    WITH myTally (n)
    AS
    -- SQL Prompt formatting off
    (SELECT n = ROW_NUMBER() OVER (ORDER BY (SELECT null))
      FROM (VALUES (1), (2), (3), (4), (5), (6), (7), (8), (9), (10)) a(n)
       CROSS JOIN (VALUES (1), (2), (3), (4), (5), (6), (7), (8), (9), (10)) b(n)
    ),
    cteCoordinates (x, y, z)
    AS
    ( SELECT
    CASE
         WHEN ( a.n/3 != LAG(a.n/3, 1, 0) OVER (ORDER BY a.n)
           AND  a.n/5 != LAG(a.n/5, 1, 0) OVER (ORDER BY a.n)
             )THEN 'FizzBuzz'
         WHEN a.n/3 != LAG(a.n/3, 1, 0) OVER (ORDER BY a.n) THEN 'Fizz'
         WHEN a.n/5 != LAG(a.n/5, 1, 0) OVER (ORDER BY a.n) THEN 'Buzz'
         ELSE CAST(a.n AS VARCHAR(8)) END,
    case WHEN ( b.n/3 != LAG(b.n/3, 1, 0) OVER (ORDER BY b.n)
           AND   b.n/5 != LAG(b.n/5, 1, 0) OVER (ORDER BY b.n)
             )THEN 'FizzBuzz'
         WHEN b.n/3 != LAG(b.n/3, 1, 0) OVER (ORDER BY b.n) THEN 'Fizz'
         WHEN b.n/5 != LAG(b.n/5, 1, 0) OVER (ORDER BY b.n) THEN 'Buzz'
         ELSE CAST(b.n AS VARCHAR(8)) END,
    case WHEN ( c.n/3 != LAG(c.n/3, 1, 0) OVER (ORDER BY c.n)
           AND  c.n/5 != LAG(c.n/5, 1, 0) OVER (ORDER BY c.n)
             )THEN 'FizzBuzz'
         WHEN c.n/3 != LAG(c.n/3, 1, 0) OVER (ORDER BY c.n) THEN 'Fizz'
         WHEN c.n/5 != LAG(c.n/5, 1, 0) OVER (ORDER BY c.n) THEN 'Buzz'
         ELSE CAST(c.n AS VARCHAR(8)) END
        FROM mytally a
        CROSS JOIN mytally b
        CROSS JOIN mytally c
    )
    SELECT *
      FROM cteCoordinates
      ORDER BY cteCoordinates.x, cteCoordinates.y, cteCoordinates.z

    That doesn’t seem to work. Even forgetting the ordering, I have a mess.

    2018-07-02 14_58_53-SQLQuery4.sql - (local)_SQL2016.sandbox (vstsbuild (53))_ - Microsoft SQL Server

    At this point I took a break. Clearly I’m overlooking something in my five minutes of work.

    Debugging

    Let’s move the items around and get some ideas here. I’ll get the actual numbers and then the FizzBuzz results. When I print the coordinate values along with the decodes, I see this.

    2018-07-02 15_04_06-SQLQuery4.sql - (local)_SQL2016.sandbox (vstsbuild (53))_ - Microsoft SQL Server

    What’s my error? I’m not thinking of LAG() correctly. This is by row, and the lagging for the x and y coordinates (the first two columns), aren’t changing at the same rate.

    Aha.

    Let’s change this. I’ll setup a simpler CTE first, one that takes the values from 1-100 and returns the value as well as the FizzBuzz calculation. This gives me this code:

    WITH myTally (n)
    AS
    (
    SELECT n = ROW_NUMBER() OVER (ORDER BY (SELECT NULL))
    FROM
    -- SQL Prompt formatting off
    (    VALUES (1) ,(2) ,(3) ,(4) ,(5) ,(6) ,(7) ,(8) ,(9) ,(10)) AS a (n)
         CROSS JOIN    ( VALUES (1), (2), (3), (4), (5), (6), (7), (8), (9), (10) ) AS b (n)
         CROSS JOIN    ( VALUES (1), (2), (3), (4), (5), (6), (7), (8), (9), (10) ) AS c (n)
    -- SQL Prompt formatting on
    ) ,
          cteFizzBuzz (x, n)
    AS
    (
    SELECT CASE
                WHEN (n / 3 != LAG(n / 3, 1, 0) OVER (ORDER BY n)) AND (n / 5 != LAG(n / 5, 1, 0) OVER (ORDER BY n))
                   THEN 'FizzBuzz'
                WHEN n / 3 != LAG(n / 3, 1, 0) OVER (ORDER BY n) THEN
                    'Fizz'
                WHEN n / 5 != LAG(n / 5, 1, 0) OVER (ORDER BY n) THEN
                    'Buzz'
                ELSE
                    CAST(n AS VARCHAR(8))
            END, n
    FROM myTally
    ) ,    cteCoordinates (x, y, z)

    Now that I have this, let’s build the coordinates now. I’ll use the first set of code above as an example, and cross join the cteFizzBuzz with itself. I’ll make this the third CTE.

    ) ,    cteFinal (x, y, z, a, b, c)
    AS
    (
    SELECT a.n, b.n, c.n, a.x, b.x, c.x
    FROM           cteFizzBuzz AS a
         CROSS JOIN cteFizzBuzz AS b
         CROSS JOIN cteFizzBuzz AS c
    )

    Note that I’m returning the original values (for sorting) and the calculated FizzBuzz values, which are characters. If I didn’t care about this, I could ignore the first few columns.

    In my outer query, I display the words, but order by the numbers.

    SELECT 
        c.a, c.b, c.c
      FROM cteFinal c
      ORDER BY c.x, c.y, c.z

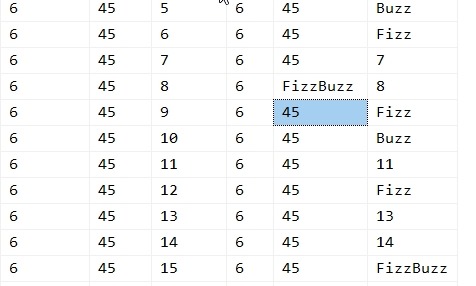
    This gives me the answer (scrolled down to show a few cases).

    2018-07-02 15_12_18-SQLQuery5.sql - (local)_SQL2016.sandbox (vstsbuild (54))_ - Microsoft SQL Server

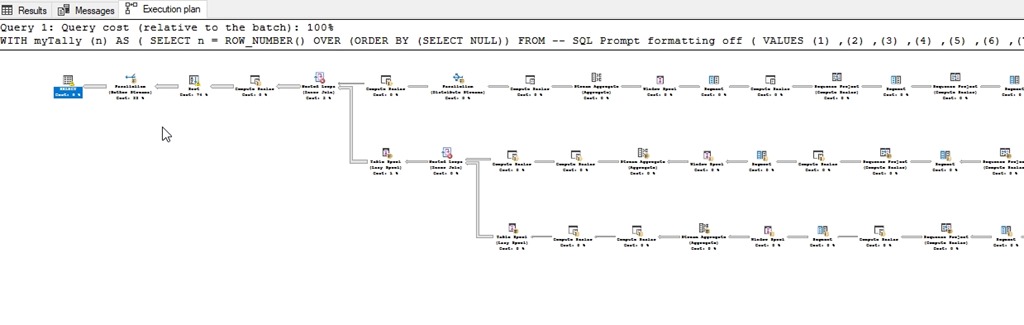
    On my machine, this takes about 4s to run. Not bad, and probably not optimal. The query plan is a mess, but this is for fun in a quick run, so let’s leave this  for now.

    2018-07-02 15_14_08-SQLQuery5.sql - (local)_SQL2016.sandbox (vstsbuild (54))_ - Microsoft SQL Server

    There are likely better solutions. I’m not an optimization guy out of the box. I get things done first, then I’ll go back and evaluate some time to tune things. In this case, adding in 3 more values (to 300) takes 1:58s. Going to 500 rows caused an SSMS out of memory error.

    If I send the results to a temp table, things are better:

    • 100x100x100 (1,000,000 rows) – 00:01
    • 300x300x300 (27,000,000 rows) – 00:06
    • 500 x 500 x 500 (125,000,000 rows)  – 00:29
    • 1000x1000x1000 (1,000,000,000 rows) – 6:48

    Note, don’t send results to the client if you don’t need to.

  • The MVP Award Looks Backward

    I was awarded the Microsoft Data Platform MVP designation in July 2018. I’ve been honored to receive this designation since 2008, though the award doesn’t drive my work. I started writing articles to help others get better with their work, just as I got help from others before me. That was the goal of SQLServerCentral, and I’m proud whenever I hear that I’ve been able to help someone solve a problem, learn a new skill, or improve their career in some way.

    Microsoft has an MVP site, and they describe the people they recognize in this way: “Microsoft Most Valuable Professionals, or MVPs, are technology experts who passionately share their knowledge with the community.” The award is for those that make efforts to help others “ranging from speaking engagements, to social media posts, to writing books, to helping others in online communities …” In other words, for those that help others, Microsoft chooses to designate some of them as MVPs for their efforts.

    Their past efforts.

    That’s the key. If you are awarded the MVP designation, then you’ve spent quite a bit of time during the previous year helping others and sharing knowledge. You could stop all your writing, speaking, etc., and you’d still be an MVP for the next year. You might not be renewed after that, but you could use the logo, attend the MVP Summit, and more during this year.

    There are budget constraints to the MVP program, just like other corporate initiatives. As a result, not every speaker, blogger, open source MS stack developer, etc. gets awarded. People get nominated, or if they’re already MVPs, they’re automatically considered for the next award period. This leads to an evaluation process where every nominee for some period is ranked in some order. I have no idea what method is used, but it’s a combination of speaking, blogging, organizing events, writing free/open source software, and likely more. There is a budget that says only xx people will be awarded, and the top xx people get picked. I really have no idea how this works, but since I’ve been a recipient of the award, this is what I’ve observed.

    Most people appreciate the award and continue to contribute to the community. Some really want to earn the award and make special efforts to ensure they make plenty of contributions. If you want to get recognized, it takes a lot of work. This is a competitive environment, with many people regularly making contributions to the community. You have to make enough to rank above the cutoff, regardless of accomplishments in prior years.

    I’m always appreciative of the award, but as I mentioned, it doesn’t drive me. I have a set of things that I do for work, and a set that I volunteer for as a part of the community. If that earns me a high enough ranking, that’s great. If it doesn’t, I’m fine with that. Ultimately my goal is to help others, and I’ll continue to do that, regardless of recognition.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 4.1MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • Back to #SQLSat Louisville

    Next week is SQL Saturday #729 – Lousiville and I’m making the trip. This will be my third or fourth trip there, and I’m looking forward to the trip. It’s a nice town, I can visit some family, and lots of #sqlfamily friends will be there.

    This is the 10th event, which is very exciting. Lots of props to John Morehouse, Chris Yates, Mala Mahadevan, and everyone setting the event up. Amazing to see another city get to their tenth event.

    The schedule is up, and there are some great sessions. I’m doing my encryption and security session, but I wonder if I’ll have many people coming. I’m up against Randy Knight’s deadlock session, William Wolf’s T-SQL session and a Linux talk from Dave Walden plus others.

    In fact, lots of tough choices. Each time slot has at least 2 or 3 sessions I’d like to see, and I’ve got tough choices to make.

    If you’re in the area, this is a fun event and the chance to learn some new things about SQL Server. Register today and come spend the day talking about the data platform.