Category: Blog

  • A Problem with POWER()

    I ran into an interesting problem while working with the POWER() function. I was trying to do some binary conversions and had a statement like this to process powers of 2.

    SELECT POWER(2, n)

    This was designed to take a value and return a power of 2. I then used a different value to determine if this was added to my conversion factor or not. In trying to work with some larger numbers, I ran into this error:

    Msg 232, Level 16, State 3, Line 3
    Arithmetic overflow error for type int, value = 2147483648.000000.

    The error tells me I’ve exceeded the size of an integer. When I looked up the POWER() function, it tells me that it returns a bigint for a bigint input. Since I had ensured my “n” was a bigint, I was confused for a few minutes.

    Then I realized that it’s not the n, but the “2” that’s the problem. By default, this scalar value is an integer. That means I need to ensure that this is a bigint to make this work. I changed to:

    SELECT POWER(CAST(2 AS BIGINT),n)

    And things worked.

    Double check all the data types when you get a conversion error. SQL Server knows what’s wrong, but sometimes you need to dig in to determine where in your code you’ve made the mistake.

  • Webinar: What We Learned at the PASS Summit

    Join me tomorrow for a webinar from Redgate Software.You can register for our webinar today at 10am EST here.

    Kendra Little and I join Grant Fritchey, the President of PASS, to discuss some highlights from last week’s PASS Summit.

    Register today and join us tomorrow.

  • Fun with Savepoints–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    I haven’t spent a lot of time with savepoints, but I did find a question recently and thought I’d take a moment to dig into how they work. They are interesting, and they can be useful for you in certain situations.

    Warning: Anything involving transactions can be tricky, so be sure you test, test, test and check out how things work with a wide variety of situations, including some you might not expect.

    Here’s a basic setup. I’ll create a table to log some actions.

    CREATE TABLE TransLogger
    (ID INT IDENTITY(1,1) NOT NULL CONSTRAINT TransLoggerPK PRIMARY KEY
    , LogMessage VARCHAR(200)
    )
    GO

    Now that I have a table, let’s do something in a transaction. I’ll start a transaction, make two inserts, but set a savepoint between them

    BEGIN TRANSACTION
    

    INSERT dbo.TransLogger (LogMessage) VALUES ('First insert inside transaction')

    SAVE TRANSACTION Firstsave

    ROLLBACK TRANSACTION Firstsave

    COMMIT

    SELECT top 10
      *
      FROM dbo.TransLogger AS tl

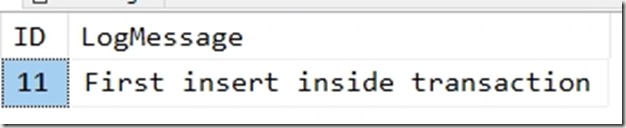
    If I look at the results, I see this:
    2018-11-12 16_46_08-SQLQuery8.sql - Plato_SQL2017.sandbox2 (PLATO_Steve (57))_ - Microsoft SQL Serve

    That makes sense. I inserted this row (I’ve been testing, so that’s why it’s 11), and marked a savepoint with the SAVE TRANSACTION Firstsave line. Then I rollback a transaction to this savepoint, which does nothing. Finally I commit. I see my one row.

    Let’s add something. I’ll add a second item, and decide to roll it back.

    DECLARE @rollback INT = 1
    

    BEGIN TRANSACTION

      INSERT dbo.TransLogger (LogMessage) VALUES ('First insert inside transaction')
       SAVE TRANSACTION Firstsave

      INSERT dbo.TransLogger (LogMessage) VALUES ('Second insert inside transaction')
       IF @rollback = 1
         ROLLBACK TRANSACTION Firstsave

    COMMIT

    SELECT top 10
      tl.ID, tl.LogMessage
      FROM dbo.TransLogger AS tl

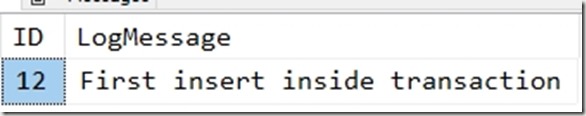
    Note I’ve added a variable so I can decide to rollback or not. I’d often have some condition or error handling that might cause a rollback, so this simulates that. Note that work before the savepoint is committed, but work after is removed with the ROLLBACK TRANSACTION Firstsave.

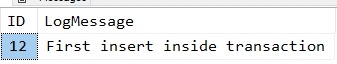
    My results are a single row. Note, I cleared the table between runs.
    2018-11-12 16_49_42-SQLQuery8.sql - Plato_SQL2017.sandbox2 (PLATO_Steve (57))_ - Microsoft SQL Serve

    Savepoints give me a place to commit work if I need it before doing more. This potentially allows me to capture some changes and not others if I don’t want to fail my entire transaction.

    Personally, if I’m doing this, I would likely just have two transactions if I can have one commit without the other.

    SQLNewBlogger

    A few minutes of experimenting gave me a quick post. I need to do more, and certainly test more, but this is a basic idea of what savepoints are. You can write something similar.
  • T-SQL Tuesday #108

    tsqltuesdayIt’s that time of month, and this is a good topic as it relates to career learning. I’m a big fan of improving your career, so I like this topic. The invitation is from Mala, one of the people I look forward to seeing each year at various events.

    Non SQL Server Tech

    At heart, I’m something of a data person, though I dabble in various other technologies at times. This year, I made it a point to work on learning two new technologies, one of which was outside of SQL Server. Python was what I chose and I ended up spending some time on various Python courses for about 5 months. Then life and work got in the way.

    I still want to spend a bit more time on Python, but I also recognize that I need a new challenge, so I’m going to pick something else for 2019. For me, this will be CosmosDB.

    I think CosmosDB is a neat technology and has some really good things inside of it, but I really don’t know enough about it. I’ve had minor exposure to NoSQL structures, but not really enough to know how well I’d use them for a project.

    The Plan

    For 2019, or at least for the first quarter(ish), I want to port a database from SQL Server to CosmosDB and play with the differences. I have a few sample ones, but I’ve been compiling a database of some SQL Saturday data and want to use that as a test. I’ll work on moving the data to the different CosmosDB structures, likely a document structure and a graph structure, and gain some experience as to how these work.

    I hope to build a simple REST website that accesses these databases, which should also let me compare the differences for data access and note where one structure might work better than the other.

    I’ll set a reminder for the end of each month in 2019 (Jan-Apr) to evaluate where I am.