Tag: administration

  • Migrating a Large Database

    I have upgraded lots of SQL Servers from one version to the next, and for the most part, the process has been smooth. That’s not always the case, and there have been some long nights where the Operations staff had to scramble to fix things, script out old logins, call Microsoft support, and perform various data exports and imports to get a new instance running. I’ve been a part of quite a few of those teams.

    Most of my upgrades were with relatively small databases, at least small for that time period. However, I have upgraded a few “large” databases in the past. We had a 400GB database on SQL Server 6.5 in 1999 that was a challenge to move to SQL Server 7. I also upgraded an 800GB database in 2001 from 6.5 to 2000 for our Financial team, which involved a lot of stress.

    I haven’t upgraded a 1TB database, much less a 4TB one, but I know this can be very time-consuming to move all that data. Even with much faster hardware and networks these days, working with that much data can require a decent amount of downtime. That’s not very acceptable these days, especially for applications that are used by customers all around the world and all around the clock.

    I found an interesting upgrade story from a SaaS provider that runs PostgreSQL. I don’t use that platform, but I found the write-up of their process to be aligned with some of my experiences with SQL Server. They delayed upgrading an old version of PostgreSQL and then had the desire to move to as current a version as possible and delay future upgrades (again). I’ve certainly experienced that. Their goal was also to minimize downtime, as their customers are constantly connecting.

    The plan for the upgrade made sense to me. Use replication to move most data and then minimize downtime. That’s a technique that can work in SQL Server, though we’d be more likely to use log shipping to simulate this. They also trimmed and cleaned some data, removing the need to upgrade some of the tables. That’s something many of us might be able to do every year in some databases, especially for large logging tables where older data might rarely be read. I’d even think about moving that data to another database and using a synonym to access it if it were needed. That’s just a good idea for general DR planning.

    I also appreciated them creating a runbook and testing the process multiple times in staging. Their big takeaway here: practice over and over with a realistic workload. They created some problems for themselves by not using a real enough workload. That ought to be something your organization does on a regular basis to test your software and ensure new code performs well. Using the same process for upgrades is a bonus.

    Large upgrades are stressful and often they are “big bang” deployments where you can’t go back to the old system. Practice as much as you can, make sure you have backups, and then be ready to adapt to whatever challenges come up. Plan ahead, and be prepared for a long night. If you do, you’ll likely have success. If you don’t, I am fairly sure something will go wrong and you’ll regret not thinking ahead.

    Steve Jones

    Listen to the podcast at Libsyn, Stitcher, Spotify, or iTunes.

  • Scripting Makes Mistakes Easier Than Ever

    A number of you likely use Atlassian products like Jira, Confluence, Opsgenie, or something else. You might have been affected by a large outage they had (post incident blog, Company Q&A, TechRepublic report) recently which lasted at least 9 days. I don’t know if all customers have their data back and are working, but this was a surprisingly poorly handled incident according to a number of reports from customers. There’s a great write-up from the outside that you might want to read.

    The bottom line in this issue is that Atlassian looked to deactivate a legacy product with a script, but they apparently didn’t communicate well among their teams. The script ended up using the wrong customer IDs and also marked the sites for permanent removal, not temporary removal (soft delete). While they supposedly test their restore capabilities, they weren’t prepared for partial restores of subsites. I’m guessing this is likely a partial database restore, which many of us know is way more complex than a full database restore.

    Leave aside the issue of a software-as-a-service (SaaS) company failing their customers, and the lack of communication with customers. The more interesting thing for me is the challenge of poor coding and communication internally. Clearly, the project to deactivate their legacy app wasn’t well planned or tested and the code used was probably executed at too wide a scale initially.

    When we deploy code changes to a large number of items, we want to test them at a small number first. Whether we are deploying to multiple databases, against many customers, or different systems, a standard method of making changes at scale involves working in rings. Azure DevOps describes this in docs, and they actually use rings to change the platform. We used the same pattern 20 years ago for software and database updates to many systems. We would internally deploy to a few users to look for issues. Then a week later we would deploy to a small number of systems to check for unexpected issues. Then typically to most systems in the third ring with a fourth ring a week later to catch up stragglers that needed more time to prepare.

    I find many customers, especially those with sharded/federated databases or many systems unwilling to spread out deployments in this manner. Often they yield to pressure from business users to ensure everyone gets the same update at the same time. I would never recommend this approach as we need to ensure we are looking at scripts in a controlled environment, or even two, before we deploy things widely. I’d be even more cautious about one-off administrative scripts that might make a change similar to the one Atlassian attempted. Those are often not seriously tested enough.

    At the very least, any of us working with multiple customers in a single database or in multiple databases ought to ensure we can backup and restore a single customer, but more importantly, can you restore a group of customers. If you make a mistake like Atlassian, which scripting allows us to do extremely rapidly, can you recover a partial set of data? Many of us don’t test this, but that’s likely something we ought to consider when we work with scripts that are designed to only change some data. Most of us don’t experience complete failures, but partial ones, usually because of human error. We ought to know how to deal with these situations.

    Steve Jones

    Listen to the podcast at Libsyn, Stitcher, Spotify, or iTunes.
  • Removing a LocalDB Instance

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    This might be obvious and easy, but I spent a couple minutes learning how to remove a LocalDB instance.

    I tried to use remote, but that didn’t work:

    2022-03-03 09_17_39-C__Windows_System32_cmd.exe

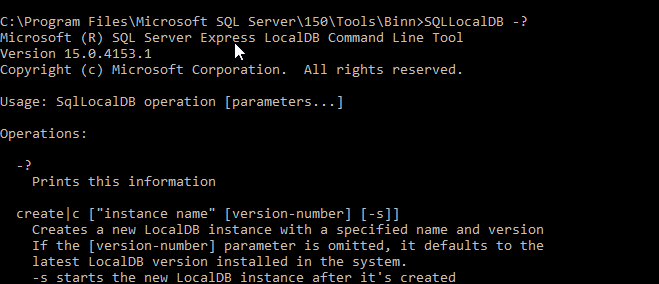
    There error reminded me that in my day, most commands use –? or /? to get help. A lot of CLIs these days use –help (two dashes). That doesn’t work here. But /? does.

    2022-03-03 09_18_33-C__Windows_System32_cmd.exe

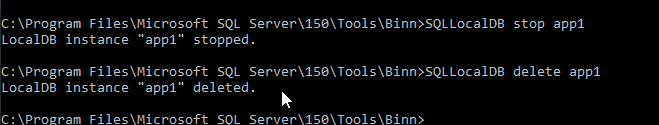
    This shows me the delete option is the one to use. I tried that, but I needed to stop the instance.

    2022-03-03 09_19_55-C__Windows_System32_cmd.exe

    Running stop and then delete allowed this to succeed.

    2022-03-03 09_20_51-C__Windows_System32_cmd.exe

    SQL New Blogger

    After writing a previous post, which took me 10 minutes or so, I went to clean up my environment. I realized this was easy, but also worth a post about how I learned this.

    Just 5 minutes. You could write posts like this to further your knowledge and help your career.

  • Starting LocalDB–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    Lots of people have never worked with LocalDB, which is an in-process version of SQL Express. No service account, just a SQL Server instance running with your app. It’s a nice lightweight way to get SQL Server running quickly without a hassle.

    This is a SQL Server Express version, but the bare bones for development. This post looks at how you can get this running.

    This version of SQL is installed with SQL Express, and with Visual Studio. If you look in this path: C:\Program Files\Microsoft SQL Server\150\Tools\Binn, there is a SQLLocalDB.exe. You can see that here.

    2022-03-03 09_08_00-Binn

    This is my SQL Server 2016 version of LocalDB. I can start a new instance by calling this with the CREATE option. I can give this a name as well, as I might want to stat multiple instance for different apps. Here I’ll create an instance called app1.

    SQLLocalDB create app1

    I then call the same command, but use START instead of CREATE. You can see this reports as started from the CLI. I also add the INFO call to get status.

    2022-03-03 09_10_35-C__Windows_System32_cmd.exe

    Now I can connect. I use (LocalDB)\app1 to connect:

    2022-03-03 09_11_39-Connect to Database Engine

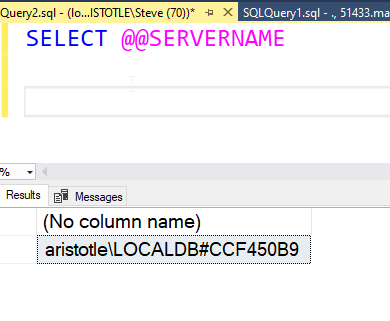
    I see I’m connected to a version of LocalDB then:

    2022-03-03 09_12_03-SQLQuery2.sql - (localdb)_app1.master (ARISTOTLE_Steve (70))_ - Microsoft SQL Se

    Now it’s just an instance of SQL Server I can use.


    SQL New Blogger

    I needed to check something for a customer and realized I hadn’t started LocalDB in a long time, so I needed to check the docs. I spent 10 minutes putting this post together.

    An easy type of post for any of you out there. Learn something, try something, write something.