Tag: administration

  • New Tagging in SQL Monitor to Keep Organized

    I recently got an update from the SQL Monitor PM on the progress we’ve made across all the teams. We have a number focusing on different aspects of the product, and they’ve built an impressive produce over the years. I remember when it was SQL Response and only provided alerting. Now it’s an Enterprise Monitoring solution for SQL Server.

    One of the additions that was added across the last few months is tagging. Traditionally the monitored instances and databases are organized in categories, which is OK, but very limited. Below you can see at monitor.red-gate.com that we have instances in various categories: production, azure database, staging, test, and simulation.
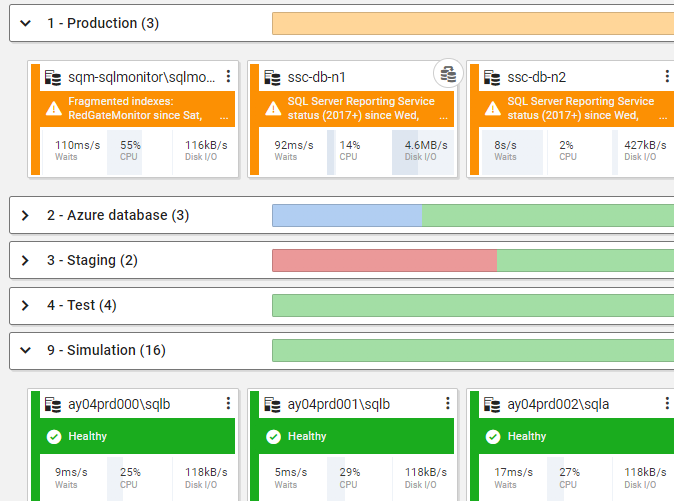
    2022-02-10 12_12_40-Global Dashboard

    Tagging is a much more flexible structure that makes it easy to classify and filter your estate. There are plenty of cases where you might not only have an instance set as Production, but perhaps it’s a US or UK server and you want to know the geography. Maybe there is a need to know this instance also relates to CRM v a data warehouse system. Tagging makes that easy.

    Filtering with Tags

    At the top of the global dashboard shown above, there is a new filtering area where we can filter by tags. You can see below that I’ve filtered the 28 instances in our demo setup to the 2 that have the “sqlservercentral” tag.
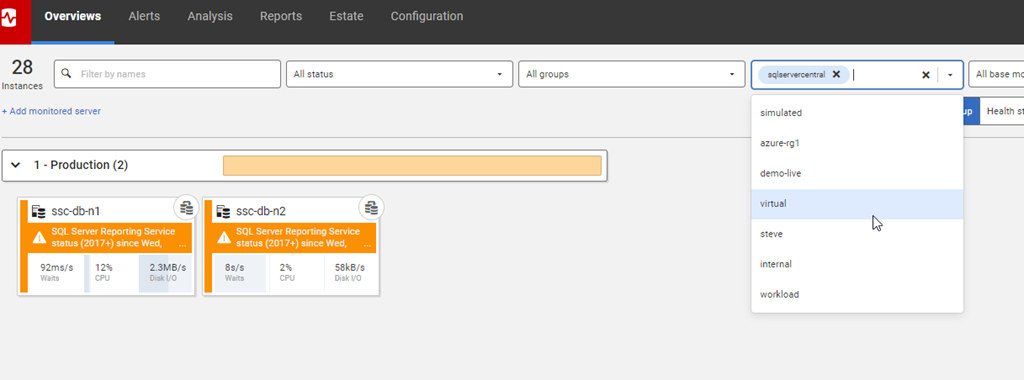
    2022-02-10 12_15_45-Global Dashboard

    What’s more, clicking in the tag box shows me the existing tags that are applied.

    Tagging is also available on the Estate tabs.
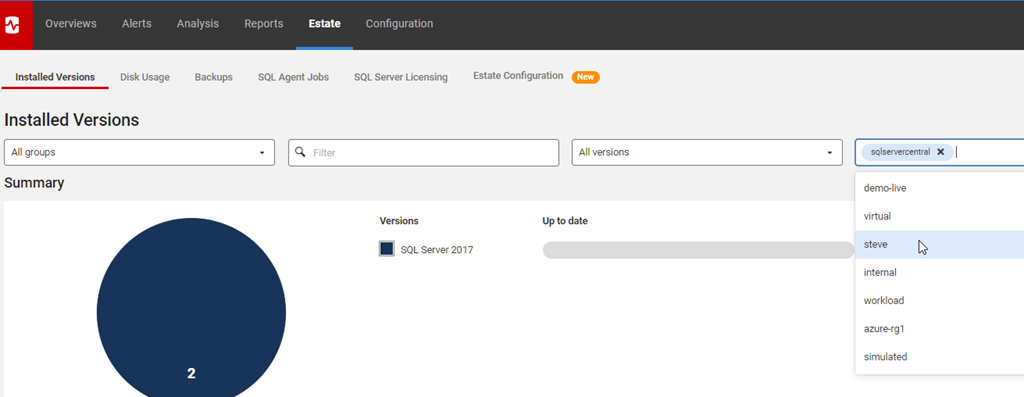
    2022-02-10 12_28_55-Installed Versions

    There are a few other places, and it’s slowly making its way across the product to all areas. You’ll see it slowly appear in other places as well.

    Adding Tags

    You can add these in the Server Configuration, which works fine. Pick a server and then you can add tags that correspond to what you care about.
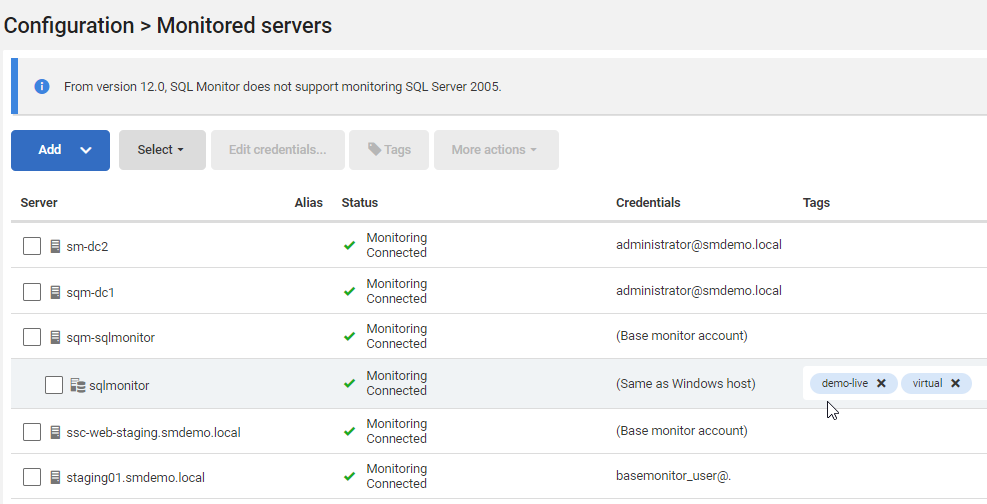
    2022-02-10 12_48_21-Monitored Servers

    If I’m working with a server in the overview, I can also expand the right Alerts panel and in the top About section, I can adjust tags. A good way to fix these up as you work on issues.
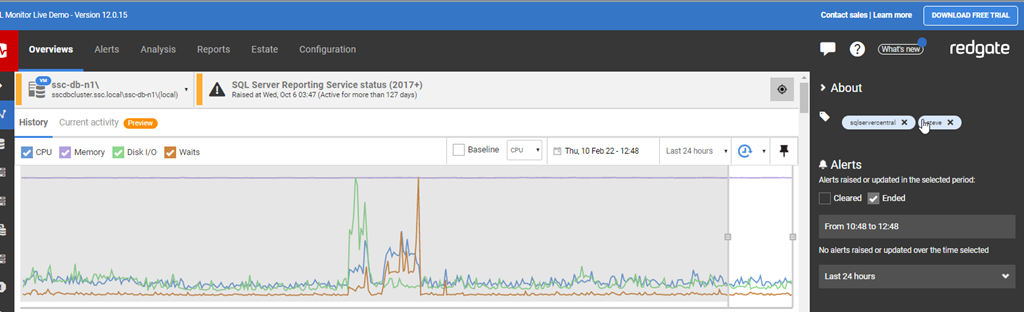
    2022-02-10 12_48_55-ssc-db-n1_ - Server Overview

    Look for tagging to make it’s way into the PowerShell cmdlets as well.

    There’s a post on the Redgate Blog about tagging as well. They are looking for feedback, so please send it along.

    If you haven’t used SQL Monitor, it’s a great tool to help you keep an eye on your estate with minimal effort. You can get alerted of issues and even integrate with other tools. Download an eval and give it a try today.;

  • Think Marathon, not Sprint

    I saw an article about automating responses to security issues being a marathon not a sprint. The articles gives a few examples of different levels of automation response to situations, noting that each of this is a different level of maturity in the organization. At early stages, the response is mostly alerting a human to take action. Later, the automation will make some changes, but still defer to a human for more actions. The final example is automation handling most of the issue itself. Note, none of this means humans are unaware of what responses are being made.

    The idea is that improving security with automation is something that takes place across time, as the organization matures and becomes more comfortable and trusting of automation. It’s a marathon, where we push, but we know this will take some time to get to the end. It’s not a sprint where we make a quick fix and get a result.

    Actually, I think a lot of things are marathons in the technology area. That’s if we are looking to improve how we work with automation. If we like just firefighting issues and building quick patches, then we’re constantly sprinting.

    A lot of the work I do in advising clients about DevOps is to get them to think marathon. There isn’t really a finish line, but we are racing our competitors and trying to improve how we work. We just need to recognize that this is a process that takes months, not minutes. We want to mature and evolve processes, making them better over time. We also start small with our scope, hoping that we expand things to the entire organization over time, but again, that time is months.

    This was my same approach as both a developer and DBA. Find something that I can automate to make better, start to improve it, learn from success and failure, and repeat. At some point, I usually found something was working well enough to move on to a new area to improve. If I needed to come back and continue to improve something, I could do that as well.

    I don’t like sprinting. In real life, or in technology. I prefer to think marathon. We are pushing to achieve something, but with the further away future in mind, not the next few minutes.

    Steve Jones

    Listen to the podcast at Libsyn, Stitcher, Spotify, or iTunes.

  • Knowing When to Respond

    I ran into this quote on the Microsoft Learn site, which I thought was a great way to think about how to administer a system: “Without a baseline, every issue encountered could be considered normal and therefore not require any additional intervention.”

    When I’ve had users file tickets or complain about things not working well, I’ve found more often than not their perception has changed more than the actual performance. I’ve been called for “slow applications” only to find out that “slow” was 30 seconds and the complainer wasn’t sure how long it used to take, but today being end of the quarter, it is slow. Digging into monitoring history has shown that the query always took at least 20s and could take over 30s. My main takeaway was a little stress for users sometimes culminates in unnecessary work for operations staff.

    There certainly are times when a database query takes longer than expected but is it because the system is overloaded or there’s a lot more data? When was the last time this ran and what changed? Are there more queries against the same objects than in the past? Even when there are real problems, without knowing how a system typically looks at this time, we may struggle to quickly determine where the problem lies. We may not even know how to craft a good solution without some baseline.

    Maybe the best reason for me to know a baseline is for triaging and prioritizing issues. Seeing a server at 100% CPU is one thing, but if this is a daily occurrence, I might decide another issue is more important. Especially at 2 am.

    Having a baseline for your systems is important. Build a system if you must, buy one if you can, but get monitoring set up for your systems. It will help you focus development efforts when changed code doesn’t work as expected. It also helps your operations staff to help them respond more efficiently to future issues.

    Steve Jones

  • Reusing Tools for New Purposes

    One of the things you learn early on in programming is that you ought to reuse code whenever possible. This often means refactoring code into functions or methods. This ensures that the code is more easily maintained and that the knowledge and work of solving the problem is reused in many places.
    In database code we don’t do this too often. We certainly can reuse some code by encapsulating it in a view, but this often brings performance penalties. We often don’t want to reuse code in stored procedures and functions as embedding this into queries can cause lots of issues. In fact, it seems that much of the way databases optimize query performance isn’t that amenable to reusing code.

    That being said, I ran into an interesting case recently when thinking about maintenance in the cloud. Someone was asking about SQL Agent and the lack of support for it in many PaaS database systems. I understand that, and while there are some ways to do this, they feel complex compared to using a SQL Agent on a local instance, which is usually easy to set up and readily available. One of the speakers taking questions mentioned that they user shouldn’t forget about Azure Data Factory as an automation agent.

    That caught my attention as I hadn’t thought about it before. This week, there was a blog on that very topic and I read through it to see what I thought. While this isn’t as easy as SQL Agent, it does seem to be easier than Azure Automation, and likely more familiar than elastic jobs.  That’s if you already have ADF running in pipelines. In many ways, this feels like using the maintenance plans in SQL Server, though just the call a stored procedure task. Since many people use a solution like Ola’s, this is very easy to implement.

    I like that this pattern reuses skills and a system that you may already be using, transferring the skills from one area (ETL) to another (administration). This might not seem like much, but limiting the tools and technology, reduces complexity and means that each person needs to know less to support your environment. I’m a fan of code re-use, outside of T-SQL), and I think reusing other technology systems, where appropriate, is a good idea..

    Steve Jones