Tag: administration

  • Easily Repeating Work

    I love this idea from Ken Fisher: saving your work. I don’t act as a DBA anymore, but when I did, I did something similar. We often logged the scripts we used in a file,  as a part of a log, so that if we broke something and another DBA got a new ticket, they could check what you had done. Over the years, we tried two different methods. First was using the desktop of the instance itself, since we often went to a room to log into the server in those days

    The second way was in an Exchange public folder, where we added a new entry for each day. This way we could note the server and the scripts run. Since most tickets were dated, we could easily find the scripts if we were looking at a ticket. Since a user often updated or re-opened the ticket, we could use the public folder as a central note location from the DBA team. We could even point to this folder for our ISO and SOX auditors to show them what had been logged by people who supported the systems. Not a perfect auditing system, but one that often was accepted by auditors.

    However, the one thing missing in there, from my perspective, is version control. While I think it is important to track these scripts in a team of DBAs, I also think we want to ensure that as we grow and change these scripts, we know how and why. Junior people can learn from changes made by senior ones, and if a DBA alters one of these scripts and breaks something, just as a developer might refactor code and introduce a bug or break functionality. After all, these scripts are code.

    If there is a problem, we want to be able to roll back, which means that we ought to save these scripts into a repository of some sort. While I like the idea of a share that all DBAs can access, I more like the idea of a (secure) Git repository that can be downloaded anywhere, provides a second backup, and can be audited over time. All of these are important features that any enterprise should implement, especially one that is regulated. We want to protect ourselves if a DBA gets hit by the proverbial bus.

    I like collaboration, sharing knowledge, and tracking the work you do in a team. It’s important for raising the skills of everyone on the team and helping new members get up to speed quickly. This facilities consistent results, and if done using a tool like version control, helps ensure that your scripts are backed up in a way that preserves the knowledge in your code through any changes made by the team.

    Steve Jones

    Listen to the podcast at Libsyn, Stitcher, Spotify, or iTunes.

  • Changing the Owner of a Database #SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    I had an authorization issue with my account, and I decided to delete it and re-add it. That’s the subject for another day, but before I could delete it, I had to remove the ownership of some databases. You can’t delete a login that owns databases.

    I realized I wasn’t sure how to do this, so I wrote this post.

    A Deprecated Proc

    There used to be a dbo.sp_changedbowner proc that was used, but I know this is deprecated and it shouldn’t be used. It likely would work fine in SQL Server 2019, but I also know there should be more modern code. I decided to look, as I ought to know what is recommended these days.

    In searching around MS Docs, ALTER AUTHORIZATION comes up in the list. I checked, and this allows me to transfer the ownership of a securable, which a database is one of the items in the list. Example F shows what I want to do and uses this code:

    ALTER AUTHORIZATION ON DATABASE::dbname TO [login]

    I can replace dbname and login with the values I need.

    Which Databases?

    I have a lot of databases, and I don’t need to change them all, though I could. In my case, I decided to get a list of databases and owners. If you query sys.databases, there is an owner_sid column. If you join that with sys.server_principals, you can do so on the SID column. This query shows me what I need:

    SELECT d.[name], sp.[name] FROM sys.databases d
      INNER JOIN sys.server_principals AS sp
       ON d.owner_sid = sp.sid

    The results are here:

    2022-02-25 12_34_10-SQLQuery1.sql - ARISTOTLE_SQL2017.master (sa (54))_ - Microsoft SQL Server Manag

    In some sense I hate that “sa” isn’t the default owner, but I get it. There might be a need for other accounts. However, my account is a sysadmin, so my view here is that “sa” ought to be listed.

    I digress. Now that I have a list, I can limit it to my account with a WHERE clause. I can take that list of items and build the code. I could use a cursor, but this is a one-off task, so this works:

    SELECT
                    'ALTER AUTHORIZATION ON database::' + d.[name] + ' TO sa;'
                  , d.[name]
                  , sp.[name]
    FROM
                    sys.databases d
         INNER JOIN sys.server_principals AS sp
             ON d.owner_sid = sp.sid
    WHERE          sp.name = 'ARISTOTLE\Steve';
    GO

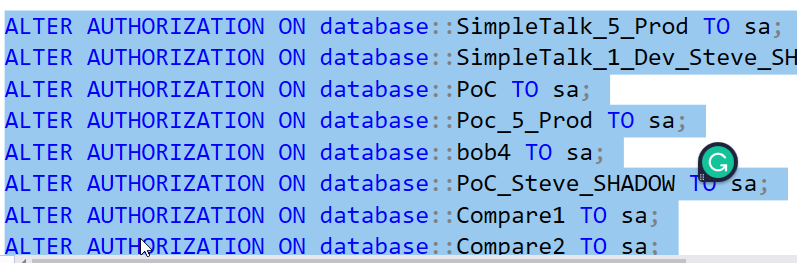
    This gives me the code in the results I want to run. I copy paste this and I have a bunch of statements to run. 

    2022-02-25 12_41_07-SQLQuery1.sql - ARISTOTLE_SQL2017.master (sa (54))_ - Microsoft SQL Server Manag

    Despite Grammarly not being happy, this worked fine.

    SQL New Blogger

    As soon as I realized I needed to do this, I knew there were two posts here. One on the removal and adding back of my Windows account, and the second on this topic (when the first didn’t work).

    This took about 15 minutes extra, finding the docs and writing some code, but it’s a good example of where a small situation that occurred helped me find something to write about. Easy for you to take little tasks like this and document your knowledge when you learn something.

  • Is the Time of the DBA Ending?

    I ran across a piece on the fall of the DBA (or part of a piece), and wondered if this is the time when the DBA is disappearing. I do know that plenty of organizations never formally adopted the DBA as a position, and plenty more have abandoned it. Not that there aren’t people managing databases, but they have moved into Database Engineer, SRE, or plain old sysadmin. They might even have another job but function as an accidental DBA.

    The DBA role has often been a mix of many things. Certainly, this is a tactical, operations role that keeps systems running, dealing with performance, security, and availability. DBAs also fix quality issues in production, deploy code changes, and often advise developers on what works well and what doesn’t. They tend to be a bit of insurance against things going wrong as well as the scapegoat when anything does go wrong. I found the DBA role to be a constantly changing, never-ending grab-bag of challenges on a regular basis.

    Those tasks don’t go away with a title change, nor with a move to the cloud, the adoption of NoSQL data stores, or the move to a DevOps style of software development. They might get handled by another role or team, but they still need to be dealt with. The DBA might need to change titles or groups, and they might need to learn how to use automation, GitOps, or some other new protocol for handling the work. As the article linked above mentions, they may need to tackle work at a higher level, not the manual, click, click repetitive process they might have followed in the past. The trend is often to work smarter, not harder.

    As with any change, there will be people who succeed and do better in the future, as well as those that find their best days behind them. I find change often brings opportunities if I am open to them and make an effort to look for those opportunities. You might find your title changes and you can ask for more compensation or more interesting work as the role changes.

    Embrace change, learn something new and find a way to make change work to your advantage. There is always a way to make this happen.

    Steve Jones

    Listen to the podcast at Libsyn, Stitcher, Spotify, or iTunes.
  • Backup Architecture

    I saw a question posted recently on what data is included in a full SQL Server database backup. I hadn’t seen that question in some time, but the post was a good reminder that this is not an intuitive concept, and new data professionals might not understand how a full backup works. If you don’t know, you should do a little research (and write a #SQLNewBlogger post for yourself).

    The way a SQL Server backup works, either with an on-premises install or the Azure SQL Database version, is well known and documented. Even if you can’t make a “normal full backup” in Azure SQL Database, the process is the same. You don’t have to run the backup, as Azure does that for you, but you can specify a restore and understand which data will be available in your restored database.

    Cosmos DB is a different type of data store, existing only in Azure and storing non-relational data. The service has been promoted quite a bit, and some of you might even be using it. Do you understand how backups, and more importantly, how restores work?

    I ran across an article that discusses the way Cosmos DB continuous backup works. This process isn’t quite what I’d expect. Changes are backed up locally (either LRS or ZRS), which makes sense. However, all changes (called mutations for some reason) are backed up within 100s, asynchronously. That’s good, and it’s not perfect, but it’s pretty good. What’s more, you can restore a container, a database, or the entire account. That matches up closely with what I expect in Azure SQL, including the need to restore into a new account. What isn’t great is that stored procedures, triggers, and UDFs aren’t restored.

    As with any sort of backup and restore operation, you should be sure you understand the way operations occur, the impact of restores, and the costs involved. You get charged for backup space and restores. Maybe the most important thing to know is how to perform a restore. If you have a problem, you want to be sure that you not only know the mechanics of restoring data but how to reconcile any potential changes between the old and new database, as well as how to ensure all other objects (stored procs, etc.) are put back in place and clients are directed to the correct database.

    This process might not be as simple as MS Docs describes, and certainly, I’ve found SQL Server restores are not always as simple as we might like. Practice ahead of time and be sure you can recover a system in a way that meets your clients’ needs.

    Steve Jones


    Listen to the podcast at Libsyn, Stitcher, Spotify, or iTunes.