Tag: DevOps

  • I Will Write Bad Code

    I’ll write bad code. I know it will happen. I’ll produce a bad query, incorrect logic, or the wrong data transformation being returned.

    This won’t be a malicious act. It might be because of ignorance, or perhaps just a simple mistake. My code might be the result of short-sightedness or not accounting for a potential situation. I might even misinterpret poorly written specifications and place the blame on others. Maybe I’ll misread the code and won’t realize there’s a problem.

    And, for sure, this code will get deployed to production.

    At some point I know this will happen, to me or someone else. And for whatever reason, I need to account for that fact in my software development process. I can’t prevent mistakes, as decades of software development have proven. Despite my best efforts, code reviews, the tests implemented in QA and elsewhere, bad code is going to get deployed.

    The important thing in any software development project is how you handle the mistakes. How do you move forward, and certainly, how do you apply a patch? Can you do it quick enough to minimize the impact to clients? Or must they deal with the issues, developing the workaround or missing functionality for a significant portion of time? Or will they consider abandoning your software for some other vendor?

    One of the reasons I continue to advocate for a DevOps approach is that a known process can enable you to fix your mistakes in a timely manner. With a consistent approach to writing, testing, and deploying software, you can apply a patch when it is needed. Certainly the code needs to be logically fixed, but a reliable process will help ease all the overhead of getting your code to a production system.

    DevOps can be implemented many ways, and if applied in name only, things won’t improve. We can’t say we’re using DevOps, or we’re coding faster, or we release every week. We need to really implement the three ways. However, if you approach your project and staff with the idea that although things are flawed, they can be improved and made better, you’ll find that you can deliver those fixes for clients in an extremely timely manner with a minimum of risk.

    DevOps allows us to move faster, but that’s not the goal. The goal is that we improve things and have confidence that we can release when we want to, in a repeatable, reliable, less risky fashion.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.7MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • DevOps Basics–Git Clients

    This is also a part of a basic series on git and how to use it.

    There are lots of git clients. If you look at the top list for this year, you’ll see quite a few. I’ve used a couple of these, but they all give you roughly the same information. Where am I in the commit tree, and what branches are out there. I tend to prefer the command line most times, but clients are handy to have.

    There are two main ones that I have been using, trading off and on between them, so a quick look at both Sourcetree and Gitkrakken.

    Sourcetree

    Sourcetree is a free client from Atlassian. They’re a software company, much like Redgate, that gives back to the community. One of the ways they do this is with Sourcetree and Bitbucket . This client is available for Windows and MacOS, so it’s cross platform.

    It’s simple and easy to setup, and the install isn’t worth covering. Amazing how simple most installs are these days. Once installed, you can open or create repositories easily.

    The interface is clean and easy to understand. All the main features (push, pull, commit, branch, etc.) are large buttons at the top. The graph, comments, and other information is in the middle.

    2017-08-25 11_36_24-SourceTree_1.9

    Below here are the staged and unstaged files in my repo, so I can easily see the state of my work.

    There are tabs for each repo, so if you open multiple ones, you’ll see them listed at the top and can easily switch between them. Handy if you need to work on multiple projects.

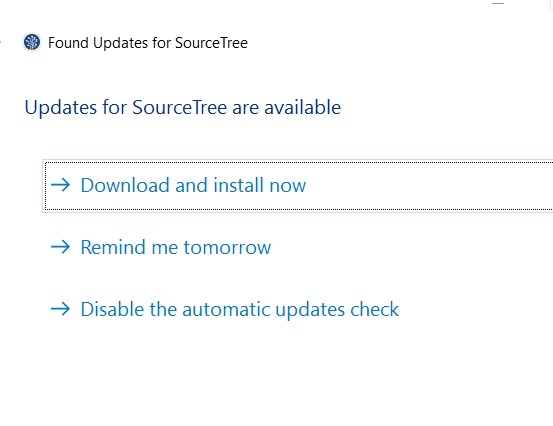
    Sourcetree will check for updates and let you know when they are available. As with most software, this will download the patch and then let you know that you need to close the app to start the install.

    2017-08-25 11_33_48-Found Updates for SourceTree

    After using other clients, I find this sometimes a bit slow, but usually commit/push time isn’t a large factor in work. I can start the process and go get coffee or take some break.

    I’d say Sourcetree is a nice client, and it’s easy to use. There’s also a nice button to pop open a Git Bash terminal, which is helpful if you want to work in a text format.

    Gitkraken

    I stumbled on this client somewhere. I think someone recommended it on Twitter, and I decided to give it a try. Sourcetree was working, but I was curious if there was something else.

    Gitkraken bills itself as the most popular client. It might be, but even if it’s not, I like some of the simplicity. This client is available for Windows, MacOS, and Linux, so you might prefer this if you move across all those platforms.

    It’s also cool to look at. The animation when it starts is neat.

    Others

    There are other clients, including some MS tools in Visual Studio (regular and code) that work with git. I don’t really use those, as I tend to work with the command line or simple interfaces for commits, not examining differences or looking at branches. For those tasks, I do like these two clients.

    Of course, at some point you may need to drop into the command line if you find yourself in a pickle. While I’m sure you’ll google most issues, be comfortable solving them in the command line and practice a few tasks periodically by typing the syntax.

  • Database Development Made Easy

    I ran across this post on developing database with SSDT. It has a lot of steps, and reading through it, I find this to make some sense, but I’m not sure I think this is easy. I can see why developers find databases to be a pain to work with. There are a lot of steps in this post to just setup and configure a database project. Databases are fundamentally hard to work with, as the model of maintaining state between changes and ensuring data is not lost can be hard. While the concept is similar to keeping track of configuration files, the scale of data in a database is vast and ever changing. Tooling to manage data that might need to be recovered isn’t very practical.

    I ran across a developer that was trying to automate their database development. They used tooling to deploy a table to a production system. The application connected and data was stored in the table. The developer then dropped a column from a table and deployed this change. It worked, but this was a mistake and this person decided to deploy the previous version of the database, with the additional column restored. The deployment worked, but there wasn’t data in the column that had been dropped, and added back. Why not, asked the developer?

    Many people are of two minds here. One, any tooling or automation should preserve data and allow for rollbacks. In the application world, this makes perfect sense, and even the data our application uses (reference files, configuration files, etc.) are restored if we rollback to a previous version.

    For the data people, this makes no sense. The data in a column could be of significant size. We often plan for systems to reach millions (or more) rows of data, and trying to save the state of this data before a change isn’t practical. Even if we were to store changes items for a few deployments, it’s entirely possible that putting the data back wouldn’t make sense as related information in other tables might not match up correctly. Consider the case of a financial system and restoring old money values. Who knows what issues would be created?

    For developers, this highlights one of the things they dislike about databases. They are must manage state transitions across deployments, and rolling back to previous versions isn’t often possible. This is one reason that I have often performed a backup before major deployments, and even today, in an automated DevOps process, I’d want to perform a backup if any significant data were being changed or deleted.

    I’ve spent a lot of time advocating for DevOps and smoother, modern database development practices for the last few years. I don’t want the database to be a hindrance or impediment to change, but I also don’t want to compromise the integrity or safety of data. My pitch has always been that our database automation tools at Redgate don’t perform any magic. They smooth, and hopefully speed up, the process of making database changes that we’ve used for decades. They save you time and effort, just as other tools may do, but they can’t change the rules of relational database changes.

    Everyone developing code inside or connecting to a database needs to understand how transactions and data changes work. There are rules and restrictions the protect our data. These mean we need to sometimes plan and consider the consequences of our actions. This should also mean that despite wanting to move faster and make changes, we can’t treat data placed in columns as malleable in the way a method in C# can be changed back and forth. We need to account for, and protect, the information stored in our systems. There are patterns that can help you evolve your database from one state to the next, but there isn’t any magic that lets you drop and add data storage elements without some preparation for handling the data itself.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 5.1MB) podcast or subscribe to the feed at iTunes and Libsyn.
  • Use More Pull Requests

    I noticed a short while back that Books Online is on github. You can fork the code and make corrections to pages and then submit a pull request. This is the model that many OSS projects use, including the amazing DBATools project. That one I really like, and if I was better at PowerShell, I’d contribute. If you’re a PoSh whiz, I’d urge you to contribute.

    A few years ago I saw a lot of complaints about the SQL Saturday site, and over the years I’ve also seen a number of complaints about the Pass Summit sites, and the registration process. At one point there was a debate over whether PASS should build a registration system or continue to pay for the service. To me, this was a perfect place to start a project, maybe with a few volunteers, and then crowdsource enhancements and improvements. Get help from the members of this technical community, after all, this is the way most of us make a living.

    If Microsoft can get help from outside, I’d expect other organizations could as well. Certainly PASS has limited resources, and this is a great way to perhaps get new ideas, innovate, and grow their system. There will be some friction and loss in reviewing changes, but I’d expect that the overall gain would come from the greater number of people contributing to the software.

    We’ve kicked this around for SQLServerCentral and Database Weekly, and I am hoping to start getting help in enhancing my own site from its community at some point. There are certainly challenges and difficulties in integrating code from lots of sources. DevOps makes this easier, with more automation to evaluate and test code before a human needs to review it. However, DevOps has its own challenges, with extending the culture and process to others, and finding those individuals that want to contribute and buy into the philosophy, not to mention maintaining code quality and standards. However, I hope that you consider using pull requests and getting help from others in your own organization or project.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.0MB) podcast or subscribe to the feed at iTunes and Libsyn.