One of the hot terms in software these days is observability. There are a few definitions (Splunk, RadixWeb), but essentially this is the insight into how your software runs and performs using metrics, logs, traces, etc. In DevOps, we do this with an eye toward improving performance and identifying the root cause of issues. The focus is slightly different from monitoring, where we often focus more on resources and health. We need both, but often in trying to improve software and the behavior for users, developers need observability. Infrastructure people responding to acute issues and looking to ensure we have the capacity, availability, and other x-bilities, that need monitoring.
Today I’m wondering if you collect a variety of types of metrics for your software that might tell you how your system is running. What things are important to you in order to better serve your clients? If you’re a DBA/sysadmin, what is important to you? If you are a developer, are there different types of data you want?
Certainly, you might collect various resource measures (CPU, IO, reads, etc.), but there are many more things. There are logs, which could include the SQL Server error log, but I’d hope that you had a more in-depth way of measuring the activity on your system. Do you have custom xEvent traces running? Can you collect application logs easily when you’re looking at issues? Do you spend time trying to solve chronic issues? Do you look for potential future problems?
Most software applications should include some sort of basic logging of major functions, but I would hope that there are various levels available. If problems are reported or noticed, can you increase the detail of logging? Can you correlate this with logs from different systems, such as the database? Can I get execution data that matches calls and trace down the potential issues that users are experiencing?
I know that we have problems in applications. Some (many?) of these are data-related, which might be easy or hard to trace down. That often depends if the data changes too quickly or is static enough for someone to investigate a report. Some errors are logical code errors, which might indicate a lack of testing early in the software process, but we ought to be able to determine this quickly from logs. If there are performance issues, and we have a lot of these, how easily can we verify a problem?
Let us know what types of metrics help you solve issues. I certainly think that you should have some sort of monitoring and observability system in place that helps you dive deep into the database, especially concerning execution plans at the time of the issue. The situation can change quickly inside a database, so capturing data regularly is important. If there is something you wish you had, let us know as well. Maybe someone else will have a neat solution for you.
I delivered a talk today on database deployment best practices at the Denver Dev Days 2024. This is a great event, and I have been lucky enough to attend a few and speak.
Recently the Flyway Desktop (FWD) team release support for state-based deployments. These are similar to SQL Compare deployments, but with your code source control, which is where you want it. This post looks at how this works.
I’ve been working with Flyway Desktop for work more and more as we transition from older SSMS plugins to the standalone tool. This series looks at some tips I’ve gotten along the way.
State-based Projects
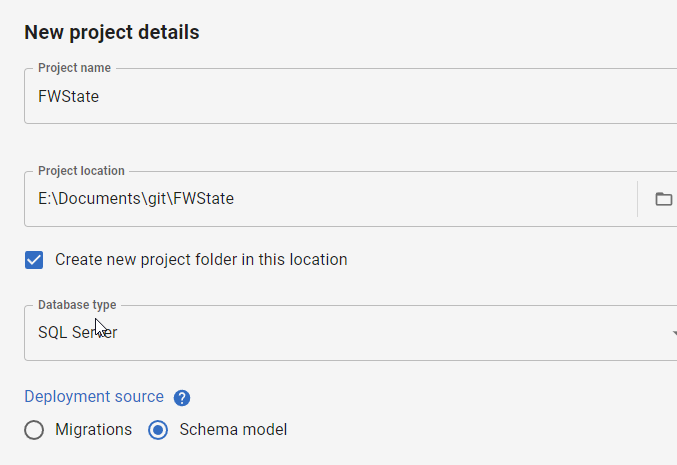
When I create a new project, I now have a choice: migrations or schema model (state-based). You can see the choice below.
I’ll demonstrate this now by creating a new project. I give it a name, folder, type, and then I pick the Schema model deployment source.
Once that is complete, the project is set up and I need to link a development database. I’ll do that first, picking a database with a few objects. In this case, I’ve picked my FWState_1_Dev database.
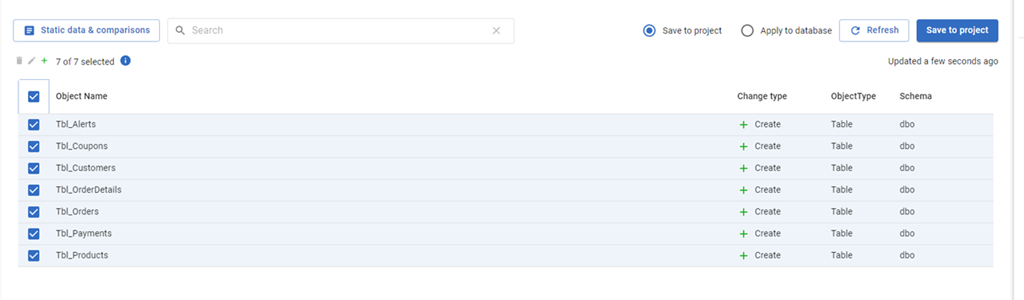
Once this is linked, the FWD tool will read the database, compare to my filesystem and tell me which objects have changed. Since this is a new project, all the objects are new and show up. I’ll select them all and click “Save to project”.
This gets all the code for my objects into the file system (and a VCS). I won’t commit these now in this demo, but normally I would save this code.
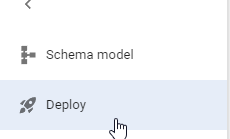
The main change in FWD is the change on the left side menu. Where we have “Generate migration scripts” and “Migration scripts” as options for a migration based project, for a state-based project, we have just a “Deploy” option. I’ll select that.
Once this happens, I have to pick a target. I haven’t configured anything (this is a new project), so I’ll select the “Manage environments” in the upper right section of FWD.
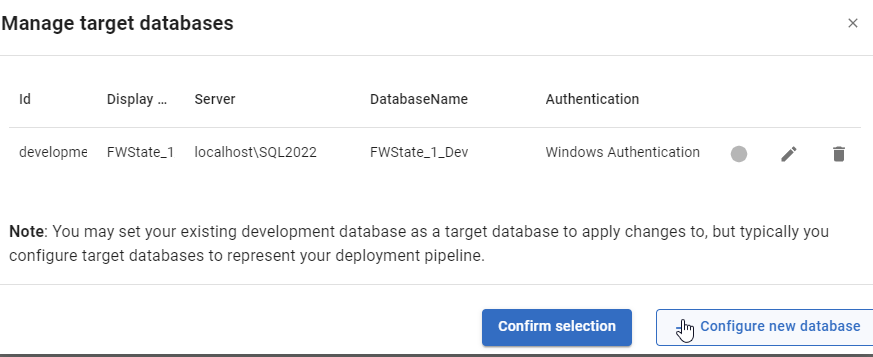
When I do this, I see the environments I’ve configured. So far, I’ve only configured a development environment, but I can click “Configure new database” to add a downstream target.
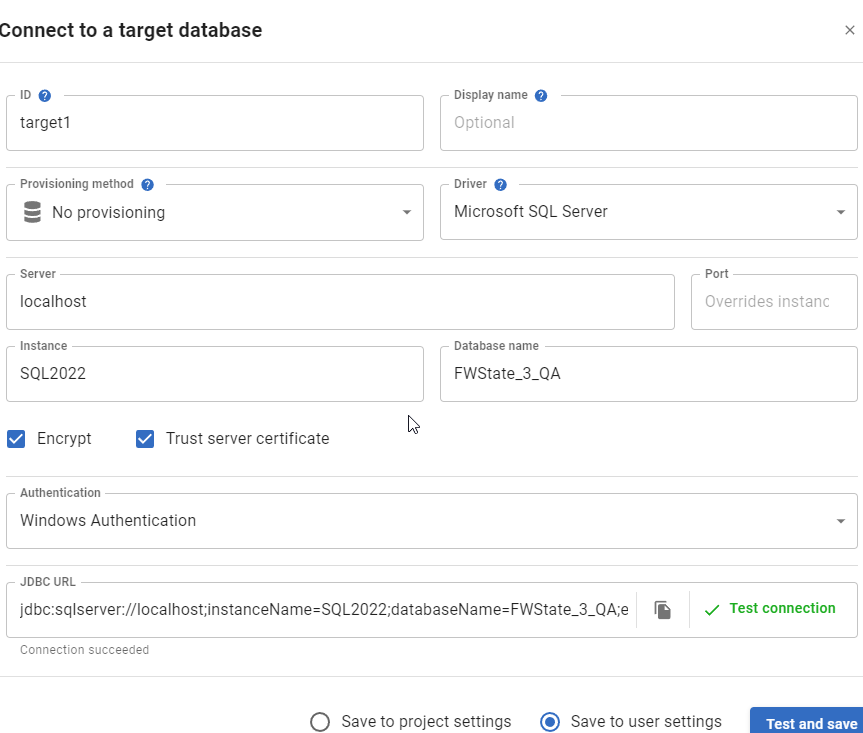
I get the standard FWD connection dialog, and I’ll enter details for my QA database. I usually also click “Test” to ensure I haven’t typo’d something. You can see I didn’t make a mistake below.
Once this is added, it is selected by default. However, I can always click the radio button in the Manage environments dialog and click “Confirm”.
This brings me back to the FWD screen where I see the changes that exist in the project, but haven’t been deployed to the target. In this case, it’s everything (QA is empty). I’ll just click the tbl_Customers table.
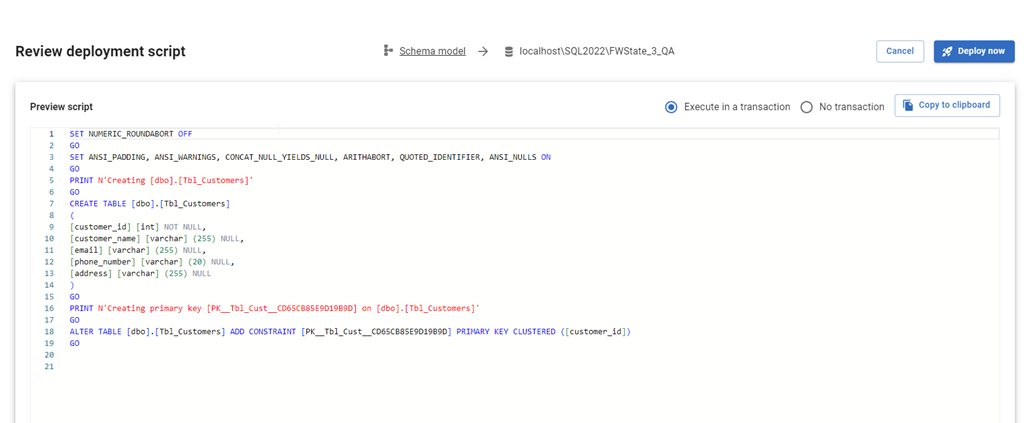
When I click Deploy, the script is generated just as it would be in SQL Compare to update the target with the code from the source. I can review the script, as well as change options. I can add an explicit transaction around all changes, or let them run with the default implicit transaction for each statement. I can also copy the script to the clipboard if I want.
If I check QA, I see no tables.
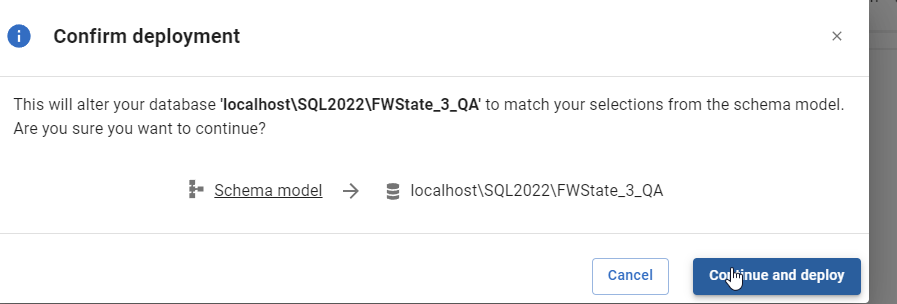
I’ll click “Deploy now” in FWD and the deployment starts. I confirm this is what I want to do.
Once this is done, FWD returns to the screen of objects. Note that tbl_Customers is no longer listed. The project and the target are in sync for this object.
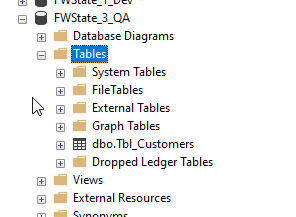
If I go back and refresh QA in SSMS, I see the table exists.
Summary
This short post shows how FWD and the Flyway system can be used to perform state based deployments, similar to SQL Compare or SQL Source Control. If you are used to working in SQL Source Control, this is an easy transition for you to a more modern tech, which will also support Oracle, PostgreSQL, and MySQL.
Try Flyway Enterprise out today. If you haven’t worked with Flyway Desktop, download it today. There is a free version that organizes migrations and paid versions with many more features.
If you use Flyway Community, download Flyway Desktop and get a GUI for your migration scripts.






 Voice of the DBA
