Tag: disaster recovery

  • The Impact of Outages

    This is not what any of your clients want to see. So prepare for issues

    Are you going to start seeing more pressure for outages in applications? I suspect many outages are caused more by application issues than database ones, but those two are becoming very tightly linked as we look to more rapidly deploy features and enhancements in our applications, which often include database changes

    This outage from United shows that there can be a huge impact, not only financially, but also an inconvenience to clients and potential lost future business. A company might struggle to with future business after a large outage, especially when there are so many other choices easily available to consumers across the Internet.

    That brings to mind a very interesting problem as companies grow and look to build scalable systems. Large groups of servers require some level of standardization, mostly for the ease of management by IT workers as well as the ability to train future workers to understand the systems. However that standardization becomes a point of failure when there is a problem during an upgrade, or even a hack from some type of malware.

    I saw an interesting piece on how Netflix has tried to expect, and handle failures in the cloud, and a comment from Jeff Atwood that you ought have your own chaos monkey to regularly test your systems. Interesting advice, and in many cases, it’s probably good advice to ensure that both your systems and your people know how to deal with outages.

    You probably cannot eliminate outages, as Netflix and many other companies have learned. However you can work to ensure your people and systems know how to respond. I also wonder if having (at least) two versions of your systems out there at all times that work in a similar way might be a way to provide some tolerance against a single point of failure. I don’t know how you might implement this, but it might provide some protection against a failure in a completely homogeneous environment.

    Steve Jones


    The Voice of the DBA Podcasts

  • Multiple Failures

    Imagine this right after a failed RAID array.

    When we have a large scale disaster from a man made system, usually we have had multiple things go wrong. Chernobyl had multiple failures, so did the recent issues in Japan at their nuclear facility. It seems to me that in many cases when Mr. Murphy has struck in my career, he has done so multiple times.

    Recently I was studying some high availability (HA) scenarios. In a mirroring situation the implication of a long mirroring queue was shown dramatically as a the primary server failed and the company experienced data loss in a failover to the secondary server. The data was eventually recovered by bringing up the primary server, extracting the missing data, and then manually merging it back into the system.

    Incidents like that are never fun to deal with, but are they common? It seems that the old adage about “when it rains it pours” has happened more than a few times in my career, but for this Friday I wanted to see if that has been the case for the rest of you.

    How many of you have had multiple failures at the same time?

    A RAID drive fails and shortly thereafter a network card dies. You find corruption and while working on that, the server hardware crashes. Have any of you had two or more failures occur on the same system at almost the same time?

    Let us know this Friday, along with any lessons learned. Have you changed the way that you prepare for disasters or plan for issues in your career? I’m sure there are many people that would love to learn those lessons from a post rather than experiencing them first hand.

    Steve Jones


    The Voice of the DBA Podcasts

  • BCPs – The Disaster Recovery Plan

    I came up with a short acronym for my Preparation for Disaster presentation: BCPs. It describes what I think you need to do in order to be prepared for issues with your database server. The initials stand for:

    • Backups
    • Checks
    • Practice and Preparation
    • Script and Schedule

    With a utility in SQL Server going by BCP, this ought to be easy to remember. I’ll describe what I mean below by each of these:

    Backups

    You need to make sure that you have backups. They are insurance for the issues that will befall you at some point. They are also required for restores, which do matter.

    You need a backup plan that meets the need for the particular system you are protecting. Not your entire infrastructure, but what’s appropriate for each system. Once size does not fit all here.

    Checks

    You can’t prevent corruption and it can occur at any time. The best you can do is detect it early, and fix it as soon as you can. Make sure you have checks in place that look for corruption.

    You also want checks for things that are out of the ordinary. Make sure you have some monitoring/base-lining set up so that you can proactively be aware of what a disaster might occur.

    Practice and Preparation

    All of the backups, checks, etc. in the world are useless if you don’t know how to apply them. Or if you don’t have the keys, passwords, account numbers, etc. Practice the skills you need to recover your systems, and make sure that you are prepared to do so in a variety of situations.

    Explaining to your CEO that you don’t have the keys for that TDE encrypted restore will make for a very, very bad day.

    Script and Schedule

    You must automate most of your job to be successful and efficient, and you ought to have lots of your DR insurance (backups/scripts) scheduled so that it get performed in a timely manner, and a regular manner. Humans forget things, and make mistakes constantly. You need to ensure that you are scripting your tasks (to speed up processes) and scheduling them (to ensure they occur regularly).

  • T-SQL Tuesday #19 – Disaster Recovery

    TSQL2sDay150x150This month Allen Kinsel hosts T-SQL Tuesday #19 with a disaster recovery theme. This is the blog party idea started by Adam Machanic where everyone that participates writes on a single theme.

    If you want to host, contact Adam. If you want to participate, read Allen’s post and write your own post and link it in.

    What’s a Disaster

    It’s interesting that this is the theme since I already had two posts on DR scheduled this week and am working on modifying my “Preparation for Disaster” presentation for SQL in the City.

    It’s hurricane season for Allen on the Gulf, and while hurricanes give you advance notice when they are coming, you have to be prepared. I’ve lived on the East coast, and we always were worried about getting hit in Virginia Beach. We never did get hit, but that didn’t stop us from being prepared and sometimes even initiating some of our disaster protocols.

    As a side note, we had an office in High Point, NC, and it actually got hit by a hurricane, or the remnants of one and lost power. I was in a downtown hotel at the time and woke up without power.

    The thing is large disasters are rare. You have very little chance of your data center getting hit by a hurricane, a tsunami as Japan recently had, a tornado such as the Northeast have experienced this year,  They happen regularly, but the chance of them hitting your data center is low. The chance of you “losing” a data center is low. It just doesn’t happen that often, and the complete loss of a data center might mean you have bigger things to worry about.

    However there are plenty of disasters that you are likely to experience. It’s possible that you could have a fire in your data center that affects the database server. Not likely, but it could happen. It’s more likely that you could have one of these:

    • an operator spill coffee on your server
    • someone trips over a power cord or fiber cable and brings down your system
    • a memory chip go bad and get in memory corruption.
    • it’s possible power goes out for some reason, even with a UPS.
    • It’s highly likely that a drive will fail that contains data you need.

    These are the types of disasters that you really have to prepare for, since they are possible, and even likely.

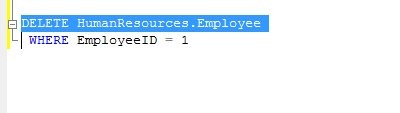
    What’s more likely are the “Whoops” disasters as I like to call them. It’s very likely that someone will import the wrong file, update all prices instead of one, or even more likely, a developer or DBA will run the wrong code on the wrong server. The most likely disaster is probably this one:

    drwhoops


    If the DBA hits “Execute” here, it’s a disaster. Not a big one, but if this is a critical table in a critical system, you might have an even bigger reaction from manangement than if a hurricane hit.

    You have to prepare for disasters, but don’t get caught up in worrying about the data center being destroyed. Those disasters are rare. Most of your preparation, your practice, your checks, have to be focused on the more likely disasters, which are often smaller in scale and focused on your database.