Tag: software development

  • DBAs Need to Learn to Develop

    This editorial was originally published on Jan 7, 2014. It is being re-run as Steve is at SQL in the City today.

    My first exposure to computers was as a child, learning to program in BASIC, Assembler, and Pascal. From there I moved into other areas, such as networking and system administration. I learned about a variety of technologies before focusing on databases, but I found that my knowledge from other areas of computing helped me be a more successful DBA at quite a few jobs.

    Last year we put on a number of SQL in the City Seminars where Grant Fritchey and I talked about development practices. We give a variety of advice and practices that you can use, but one of the best things that we say in our half day event comes from Grant. He says that DBAs need to “Follow the local development paradigm as much as possible.”

    I completely agree with this. I think that many of the practices of building software, as flawed as they might be, are good ideas that many developers use on a regular basis. They know how to work in a flexible manner, tracking their code and keeping it under control, and fixing problems in a rapid manner. As immature as the software development process can be, there are things that we, as DBAs, can learn.

    As SQL Server continues to grow as a platform, there are more and more enhancements, many of which involve programmatic capabilities expanding. I highly recommend that DBAs think about learning more about programming, and specifically a .NET language, if you’ve never used one. If you have, consider brushing up those skills.

    Steve Jones


  • DLM Automation–Making a Database Connection

    One of the things I’ve been wanting to do is dig more into the command line automation cmdlets from the Redgate DLM Automation suite. While there are plugins for many build and release systems, I should be able to customize, or fall back, to the command line if necessary.

    Plus, this allows me to get a better feel for what’s happening at each step.

    This post looks at the basics of making a connection to a database. Note that this is documented on the DLM Automation 2 Cmdlet Reference page.

    New-Database Connection

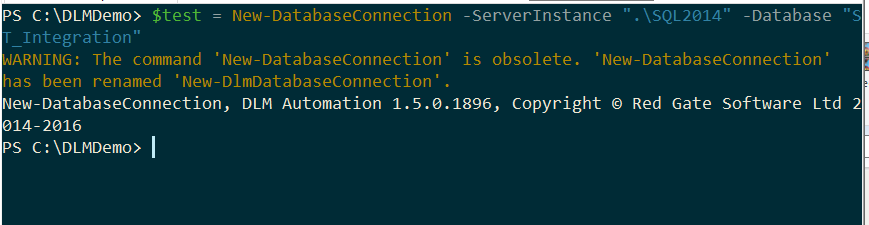
    When I started working with the connections, I used the New-DatabaseConnection cmdlet. However, when I run this now, I get this:
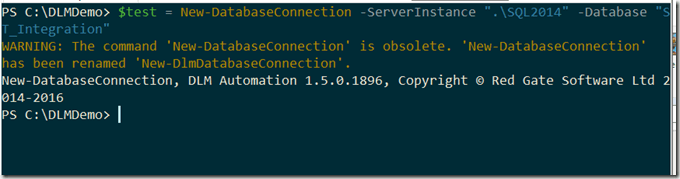
    2016-10-14 15_32_04-DLM Automation–Making a Database Connection - Open Live Writer

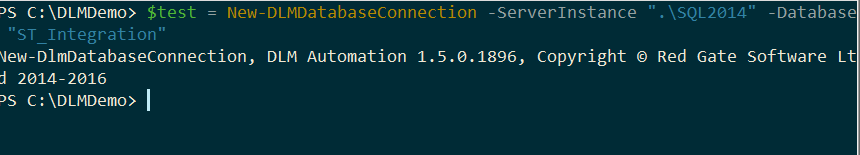
    That’s fine, as my call to the new cmdlet works.
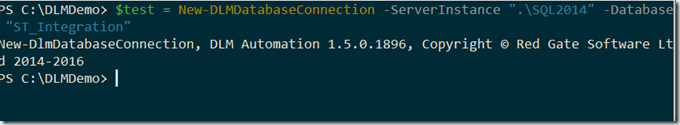
    2016-10-14 15_32_34-cmd - powershell

    Do I know what’s happening here? I should investigate further.

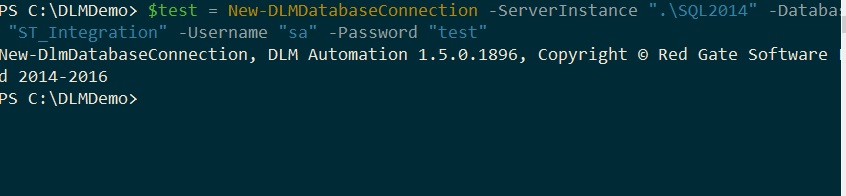
    First, if I’ve run this, what does it do? Not much, apparently. If I run an Extended Events session looking for a connection, I don’t get one. Let’s try a new command, this time using a name and password.
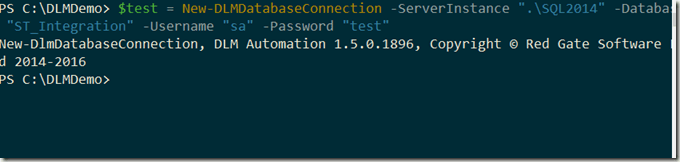
    2016-10-14 15_37_53-cmd - powershell

    That’s an invalid password for my instance (as it should be on every instance in the world). However, I don’t get an error. No connection was made. In this case, the cmdlet is storing off the connection credentials that will be used. If I don’t provide the user/password, then a trusted (Windows auth), connection is assumed.

    Can I now test this? Sure, I’ll use the Test-DLMDatabaseConnection to make a connection.

    2016-10-14 15_39_37-cmd - powershell

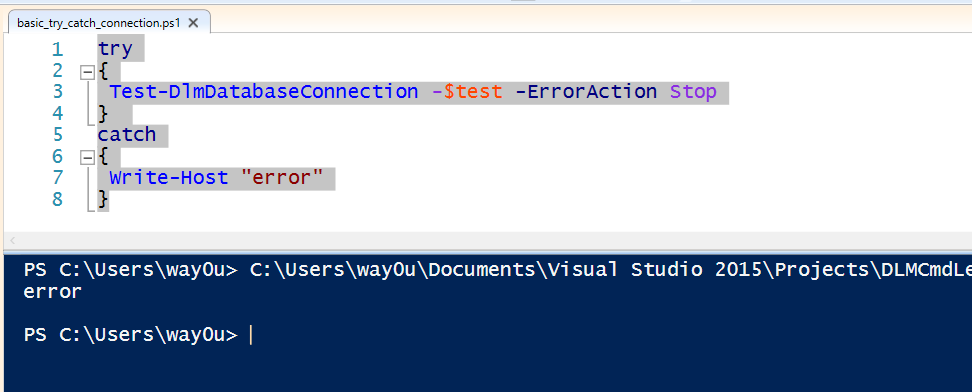
    This fails. That’s good to know. Now I can use this to actually determine if I target database is alive before I continue processing. My preferred method here would be to wrap this up in some error handling. For example, I can use a try..catch structure in PoSh. I’ll switch to the ISE to make this cleaner. Here’s the code

    try
    {
    Test-DlmDatabaseConnection -$test -ErrorAction Stop
    } 
    catch
    {
    Write-Host "error"
    }

    In the ISE:
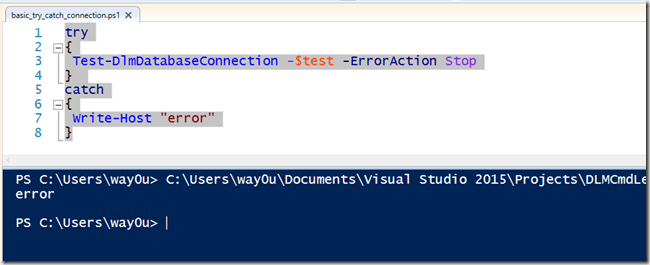
    2016-10-14 16_22_45-Windows PowerShell ISE

    I can also get the error details from the current object ($_). Note, I’m not a PoSh expert, so if there are better ways, let me know.
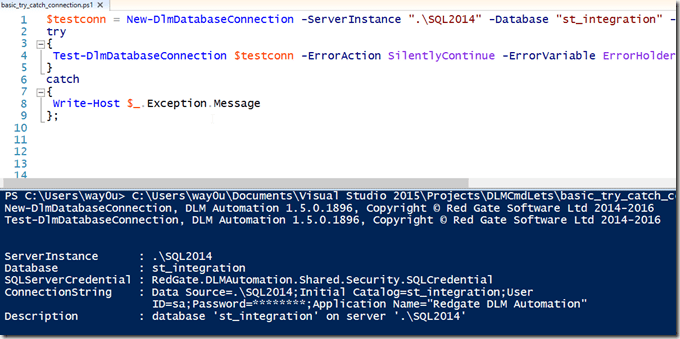
    2016-10-14 16_36_48-Windows PowerShell ISE

    I can also pass in some common parameters, like –ErrorAction and –ErrorVariable. Then I can use these to decide whether or not to continue. In my case, I’ll just write a message. Here’s my code:

    $testconn = New-DlmDatabaseConnection -ServerInstance ".\SQL2014" -Database "st_integration" -U "sa" -Password "test"
    try
    {
    Test-DlmDatabaseConnection $testconn -ErrorAction SilentlyContinue -ErrorVariable ErrorHolder;
    } 
    catch
    {
    Write-Host $_.Exception.Message
    };
    
    if ($ErrorHolder)
    {
    Write-Host($ErrorHolder)
    }
    else
    {
    Write-Host("Everything works");
    }

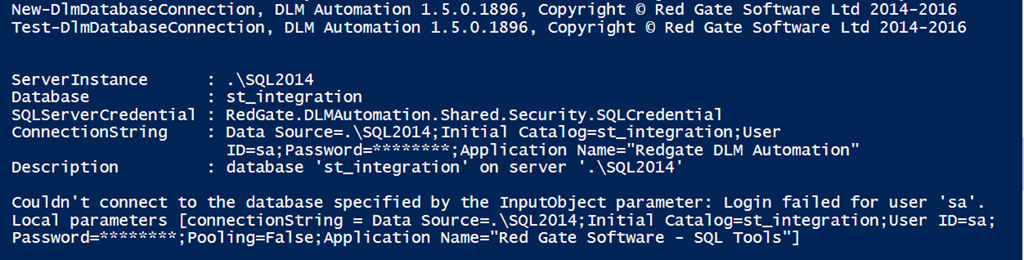
    That will give me this:
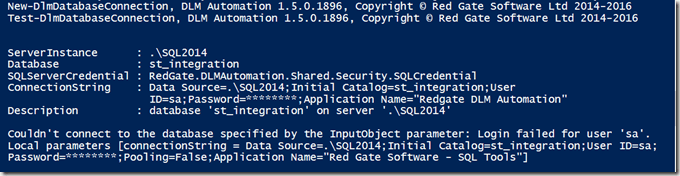
    2016-10-14 16_41_08-Windows PowerShell ISE

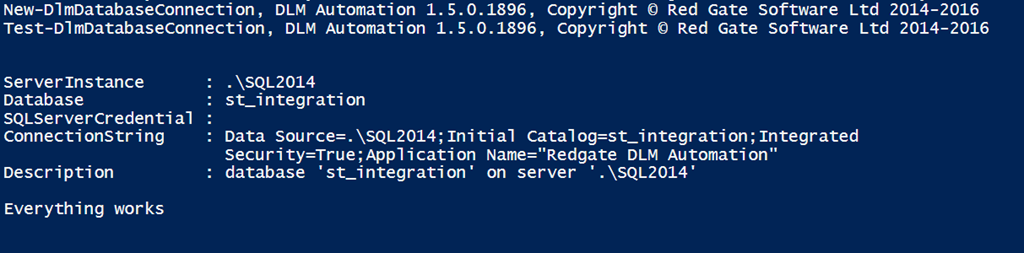
    If I remove the user and password parameters, I get this:
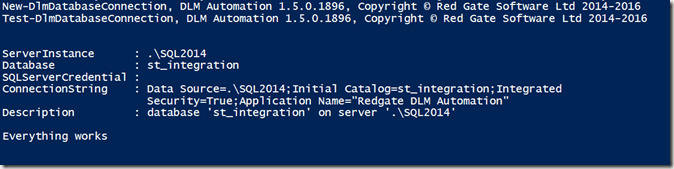
    2016-10-14 16_41_29-Windows PowerShell ISE

    You didn’t think I’d publish the real sa password, did you? Of course not. If I change the code to the right password, things connect.

    Checking the Object

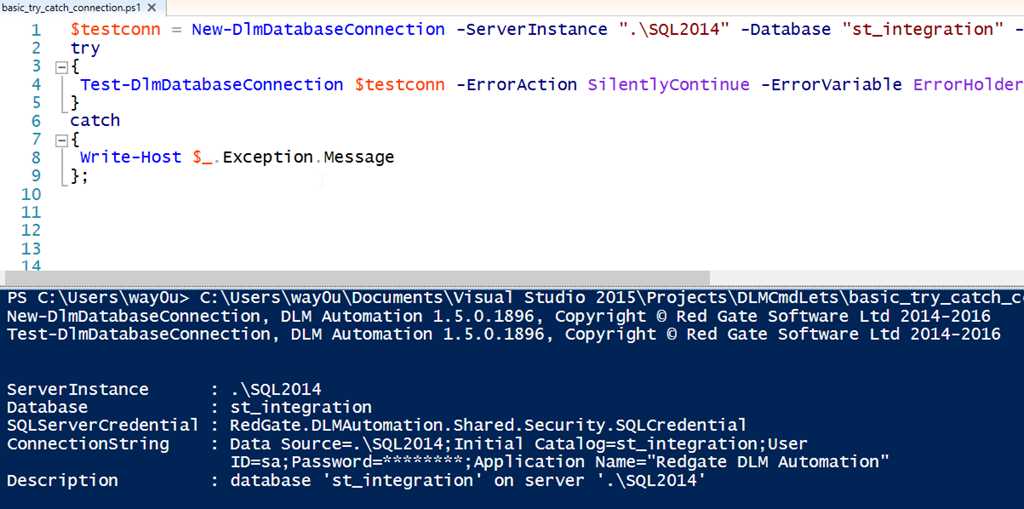
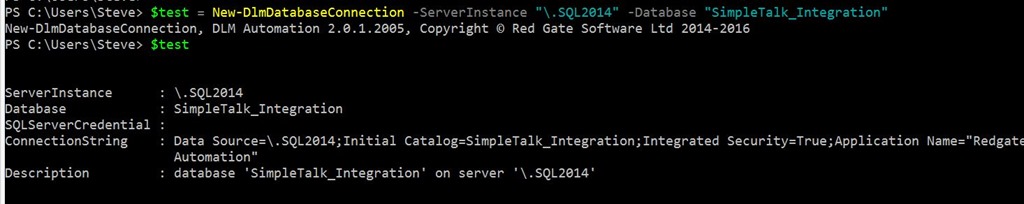
    What if I just want to check the object? Well, there are properties associated with the object. For example, if I use a simple variable to assign to the object, I can see some properties. If I just type the variable name, $testconn, I get these properties:

    • ServerInstance
    • Database
    • SQLServerCredential
    • ConnectionString
    • Description

    You can see these returned in a test session.
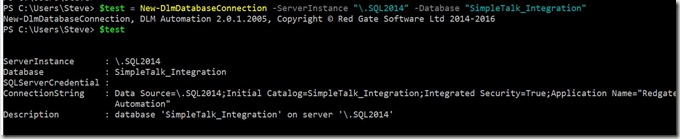
    2016-11-14 16_58_29-cmd - powershell

    Other Options

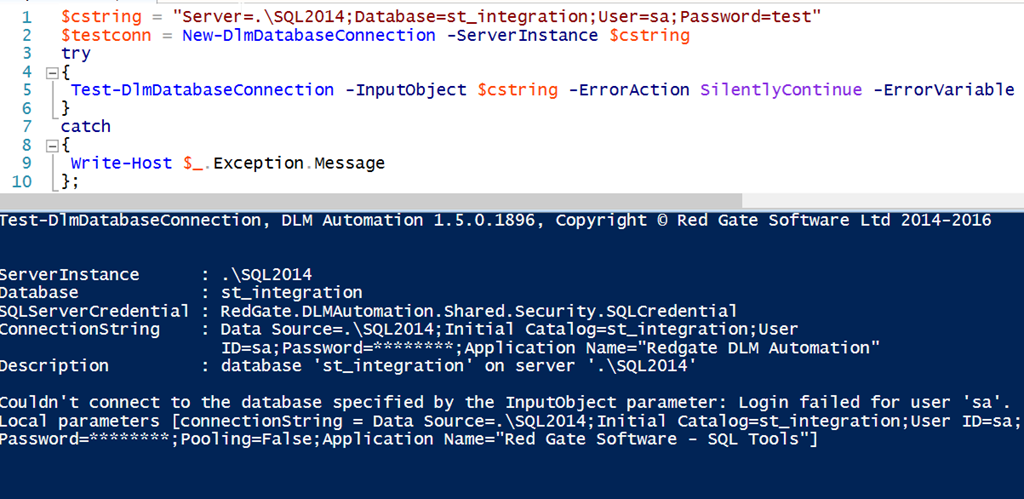
    I have other parameters I can use with my connection, or rather, in place of my connection object. I can use a connection string, with all of the parameters that are valid there. For example:
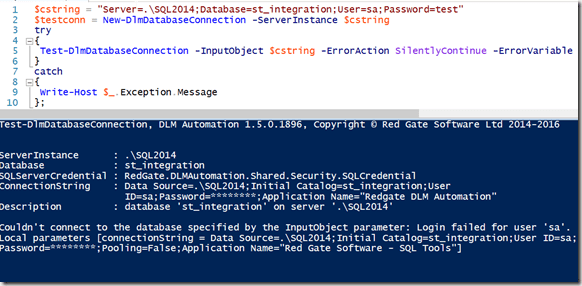
    2016-10-14 16_53_17-Windows PowerShell ISE

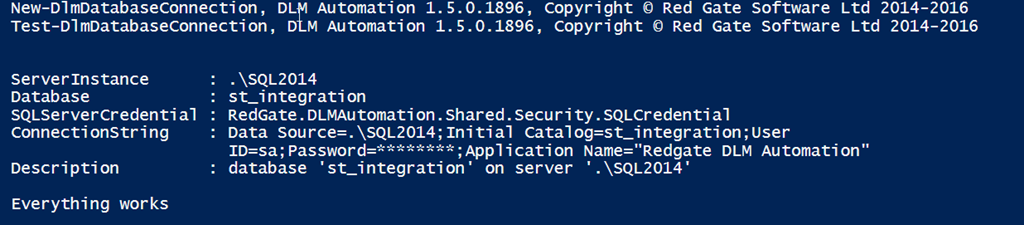
    If I enter the correct password, I get this:
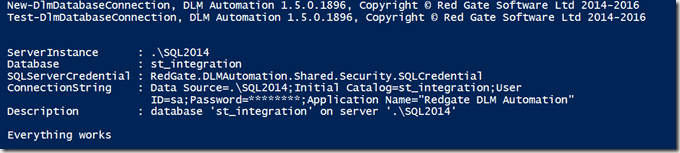
    2016-10-14 16_54_09-Windows PowerShell ISE

    My connection string can contain all of the items I might normally use: ApplicationIntent, Encrypt, NetworkLibrary, etc. A full list of parameters is at: https://www.connectionstrings.com/all-sql-server-connection-string-keywords/

    The New-DlmDatabaseConnection object outputs a RedGate.DLMAutomation.Compare.SchemaSources.DatabaseConnection object, which is the input to quite a few other of the cmdlets. While not complex, it is worth understanding how to use this cmdlet, which is the basis for determining from which source or two which target you will be moving database changes.

    In another post, I’ll start to bind this cmdlet with others and actually perform some database deployment automation work.
  • Held Hostage by the Database

    Your database platform will constrain and limit the flexibility you have in evolving your software. It doesn’t matter which platform you choose, which type of database, or even the format for your data. At some point, you will be dealing with legacy data in some legacy schema or structure, and your development, and certainly deployment, will be slowed or impacted. Face it, the need to maintain state for your data is an impediment in a relational system. In a NoSQL or other store, the need to maintain code in your application that can interpret your data might be the issue over time.

    That’s not to imply this need to maintain state has to slow your development. On the contrary, there are many companies that find themselves moving quickly, able to make database changes on a weekly, or even daily, basis. There are multiple tricks and techniques for managing change, but ultimately the real secret is having a process that computers can follow and your developers adhere to.

    In other words, having some automation.

    Certainly you need to program the automation, or use tools like those from my employer, Redgate Software, but it doesn’t matter which what process you use. The process does need to be flexible because it will change over time. I can almost guarantee that the way in which you need to deploy code to the database in your environment will change over time. It has to as the needs and requirements of your business change.

    This means the way in which your developers need to build, test, and package changes will need to grow and evolve as well. While every developer and sysadmin needs to work within the process, the process does also need to be flexible as needs change. That isn’t to imply that your process should change every week, or for every deployment, but it will need to do so periodically, and hopefully, rarely.

    There are techniques to make deploying database changes easier on the developer and system administrator, but there are no magic techniques. All the tools I’ve encountered, including those from Redgate, do the same types of things you’d do manually. They just save you time and stress by helping you get set up and easily maintain your deployment tasks over time.

    Whether you use tools or not, please don’t allow the database to hold back your software development. Learn new ways to alter your database. Learn the ways to make changes to large tables. Learn how to avoid downtime. Just learn to design database changes in a better way and then automate the deployment of those changes.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.6MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • Server Hardware or Coffee?

    I actually chuckled out loud in my office recently. I was reading a piece about Expensify and how they learned some lessons from their database architecture over time. It’s a good piece, but at one point the author talks about two Dell servers. There’s a dual core 2.8Ghz CPU with 500GB of storage for US$700. This could be upgraded to an 8 core, 3.7GHz CPU with 64GB of RAM and 10TB of storage for around US$3,200. However, the author says don’t be cheap. Why?

    That’s less than the company spends on coffee each month.

    I thought that line was funny, and it proves a point. It can be easy to think about the cost of hardware as being high because it’s a large ticket item for most of us. When you view it in the context of the scale of business, then it’s cheap. If any of us spent $3000 a month on food, we might not think $3000 for a server is expensive. When you look at the cost of your labor that might need to babysit an underpowered system, a few more thousand dollars seem like a bargain for memory or CPU resources.

    The author also notes that while EC2 charges for managing your systems, it’s still a steal, and for many of us, capacity isn’t a big issue. We do find that one single system runs most of our workload. If it doesn’t, then we could buy more, or a second system, for a relatively low cost. At least, compared to the rest of our business.

    There certainly are some of you that have a large workload, or you have spent substantially more on server hardware. I think many of my systems have been tens of thousands of dollars, but there are good points to be made. Today’s computers are very powerful, and even though we have more data, a single server is likely able to handle many workloads.

    If we write good code.

    That’s a big caveat, but training your staff to code better, having them spend time learning to query hierarchies more efficiently or quickly splitting strings, can pay off with much happier servers and customers. While I am a fan of using hardware to avoid spending too much time tuning queries, I also think continuously improving the skills of your development staff is much more important and might be the best IT investment you can make. Assuming, of course, that you treat them well and they enjoy working for your management staff.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.9MB) podcast or subscribe to the feed at iTunes and Libsyn.