Tag: SQLNewBlogger

  • FILESTREAM v FileTable –#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    I was really interested in the FILESTREAM technology when it came out. Unfortunately, the access from only Win32 APIs made this a pain for many people. I get why this is needed, but without having some tooling to make it easy to add/edit/delete blobs.

    In SQL Server 2012, we got FileTable, which simplified development and allowed everyone to easily get data in and out of SQL Server.

    This post looks at a few differences between the technologies.

    FILESTREAM is essentially a folder surfaced as a column in SQL Server. You can create a filegroup to hold FILESTREAM files, and these are paths. The path is managed by SQL Server, and when you designate a column as containing FILESTREAM data, a new folder is created.

    None of that matters, as you should NEVER go to these folders, but this is also how some other things in SQL Server  (like In-Memory OLTP) also work.

    Access to this data is with a Win32 API, and it’s semi-complex. Not hard, and really you can use the sample code (with some additional error handling) to do the work you need. On the application side, you need to do some stream handling and manipulation, but that’s really not difficult. It can be cumbersome, but it’s easy.

    FileTable was an additional layer that gives you SMB, or Windows Explorer, access to the data in the FILESTREAM column. Except, you can’t make a FileTable column, you create a FileTable, which has some restrictions, limitations, and required columns. You can add some things to the table, but really you want your FileTable to be a vertical partition of your regular OLTP data. Separate out the blob stuff from other items in your entity.

    Both save your data in database backups, both are more efficient for semi-large blobs moving in and out of SQL Server.

    Neither works in the PaaS cloud, though they could. I’d hope that FileTable especially would be added, with some enhancements to smooth the way a FileTable is structured, ubt I think with the focus on database level technologies (contained in a db), this technology is likely never getting any enhancement.
  • Don’t Forget Unique with FILESTREAM–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

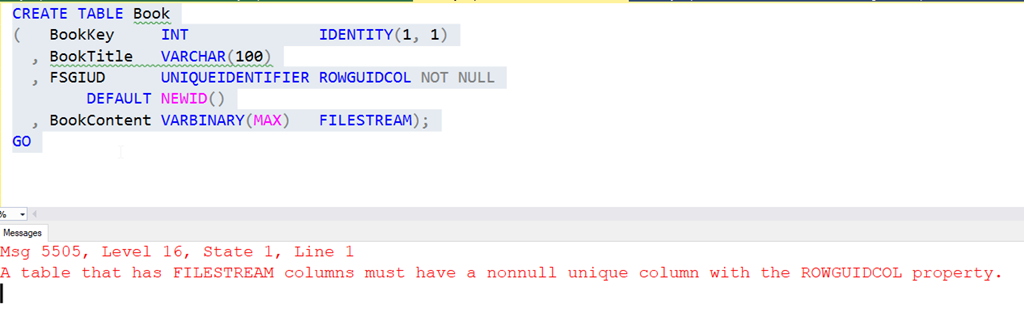
    While testing FILSTREAM with SQL Clone the other day, I kept getting an error while trying to create a table. I’d click Execute and see this:

    2020-08-12 14_10_37-SQLQuery2.sql - ARISTOTLE_SQL2017.FSTest (ARISTOTLE_Steve (58))_ - Microsoft SQL

    My mind kept focusing on the ROWGUIDCOL part, and not thinking unique. It’s been a few years since I worked with FILESTREAM as it’s not an Azure feature and things have been going that way for me.

    In any case, after running this a few times, and then checking an old demo, I realized that I had forgotten UNIQUE as an attribute for the column. Once I added that, it worked.

    The docs for CREATE TABLE shows this that unique is listed as a constraint property, but under the FILESTREAM section, is does say this about the ROWGUID column: “This column must not allow null values and must have either a UNIQUE or PRIMARY KEY single-column constraint.”

    Don’t forget this, but if you do, read the error message,

    SQLNewBlogger

    This post took me about as long to write as it did to realize I was being silly and forgetting to read. Overall, this was about 10 minutes to compile, take the screenshots, and get the references.

    When you write, look for places you’ve learned something, and then use those as ideas for blogs.

  • Quick SSMS Tip: Map Mode for Code–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    In recent versions of SSMS, there’s been an addition to the query windows that I find helpful and useful. This is the map mode for code, and it means that when you have a large script, you can get a quick view of where you are in the file, and where you code is located.

    First, turning this on. In the Options for SSMS, select the Text Editor section on the left, then expand the All Languages item. There is a Scroll Bars section to select. When you pick this, on the right you will see the Behavior section near the bottom. The default is bar mode, but you can switch this to map mode.

    2020-07-23 16_44_26-Window

    When you do that, if you open a script that is bigger than your query window, you will see a map of the code, along with a light colored bar that shows where you are in the code.

    In the image below, Glenn Berry’s diagnostic script is open, and  I have actual code near the middle of my screen, and on the right, you can see the pink just at the bottom of the oval that’s lighter in color than the map.

    2020-07-24 10_24_27-Window

    This is a little hard to describe, but if you turn this on and experiment, you’ll get an idea of what happens.

    Let me add some blank links to this script. When I do that, I can see the map expand with some gray spaces near the top.

    2020-07-24 10_46_23-Window

    You can also get a preview of code by putting the cursor on the map to the right. Below I’ve put the cursor on the right side, above the current location in the query window. I see a preview of the code, while I see the locator bar below the preview, showing me where I am in the code file.

    2020-07-24 10_47_33-Window

    Map mode is an interesting way to manage large code files, which sometimes occur in stored procedures and complex queries. While I would hope that most people don’t have hundreds of lines of code in any one file, I do know some do. Map mode can help.

    SQLNewBlogger

    This was a question someone asked me in a presentation. It took me almost as long to type an explanation as it did to take a few screenshots. Adding a little text made this a 10 minute effort.

    This is the type of thing that you can do, showing how this might help you with some code that is complex and harder to navigate. In addition, this is a nice way to show you are honing your craft and learning to use your tools.

  • Adding a FK to a Table–#SQLNewblogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    One thing that helps ensure your data is intact and doesn’t get out of synch in a relational database is a foreign key. You ought to have these as a part of your design, ensuring that a linkage between a parent and child cannot be broken.

    This post looks at adding a FK to an existing table. I’ve written about how to do this in the CREATE TABLE statement in another post.

    I have two tables set up: Contacts and Status. Both of these have a StatusID column in them. The Status table contains the lookup values, and these are stored in the child table, Contacts.

    To add the foreign key, I add a constraint with the ALTER TABLE ADD CONSTRAINT syntax. After this, I use FOREIGN KEY to list the column(s) and then the REFERENCES phrase to point out the parent table and column.

    The example is shown here:

    ALTER TABLE dbo.Contacts
       ADD CONSTRAINT FK_Contacts_Status_StatusID FOREIGN KEY (StatusID)
          REFERENCES dbo.Status (Statusid)
    ;

    This will give me  a FK that enforces the values in Contacts as existing in Status.

    SQLNewBlogger

    I had to do this recently and decided to quickly write this up as I had to look up the syntax to be sure I remembered it correctly. Then it took me about 5 minutes to produce this.

    It took me almost as long to see if I’d already written about altering a table with a FK.

    Do this for your career, and to show interviewers that you know how to handle common data referential integrity tasks.