Tag: SQLNewBlogger

  • Always Use Roles–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    Which of these is more complex?

    GRANT SELECT ON dbo.Customer TO JoeDev

    or

    CREATE ROLE Sales
    GRANT SELECT ON dbo.Customer to Sales
    ALTER ROLE Sales ADD MEMBER JoeDev

    The second one, right? What if I change this slightly. I have this code:

    GRANT SELECT, INSERT, UPDATE ON dbo.Customer TO JoeDev
    GRANT SELECT, INSERT, UPDATE ON dbo.Customer TO SallyDev
    GRANT SELECT, INSERT, UPDATE ON dbo.Customer TO SaraDBA

    or

    GRANT SELECT, INSERT, UPDATE ON dbo.Customer TO Sales
    ALTER ROLE Sales ADD MEMBER JoeDev
    ALTER ROLE Sales ADD MEMBER SallyDev
    ALTER ROLE Sales ADD MEMBER SaraDBA

    What if I changed this slighly and told you that between the GRANTs to users, a few months of time had passed and you had to go figure out which rights JoeDev had because the request was “give Sally the same access as Joe.”

    That’s the type of thing I’ve done often as a DBA. I’ve often had to move permissions between users, duplicate the access, or quickly remove lots of access from multiple users.
    While it seems like there are just two extra statements using roles, there is often lots of time tracking down security and building statements to duplicate rights.

    Always use roles and your life will be easier.

    Plus you can script the permissions for objects once, log them, and forget about them. From that point forward you’re just adding/dropping users from roles.
  • Lengthen a Primary Key–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    I saw a post recently where someone needed to increase the size of a PK and was getting a table rebuild message in SSMS. This is short post to show that isn’t required.

    First, let’s create a table and give it some data. Note that the PK is set to a specific size.

    CREATE TABLE dbo.Document
    (DocumentKey NVARCHAR(5) NOT NULL CONSTRAINT DocumentPK PRIMARY KEY
    , DocumentName NVARCHAR(200)
    , DocumentDate DATETIME2
    )
    GO
    INSERT dbo.Document
         (
             DocumentKey
           , DocumentName
           , DocumentDate
         )
    VALUES
         (N'ABC23', N'Something very interesting', '2019-01-02'),
         (N'QNI43', N'An adventure you admire', '2019-02-02'),
         (N'MNT33', N'Magnets describing life', '2019-03-04'),
         (N'DEF25', N'Time for nothing', '2019-03-12'),
         (N'HIJ54', N'Dreams of the dark', '2019-04-17')
    GO
    SELECT top 10
      *
      FROM dbo.Document AS d
    GO

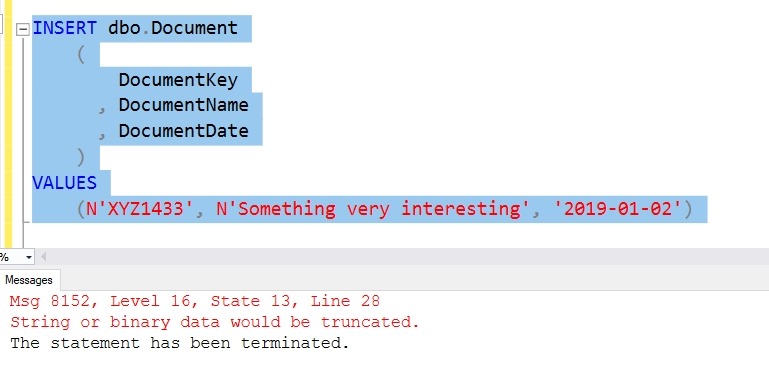
    If I try to insert data that’s larger, I’ll get this message:

    2019-04-16 08_58_43-SQLQuery10.sql - Plato_SQL2017.sandbox (PLATO_Steve (53))_ - Microsoft SQL Serve

    In SQL 2019, I’ll get a better error, but for now, this shows me a limitation of my key.

    Now I’ll increase the size of the key. I use the ALTER TABLE … ALTER COLUMN statement.

    ALTER TABLE dbo.Document ALTER COLUMN DocumentKey NVARCHAR(7) NOT NULL
    GO

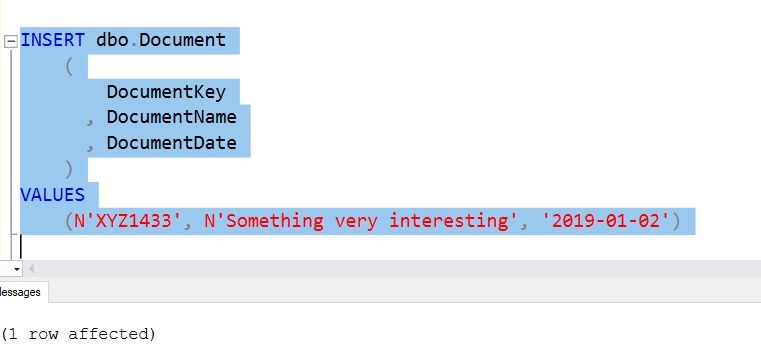
    Now, I’ll run my failed insert again:

    2019-04-16 09_00_00-SQLQuery10.sql - Plato_SQL2017.sandbox (PLATO_Steve (53))_ - Microsoft SQL Serve

    As you can see, I can increase the size of the PK without rebuilding the table. Making it smaller is a post for another day.

    SQLNewBlogger

    This was a quick repro I set up to answer the question for myself and others. I thought I could do this and spent five minutes proving it.

    The longest part of this post was the test data. You could do the same thing, maybe showing how this relates to a child table as well. In fact, start today and you might beat me to creating that post.

  • Upper Casing All the Data–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    There was a post recently where a user asked about needing to update all the data in all their tables to upper case. A somewhat strange requirement, though one I could see in some environments where they want to ensure all  data matches in searches.

    There isn’t a good way to do this, since you have disparate table names and column names. The quick way to do this one time is with a cursor, though I’d worry about performance here if this ran at any scale, and more often than once in a very rare time.

    In any case, the way to get schema, table and column names is to query the INFORMATION_SCHEMA.COLUMNS view. I’d limit this to character columns of the non- and Unicode types. In the code below, I get that data into the cursor.

    DECLARE updatecurs CURSOR FOR
    SELECT
          c.TABLE_SCHEMA
        , c.TABLE_NAME
        , c.COLUMN_NAME
    FROM INFORMATION_SCHEMA.COLUMNS AS c
    WHERE
          c.DATA_TYPE IN ( 'varchar', 'char', 'nvarchar', 'nchar' );
    DECLARE
         @schema VARCHAR(100)
       , @table VARCHAR(100)
       , @col VARCHAR(100)
       , @cmd VARCHAR(8000);
    OPEN updatecurs;
    FETCH NEXT FROM updatecurs
    INTO
         @schema
       , @table
       , @col;
    WHILE @@FETCH_STATUS = 0
    BEGIN
         SELECT @cmd = 'update ' + QUOTENAME(@schema) + '.' + QUOTENAME(@table) 
         SELECT @cmd = @cmd + ' set ' + @col + '= UPPER(' + @col + ')'
         SELECT @cmd
         FETCH NEXT FROM updatecurs
         INTO
             @schema
           , @table
           , @col;
    END;
    DEALLOCATE updatecurs;

    The code then loops through the cursor and builds an update statement for each column. This could be enhanced to get a single statement for all columns in a table, but it’s a quick and dirty piece of code.

    There is a SELECT @cmd statement in there that shows what command is executed. To make this work, that would be changed to EXEC(@cmd), but make sure the code is what you want.

    Not pretty, but effective.

    SQLNewBlogger

    Quick, effective code. This has caveats, but works.

    If you want to write about this, change the cursor to make one update per table.

  • Changing the Database Collation–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    I was testing some changes recently and needed to verify how things worked in a different collation. Here’s the scenario: I had this situation and ran a query.

    2019-02-13 12_22_07-SQLQuery7.sql - Plato_SQL2017.sandbox2 (PLATO_Steve (64))_ - Microsoft SQL Serve

    As you can see, the query rates these two Unicode strings as equal, which makes some sense as this is a Case Insensitive, Accent Sensitive, default US English database.

    I then went to the database properties to change this. When I did so, I picked a case sensitive collation.

    2019-02-13 12_22_55-Database Properties - sandbox2

    I clicked OK, and a few minutes, later I get this:

    2019-02-13 12_25_38-Database Properties - sandbox2

    Hmmm, why is this locked on my workstation? I have a query window open. Changing a collation is potentially a disruptive operation and requires an exclusive lock on the database. This means no other users can be inside the database with a connection.

    The solution? Change the context of my query window. I can change this to master (or any other database) and make the change again.

    While collation isn’t something you often change, if you do find a database that needs this alteration, you will need to drain off any connections before you can make this change.

    SQLNewblogger

    I ran across this while doing testing and realized this was a nice, short piece of information that I should remember. Not because I do this often, but because as I automate changes and use pipelines, I’d need a way to remove all connections before this would deploy.

    An example of a nice short piece of information that I can document about my knowledge, and that might get asked about in an interview.