I haven’t done one of these in awhile, but I saw an article recently about this and decided to explain it to myself, but in a slightly different way. You’ll see how I checked on RANK() vs DENSE_RANK() below.
Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.
Getting Started
Imagine you’ve never used these functions, but you need to rank some data. Let’s say that you have a series of things that measure sale and you want to know who has done the best job this week. I’ll start with AdventureWorks, and we’ll assume it’s June 2011. If I look at some data from that database, I see this. Order Headers and Order Details from that range.
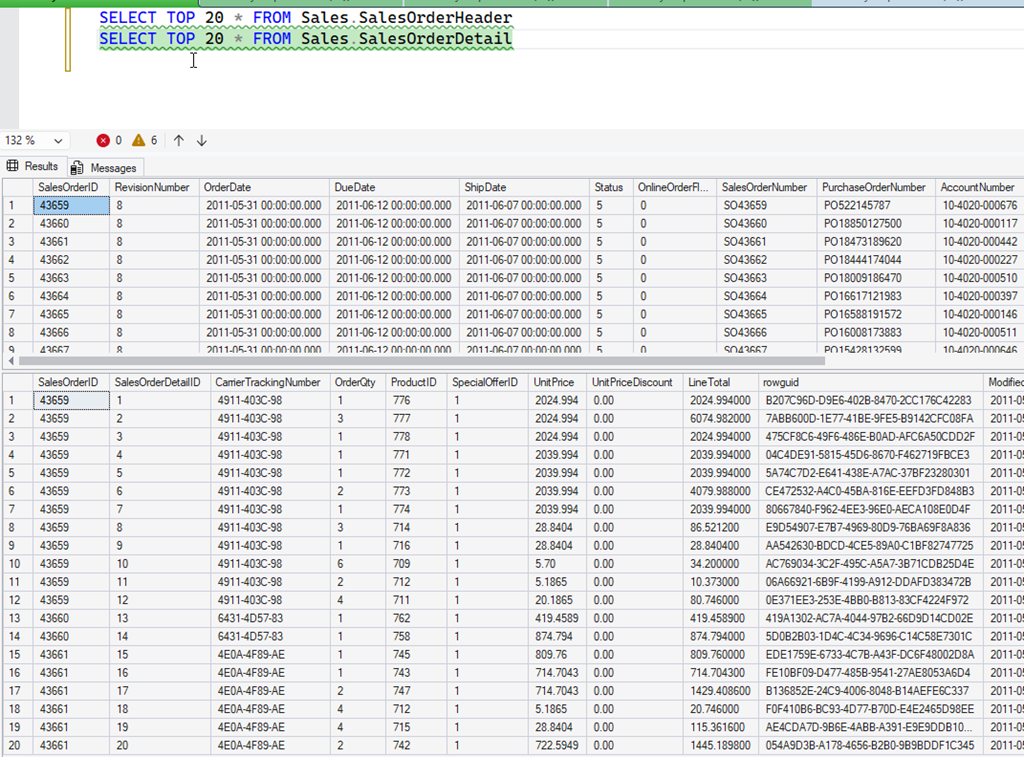
Who are the top 5 salespeople?
I put this into SQL Prompt AI: who are the top 5 salespeople with ranking for the first week of june 2011. Give me the salespersonid, the rank and sales total
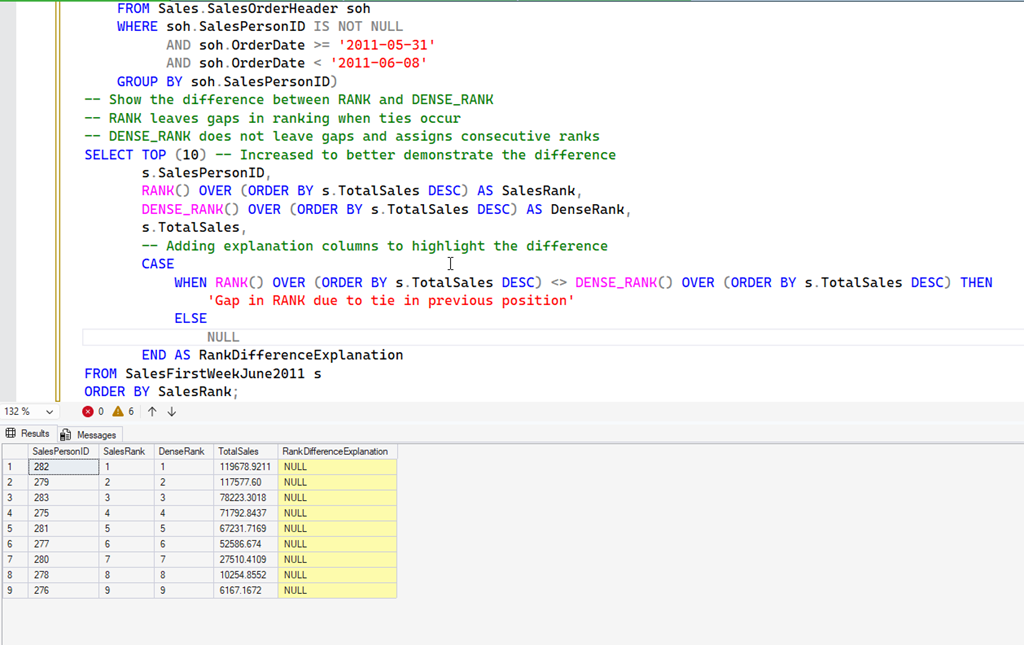
I got this code, though with 2011-06-01 as the first date, which didn’t work as there were no orders that week. I adjusted this back to May 31. You can see this uses RANK() as the aggregate.
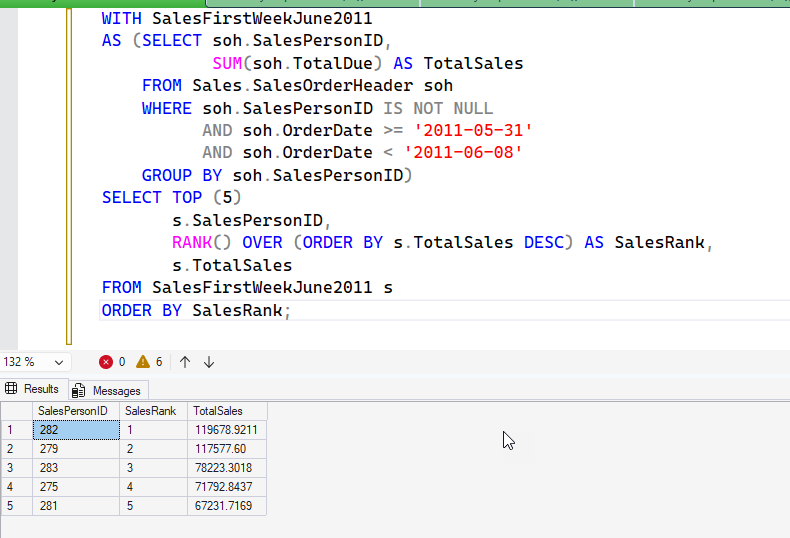
I then asked about DENSE_RANK, because I heard about it and might want to use it.
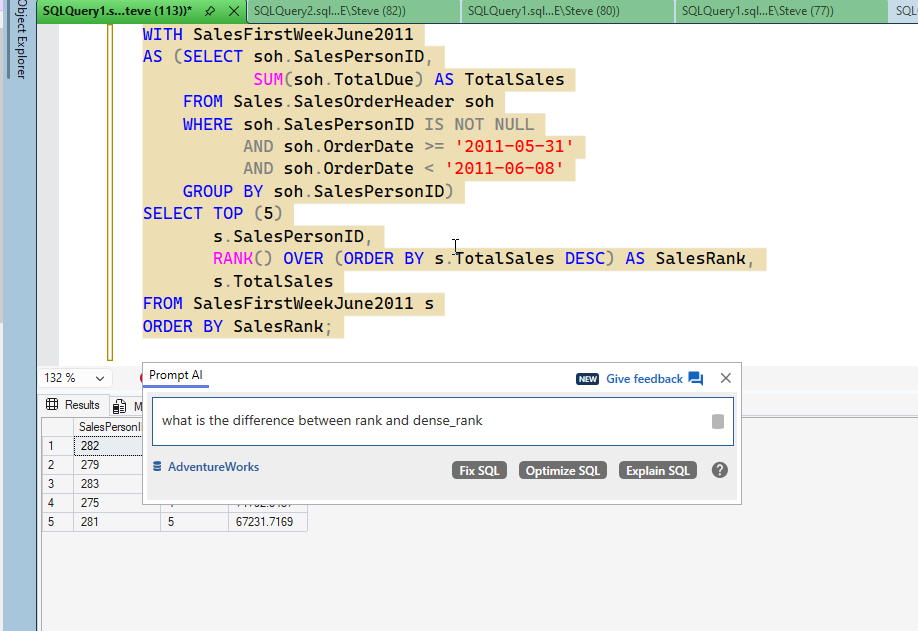
Prompt adjusted the query to add DENSE_RANK, but I then clicked the “add explanation” next prompt prompt (is that a thing now?)
I now see an explanation, though in this example, this doesn’t help.
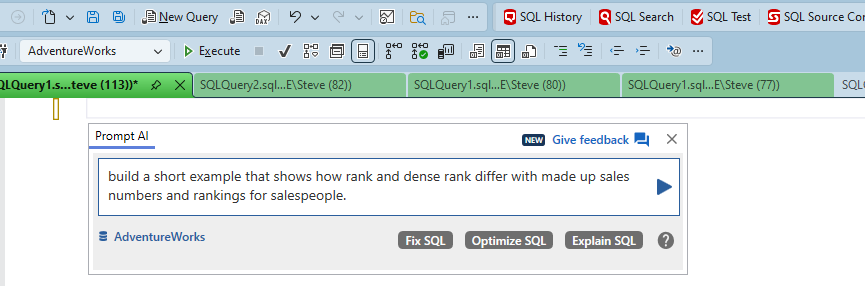
I then asked Prompt to help me understand.
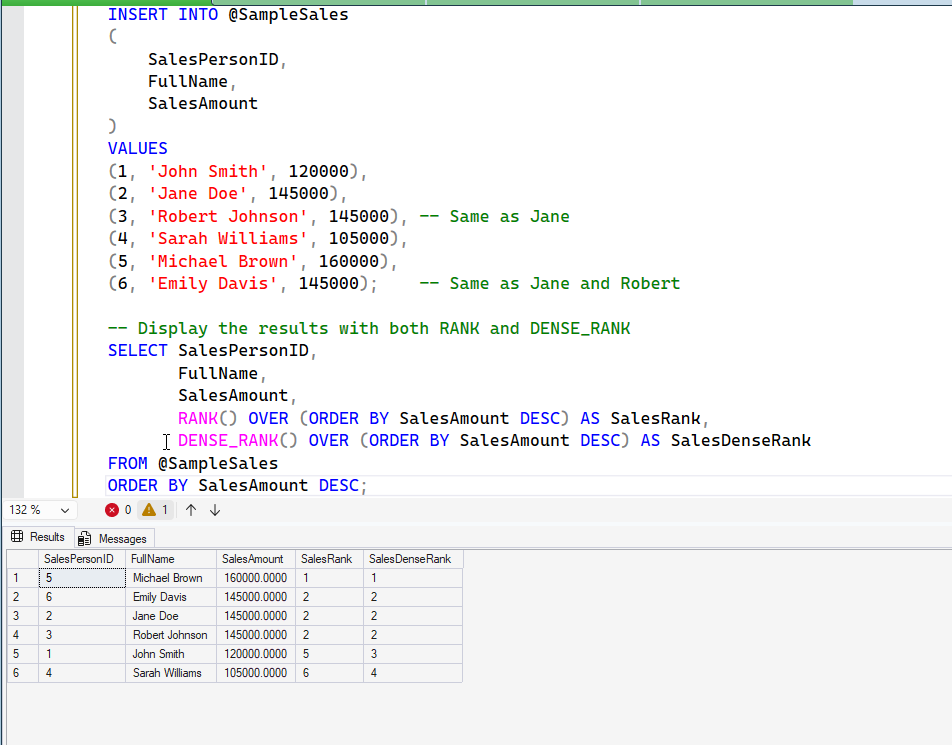
I got back this code. You can see in the results, that both show me the ties for 2nd with people that have the same sales totals. However, with RANK, we jump to 5, since there are 3 people tied at 2 (presumbly taking 2,3,4th place). The dense ranking goes from the ties at 2 to 3.
I asked for an explanation:
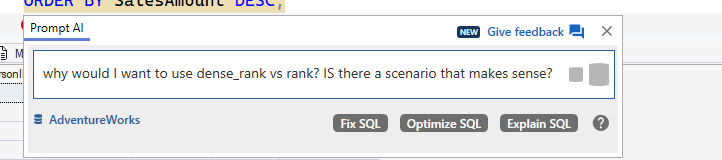
I got this. This is the text from SQL Prompt AI (in italics):
# RANK vs DENSE_RANK: When to Use Each
The key difference between RANK and DENSE_RANK is how they handle ties:
## RANK
– Assigns the same rank to ties
– Skips the next rank(s) after ties
– Creates “gaps” in the ranking sequence
– Example: 1, 2, 2, 4, 5 (note the missing 3)
## DENSE_RANK
– Also assigns the same rank to ties
– Does NOT skip ranks after ties
– Creates a “dense” or consecutive ranking without gaps
– Example: 1, 2, 2, 3, 4 (no gaps)
## When to use DENSE_RANK:
1. **Consecutive Ranking Systems**: When you need a continuous sequence without gaps, such as in competitions where tied participants should receive the same position, but the next participant should be ranked immediately after.
2. **Top N Analysis**: When identifying items in the “top 10” or similar groups, DENSE_RANK ensures you get exactly 10 distinct ranks regardless of ties.
3. **Percentile Calculations**: When calculating percentiles or quartiles where a continuous ranking is needed.
4. **Educational Grading**: When multiple students with the same score should receive the same rank, but the next student should be ranked immediately after.
## When to use RANK:
1. **Traditional Competition Standings**: Olympic medals and many sports competitions use this approach – if two athletes tie for first place, the next finisher gets bronze (3rd place, not 2nd).
2. **Statistical Analysis**: When you need to preserve the mathematical properties of ranks where the sum of all ranks should equal the sum of consecutive integers.
3. **Scenario Where “Skipped” Positions Matter**: When it’s important to account for how many entities are ahead of each entity.
Your example query perfectly demonstrates this difference:
– Employees with $145,000 all get rank 2 with DENSE_RANK
– With RANK, they get position 2, but the next rank is 5 (skipping 3 and 4) because there are three employees sharing rank 2
Each function has its appropriate use cases depending on whether you want a continuous ranking sequence or one that accounts for the number of entities at each rank level.
What I Learned Here
I knew most of this, but in terms of trying to understand better where/why to use each, the explanation made sense. I hadn’t thought about the Educational Grading for DENSE_RANK, but that makes sense. I knew the others, and often that the TOP N needs the correct number of rankings.
For RANK, we use the competition ranking with volleyball, so I see that all the time, but I don’t do a lot of statistical analysis where this has come up, but it’s good to keep it in mind.
To me, I often go back to the client, or think about both of these when I rank things. I will do what Prompt AI did and put both in a query, see the differences and then decide (or let someone else decide) how to present the ranking data.
SQL New Blogger
When I started to explain this, I first opened the DOC pages and was going to use those to write this and thought, this is a good place to test AI models and see. I took a different tact and incorporated some AI into my work, because that’s where the world is going. Like it or not.
This went faster with AI, and less cognitive load from me. I wrote this post, but I used AI to help set things up, generate code, and get me there quicker. You could do the same thing and use a blog to showcase that you’re learning how AI is a tool you can use.
SQL Prompt can help you learn more about your code, in addition to all the cool time saving features. Give it a try today.
FWIW, I asked CoPilot the same query and got an answer (0 people), without code. When I asked for code, I did get it, but not quite what I wanted.
 Voice of the DBA
