Tag: T-SQL

  • T-SQL Tricks – Trigger Your Memory

    I was scanning Twitter the other day and saw a note from someone that they had written a query using an obscure T-SQL command and were glad it had worked. I exchanged a note with the person and they mentioned that they had to look up the command and syntax periodically when they had to write a similar query.

    I mentioned templates.

    If  you haven’t used these, you should, and I wrote a basic post about how to access them and one on customizing these for yourself. These templates are like Snippets in SQL Prompt (Which are way more useful to me), and they are a tool every DBA should use.

    Here’s one way I think they’re really helpful:

    Suppose I need to write a PIVOT query. I rarely do this, and it’s not too hard, but I write this query:

    select
        *
      from
        ( select
              runner
            , miles
            , mins
            from
              results
        ) as rawdata pivot ( avg(mins) for [miles] in ( [3], [5], [10] ) ) as pivotresults
    ;
    GO

    That’s easy enough, but it’s specific for my tables. However when I glance at it, I can see that there’s an aggregate columns, and I know the PIVOT requires that I list the values that are to be used in the columns.

    What if I change the query? I can do this:

    select
        *
      from
        ( select
              runner
            , <pivotcol, varchar, miles>
            , <aggcol, varchar, mins>
            from
              results
        ) as rawdata pivot ( avg(<aggcol, varchar, mins>) for [<pivotcol, varchar, miles>] in ( [3], [5], [10] ) ) as pivotresults
    ;
    GO

    Now if I make this a template:

    templates7

    I can drag this into a new query window. When I see it, I can CTRL+Shift+M and get this:

    templates8

    Now I change a few values and I have a pivot.

    templates10

    Of course, I need to actually enter the values I want, but this gets my PIVOTs done quickly without the need to decode BOL or swing by SQLServerCentral. Once I do that, I have a query I can use.

    templates11

    I’d encourage you to use templates. They’re very, very handy for quick sections of code that you use often, or want to remember in the future.
  • Converting Dates

    I ran across a post recently where someone had dates stored as characters (never good), but also in this format: CYYMMDD. I’d never seen that, and thought it was strange. The person was asking for a way to convert this to YYYY-MM-DD, which I think it fairly easy.

    Let’s set up some data:

    CREATE TABLE RandomDates
    (
        myid INT
        , mydate VARCHAR(7)
    );
    GO
    INSERT dbo.RandomDates
            ( myid
            , mydate
            )
        VALUES
            ( 1, '0600102' )
           , ( 2, '1121004' )
           , ( 3, '0920415' )
           , ( 4, '1040611' )
            ;
    GO

    The format for the data is 7 characters denoted as century, year, month, day. The century is encoded, with the single value representing:

    • 0 = 1900
    • 1 = 2000

    That’s pretty straightforward and it means that we have two dates in the 1900s and 2 in the 2000s. The dates are:

    • January 2, 1960
    • April 15, 1992
    • June 11, 2004
    • October 4, 2012

    Querying these dates and converting them is straightforward, but there are a couple ways to do this. If we are just looking to convert these to characters, I saw this solution from ZZartin.

     SELECT CONVERT(DATETIME, CASE 
                                WHEN LEFT(mydate, 1) = '1' 
                                    THEN '20' 
                                    ELSE '19' 
                                END 
                                + RIGHT(rd.mydate, 6)
                    , 112)
      FROM dbo.RandomDates AS rd;

    That’s fairly straightforward, and overall I like it. It uses simple functions and puts things together.

    I had another idea, mostly because I initially favored keeping the items separate as parts of the date in case I needed them. I thought about DATEFROMPARTS, which is a SQL Server 2012+ function. My thought was to calculate each of the parts and send them into the function like this:

    SELECT DATEFROMPARTS(
                        CASE WHEN LEFT(mydate, 1) = '0'
                            THEN 1900
                            ELSE 2000
                            END + SUBSTRING( rd.mydate, 2, 2)
                        , SUBSTRING( rd.mydate, 4, 2)
                        , SUBSTRING( rd.mydate, 6, 2)
                        )
     FROM dbo.RandomDates AS rd
     ;

    My idea has more function calls, and I’d think it would take longer to build, but I’m not sure. Let’s test.

    I’ll use Data Generator to insert a few million rows into this table. Then let’s run both pieces of code.

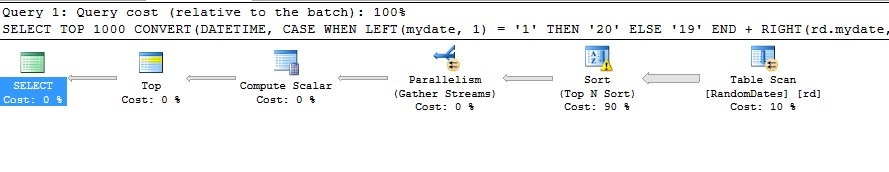
    The first code, from ZZartin, required about 19,000 logical reads and this execution plan when I ran it a few times. The CPU execution was in the 40k ms, and about 9 sec of real time.

    dates1

    The second code, mine, had about 30,000 logical reads, with only 8k CPU ms, but about 40sec of real time. The execution plan:

    dates2

    That’s interesting, and it matches what I’d expect. The first code is much simpler, intuitively, and it’s easy to read. With the format of the date essentially in order, it doesn’t make sense to try and "assemble" the date from parts. It’s easier to convert the first character to two (with the CASE) and then just cast this as a date.

  • T-SQL Tricks – Customizing SSMS Templates with Parameters

    I wrote briefly about templates in Management Studio (SSMS), and showed the default templates that come with SQL Server. I now want to customize some of the templates in a way that makes sense for me.

    If I grab a script I use often, like this one, I can make it generic.

    SELECT
            username
        ,   topic
        ,   COUNT(replies)
        FROM
            users u
            INNER JOIN posts p
            ON u.userid = p.userid
        WHERE
            u.email = 'bob@bob.com'
        GROUP BY
            username
        ,   topic;

    I run this often to check things, but I rarely need Bob’s information. Instead, I’ll often get different users, and sometimes I need dates. I can add these changes:

    SELECT
            username
        ,   topic
        ,   COUNT(replies)
        FROM
            users u
            INNER JOIN posts p
            ON u.userid = p.userid
        WHERE
            u.email = '<email, varchar, bob@bob.com>'
        AND startdate > <startdate, datetime, dateadd(m, -1, getdate())> 
        AND enddate <lessthan, char <> <enddate, datetime, getdate()>
        GROUP BY
            username
        ,   topic;

    I’ve changed some of my variable items to parameters. I do this by taking an item that I want to make variable, like “bob@bob.com” and changing it to “<email, varchar, bob@bob.com>”.

    The format for a template is:

    • name
    • type
    • default

    all of which are placed inside angled brackets and separated by commas. Now when I click CTRL+Shift+M, I get this:

    templates16

    I can click OK for the defaults to be placed in the script, or I can enter new ones. Either way, I save time and effort with saved queries, but saved as templates, not queries I need to edit constantly.

    UPDATE: Someone pointed out that the less than, the <, was . I got this from Stack Overflow, which had a good solution. I made the < a parameter as well.

  • Real World T-SQL Tricks

    I’ve been playing more with T-SQL this year, doing some testing and development in various places. I’ve been trying to improve my skills, and keeping up with the advancements the language has made in the last few versions. Like many of you, if I haven’t had the need for a particular feature, or the chance to implement it, I haven’t done much with it.

    I think that’s the case with many people, who may not catch all the changes in T-SQL with new versions, especially if you upgrade after a year or two and don’t often do more than refactor the existing code you have in production. In the spirit of improving skills, and also learning more about how others work in this profession, I want to ask you:

    Have you used any of these T-SQL items in production code?

    • APPLY
    • THROW
    • LAG/LEAD
    • a tally table
    • symmetric or asymmetric keys
    • TRY..CONVERT
    • CONCAT/FORMAT
    • IIF
    • SEQUENCE

    Some of these have been around for a long time, some are new in SQL Server 2012, but they are all improvements beyond the core T-SQL language that I see so many people posting and asking questions about.

    Let us know this week if you’ve used any of these constructs, and if you can, how they solve a problem that you struggled with in the past, or maybe how these new features have improved performance or sped up code development.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.0MB) podcast or subscribe to the feed at iTunes and LibSyn.