Tag: T-SQL

  • Default Framing–Window Functions

    I’ve been playing with the window functions in T-SQL a bit, and I find them very interesting. They certainly solve some problems very well, in a way that’s much easier than has been available in T-SQL.

    However there are some things you need to understand. One of these things is the framing of the window, and the data processed. A quick example will show some of this.

    Imagine that I create a table and insert some data:

    CREATE TABLE HomeRuns
    ( hrid INT IDENTITY(1,1)
    , player VARCHAR(200)
    , team VARCHAR(200)
    , hrdate DATE
    , HRcount TINYINT
    CONSTRAINT hr_IDX PRIMARY KEY (hrid)
    );
    GO

    We add a few row, which I’ll keep short.

    INSERT HomeRuns (player, team, hrdate, HRcount)
     VALUES ('Troy', 'COL', '4/7/2013', 1)
          , ('Troy', 'COL', '4/18/2013', 1)
          , ('Troy', 'COL', '4/22/2013', 1)
          , ('Derek', 'NYY', '5/7/2013', 1)
          , ('Derek', 'NYY', '6/24/2013', 1)
          , ('Nelson', 'BAL', '3/31/2013', 1)
          , ('Nelson', 'BAL', '4/2/2013', 1)
          , ('Nelson', 'BAL', '4/20/2013', 1)
          , ('Lonnie', 'CLE', '5/9/2013', 3)
    ;
    GO

    This is a small set of data. Let’s imagine that I want to count the total home runs by team in each month. If I try to do this with windowing, I’ll get something like this:

    select 
      team
      , datename( mm, hrdate)
      , HR.hrdate
      , sum(HR.HRcount) over (partition by month(HR.hrdate), team)
     from dbo.HomeRuns HR

    When I run that, I see all the rows returned, which isn’t what we expect from aggregates. However it’s also not any kind or running total or examination of the data in a row by row processing that many window functions perform.

    That’s not completely accurate, but it’s a feeling many people get when starting with these structures. However the results highlight something. Let’s look at them:
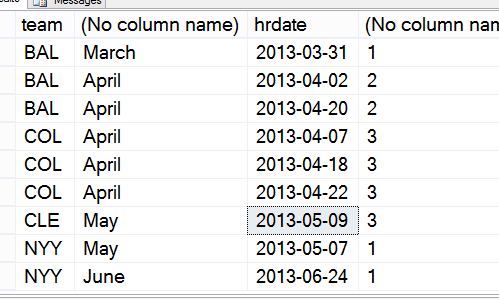
    window_1

    We can see that for April, for Baltimore, we see 2 rows, with a total of 2 for each row. There was one home run hit on each day, and the total is 2, but both rows are processed as one window.

    Why?

    That’s because the framing, the section of the partition that’s examined by the window aggregate, is the “”RANGE” of the partition by default. The entire partition, so all rows in front of, and behind, the current row, are used for the results.

    This is a simple example, but it does show that you need to be aware of the default, which I don’t love. I wish the default were ROWS, and I’ll talk about that another time.

  • Intermediate T-SQL: Window Functions

    This is the third hour of a three hour set of presentations on intermediate T-SQL techniques and features.

    This presentation covers the window functions that are available in SQL Server. Some of these functions were introduced in SQL Server 2005 and some in SQL Server 2015. We start with a brief introduction to what a window is, how a partition works, and then look at ordering and framing of rows. Then we cover the following in demonstrations:

    ROW_NUMBER()

    RANK(), DENSE_RANK(), and NTILE()

    The OVER clause and windowing in SQL Server 2012

    Using PARTITION BY and ORDER BY in the OVER clause

    Default framing with RANGE and how ROWS are different

    PERCENTILE() functions

    This covers a lot of information in an hour, but I try to use small data sets to explain what is happening with the window functions and how they can improve the performance, as well as simplify the code, for a number of common queries.

    Slides: TSQL_Windowing.pptx

    Code: TSQL_Windowing_code.zip

  • Intermediate T-SQL: PIVOT, UNPIVOT, and APPLY

    This is the second of a series of talks I put together on intermediate T-SQL topics that many database developers might not understand. In this talk, we cover the other join-type operators that exist in the FROM clause, outside of the INNER, OUTER, FULL, and CROSS join clauses. We break this hour into three main areas, covering:

    • PIVOT and crosstabs
    • UNPIVOT
    • APPLY

    Most of the time is spent on the APPLY operator, which is arguably the most useful of the three. I show how APPLY is like an inner or outer join, and also how it can be used to improve performance of a scalar function, how it can be used to run some queries that are difficult with INNER JOINs, and how we can use this to easily find query plans and code in performance tuning.

    The PIVOT operator is compared to a crosstab, which is similar. We see how to write a query using either method. We also show the UNPIVOT operator.

    Slides: TSQL_IntermediateQueries.pptx

    Code: TSQLPIVOT_Unpivot_Apply.zip

  • Intermediate T-SQL: Writing Cleaner Code

    This session is an intermediate T-SQL session that helps users learn how to write better T-SQL code by covering a few items that many database developers might not be aware of. In an hour, users will lean how to:

    • write and use CTEs to simplify complex queries.
    • learn basic error handling, including recommendations for SQL Server 2012 and beyond with THROW.
    • use templates to store common code elements
    • tricks in SSMS to speed up code development
    • understand what a tally table is and how to use it to perform a few common tasks.

    This is the beginning of a three hour series I have on intermediate T-SQL code.

    Slides: TSQL_WritingCleanerCode.pptx

    Code: TSQL_CleanerCode.zip