Tag: T-SQL

  • Which product was purchased the most? T-SQL

    Suppose you had a list of product sales and were curious about which one was sold the most? It’s a simple query, and one that I used to ask people in interviews so I thought it would make a nice easy blog post.

    If I look at AdventureWorks2008, I have a Sales.SalesOrderDetail table that roughly looks like this:

    sales1

    There’s a productID in there, and if I want to see how products were sold, I can do this:

    SELECT 
       COUNT(DISTINCT ProductID)
     FROM Sales.SalesOrderDetail
     

    However that doesn’t help me with the actual products. I could instead do this:

    SELECT 
        productid
      , COUNT(*)
     FROM Sales.SalesOrderDetail
     GROUP BY ProductID
     

    That isn’t ordered, so I can easily add an ORDER BY to see the products sold and the counts.

    SELECT 
        productid
      , COUNT(*)
     FROM Sales.SalesOrderDetail
     GROUP BY ProductID
     ORDER BY COUNT(*) DESC

    That gives me a list, but I really want to just get the top seller. That’s easy as well.

    SELECT TOP 1
        productid
      , COUNT(*)
     FROM Sales.SalesOrderDetail
     GROUP BY ProductID
     ORDER BY COUNT(*) DESC

    Which returns:

    productid  
    ———– ———–

    870         4688

    However I don’t know which product this is, so I’d really want a join here.

    SELECT TOP 1
        p.Name
      , COUNT(*) 
     FROM Sales.SalesOrderDetail sod
       INNER JOIN Production.Product p
         ON sod.ProductID = p.ProductID
     GROUP BY p.Name
     ORDER BY COUNT(*) DESC


    Which lets me know that a water bottle was the most sold item.

    Name                                              
    ————————————————– ———–

    Water Bottle – 30 oz.                              4688

    However I wasn’t asked for the count of sales, just the most sold item. I don’t really need the count in order for the query to work. I can do this:

    SELECT TOP 1
        p.Name
     FROM Sales.SalesOrderDetail sod
       INNER JOIN Production.Product p
         ON sod.ProductID = p.ProductID
     GROUP BY p.Name
     ORDER BY COUNT(*) DESC
     

    Which just returns

    Name

    ————————————————–

    Water Bottle – 30 oz.

    What if there were two items that had the same sales? I’d really want to include WITH TIES to be complete.

    SELECT TOP 1 WITH TIES
        p.Name
     FROM Sales.SalesOrderDetail sod
       INNER JOIN Production.Product p
         ON sod.ProductID = p.ProductID
     GROUP BY p.Name
     ORDER BY COUNT(*) DESC
    

    It’s simple, easy, but it’s a query that trips a lot of people up in the intervening steps. I’d prefer you quickly returned the last query to me (wrote it, told me, etc.), but if you had to work through it, I’d hope that you talked about the steps I did as you went through deriving the query so I can understand how you think, and how you improve. If you have me the first query, I’d probably hint around with you about the items forgotten.

    You could use a CTE, subquery, or other methods, which are more complex, less efficient, and unnecessary, but could be valid answers. It’s best to stick with something simple, but go with your first instinct and work through it. If you get stuck, backtrack and try something else, explaining along the way. Or tell the interviewer you don’t know if you don’t.

    It’s best to be honest, and to show that you can learn, correct yourself, or even admit you don’t know.
  • Checking Your Service Account with T-SQL

    Somehow this slipped by me, but there were some new DMVs added in SQL Server 2008 R2 SP1. I suspect my test machines were mostly SQL Server 2008 or SQL Server 2012, and I hadn’t been paying attention to the changes in SP1.

    You can now use T-SQL to check for services information, as well as registry information, without using extended stored procedures or any hacks of xp_cmdshell. There are two new DMVs:

    These were not present in the RTM of SQL Server 2008 R2, but after installing SP1, they appear. The KB article for SQL Server 2008 R2 SP1 includes a note that new trace templates for Profiler are included, but I did not see a note about these two DMVs.

    So much for not adding features in Service Packs.

    In any case, you can query the sys.dm_server_services for service account information. You will get the service name, the startup type, the account, and more.

    If you aren’t a Windows administrator on your SQL Server boxes, you should still be able to get information regarding the services from this DMV as long as you have VIEW SERVER STATE permission.

  • Where’s My Backup? SQL Server Backup Issues

    You can cause yourself problems if you don’t know where your backups are stored, and how they are being made. It also helps to understand the defaults of how your backups are created in files.

    Here’s a short story to illustrate an issue you might encounter as a beginner if you are not clear about the backup process.

    Let’s say you’re a junior DBA, and you create a database.

    CREATE DATABASE BackupRestoreTest
    go
    CREATE TABLE MyTable( mychar CHAR(1), mytest VARCHAR(200))
    go

    You know that backups are important, so you setup a basic command like the first one below, schedule it in SQL Agent, and you have backups being performed. In between the backups, work is being done. Probably more than one INSERT, but this is just to show something is happening in the database.

    -- schedule backup
    BACKUP DATABASE BackupRestoreTest
      TO DISK = 'MyBackup.bak'
    GO
    
    -- do work
    insert dbo.mytable SELECT 'a', 'b'
    GO
    
    -- backup database
    BACKUP DATABASE BackupRestoreTest 
      TO DISK = 'MyBackup.bak'
    GO
    

    This continues on, day after day. Work gets done, you run your nightly backups.

    -- do work
    insert dbo.mytable SELECT 'c', 'd'
    GO
    
    -- nightly backup
    BACKUP DATABASE BackupRestoreTest 
      TO DISK = 'MyBackup.bak'
    GO
    
    -- do work
    insert dbo.mytable SELECT 'e', 'f'
    -- mistake is made
    DELETE dbo.mytable
    -- more work
    insert dbo.mytable SELECT 'g', 'h'
    GO
    
    -- nightly backup
    BACKUP DATABASE BackupRestoreTest 
      TO DISK = 'MyBackup.bak'
    GO

    Then one day, someone runs this and calls you:

    -- mistake noticed
    SELECT MyChar FROM dbo.mytable
    GO

    Only the row with “g” is returned from this. The user asks about all the other data. Where are the rows with “a”, “c”, and “e”?

    You decide to restore.

    -- restore, use good habits. NORECOVERY always.
    USE master
    GO
    RESTORE DATABASE BackupRestoreTest 
      FROM DISK = 'MyBackup.bak'
      WITH NORECOVERY
      , REPLACE
    GO
    
    -- bring online
    RESTORE DATABASE BackupRestoreTest
      WITH recovery
    go
    

    You check the data and you get this:

    -- check data
    USE BackupRestoreTest
    GO
    SELECT MyChar FROM dbo.mytable
    GO

    The results?

    MyChar

    ———–


    Nothing. No data. Why not? If you look, you’re last insert (row “g”) occurs after the delete and before the backup. Why isn’t it in the restore?

    The answer comes from a few sources. If we read the BACKUP page in Books Online (BOL), we find that if we don’t include the INIT option for a disk file, the backup is appended to the current file. The phrase in BOL is:

    “If the physical device exists and the INIT option is not specified in the BACKUP statement, the backup is appended to the device. ”

    If we look at the INIT argument, we see that the default is NOINIT

    “NOINTI – Indicates that the backup set is appended to the specified media set, preserving existing backup sets. If a media password is defined for the media set, the password must be supplied. NOINIT is the default.”

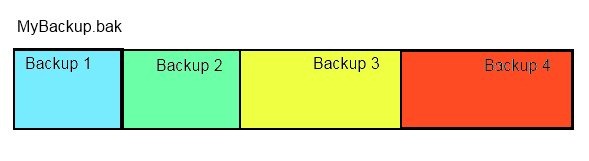
    This means that we’ve essentially done this:

    backup3

    Our one file, MyBackup.bak, contains 4 full backup files. This file is larger than it needs to be, and also it poses a risk. If I lose this file, I don’t lose one backup, but I lose 4.

    Can I check this? Sure. Run this:

    RESTORE HEADERONLY FROM DISK = 'MyBackup.bak'
    

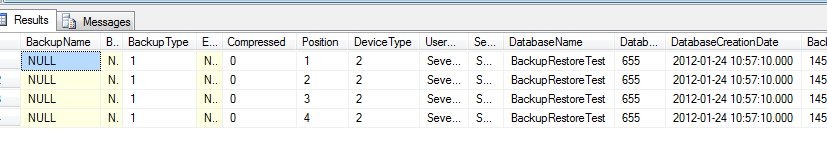
    I get these results:

    backup4

    You can see there are four files, with a “position” that differs.

    Now, on the restore, why didn’t I get one row back in my table? The insert for row “g” occurred before the last full backup (backup 4), so why wasn’t it restored?

    If we read the RESTORE Arguments page in BOL, we find out that for the FILE arguement

    “When not specified, the default is 1, except for RESTORE HEADERONLY in which case all backup sets in the media set are processed. For more information, see "Specifying a Backup Set," later in this topic.”

    The backup that was restored was our first backup, made before we did any work (inserted any rows).

    What do we do? Well, we have a few choices. The last (fourth) backup would only get us the one row. If we restore the third backup, we lose the data in rows “e” and “g”. That’s usually what we want to do, so let’s restore that backup:

    -- restore file 3
    USE master
    GO
    RESTORE DATABASE BackupRestoreTest 
      FROM DISK = 'MyBackup.bak'
      WITH NORECOVERY
      , FILE = 3
      , REPLACE
    GO
    -- bring online
    RESTORE DATABASE BackupRestoreTest 
      WITH recovery
    go
    -- test data
    USE BackupRestoreTest
    go
    SELECT TOP 10 
       mychar, mytest
     FROM mytable

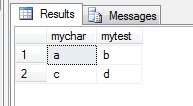
    That gives me two rows back. I’ve lost some work, but I potentially have recovered more in many situations.

    backup5

    Ideally I could recover more if I had transaction log backups, but that’s another blog.

    The main thing to be aware of here is to use the INIT command, write your backups to separate files, preferably with the timestamp in the file name. If you’re not sure how to do it, a maintenance plan can do it, or there’s a great script on SQLServerCentral that can help.

    Lastly, the default recovery models mean you need log backups. Make sure you know how to manage your transaction logs.

  • Computed Columns and Divide by Zero

    Edit: This was a poor example of using the divide by zero handling. I was trying to alter something I’d done in the past and this didn’t work well. I will rewrite this soon with a better example.

    I have a few posts on computer columns, the basics of computed columns, using CASE in a computed column, and UDFs in computed columns, but there was another use that someone pointed out to me recently: catching divide by zero errors.

    Suppose you have a column that is determining a percentage of profit for some sales. I’ll create a table and include some values:

    CREATE TABLE MySales
    ( salesid int , Product VARCHAR(20) , Cost numeric(10,4) , Price numeric(10,4) , profit AS (price - cost)/ cost
    ) GO INSERT MySales SELECT 1, 'Bike', 150.45, 180.99
    INSERT MySales SELECT 1, 'Shoes', 23.55, 45.99
    INSERT MySales SELECT 1, 'Soda', 0.25, .99

    If I look at the values in the table, I get back these items:

    /*------------------------
    SELECT Product
    , Cost
    , Profit
     FROM MySales
    ------------------------*/
    Product              Cost                                    Profit
    -------------------- --------------------------------------- ---------------------------------------
    Bike                 150.4500                                0.202991026919242
    Shoes                23.5500                                 0.952866242038216
    Soda                 0.2500                                  2.960000000000000

    Things work great, and everything seems to be fine. However, what if we get some free products that we can sell, say something we made out of scraps, or were given to us as a gift with essentially no cost?

    INSERT MySales SELECT 1, 'Keychain', 0, .75

    It works. However if I select data:

    SELECT Product
    , Cost
    , Profit
     FROM MySales

    I get this:

    Product              Cost                                    Profit
    -------------------- --------------------------------------- ---------------------------------------
    Bike                 150.4500                                0.202991026919242
    Shoes                23.5500                                 0.952866242038216
    Soda                 0.2500                                  2.960000000000000
    Msg 8134, Level 16, State 1, Line 2
    Divide by zero error encountered.

    The computation occurs on query, and it doesn’t work well.

    However we can fix this with a function in our computed column. There are a couple choices here. I can use ISNULL and a CASE to build a formula, I could use COALESCE, or I could use NULLIF.

    NULLIF returns null if two values are equal. If a NULL is acceptable in my table, I could use that. I could end up with:

    CREATE TABLE MySales
    ( salesid int , Product VARCHAR(20) , Cost numeric(10,4) , Price numeric(10,4) , profit AS (price - cost) / NULLIF(cost ,0) ) GO INSERT MySales SELECT 1, 'Bike', 150.45, 180.99
    INSERT MySales SELECT 1, 'Shoes', 23.55, 45.99
    INSERT MySales SELECT 1, 'Soda', 0.25, .99
    INSERT MySales SELECT 1, 'Keychain', 0, .75
    GO SELECT Product
    , Profit
     FROM MySales

    and get back:

    Product              Profit

    ——————– —————————————

    Bike                 0.202991026919242

    Shoes                0.952866242038216

    Soda                 2.960000000000000

    Keychain             NULL

    NULL is a good marker here, but your application needs to handle this and let the user know there is an issue.

    You could use COALESCE, which returns the first non-null value. I could see any of these as being a valid formula:

    , profit AS (price - cost) / COALESCE(cost ,0) 

    which uses “0” profit margin as a marker, or even something like:

    , profit AS (price - cost) / COALESCE(cost , 999)

    which uses 999. Lots of times we’ve used a large, nonsense number as a marker that lets someone know there is a strange value here.

    If we converted this to a varchar, it’s possible that we could even use words in there, but I wouldn’t recommend that as downstream uses of this column might involve other calculations.

    That’s a short look at how a computed column can solve an easy, common issue: divide by zero.

    Credit to Atif Shehzad, whose article I found while researching this.