Author: way0utwest

  • The Value of Your Personal Data

    Years ago I read Being Digital by Nicholas Negroponte of MIT. In the book, he relates a story about crossing the border from the US into Canada and a Border Patrol agent asking the value of his laptop. He said millions, not because of the hardware, but because of the data. I thought that was interesting, and I somewhat agree. The data I have on my machines, or really now, in cloud services, is more valuable than the hardware. The hardware is barely worth anything to me, including the time it takes to reinstall my applications, because I really treat my laptop as a piece of cattle. I could drop it, render it completely unusable and I’d be back up, running, and productive with new hardware in less than 4 hours.

    Then I saw this article on ransoming data for iCloud users, where the request is for US$75,000. This is for Apple itself and not individuals, but what if it were for each user? What would I pay to avoid losing all the data on my mobile device?

    It certainly wouldn’t be $75,000 despite the fact I think some of the data I have is precious. I love the pictures and video of my family most of all, but if I lost some of them, maybe all of the digital storage, would I just pay a ransom? Probably not. What about all the code in a VCS for my company? Would we pay a ransom for that? Likely we would, though perhaps not. We might think about reconstructing the code, especially if we were a small company.

    Ultimately I think there isn’t a lot of money to be made with individuals’ data. Too many of us older folks remember when we did lose physical objects and they were just gone. The idea of losing things is painful, but not inconceivable. For younger people, it seems that much of the data we produce and consume is transient and isn’t necessarily that valuable to us. My kids love Snapchat for the ability to create and lose memories. I dislike it for the same reason.

    Much of the data we personally have can be backed up, and possibly recreated if it isn’t. Many of our digital records have the characteristic that while we may have a copy, often some business or organization has another copy. Requesting new data is easy, and while it might cost some time and money, it may be preferable to the idea of paying a ransom, and potentially having to continue to pay again in the future with some virus still on our systems.

    I don’t quite know what to think about ransomware and how this might evolve. I suspect that this will always be a problem in some way, just as hardware failures will likely plague us forever. The only solution I have is to create backups regularly that contain versions, and can be restored to separate, clean devices. I’ve gotten away from my own personal offline backups, mostly because of data size, but I do continue to try and keep at least 2 or 3 backups going to different locations and with different services because my data is at least that important.

    Steve Jones
  • Does Speed Compromise Quality?

    One of the parts of DevOps that is often hyped is the speed and frequency of releases. Starting with Flickr and their 10 deployments a day, to Etsy deploying 50 times a day, we’ve seen companies showcasing their deployment frequency. Amazon has reported they deploy code every 11.7 seconds on average. That seems crazy, but with so many applications and lots of developers, not to mention each change being smaller, perhaps it’s not completely crazy. With the forum upgrade here at SQLServerCentral, we had two developers (with occasional other sets of eyes reviewing code changes), and while we were bug fixing, we deployed multiple times per day.

    Is that a good idea? Does a rapid set of changes mean that quality is lower and more bugs are released? It certainly can. In fact, if you’re a development shop that struggles with releases and code quality, producing software faster is not going to help you. In fact, if management pressures you to adopt DevOps, and deliver code faster without culture change, without implementing automated testing, including for your database code, and using automated scripts, tools, or something to deploy software, then you are going to get more bugs out faster. You’ll still get to change direction quicker if you find you’re building the wrong software, but you’ll still end up becoming more inefficient because of bugs (And technical debt).

    There’s a fantastic video (long) about refactoring code in two minutes. A bit of an oxymoron since the presentation is nearly two hours long, but the video is from a real project. However, their approach is that good unit testing allows them to refactor code, to change things, without introducing bugs. That’s a big part of the #DevOps philosophy. I always note in my DevOps presentations that if you can’t implement unit testing, meaning you won’t bother, then you don’t get much benefit from CI, CD, or any DevOps ideas. Tests protect you from yourself (and others).

    In many of the DevOps reports, companies that release faster report fewer bugs and less downtime. Since Amazon has increased their speed, they have 75% fewer outages across the last decade, 90% fewer time down, and many, many fewer deployments causing issues. Turbotax made over 100 production changes during tax season and increased their conversion rates. The State of DevOps reports bear this out (2016 here). Thousands of responses show that speed doesn’t cause more bugs.

    Because they work differently.

    If your management won’t let you change the way you work, if you don’t implement automated unit tests (and other types of tests), if you don’t take advantage of version control, if you don’t ensure every change is scripted, then you won’t work differently, and speed will bring bugs.

    You can do better. Your company can do better. Will they?

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 4.2MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • T-SQL Tuesday #89–Changing Times

    tsqltuesdayThis month the invitation is from Koen Verbeeck and it has to do with the cloud changes coming to the data world, especially SQL Server. That’s an interesting topic, not necessarily technical, but it is an interesting one to think about.

    I’m going to be a little short because life is busy, but I think this is an interesting item to keep an eye on for many people. Not necessarily at your current position, but what if you need to move on?

    If you’re interested, I host all the T-SQL Tuesday topics at tsqltuesday.com.

    The Cloud is Changing Things

    I sat in a talk at SQL Bits from Conor Cunningham of Microsoft. He’s one of the principal architects of SQL Server and Azure SQL. In the talk he talked about some interesting ideas in how SQL Server engineering has changed in the last decade. Victoria Holt wrote a short piece on some of the things Conor talked about.

    There are a couple interesting things that the cloud is enabling. First, Microsoft runs their cloud without any Ops team, really having developers be responsible for things in production. This is 1.7mm databases, without any DBAs. Why? They gather lots of data, so they learn when things are broken, unstable, or problematic. They do this with the 600TB of telemetry they gather every day.

    Of course, you and I won’t have that much information, but the cloud does enable Microsoft to think about how to make SQL Server more stable, and also how to add automation capabilities into the product. We haven’t seen much of this change in current versions, but the Query Store is the start of one thing, and Adaptive Query Processing (coming in v.Next) is another. I wouldn’t be surprised to see more, and that means our jobs as DBAs will change.

    I think there will be less, check, configure, verify, maybe even some less tuning work for DBAs. There will always be developer needs, especially with more complex reporting, visualizations, and just understanding large data sets. There will also constantly be the need to write better SQL as the optimizer can only do so much with bad queries.

    The cloud interests me and excites me. There are issues, concerns, and challenges. However, I also find working with Azure through Powershell, being able to access different services from various places, keeping some data there (non PII) and avoiding the need to manage infrastructure to be key.

    I don’t know if it will happen, but I would hope at some point that the Azure cloud, the AWS cloud, the Google cloud would license their service, or even allow others to resell and manage portions to encourage competition and give us some choice in who we might choose to deal with. If so, they I could see more and more companies just considering moves to the cloud for more data, especially when there could be different levels of service and protection for different needs.

    The cloud is changing things, even if you aren’t in the cloud. That can be opportunity if you take advantage of it.

  • Upgrading VSTS Redgate Build Tasks

    I’ve been putting it off, but in prepping for SQL Bits demos, I decided this was a good time to just upgrade my original build and release tasks on VSTS from v1 to v2 for the Redgate tasks.

    The first step was to go into the marketplace and find the new tasks. If you browse the marketplace (click the shopping bag icon in the upper right of VSTS) and search for “redgate”, you’ll see the tasks.

    2017-03-31 16_42_13-Search results - redgate _ Visual Studio Team Services , Visual Studio Marketpla

    I picked the two on the right, the build and release tasks v2. The v1 tasks aren’t in the marketplace, but if you’ve added them to your account, they’re still there and they work in your build and release pipelines.

    Once I installed them, they appear in my list of extensions.

    2017-03-31 16_44_56-Manage extensions - Visual Studio Team Services

    Now I can edit my pipelines.

    I’ve got a release pipeline that looks like this. Note that these are the v1 plugins, because there’s no v2 on the name.

    2017-04-01 11_25_17-SimpleTalk Release Pipeline 1 - Visual Studio Team Services 

    My plan is to upgrade these to the new extensions, however, there are lots of settings. If you look to the right for any of the tasks, for example the Create task, there are lots of boxes to fill in.

    2017-04-01 11_26_34-SimpleTalk Release Pipeline 1 - Visual Studio Team Services

    This is expected as if I were doing this manually, I’d expect to have  along set of commands or switches to programs or parameters, that I’d need to pass in to a process. After all, the mechanics of implementing CI or CD aren’t hard, but they do have lots of moving parts.

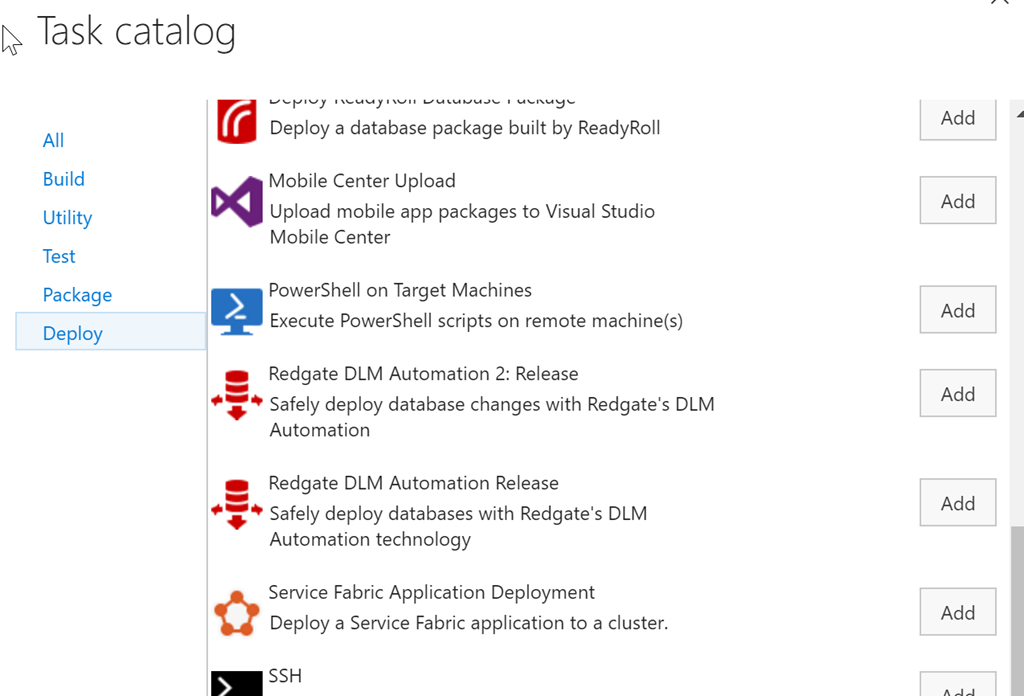
    My first step in making this easier is to add a new task. To do that, I click on the “Add tasks” button above. This will default me to the set of tasks for me particular function, in this case, release (deploy). I scroll down to see the v2 tasks.

    2017-04-01 11_29_23-SimpleTalk Release Pipeline 1 - Visual Studio Team Services

    Here I see the v1 and v2 tasks because they’re both listed in my set of tasks because I’ve installed both into my account. In this case, I’ll pick the “2” version of this task.

    Once this is added, I need to configure the task. In my case, the easiest way to do this was to click on the v1, copy the contents of a text box, and then click on the v2 task and paste the values in there.

    Once I had done this, I have both tasks listed. For this particular pipeline, I had actually added a new Agent Phase, separating my tasks out. There wasn’t any great benefit to this, though I can then just delete one whole phase and all the tasks in it (once things are working).

    2017-04-01 11_33_41-ST Pipeline_Mobile - Visual Studio Team Services

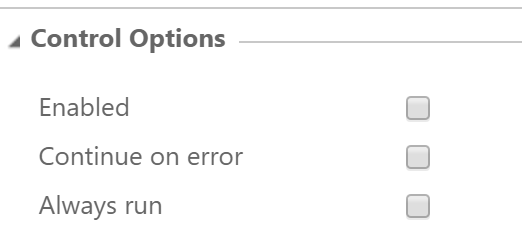
    After copying all the settings from one to the other, and checking that v2 was configured the same, I was ready to test. I first went to each of the v1 tasks and unchecked the “enabled” box. This means those tasks won’t run, but they’re still in the definition.

    2017-04-01 11_33_52-ST Pipeline_Mobile - Visual Studio Team Services

    After that, I created a release and deployed it. Not every deployment worked. My first ones did, but when I tried to hit the production environment (the far right), it failed early on. This list is from newest to oldest, so I had a few things to work out here.

    2017-04-01 11_36_20-ST Pipeline_Mobile - Visual Studio Team Services

    As you can see, this isn’t necessarily a simple, easy process. In my case, the v2 tasks have some additional path items, and I had to sort those, I also had firewall issues to production as I was traveling between the tests, which meant forgetting, and then needing, to reset the firewall rules.

    However, it’s all good now.

    2017-04-01 11_38_21-ST Pipeline_Mobile - Visual Studio Team Services

    I would encourage you to upgrade your DLM v1 tasks to v2. There are a few bug fixes, some of the deprecated cmdlets are removed, and these work slightly better. I know have pathing options to separate my environments on the agent and can easily see the code being run.

    I’ll talk about my test procedure for upgrading in the next post, because I think trying to do too much at once is how I’ve gotten into trouble and created stress for myself in the past. Now I have a better idea.