I got a notification from a question I’d posted at SQL Server Central: Getting the Average. A user had posted their repro didn’t work, with no real comment. As a SQLNewBlogger FYI, that type of post shows poor communication and a lack of communication. I see that a lot and it’s a challenge in the modern world.
Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.
A Quick Setup
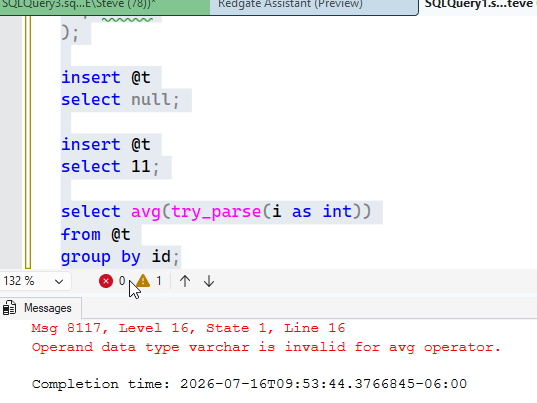
This was what the user posted:
declare @t table
(
    id int identity
  , i int
);

insert @t
select null;

insert @t
select 11;

select avg(try_parse(i as int))
from @t
group by id;
This does return an error, as you can see below.
Why?
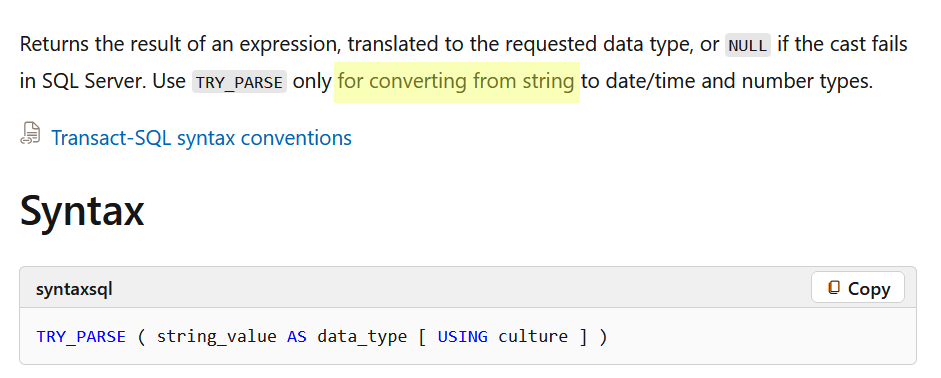
Well, the TRY_PARSE() docs give part of an explanation. I highlighted this in Yellow, but the relevant text says “only for converting strings”.
Shouldn’t an int convert to a string? No, the precedence rules have int higher than char types. We convert lower to higher, not higher to lower.
SQLNewBlogger
I noticed something, thought for a second why this wouldn’t work, and then checked the docs. I decided to write this up and it was a 5-10 minute post for me. Easy to do and showcasing knowledge.
It helps me remember, might teach someone something, and gives an interviewer something to ask me. Add to your blog with short posts like this (or drop on LinkedIn).
T-SQL Tuesday #200 was in July, hosted by Brent Ozar, and it was a great topic: How do you recognize a bad query? In the age of AI, when lots of people will get queries written by others (people or AIs), how can you easily and quickly review code? Review is already a challenge in the software world, and I am sure it’s going to be even more challenging as people let machines author more database code.
Lots of you might hope that an AI agent will write better code than your average developer, but I don’t know if I’d count on that. There is a ton of poor query examples on the Internet and that’s where AI models are trained. You need some sort of feedback loop, good testing, and strong guidance if you want better query code. I think it’s as likely as not that AIs will produce poor queries just like humans.
Just faster.
How can you recognize poor queries? How do you judge if there are issues? Brent’s roundup shows what a number of people think, and there are some good “quick checks” to use to evaluate your code. The things that people wrote in their blog posts are the types of things that I’d want added to Flyway’s Code Analysis rules to catch problems before they get deployed to production. After all, anything that gets to production usually lives for 10 years (my rule of thumb).
Getting feedback early in the development process is critical. We know from over 50 years of software development that finding problems early is less expansive than finding them later. Whether we use humans or AI agents, we don’t want unnecessary time spent on simple bad code things that we know cause issues. Shift-left is still a challenge, even in the automated era of DevOps and guided AI agent skills. We need reliable, repeatable ways to analyze code and limit the downstream effects of poor quality.
Especially these days, where the volume of changes is overwhelming CI/CD systems. This was a problem already in organizations with too many teams in one codebase. It’s a growing problem in more organizations as users use AI and submit more changes.
Plus wasting time gets expensive. Human labor is slow and spending time on more tokens for rework gets expensive.
Don’t let bad queries flow through to CI/CD systems if you can avoid it. Learn to provide quick feedback early to whoever, or whatever, writes your SQL.
I have been experimenting with MCP servers in a few ways, and pressing on our Redgate Monitor team to add one to their system. They did, started adding tools, and are continuing to work. I’m excited.
Here’s a quick look at the MCP server for Redgate Monitor (preview in July 2026).
I’m not going to bore you with the setup and configuration. You do need to be on a 14.23 or later as the version. Your account rep can get you setup instructions, which are still be worked on and finalized. This is really a work in progress as of this writing (Jul 30) and I’ve found a few things that didn’t quite make sense, so be patient. This is editing the Monitor Webserver config file and enabling this.
Once that’s done, it’s a little tricky with an AI agent system. This is the high level, and I’ll do some more detailed notes about getting this in VSCode and Claude, where I work. The basic steps are:
Enable in Redgate Monitor
Create an MCP Access token
Add the MCP config to your Agent setup
It’s not quite as simple as it sounded to me, but it wasn’t that hard. It’s mostly working through some of the steps and ensuring you get your JSON correct.
Accessing the MCP Server
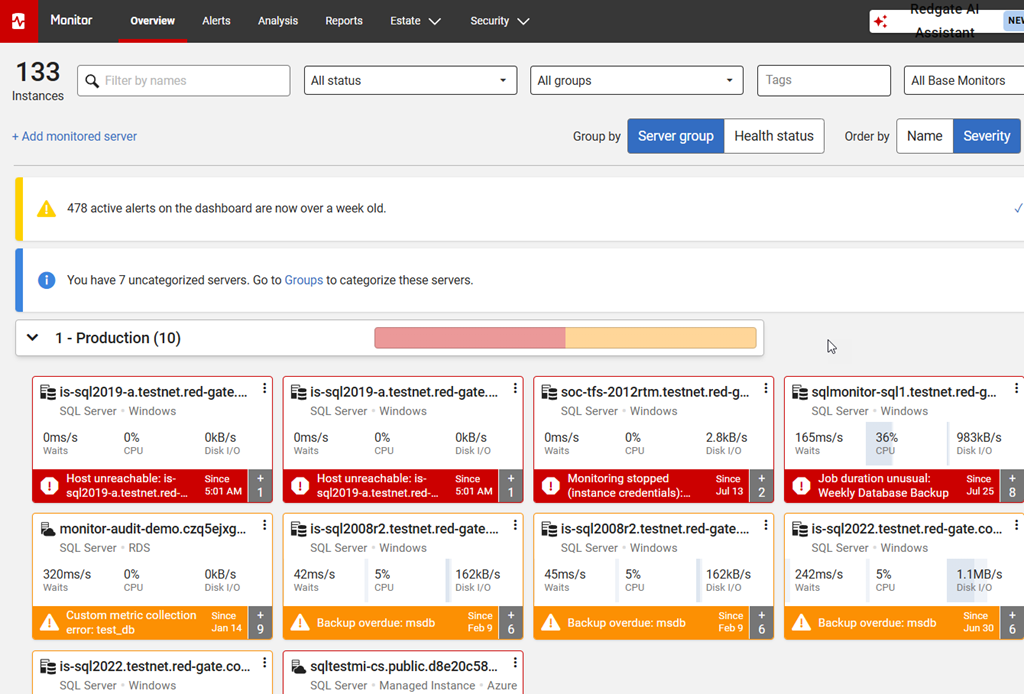
I connected with Claude for the demo in the Video Walkthrough below, but I’ll give you a quick look here. I set my token for the prod/staging/dev systems. When I look at the test instance of Redgate Monitor, I see this: lots of servers and alerts.
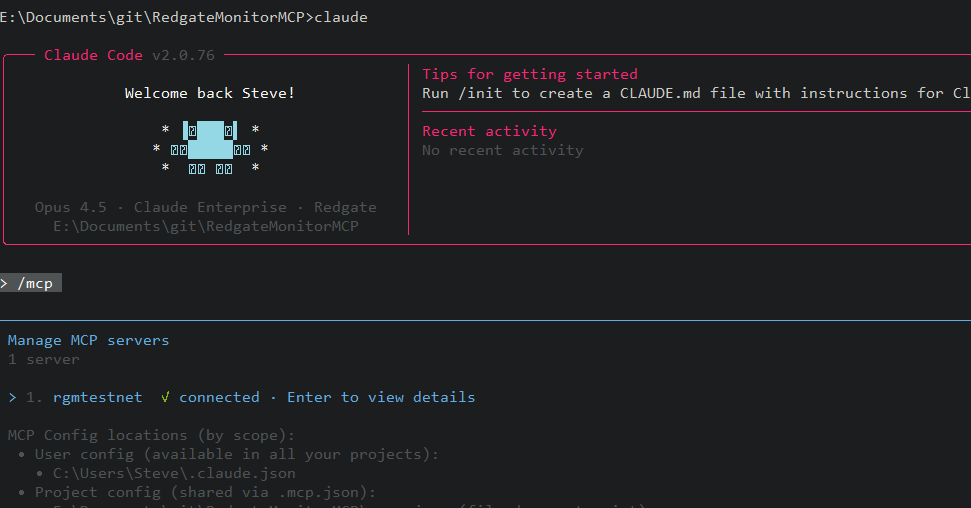
Once the MCP server is added, I start Claude and run a /mcp. I see my server get connected.
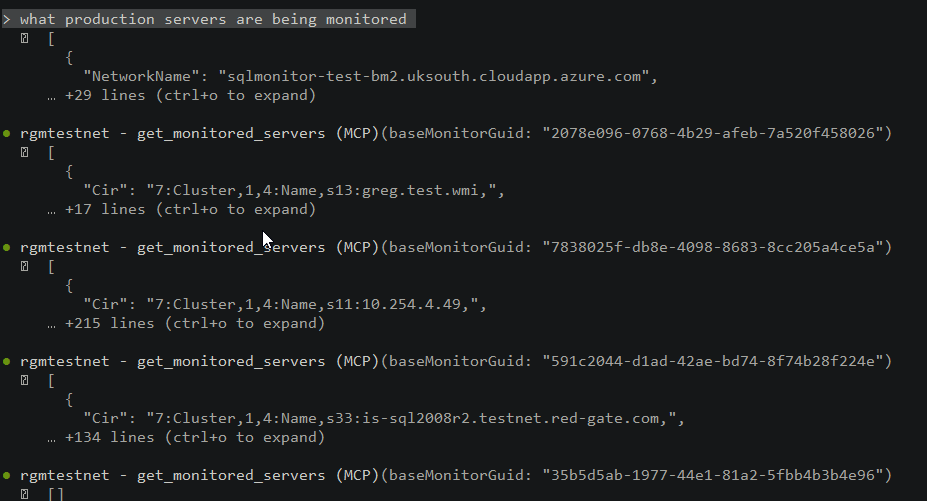
There are a number of tools, which have grown since I started testing. I don’t have a complete list and anything I put here will be out of date in a week, so I won’t bother. In any case, I’ll ask for the production servers. I can see the various base monitors being queried. This is slower than almost any customer, since we have more BMs than most people here. Most have 1-2 at most.
Note: I did get asked for permission a few times before the tools were accessed. Since all MCP stuff is read-only now, I just granted permission for all sessions.
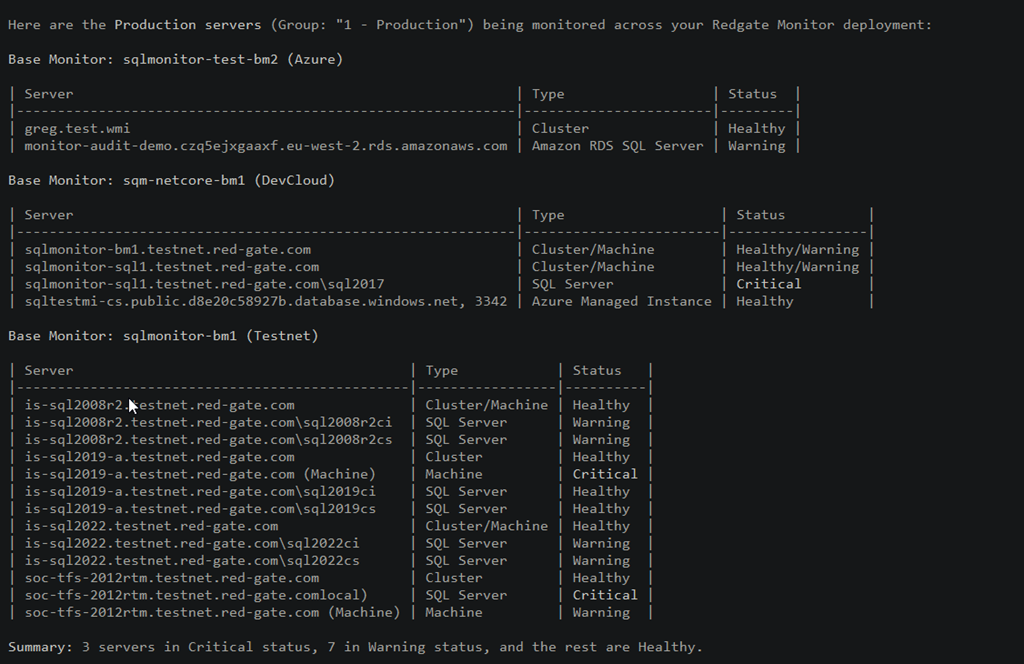
Here are the results. Note the summary at the bottom.
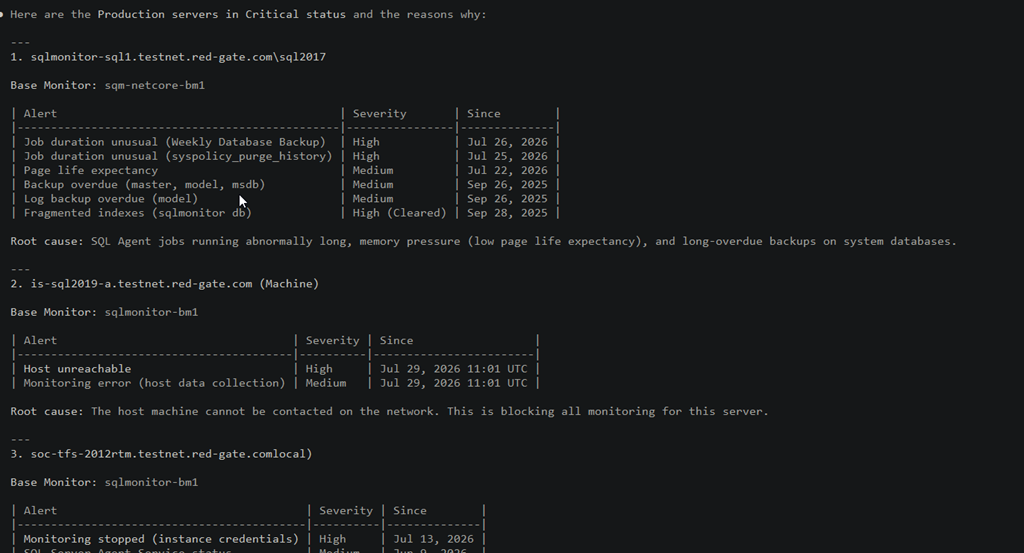
I next asked this: which servers are in critical status and why. The Claude LLM interprets this and starts querying the Redgate Monitor server, using the token for security, and the tools, which are really the API of things that can be run.
The results I got were what you see below. The LLM had to run a bunch of queries to get results and the read in those results and interpret them. In this case, there were a lot of different queries of tools to look for data. This probably took a minute or two, but it feels long while watching the screen.
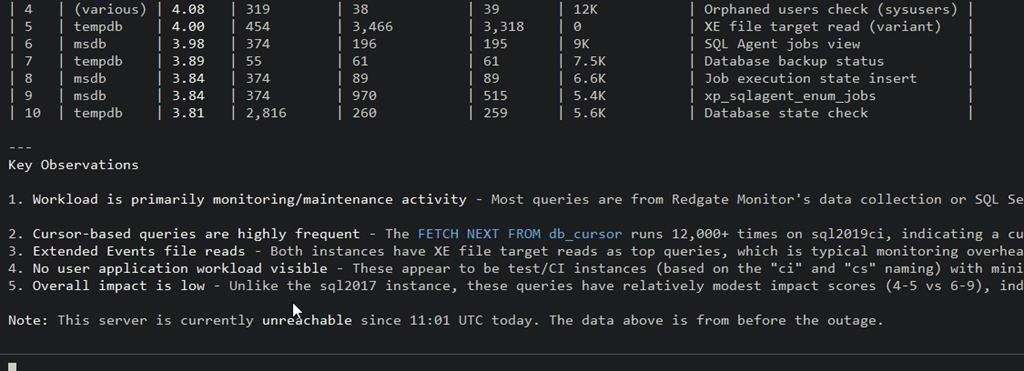
I next asked about queries on an instance. I don’t know these servers that well, but I know there are workloads on some to simulate what clients see. I decided to ask about one of the 2019 instances in production. In this case, I got asked for permission for a new tool (I hadn’t run the top queries tool) and then the agent went to work. You can see the tool usage and results. In this case, the system was down when I ran this, and it let me know this was from before the outage.
At the bottom, there are some observations, which can be useful. I’ve got cursors running, XEvents, etc. Helpful to look at this for a system I don’t spend a lot of time examining.
Ultimately the MCP server is a way for you to use tools you use already, but allow them to query the data in Redgate Monitor.
I’m excited to see where this can go, and how it can help customers interpret all the data collected by Redgate Monitor and more easily summarize it. This will be useful to some, though others of you might not like MCP access and instead stick with the internal AI tools.
It’s up to you, but we are giving you the choice to work as you wish.
Summary
The Redgate Monitor MCP server is in preview as of July 2026. I tried to give you a short sense of how you can use this to query Redgate Monitor and keep an eye on your systems. There are lots of ways to work, and I’ll try to give some guidance on specific things over time, but for now this gives you a sense of how MCP works.
I’ll do future posts that cover the config and help you get testing in your own environment.
Redgate Monitor continues to grow and advance and MCP capabilities are a great way to start using AI to help manage a large database estate, with your own AI resources.
Redgate Monitor is a world-class monitoring solution for your database estate. Download a trial today and see how it can help you manage your estate more efficiently.
When we look at the performance of software, we use Pnn notation to indicate the latency of an issue. A P95 problem is one that exceeds the time that 95% of the other queries take. In other words, this is the 5% slowest things happening, which can include database slowdowns that impact your application.
For many years in software development, we have tended to work on the P95 or P90 issues, the slowest items. This is primarily because those can make a big difference to the system’s performance. If I fix the slowest things, then the system feels faster. Certainly, I know lots of DBAs and developers will apply this logic to database queries. They focus on the slowest queries and tune them to improve the system. If most things are quicker, especially the things most users notice, then the system feels faster.
We’ve often limited our work on latent items because the time involved in working on other issues is hard. If you choose to work on items in the P70 range (30% slowest) or the P50 items, does that make sense? There are slower items, so doesn’t it make sense to focus on those P95 or P99 items when trying to increase the speed of the user experience? In software, I think this does make sense.
However, in the database world, we aren’t often thinking of one user’s experience. We’re thinking about the volume of requests from all clients. We might find there are queries that seem fast, say 400ms queries, but if these are running thousands of times a minute, we might see more benefit from clients if we reduce this to 200ms than if we speed up a 30s query to 2s. For the database world, we often think about the rate of items, not just their latency (or speed).
For database queries, how do we choose what to focus on if it’s not the slowest queries? we might not also want to tackle the most frequent queries either. My question might be: do we need to choose?
In the age of AI, especially if tokens aren’t too expensive, do we need to spend engineering time deciding? Would it make sense to let our AI coding agent evaluate and propose changes to all the queries? With a team of agents, we might have time to investigate the entire workload and try to speed everything up. This does mean we need a good system for guiding agents, separating out work, and ensuring that each agent isn’t trying to add an index for every query. That’s something humans have done, and agents likely will try if they don’t have to coordinate their work.
The effort of this work isn’t zero, and I’d bet there will be a significant amount of time to get this set up in some organizations, though I’d hope as people discover ways to organize agents for database work, with controls to scope their efforts and validation techniques, this becomes easier and easier. I’d like to think that at some point, DBAs will work in the same way software developers are hoping they work: thinking about problems, evaluating potential solutions, and managing AI helpers who type the actual code.

 Voice of the DBA
