Author: way0utwest

  • Getting the SQL Server MCP Server Running

    If you’ve wanted a SQL Server MCP server for your databases, it’s available. The SQL MCP Server is a part of the Data API Builder (DAB). DAB is a wrapper that allows you to run a service over your databases that exposes REST, GRAPHQL, and now, MCP, in a way that lets you control it.

    I’ve written a bit about this here and at SQL Server Central, and this post looks at adding MCP access to your DAB setup.

    This is part of a series on the Data API Builder.

    Adding the MCP Endpoint

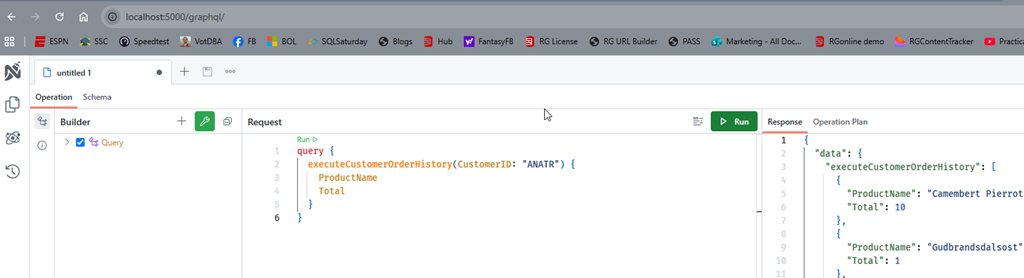
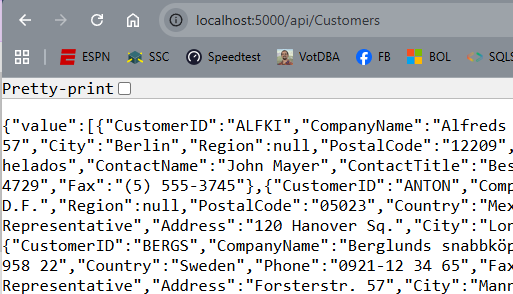
    I have a DAB setup already that runs well. I have a REST endpoint (here’s the REST view of Northwind.dbo.Customers).
    2026-07_0304

    And here is the GRAPHQL endpoint.

    2026-07_0306

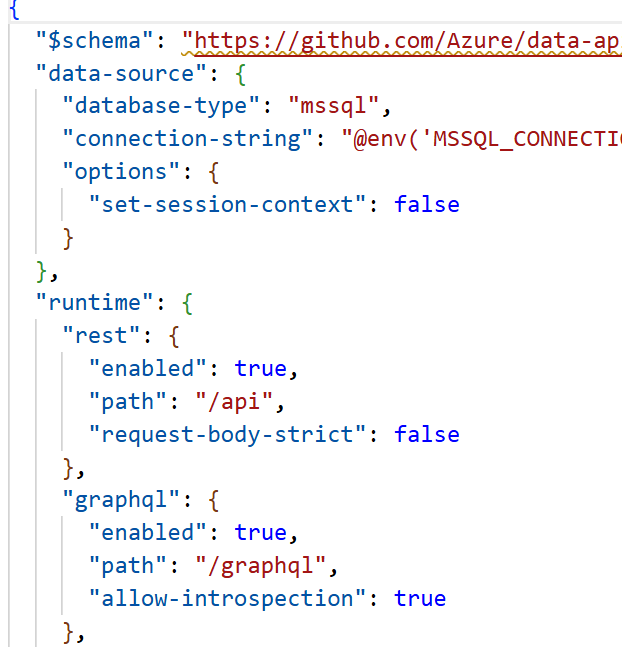
    If I look at my configuration file that drives the service, I see this:
    2026-07_0307

    What about MCP? It’s easy to add.

    The MCP Service

    The MCP capability was added in v1.7 of DAB, but the current version if over 2.0 (2.0.9 as of Jun 30, 2026). There have been bug fixes and capabilities, so I’d recommend upgrading.

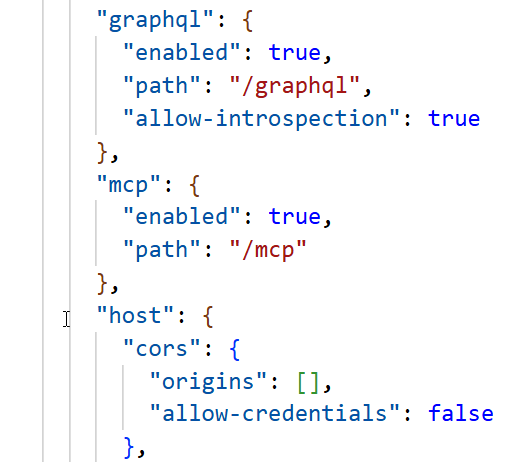
    Second, this is enabled by default for new DAB configs, but if you have an existing config, you need to add a JSON key/value in your file. This is the runtime configuration, but by default all the tools are available. Here is my new config file (which I regenerated from my old VCS items). You can see the new MCP section between the graphql and the host keys.
    2026-07_0308

    In the docs, you can add a dml-tools key and enable or disable individual tools. The DML tools available are:

    • describe_entities – Discovers available entities and operations
    • create_record – Inserts new rows
    • read_records – Queries tables and views
    • update_record – Modifies existing rows
    • delete_record – Removes rows
    • execute_entity – Runs stored procedures
    • aggregate_records – Performs aggregation queries (new in v2.0)

    Since this entry is in my configuration, I’ll start the DAB server and query it.

    Querying the MCP Server

    I need an agent to do this. The easiest one for me is the Copilot Agent in VS Code. I configured the MCP server (another post coming on this) and then sent a query. You can see the agent accessing the server and looking for the tools. Seven were found.
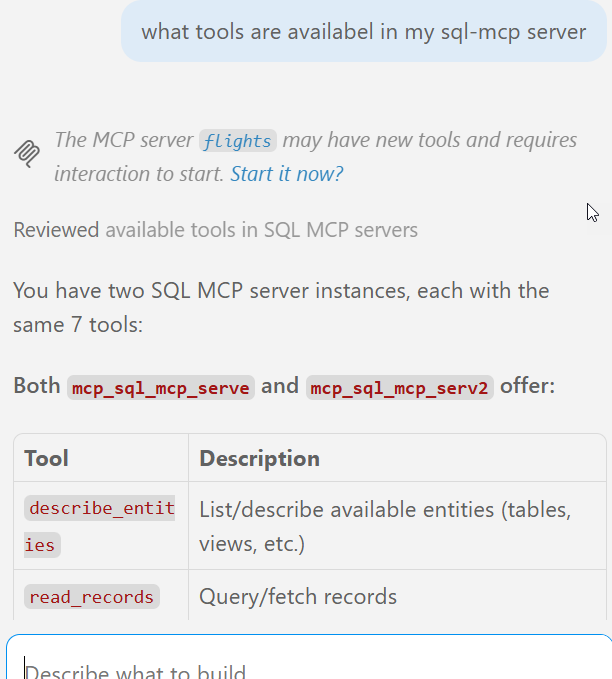
    2026-07_0309

    Here is the rest of the entry, with the descriptions of the tools.
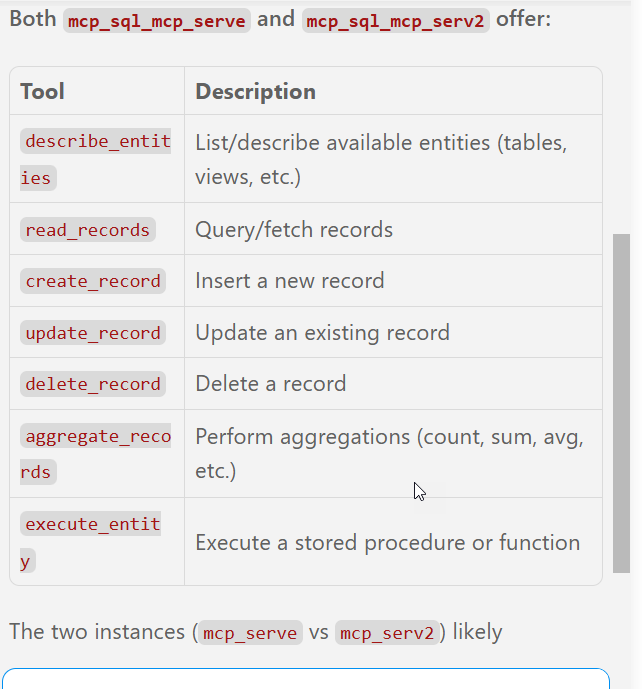
    2026-07_0310

    The power in the MCP server is I can ask my agent to use the tools to do work. I don’t need to be that specific. In the query below, I’ll just ask for data. In this case, the customers with the most orders:
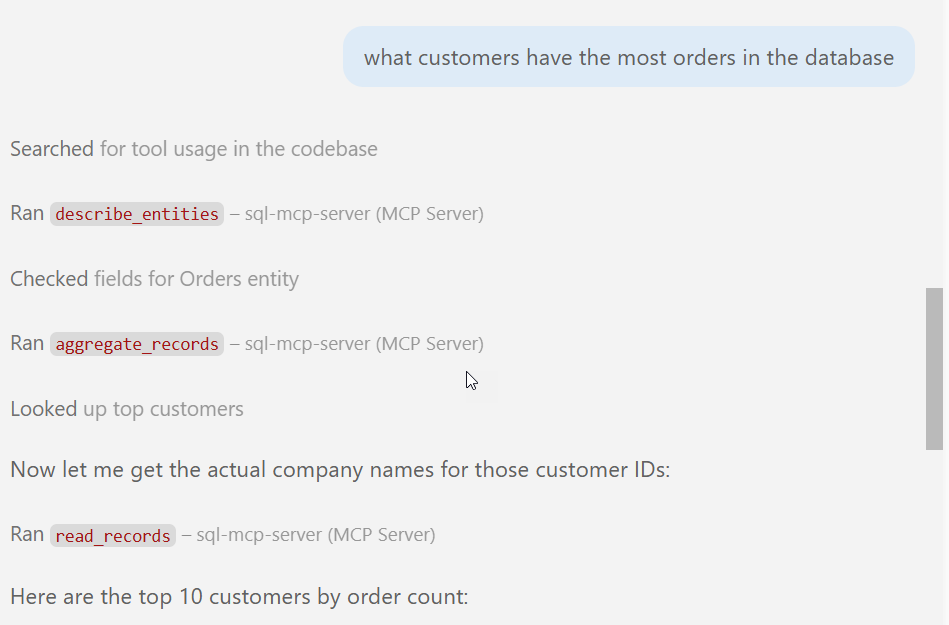
    2026-07_0311

    At each of the “ran” stages, the agent asked for permission. I granted it, allowing the agent to run code. It went through metadata in the db and then returned the data. Below the image above, I had the results returned. You can see that here.
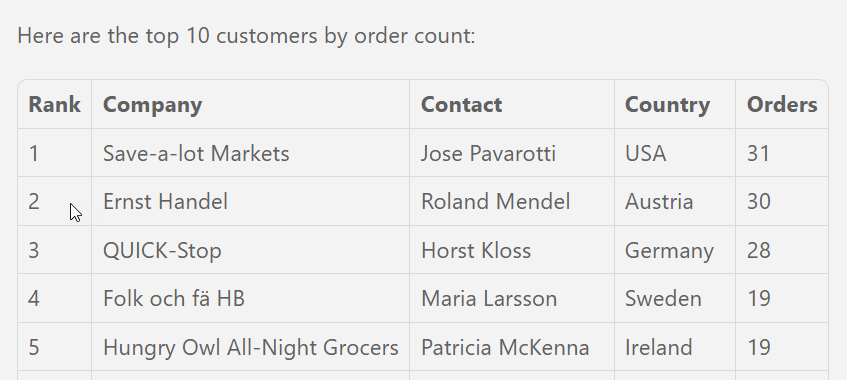
    2026-07_0312

    This matches what I get from SQL if I run a query. Below is the query I ran directly.
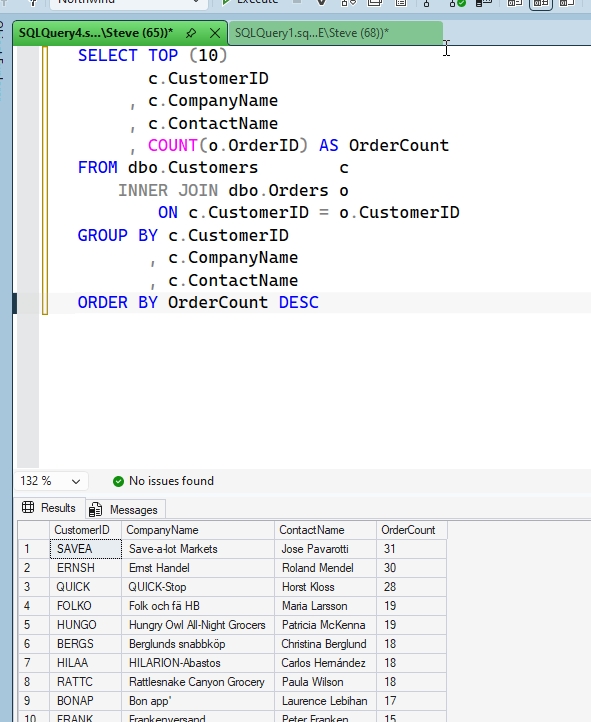
    2026-07_0313

    If I look at the DAB log, I see the mcp server being accessed.
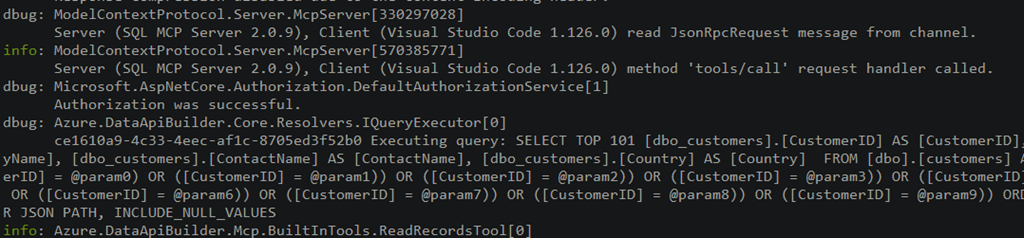
    2026-07_0314

    This is a very quick look at the MCP server working in SQL Server. It’s another great reason to use DAB. That already makes building CRUD applications easier, and now you get MCP access as well.

  • Another Model, More Data Loss

    This past week I saw an article on eWeek that the newest OpenAI GPT-5.6 (Sol) model has deleted local files and live data. Files I’m less worried about, but data concerns me. There are lots of file backups, and certainly version control should be enabled for any developer tasks on which an AI works. However, data is harder, since it can change quickly, especially in live environments.

    There are different reports, some of which seem like more human error issues than the model’s, but we should account for human error when we use models. In one report, a model had access to a live production database and cleared tables for integration tests. Database testing is hard, as I’ve learned over the years. Many developers don’t think about how testing works with live data and how it is different from mocks and stubs. It is different, and if you use a lot of testing frameworks on live databases, you run the risk of there being issues. You could have data loss, and almost certainly will have some level of downtime disruption.

    This is a great reason why adding AI coding to database tasks needs governance around what is allowed. It is easy to have success with AI-assisted work and forget that these models can make mistakes. And if you trust them with too much, like you might be tempted with an impressive but junior DBA, you might get burned. These automated tools can get hyper-focused on a certain task, and not consider the ramifications of their actions. The article notes an agent ran “rm -rf” on a dev machine. That’s similar to what happened with Toy Story 2, where a human made the mistake. Both that person and this GPT-5.6 model weren’t thinking widely enough about what tasks they were managing.

    The article notes that this model can be overly persistent and assume actions are permitted unless explicitly prohibited. Not unlike a lot of humans who assume if someone has given them rights, they can do the task. OpenAI noted in an internal case that a user approved the removal of three VMs. When the coding agent didn’t find these, it looked for other machines and chose three other VMs. Crazy, but I’ve seen humans do this in the past.

    I don’t think these models are getting closer to Artificial General Intelligence (AGI) or that they are anywhere close to sentience. However, as they become more capable and handle more complex predictive actions, they are also likely to do the same stupid things humans do by not considering all the possible consequences of their actions. After all, we have plenty of data where humans haven’t considered the effects of their actions, and that data is in the AI model training set.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.

  • Advice I Like: Responsibility

    The foundation of maturity: Just because it’s not your fault doesn’t mean it’s not your responsibility.” – from Excellent Advice for Living

    I’ve worked with a lot of people who are growing and learning into something new. This could be with my kids, kids I coach, or people at work. Often when we’re learning, or we attempt something in our jobs, we make mistakes. Sometimes those aren’t our fault, as some external factor might impact our effort.

    However.

    I’m still responsible for things. If someone doesn’t produce a good query and slows the system down, I still might be responsible if it’s the system I am managing. If a junior DBA doesn’t check somethings clients complaint to the lead DBA (me), I am likely still responsible.

    I find people often conflate these things together. You might be both at fault and responsible, but in my mind, you should feel responsibility more often than you look at fault (or blame). If someone on my team messes up, it’s often not my fault, but I still feel responsibility. After all, we’re a team. That’s what a team does.

    Don’t avoid responsibility. In fact, take on a bit more than others might want. Don’t be responsible for everything, but just a bit more than others would. It’s great advice that helps you stand out, and often, succeed.

    I’ve been posting New Words on Fridays from a book I was reading, however, a friend thought they were a little depressing. They should be as they are obscure sorrows. I like them because they make me think.

    To counter-balance those, I’m adding in thoughts on advice, mostly from Kevin Kelley’s book. You can read all these posts under the advice tag.

  • What is CPU Usage?

    I had a request from a customer recently who asked if we could give them a report of their database server instances and include CPU usage. This request was filtered through an account executive, so something was lost in translation, but I was confused and asked for clarification, as asking for CPU usage is kind of like asking how fast you were traveling in your car. There needs to be more context.

    If someone asked you for a report of CPU usage for a database, what would you expect? How would you report this? I’m sure the person asking might make a difference. A fellow DBA, your DBA manager, or maybe an executive could all view this differently. I want to know how things are performing, if there is a trend, or maybe if we are getting value for the hardware we’ve provisioned, depending on my role.

    If you were looking at your monitoring system, what would you look for? Redgate Monitor shows the last 24 hours of CPU with the last two hours in a focus window as the default, though you can easily change this. Perhaps you’d prefer this boiled down to min/max/average values over a time period? If there’s something else you’d consider, let me know. Maybe I can get it added.

    Certainly, the values you expect might depend on what you are trying to measure. Is there an acute performance issue? Then you might worry about the spot values or perhaps the last xx minutes of trending CPU values. If this is capacity planning, then peaks and average values can matter. If you are looking forward, you might even want longer trend lines and future extrapolation.

    Of course, the experienced DBA knows that other metrics need to be taken into account when looking at the CPU. 100% usage isn’t necessarily an issue if the workload isn’t creating unnecessary processes stacking up or too much latency in returning results. Perhaps the amount of memory used should be included to determine if there are CPU or RAM (or other) bottlenecks.

    There are a lot of factors that might go into how you examine the performance or efficiency of a database server, whether SQL Server or any other platform. A well-performing system has to balance lots of factors to meet the demands of a workload. A poor-performing system doesn’t do this well and often there are many more factors than how much of your CPU capacity is being used.

    The other thing this request showed me is how poorly many people communicate, and especially how much can be lost as a message moves from one person to another. This is an area where AI can succeed or fail as well. IF we communicate poorly with AI, we may waste time and money while receiving useless results. If we let AIs provide summaries to us, or from us, the model may choose to emphasize, highlight, reword, or hide things we think are important. After all, the model is predicting what should come next, not understanding the information.

    Communication is crucial and is becoming more important as we become more distributed and allow technology to sit between us.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.