Author: way0utwest

  • Classifying Data with SSMS 17.5

    I upgraded SSMS to 17.5 recently and found an interesting addition. This version has incorporated the ability to classify data. With the GDPR coming for many of us, this is a welcome addition.

    This is a quick look at this feature.

    Classify a Database

    If I select a database and right click it in SSMS, I get a few new items in the Tasks menu (as shown).

    2018-02-16 13_15_58-SQLQuery1.sql - Atlas.master (sa (51))_ - Microsoft SQL Server Management Studio

    I’ll select “Classify Data”, and I get a new tab opened. I see there are some recommendations and also a list of classifications of data.

    2018-02-16 13_16_28-Data Classification - NBA - Microsoft SQL Server Management Studio

    There’s a getting started link, which takes me to the SQL Server Security Blog. I suspect that’s an incorrect link. I think it should go here: SQL Data Discovery and Classification.

    Below this, I see a list of the recommendations. This has grabbed tables that appear to continue to contain some data that might be sensitive and require classification. One of the tenets of the GDPR  is that you know your data. You aren’t allowed to figure this out later, but rather you must proactively know what data you are collecting and processing.
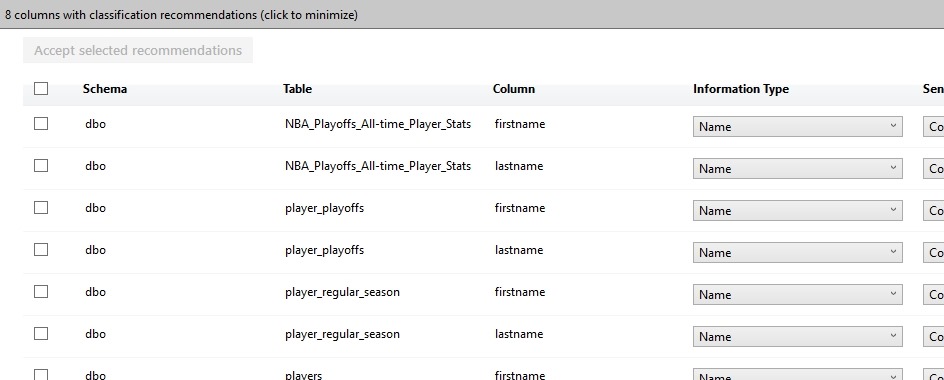
    2018-02-16 13_17_47-Data Classification - NBA - Microsoft SQL Server Management Studio

    Here we can see a few drop downs to the right. I’ll scroll and look at these. First is the Information Type. This is listed as a name, but I have other options I can set. The list is the types of that that might be sensitive information about a data subject (a human or entity) that I need to classify.
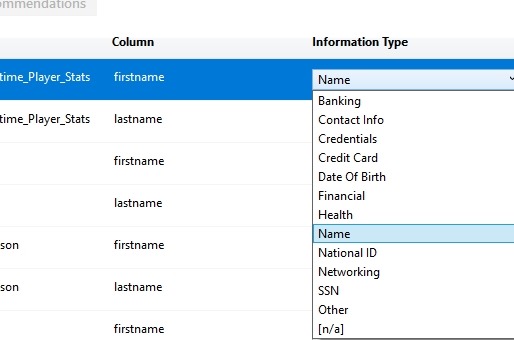
    2018-02-16 13_19_36-

    Beside this is the sensitivity label. My choices here are shown below. These range from public information, which removes some of my responsibility to highly confidential and applying to the GDPR.

    2018-02-16 13_21_14-Data Classification - NBA - Microsoft SQL Server Management Studio

    If I’m happy with these recommendations, I can select them all (or a subset) on the left. I can click the “Accept” button to add them to the classifications I have for this database.
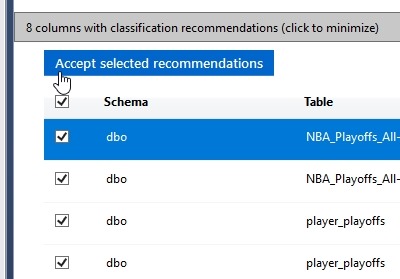
    2018-02-16 13_22_07-Data Classification - NBA - Microsoft SQL Server Management Studio

    This doesn’t save them, but adds them to the list. At the top of this tab I can see the need to “Save” my changes.
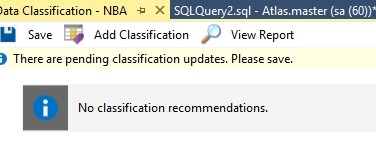
    2018-02-16 13_22_13-Data Classification - NBA - Microsoft SQL Server Management Studio

    Once I’ve done this, I could add more, or view a report. The report shows me this:

    2018-02-16 13_22_26-Data Classification - 2_16_2018 1_22 PM - PLATO_SQL2016 - Microsoft SQL Server M

    Implementation

    My guess was that these are implemented as extended properties, which makes sense. That’s how many things could make SQL Server better, and I’m right. If I examine the EP for the firstname column in one table, I see this:
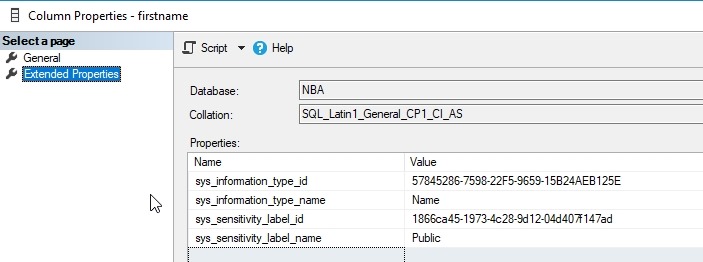
    2018-02-16 13_26_46-Column Properties - firstname

    This was the column I changed to public information. The lastname column in the same table is marked as confidential.
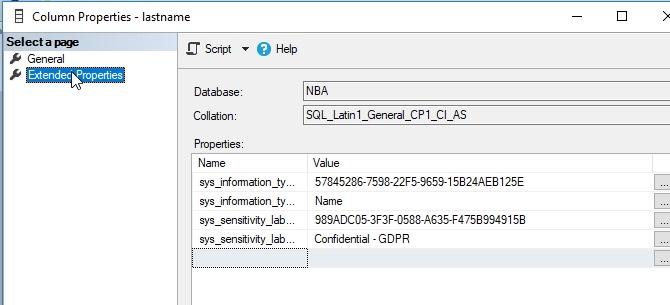
    2018-02-16 13_26_55-Column Properties - lastname

    Helpful?

    Ultimately is this useful? Yes. I can see other products taking advantage of this, such as the new Data Masker from Redgate, which could let you know which columns are sensitive and not masked. I’d also expect that this is useful and important for ETL and other operations to carry this metadata to new columns that might contain transformations or movement of this data.

  • Virtual Data

    Yesterday I republished an editorial from 2014 for the holiday. The topic was production subsets of data, which has been something that many data professionals have struggled with for years. Many of us have built scripts to delete, change, obfuscate, or alter production restores as a way of providing useful, but manageable development database sets. Or maybe it’s just some of us. I’m sure more than a few of us have given up on this task and just restored production databases in entirety to test and development systems.

    I changed over my career to become a fan of additively building a known dataset rather than deleting extra data. I advocate adding rows from production (properly masked/obfuscated) and maintaining this set over time as requirements change. However, this isn’t without it’s own administrative headaches. I think it’s easier, but this does require commitment from everyone to keep going over time. It’s certainly better than each developer adding their own 10 rows of data to a table for testing.

    A year ago, Redgate released SQL Clone, designed to solve some of these issues. Once an image is created, new databases for test and development and be provisioned in seconds. I found this to be an amazing product that really changes how I develop against databases, though it does require me to stop getting caught up trying to undo changes or manage a single database. Instead, I need to ensure I am saving code to version control and then build the habit to drop and rebuild a baseline database.

    As we’ve worked on SQL Clone, I’ve found that there are lots of companies that offer similar ways of virtualizing your data, giving you access to large, production scale systems in seconds. Data masking, obfuscation, and more are features, with some vendors requiring specific hardware. Others, like Red Gate, have software add-ons (Data Masker).  All of these products cost money, which can be an issue for many organizations, but I’m glad that this technology is growing and advancing. With GDPR and other draft legislation, many of us need to take better care of our data and build more secure architectures.

    Containers are another interesting way to virtualiza data, though they don’t solve the scale issues. If you can work with a smaller data set, and maintain that, then containers might provide a fantastic way for you to learn to build, teardown, and rebuild databases in seconds.

    The world of databases hasn’t changed a lot in some ways across my career, but in others, I’m amazed. Data virtualization is one of these areas, and if you haven’t trialed the technology, maybe you should give it a whirl this year.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.6MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • Use the Proper User for Azure MySQL DB

    I wrote about migrating the MySQL database from a third party provide to Azure MySQL DB recently. This was due to the provider raising the price substantially for me to host the site. However, after migrating the data, I ran into an issue.

    I’d read a blog on moving WordPress data and followed the instructions, but after updating my connection string, I kept getting this at tsqltuesday.com

    Error Making Database Connection

    It appeared big and bold in the browser, with no additional information. There was a time I dug into MySQL, but it’s been a long time. In any case, I wasn’t sure what the issue was, so I started messing around.

    In MySQL Workbench, I could add a new user with their GUI and grant privileges. I did this for a user called “tsql2sday”, with a password. However, when I updated the connection string in my Azure App Service, this didn’t work.

    I tried a number of items, including manually creating my own user and assigning privileges, making this a DBA (super) user, and more. Nothing seemed to work. Some of you might have even seen the error messages as I tried to get this to work.

    Eventually I checked something. In the original app service connection string, my old third party database just had the user name. This was the same for my connection in MySQL workbench. However, with my new Azure MySQL database, I needed user@dbname. For me, this was tsql2sday@tsqldb in MySQL Workbench.

    Once I added the @ and host to the connection string in the App Service, I could connect. Whew, as I wasn’t looking forward to another hosting bill.

    I think all the data is there, but if you find issues with tsqltuesday.com, let me know.

  • dbatools and Orphaned Users

    I really like the dbatools project. This is a series of PowerShell cmdlets that are built by the community and incredibly useful for migrations between SQL Servers, but also for various administrative actions. I have a short series on these items.

    One of the common issues that I would run into with refreshing development and test environments are the orphaned users. These are accounts that typically exist in production, but not in development. The logins and users are different in these environments, and often there isn’t a login on the development instance. This creates an orphaned user: one that exists in the database, but has no instance level mapping.

    Cleaning up these users isn’t that hard, often with a removal of the user, mapping to a different login, or repairing this user by adding back the server login.  These aren’t difficult tasks, but the logic to write a script to quickly fix this, especially in a DR situation, may not be handy.

    dbatools can help here with a few cmdlets. I’m not recommending this is any better than the T-SQL, but if you keep dbatools on your instances, this is a quick way to fix things.

    With Get-DbaOrphanUser, we can quickly get a list of those users that aren’t matched on the restored server. I can limit this to an instance or a database, but it gives me a list of users that I can then pipe into one of a few other cmdlets: Repair-DbaOrphanUser and Remove-DbaOrphanUser. These two cmdlets will do, as the British say, what it says on the tin. They’ll remove or remap the users, which can make it easy to quickly get your users working again.

    Note that you will want to ensure this does what you expect and run with the -WhatIf command to be sure that you aren’t altering users that you don’t want to change.

    This isn’t necessarily the way I’d always clean up users, but as part of a flow that might include automated restores, data masking, and other steps, being able to access orphaned user data and repair users from  PoSh is something I’d certainly consider.