Category: Blog

  • Flyway Tips: AI Helps with Commit Messages

    At Redgate, we’re experimenting with how AI can help developers and DBAs become better at their jobs. Everyone is asking for AI, as well as the ability to turn AI off. We’re working hard to accommodate both requests as we look for ways to leverage AI.

    One of the areas we’ve started to add some AI is in Flyway Desktop (FWD), with a few features designed to help reduce the cognitive load and save time as they work with databases.

    I wrote about summaries of migrations scripts and migration script naming recently. This post looks at another of those changes, which is the generation of a commit message..

    I’ve been working with Flyway and Flyway Desktop for work more and more as we transition from older SSMS plugins to the standalone tool. This series looks at some tips I’ve gotten along the way.

    Summarizing My Changes

    Commit messages are hard. There are numerous posts on the art of writing one, as well as no shortage of examples showing poorly structured messages. As I look through my own messages in the SQL Saturday repo, I’m somewhat surprised at times at ow well I’ve described something, or how poorly. I’ve certainly had the “fix” messages creep into my work.

    When we start making database changes, we often have a number of things we might touch. A new column could necessitate view and stored proc changes. One view might impact another, or a function. A piece of work might include alterations of a few tables, and fixes that might not be obvious need a bit of a description in the commit message.

    If nothing else, we need to ensure we’re linking commits to planned work on Azure DevOps boards, in Jira, or wherever a project manager might be assigning tasks.

    Flyway has added an AI feature to help us summarize our changes. It’s in preview as of Jan 12, 2026, and is designed to help ensure we get a better commit message than “fixed.”

    Generating Commit Messages

    When I go to the VCS tab in Flyway Desktop (FWD), I see all my changes listed. In this case, I’ve been demoing and testing a lot of things that I haven’t committed. Bad practice, and I’m a little upset with myself for not keeping my repo clean.
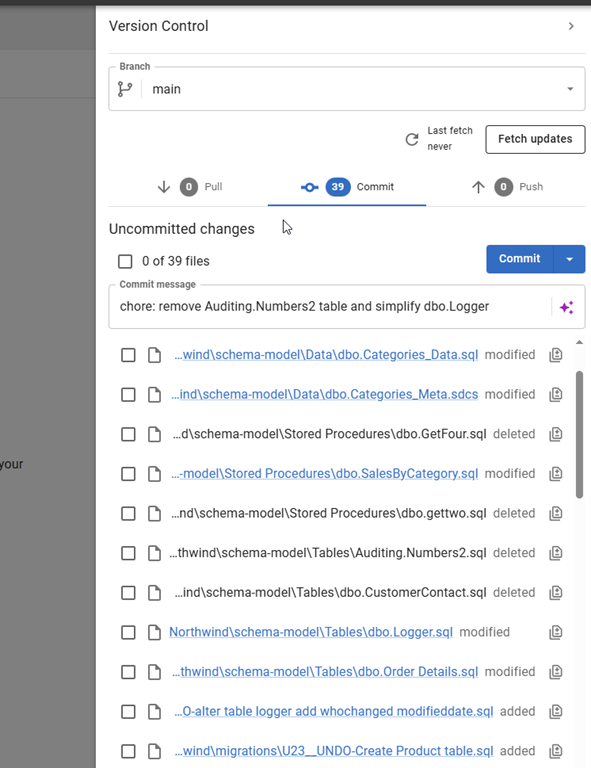
    2026-01_0186

    Notice the little sparkle below the Commit button? This is where the AI help lives. If I select a few files, in a few seconds I’ll get a message generated for me. This is a decent summary, at just over 50 characters.
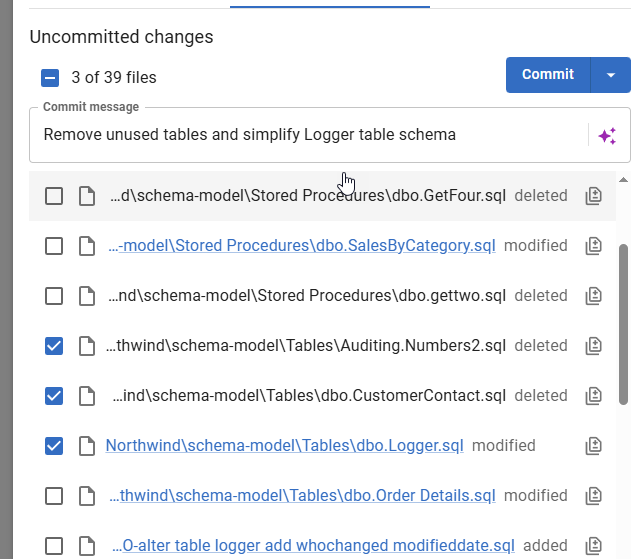
    2026-01_0187

    If I don’t like this and want to edit it I can. If I do that, the AI won’t overwrite this. I’ll change the wording and select another file. Notice that the message remains the same.
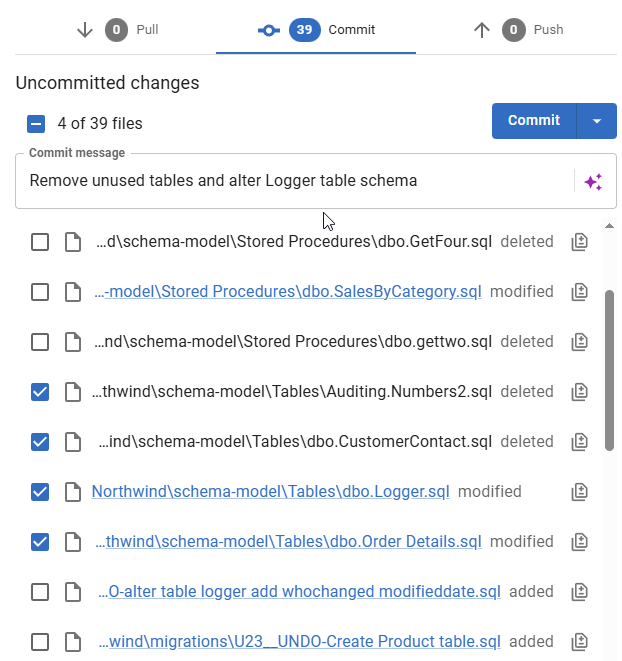
    2026-01_0188

    If I want a new message, I can click the AI sparkle and it will regenerate this. I’ll show this in the video below.
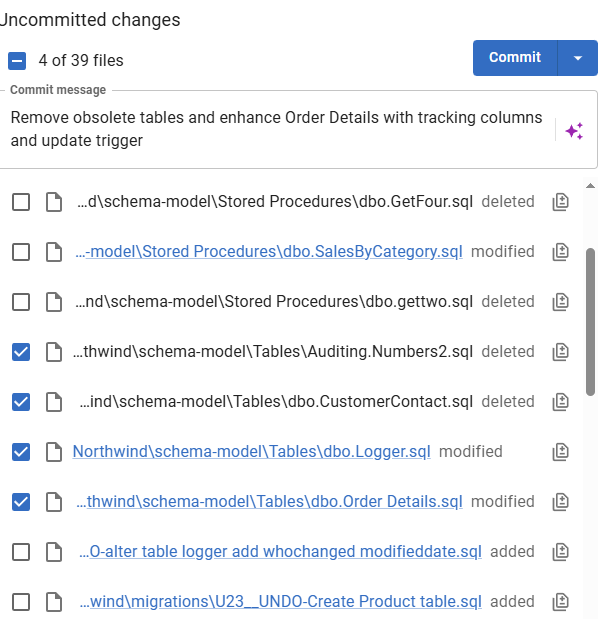
    2026-01_0189

    If I select all the files, the AI summary isn’t great, but then again, I don’t know how I’d summarize all these changes. I might not do any better.
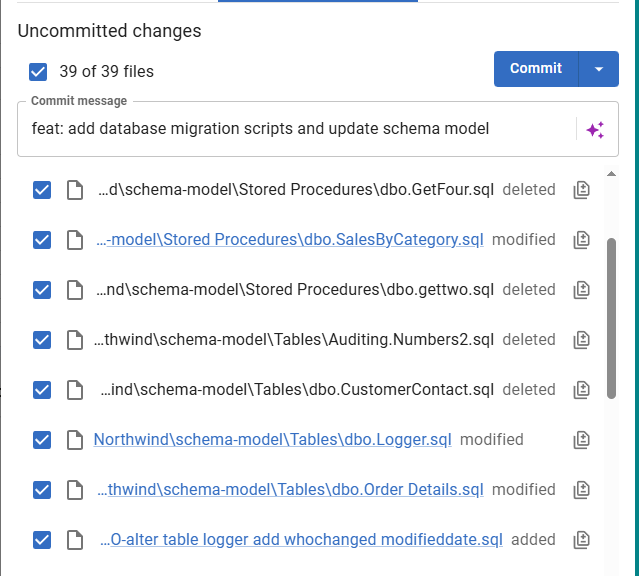
    2026-01_0190

    This is a small thing, but I often find that I struggle to come up with a meaningful message at times. Sometimes I do a good job and add something relevant with a work item number. Sometimes I want to just type “new table” or “fixed bug”.

    This reduces some of the creativity burden when I’m working through database changes.

    Enabling AI Features in Flyway

    This is a preview feature as of Jan 5, 2026 as I write this. To get this in your FWD, your organization needs to have enabled AI features in your portal. I’m just a member, but whoever is an admin for your Redgate products would find it here.

    2026-01_0173_thumb[1]_thumb

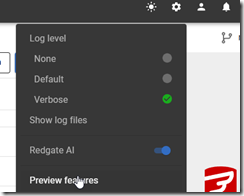
    In FWD, you need to look at the Preview Features item under the config menu.
    2026-01_0171_thumb_thumb

    In this area, you can enable or disable features as needed. I see these marked as Red-gate only, but I think they are supposed to be released to some customers by this time. It’s likely I need to upgrade my FWD, which I’ll do when I have time.

    2026-01_0172_thumb[1]_thumb

    Once you do this, you should start seeing some AI stuff with the purple/pink shaded area and the sparkle icon that we’re all seeing everywhere.

    2026-01_0174_thumb_thumb

    Summary

    Getting meaningful commit messages can be hard, but it’s also a tedious thing. I find that developers often get lazy and do the minimum. That AI might not be much better, but it does reduce the need for a user to think of a message and gives them a starting point from which to work.

    To me, this is one of the better uses of AI, handling a common, but tedious task. Now to go clean up my repo and take advantage of this with a bunch of smaller commits.

    This feature is documented, but we are likely to enhance and change it a bit, so all feedback is welcome. If your organization doesn’t want you using AI, and you could share some schema from a migration script, I’d be happy to test it for you and see what summary is produced and send it back to you. Ping me on X/LinkedIn/BlueSky if you want.

    Flyway is an incredible way of deploying changes from one database to another, and now includes both migration-based and state-based deployments. You get the flexibility you need to control database changes in your environment. If you’ve never used it, give it a try today. It works for SQL Server, Oracle, PostgreSQL and nearly 50 other platforms.

    Video Walkthrough

    See a video of me looking at this feature below.
  • A Break for the Side Job

    I wrote about Side Jobs a few weeks ago and today I’m taking vacation from Redgate for mine. I’m at Colorado Crossroads, a large volleyball tournament in downtown Denver. I suspect my players are more excited than I am since they get to play and miss school.

    Hopefully there’s plenty of coffee as I flew back from the UK yesterday.

    See you next week.

  • Using SQL Compare with Redgate Data Modeler

    Redgate recently released SQL Compare v16, which included a new feature to work with Redgate Data Modeler. I decided to give it a try in this post. I’ll take a model and compare it to a database, and deploy my model.

    There’s a video of this post at the bottom if you’d rather watch me work.

    This is part of a series on Redgate Data Modeler. This is also part of a series of posts on SQL Compare.

    A New Model

    I started a new project, mostly as an experiment to help me practice with some technologies, with the idea that this will become useful at some point in time. In my case, I created a new data model for an event registration system. We could really use one at SQL Saturday/Day of Data and right now everyone that runs an event has to handle that themselves.

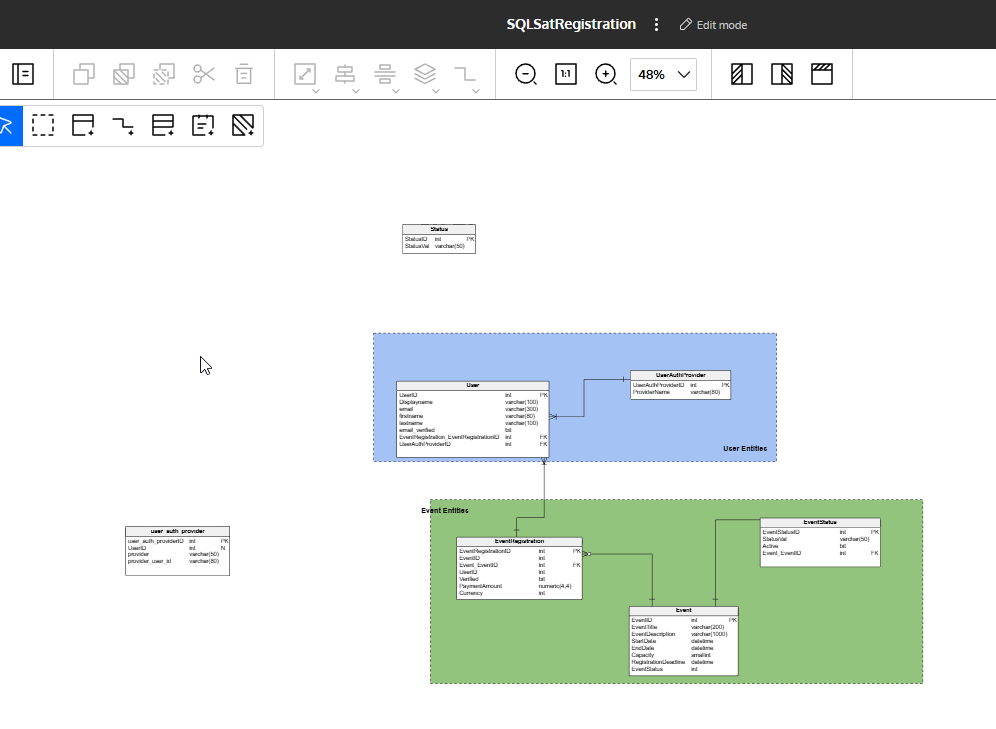
    In any case, here’s my basic starting model. You don’t need to look at the details, just know I started here by creating a model from scratch in Redgate Data Modeler. I have 7 tables that I setup.

    2025-12_0089

    I want to get this model deployed into a database. I could export the SQL, which is fairly easy, but let’s make this easy with SQL Compare 16. I upgraded after the new release, and I want to see how this works.

    Data Modeler Integration

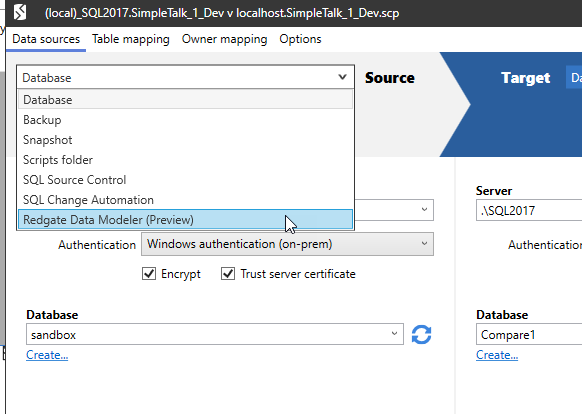
    In SQL Compare we have a new source for connecting to database code. In this case, it is Redgate Data Modeler Integration. That doc pages describes it, but when I open the tool, I can see a new choice in the connection drop down.

    2025-12_0090

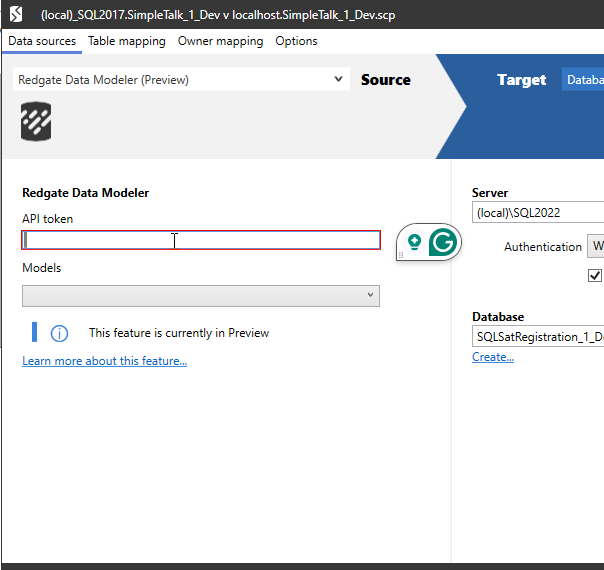
    This is a preview feature for now, but it does work. Once I select this option, I see the settings change. In this case, I need an API to get started.

    2025-12_0093

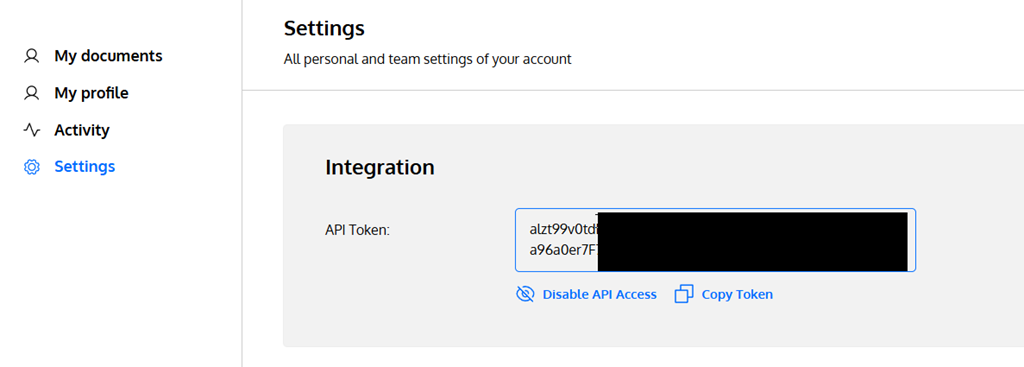
    The documentation says to go to your Settings page in Redgate Data Modeler. When I went there, I got an API section at the top, asking me to enable API access (which I clicked before taking this screenshot) and also a set of Notification Settings below this.

    Once I clicked things, I had the API token listed. I’ve blacked out most of it here, but I clicked the “copy” button to save this to the clipboard.

    2025-12_0092

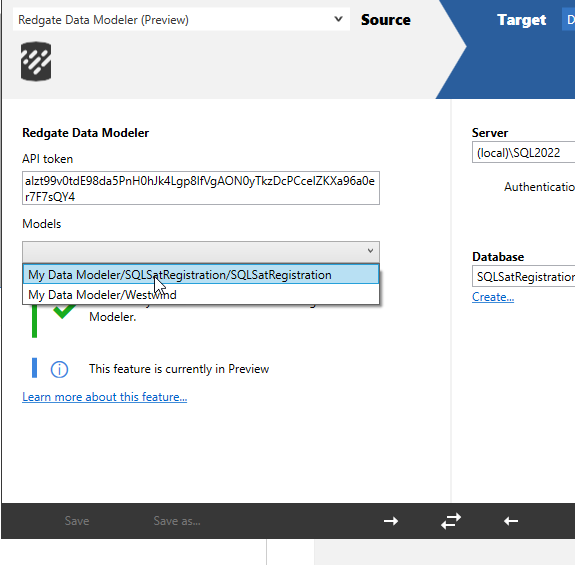
    I then pasted this into SQL Compare and the model drop down populated. I could see both my models listed.

    2025-12_0094

    For the target, I connected to an empty database that I created with this code:

    CREATE DATABASE SQLSatRegistration_1_Dev

    I could see my comparison looked correct, so I was ready to see if I could deploy my model.

    2025-12_0095

    I ran the comparison and as expected, it sees everything as new in the model and nothing in the database. I selected all objects and then clicked Deploy.

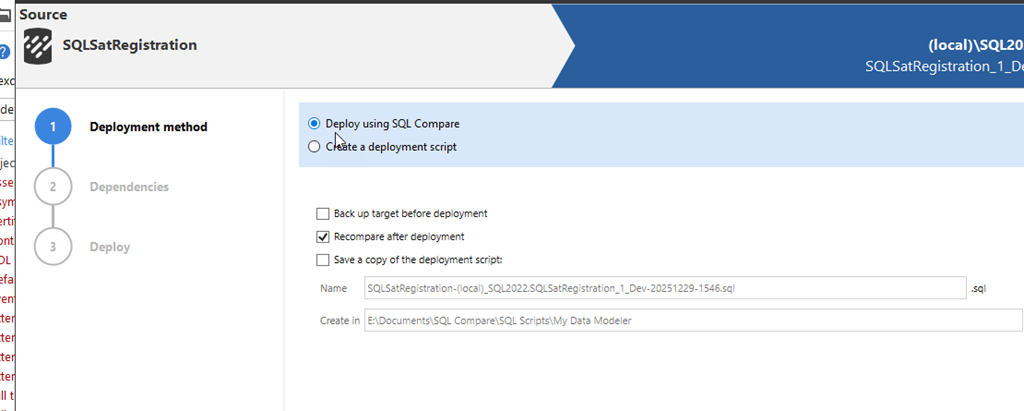
    2025-12_0096Since this is the first time I’ve deployed the model, I decided to let SQL Compare do the work.

    2025-12_0097

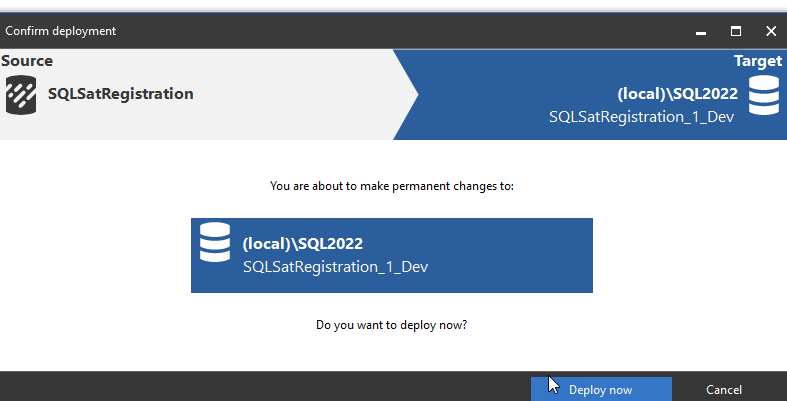
    After looking at the script briefly, I clicked Next and got the final, do you want to deploy, screen. I clicked Deploy here.

    2025-12_0098

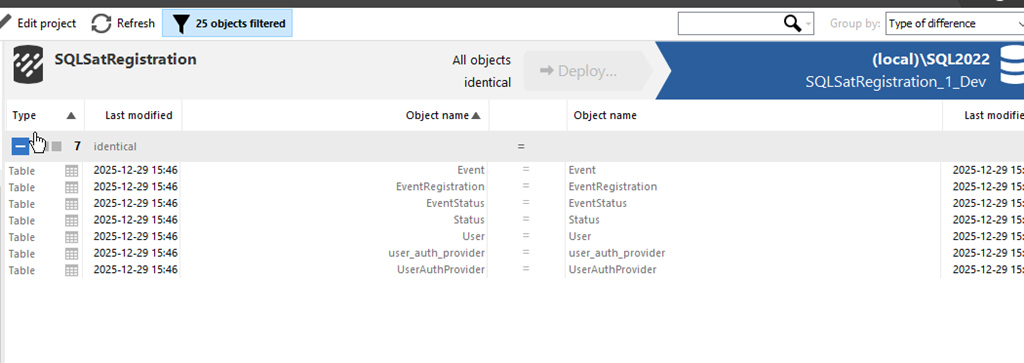
    I had selected the recompare after deployment option, so once this finished, I saw this screen. Everything is the same on both sides of the comparison.

    2025-12_0099

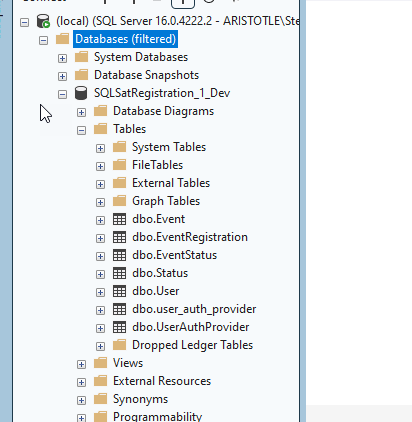
    When I checked my database, I see the objects there.

    2025-12_0100

    Summary

    This was a short look at taking a new model I’m working on and deploying it to a database for some actual work. I took a model previously created in Redgate Data Modeler and using SQL Compare, I deployed all the objects to a live database.

    This is a great integration and it’s much smoother than saving a script and then opening that to run it. I like tools working together, and I could see this being handy for architects and modelers that want to quickly test out their changes.

    SQL Compare is an amazing tool that millions of users have enjoyed for 25 years. If you’ve never tried it, give it an eval today and see what you think. Give Redgate Data Modeler a try and see if it helps you and your team get a handle on your database.

    Video Walkthrough

  • Who’s the Winningest Coach (with AI Help)

    I was listening to the radio the other day and the hosts were discussing the NFL playoffs in 2026. Someone mentioned the winningest coach was Nick Sirianni of the Philadelphia Eagles and no one wanted to face the Eagles. I was wondering if the first part of that was true. I used Claude and SQL Prompt AI to help.

    Note, I enjoyed watching the Eagles lose in the first round to the 48ers. As a lifelong Cowboys fan, that was great. However, I am impressed with Jalen Hurts and was glad to see him win last year.

    This is part of a series of posts on SQL Prompt. You can see all my posts on SQL Prompt under that tag. This is part of a series of experiments with AI systems.

    Getting the Data

    First I had to find data. I did find this page of coaching history at Pro Football Reference, which lists coaches, however, I wanted to compare the first few years of their careers, not their totals.

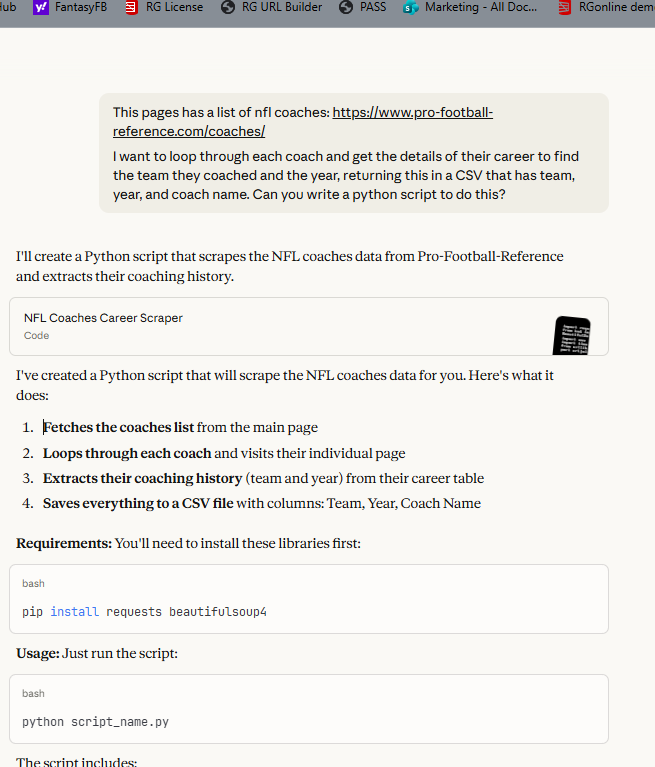
    I decided to see if Claude could help get some data. I started with a query: This pages has a list of nfl coaches: https://www.pro-football-reference.com/coaches/

    I want to loop through each coach and get the details of their career to find the team they coached and the year, returning this in a CSV that has team, year, and coach name. Can you write a python script to do this?

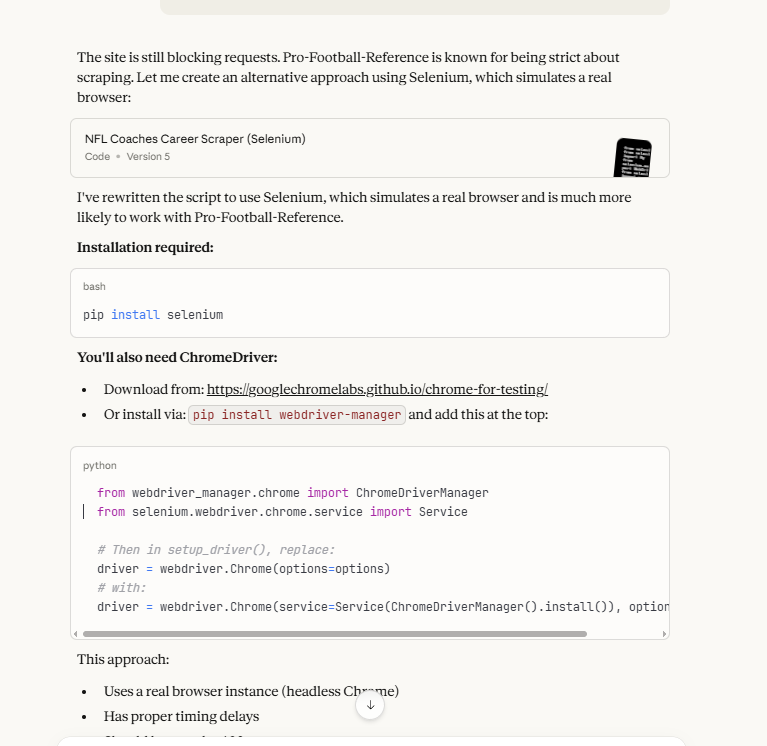
    This kind of worked. I got a script, and it ran, but there were some errors. PFR doesn’t like scrapers and they want to protect their data. I get it.

    2026-01_0117

    I told the AI there was an error and it helped me get the Chrome driver and Selenium module to drive a real browser from automation. I commented out the “headless” part so that I could see it working (a bit).

    2026-01_0118

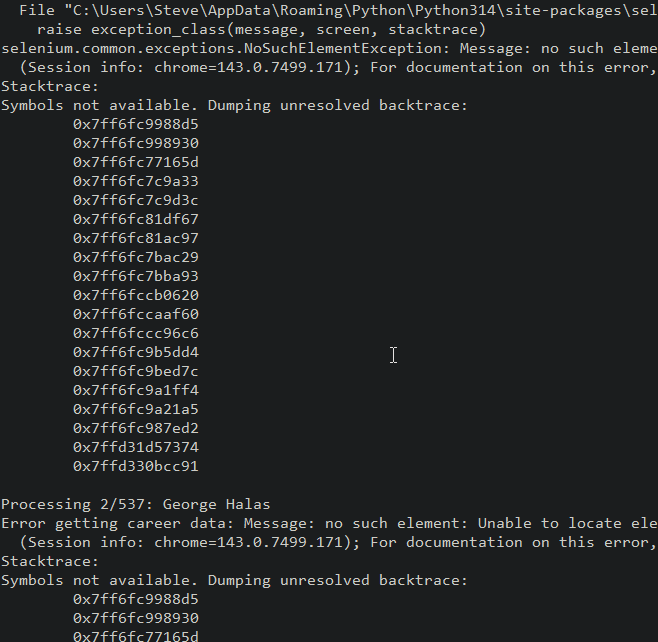
    This kind of worked, but not really. I got the coaching list and I could see the browser going through each coaches page, as well as the CLI output, but lots of errors. PFR does a good job of blocking this.

    2026-01_0119

    What was amazing is that the script in my repo is something that would have been hours of me messing with different modules and trying to debug the issues. This was literally about 30 minutes of multiple tries before I gave up for the night.

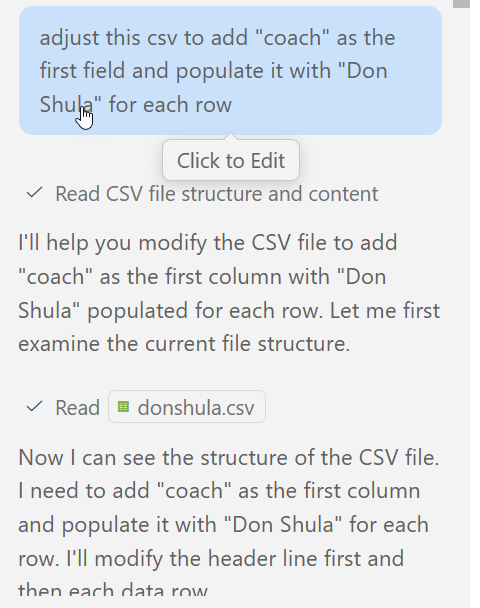
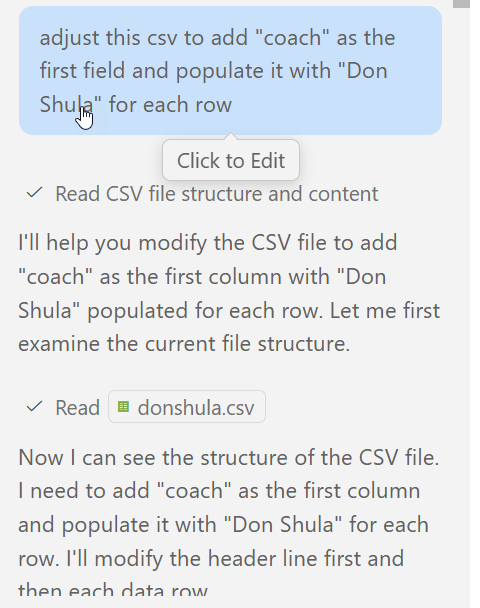
    The next day I decided to give in and just grab data from some coaches that I know have won Super Bowls and had success early in their careers (sorry, Andy Reid). I went to each page and clicked the “CSV export” item and then copy/pasted the data into a file. I then asked the Copilot AI for help. Each set of data was nice, and the file was named for the coach, but the coach’s name wasn’t in there. So I let Copilot edit it.

    2026-01_0196

    Admittedly this wasn’t automated, but by the time I’d created a new file for a new coach, CP had cleaned up my old one. With this in mind, I had 6 coaches of data stored in CSV.

    Back to Claude. No reason not to use Copilot, but I like Claude. I asked it to give me an import script.

    2026-01_0196

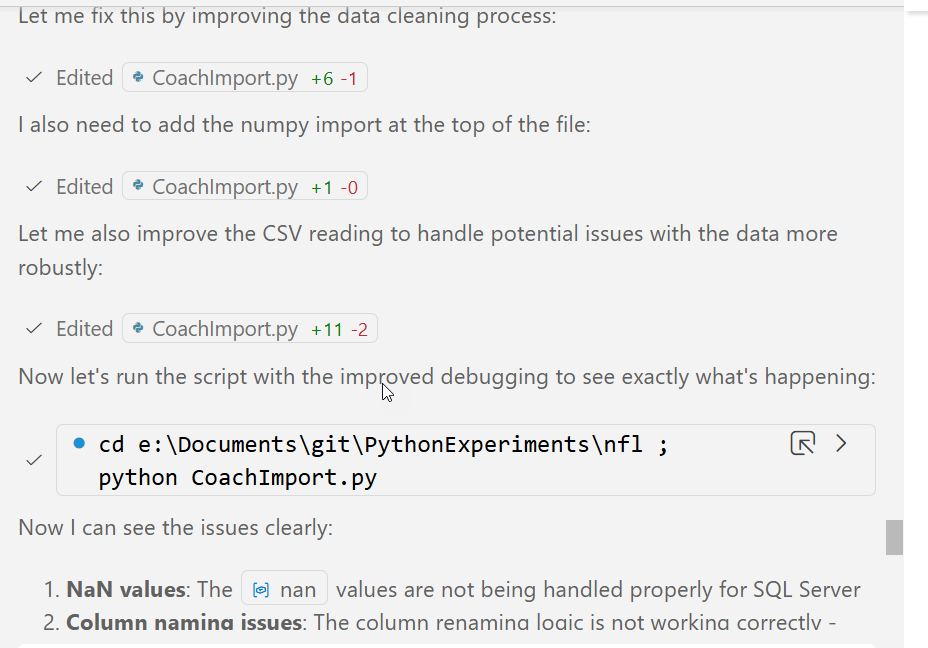
    It did, and I saved it (coachimport.py). I ran this, but it errored out. Since this was a file in my repo, I moved back to Copilot, which has access to the files. I asked it to fix the errors. This was the prompt (everything after the colon was pasted in) : I am getting this error in the script: Error importing rawdata\NickSirianni.csv: (‘42000’, ‘[42000] [Microsoft][ODBC Driver 17 for SQL Server][SQL Server]The incoming tabular data stream (TDS) remote procedure call (RPC) protocol stream is incorrect. Parameter 24 (“”): The supplied value is not a valid instance of data type float. Check the source data for invalid values. An example of an invalid value is data of numeric type with scale greater than precision. (8023) (SQLExecDirectW)’)

    It started to examine the files.

    2026-01_0200

    Then it found a problem and started fixing things. Since this is an import and I’ll stage the data, I can let it run and check the results.

    2026-01_0201

    While this was running, I also used SSMS and the Flat File Import to pull in one file from the subfolder to see how well it worked. I basically, next, next, next on this, which was good enough.

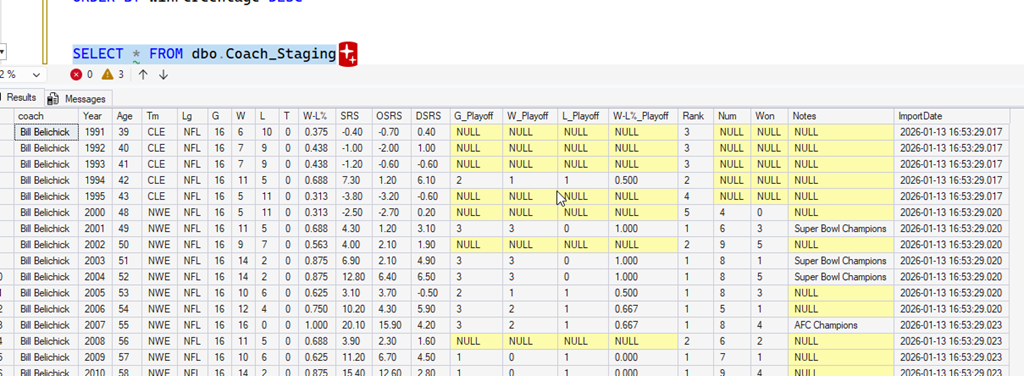
    In the time it took me to import 1 file, Copilot had finished and imported all the data. I could query the staging data and see all my rows. I quick check of the different files showed me all rows imported.

    2026-01_0203

    This was with the free Claude web tier and paid corporate Copilot account.

    Now, what do we learn?

    The Analysis

    Since I had the data in a table, I could use SQL Prompt AI to help analyze the data. I started with a simple query:

    SELECT coach, SUM(w) OVER (PARTITION BY coach)
    FROM dbo.Coach_Staging

    I could do more, but I’m playing with AI tech, so I then added a prompt: help me analyze this data by comparing each coaches first 5 years with wins, losses and ties and win percentage.

    I got this code:

    SELECT coach,
    SUM(W) AS TotalWins,
    SUM(L) AS TotalLosses,
    SUM(T) AS TotalTies,
    CAST(SUM(W) AS FLOAT) / NULLIF(SUM(W) + SUM(L) + SUM(T), 0) AS WinPercentage,
    AVG(CAST(Rank AS FLOAT)) AS AverageRank
    FROM
    (
    SELECT coach,
    Year,
               W,
               L,
               T,
    Rank,
    ROW_NUMBER() OVER (PARTITION BY coach ORDER BY Year) AS YearNum
    FROM dbo.Coach_Staging
    ) AS CoachYears
    WHERE YearNum <= 5
    GROUP BY coach

    That’s about what I would have written. I was about to start adding the row_number when I thought Prompt could help me. I additionally asked for an order by and an average rank, and ended up with a query that made sense.

    The takeaway for me was that I could have written the code, but in a few seconds, SQL Prompt gave me a query I could use. This was way faster than I could have written the query, even with SQL Prompt Intellisense.

    The Results

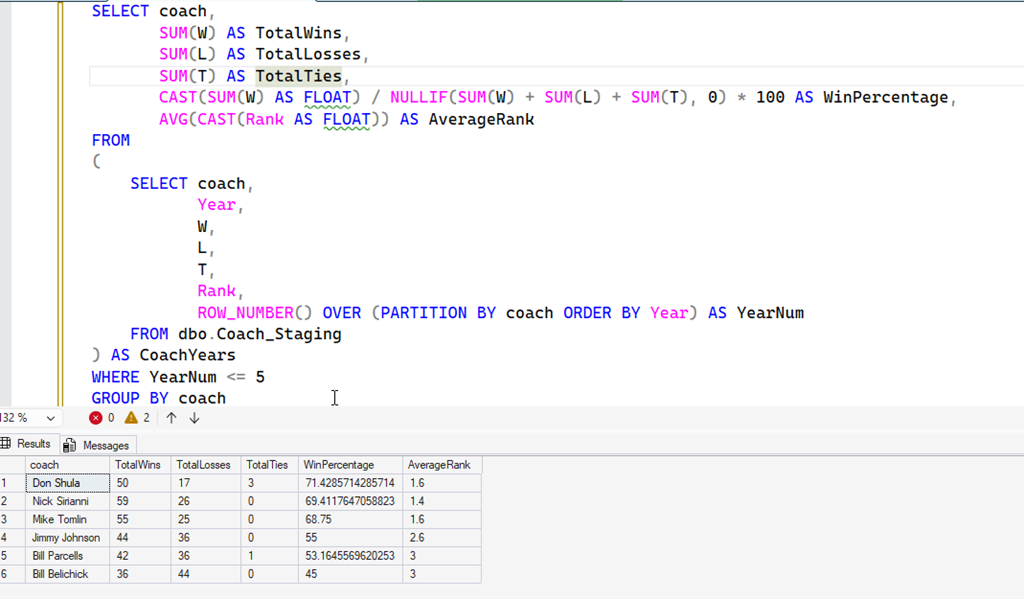
    Well, is Sirianni the winningest coach in his five years. Here’s what I see.

    2026-01_0210

    By win percentage, Don Shula is better, but there were less games, so Nick Sirianni has more wins and losses, and a slightly lower percentage, but a higher rank. I think it’s fair to say he tops the list, though it depends whether you look at wins or percentage.

    It was also surprising to see Mike Tomlin, who recently left the Pittsburgh Steelers, coming in third.

    An interesting analysis that went way quicker than a few I’ve done in the past. AI is incredibly helpful here, and as I think about all the similar types of queries people have asked for help with over the years, I can see how AI will be very helpful over time.

    Of course, with larger data sets, you’ll want to verify the queries are working with other checks of the data, and you’ll likely want some automated tests on small sets to verify any changes to algorithms still return the correct results.

    If you haven’t tried SQL Prompt, download the eval and give it a try. I think you’ll find this is one of the best tools to increase your productivity writing SQL.