Category: Blog

  • Shipping Database Changes–T-SQL Tuesday #90

    tsqltuesday

    This is a good T-SQL Tuesday topic from James Anderson: shipping database changes. It’s especially poignant for me since I talk and present often on this topic. Much of my work at Redgate involves helping people implement DevOps for Databases, deploying changes smoothly and efficiently to databases.

    I’ve got lots of stuff here, but let me go back to a previous position, many years ago before TFS, when Visual SourceSafe (VSS) was in heavy use in development. We implemented DevOps before DevOps was a thing, and included our database changes.

    Smoothing Deployments

    I worked at a startup company and we were trying to respond to requests from management and sales. As we grew from 4 developers to 10, plus a DBA (me) and a QA person, we needed to smooth out our process. Over a few months we got into a particular schedule:

    • Monday noon – Package up all completed changes for deployment to QA.
    • Monday afternoon – Discuss and plan changes for the following week
    • Tuesday-Wednesday – Bug fixes as needed
    • Late Monday to the following Monday – write code for the next deployment
    • Wednesday evening after 8 – deploy changes to production

    I had a foot in both the development and operations world and had to reconcile the need for production to work and remain stable while also ensuring new changes could be deployed every week. We were a young, new company, and we often had database changes included each week in our package.

    When I started, we would talk to developers on Monday, start to gather all the changes from VSS for our web application, script out all database code, and then deploy to QA. Inevitably, some code would be forgotten or wrong, and we’d track it down sometime between Monday noon and Wednesday noon. Then we’d (hopefully) have a good folder of changes that we could deploy to production on Monday night, manually running .sql files or copying web code to remote servers.

    The Old Process

    When I started deploying code with this group, I’d get some dinner Wednesday afternoon and then return to the office with 2-3 other developers to deploy code. I usually had notes from various issues that QA had discovered in their testing, sometimes altering scripts in real time to ensure they would deploy and work correctly on the production database.

    Myself and the web developers would work to get code deployed in an hour or so each week, and things usually went well. We’d have hiccups and issues, but we worked through them and talent helped. It was a good team and we could usually solve our issues.

    Getting Better

    The lead developer and I both had little children at the time. Spending 12+ hours at work on Wednesday wasn’t an ideal situation for us, and we decided to get better.

    The first thing we did was ensure that all code was tracked in VSS. We had most web code here, but there were always a few files that weren’t captured, so we cleaned that up. I also added database code to VSS with the well known, time tested and proven File | Save, File | Open method of capturing SQL code. This took a few months, and some deployment issues, to get everyone in the habit of modifying code in this manner. I refused to deploy code that wasn’t in VSS, and since our CTO was a former developer, I had support.

    The other change was the lead developer and I started building a release branch of code each week. We’d move over the changes that were going to be released to this branch, which simplified our process. We could now see exactly which code was being deployed. This was before git and more modern branching strategies, but we were able to easily copy code from the mainline of development to the release branch as we made changes for this week.

    Since some changes might be in development for a few weeks, we couldn’t just grab the latest version of every file. We needed to know which pages, and which database changes would be released and which were still in development.

    Automation

    Once we had the code tracked, we began to automate deployments. Both the web developer and I built separate scripting tools because we had different needs. Web code is easier, mostly just copying files to the correct locations. We had a few token replacement issues, but some creative scripting solved those.

    For the database, I had a single application and a single database, which is a simple problem to solve. Deploying database changes were always taking the latest version of object code, which might be a CREATE, or it might be an ALTER. In my case, I separated code into folders (tables, views, etc.) and then added scripting to ensure that I deployed objects in order. For the most part, we could work in gross orders (Tables first, then views, then procs, etc.). We had a few items that were out of order, but hard coded deployment checks ensured these issues were handled.

    My additional challenge was managing QA, which was my test environment for deployments as well as the application. I added processes that would automatically refresh the QA environment from production. This was a button click to start the process. Once this was done, I’d use my deployment process to deploy the database changes for the week from VSS.

    If we found issues in QA, and code changes were needed, we went back to development, made the changes there, committed to VSS, and then repeated the process. With automation and a small database, we could rebuild the QA environment with a new package in about 15 minutes.

    Going Live

    The first couple times we deployed to production, the lead developer and I still went into the office and made sure the deployments ran. After two weeks of watching our process run in about five minutes, we realized this was silly.

    For over a year, we would continue to deploy changes every Wednesday. The lead developer and I would get on the phone every Wednesday at 8pm. We’d VPN to the office and I’d deploy database changes (5 minutes or so) and then he’d run his application scripts (2-3 minutes). We’d check a few things and then sign off.

    Life got much better, we built confidence in our ability to deploy, which meant the business trusted us to get changes out to customers every Wednesday. Perhaps most importantly, we started working more normal hours rather than crazy startup schedules. We could even make quick patch deployments on a Thur or Fri if needed, and because we could smoothly roll out changes, we were under less pressure to pile as much as possible into the next deployment. If something didn’t get done in time, it would just roll to the next week.

    Modern Tools

    I work for Redgate Software now, and we’ve spent a lot of resources (and brainpower) to try and help you deploy code in an easier way. Deploying database changes is hard, because we need to maintain the state of our system.

    These days, I might still use a home-grown, scripted approach if I had one application and one database. However, I’d really consider using other tools, because they mean my developers don’t spent time doing simple scripting, they spend time solving application problems.

  • More Data Masking Options from The Foundry

    I’ve written about The Foundry before, a research group within Redgate Software. It’s a bit like Microsoft Research, but with a tighter focus on specific database related issues. One of the areas of investigation is data masking, which is becoming more important to organizations all the time as development and QA systems get breached by hackers.

    In an effort to continue their work, they’ve added a new option to the data  masking: configurable masks. This is is along the lines of the choices that Dynamic Data Masking gives you in SQL Server 2016+, but it’s built for refreshing your dev/test systems.

    If you think you want to understand the issues and how masking might help you, give the POC a try. It’s a basic representation of the problem (deployed in Azure) that you can play with and investigate the issue.

    We’d love feedback, and perhaps some of this will make it into a product, or maybe this will just be research into the issue. Either way, it’s the chance to participate and learn a few things about the problems that we face with databases.

  • DevOps Basics–Getting Started with Git

    Git is taking over the world as a Version Control System (VCS) and it’s actually fairly easy to use. This is a quick post on getting started using git.

    Git is free and you can get it from: https://git-scm.com/

    I use Chocolatey, and you can also download it for windows with this code:

    choco install git

    or

    choco update git

    In any case, this is a simple install on your machine. If you’re on OSX or Linux, you can download and install it in whatever way you want for those systems.

    Once Installed

    You can check that git is installed at the command line. There are also clients, but I like the command line, especially when getting into DevOps.

    git version

    This code tells you if git is installed. In this case, you can see my version (after I updated).

    2020-03-25 11_25_47-Window

    Now it’s installed, what do I do? Well, I first want to create a repository to track my code. A repository (or repo) is really a folder where all changes to code are tracked. I can do this with the “git init” command, but I need to do this in an empty folder.

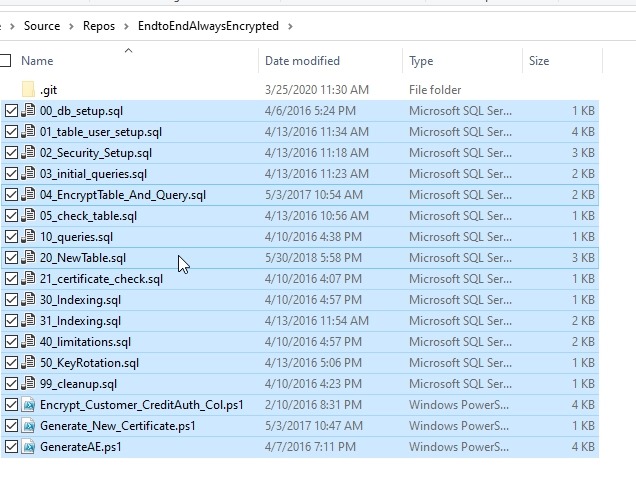
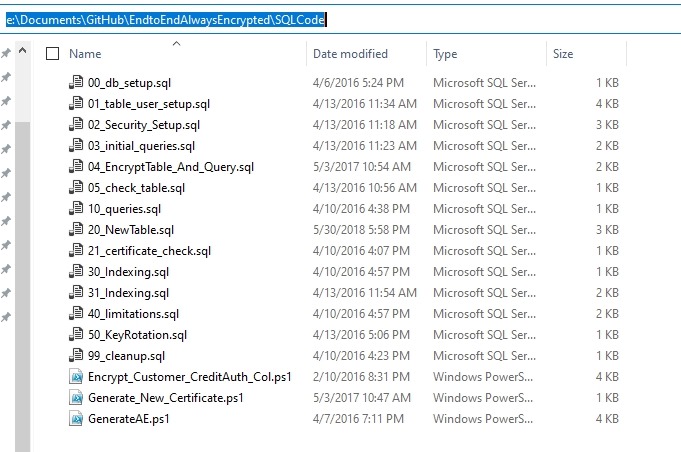
    I have some code in e:\Documents\GitHub\EndtoEndAlwaysEncrypted\SQLCode for a presentation I do. I can see lots of .sql files in here:

    2020-03-25 11_28_03-Window

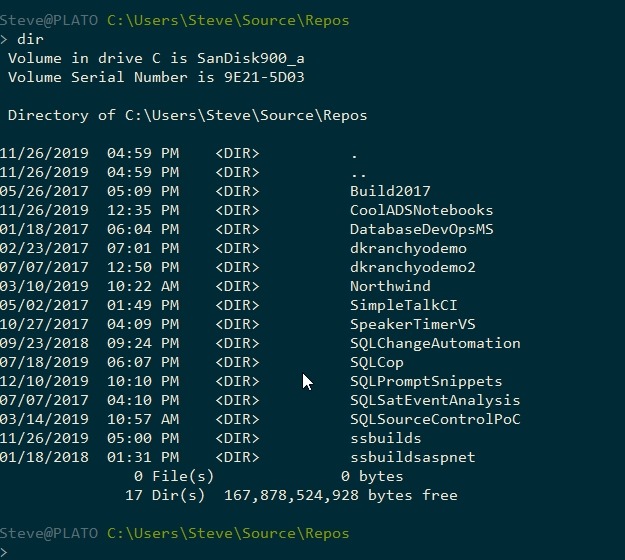
    I want to track this code, so I’ll make a repo for it. On Windows machines, there is a Source\Repos folder under your user profile. For this machine, that is C:\Users\Steve\Source\Repos. You can see I have a few folders here:

    2020-03-25 11_28_59-Window

    Let me create a new folder, called EndtoEndAlwaysEncrypted. Once I do that, I’ll change to that folder and run

    git init

    This initializes a repository. There’s nothing in there bit a hidden .git folder, but that’s fine. I now paste in my code.

    2020-03-25 11_31_57-Window

    So far nothing is different with my code. However, if I check my status at the command line, I’ll see there are no files. I do this with

    git init

    This gives me some results.

    2020-03-25 11_33_18-Window

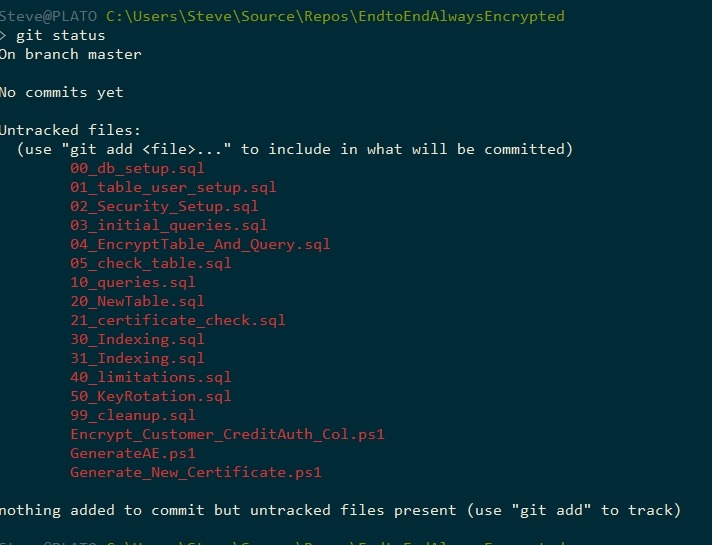
    Don’t worry about the master branch item. The thing to notice here is that all the files in red are new and aren’t being tracked by git. To add these to my git VCS, I need to track them and then commit them. To track them, I’ll “stage” them with

    git add –all

    This will add all the files. I could use git add with a filename after it, or use the dot (.) to add everything.

    2020-03-25 11_35_31-Window

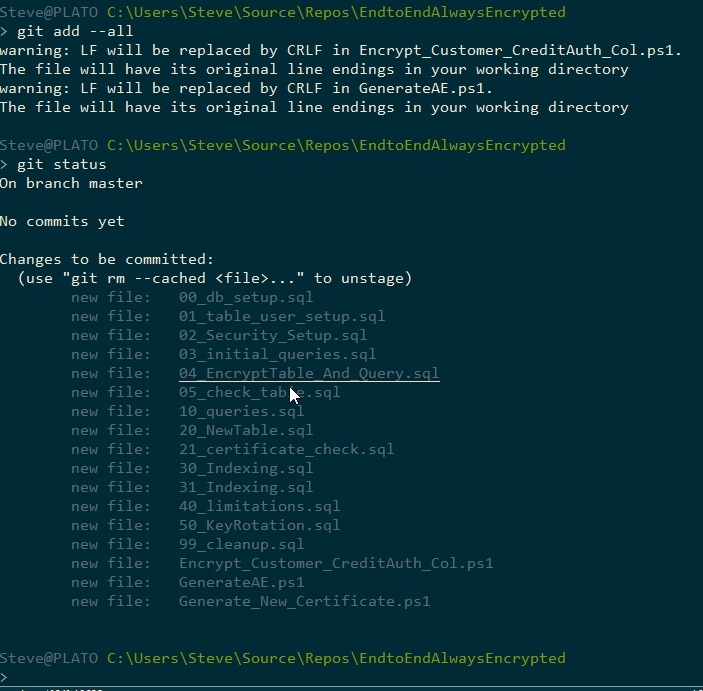
    Notice now that the files are in a lighter color, as they are tracked, but not committed. A commit means that git now knows about this version of the code and will be able to return to this version if you need it.

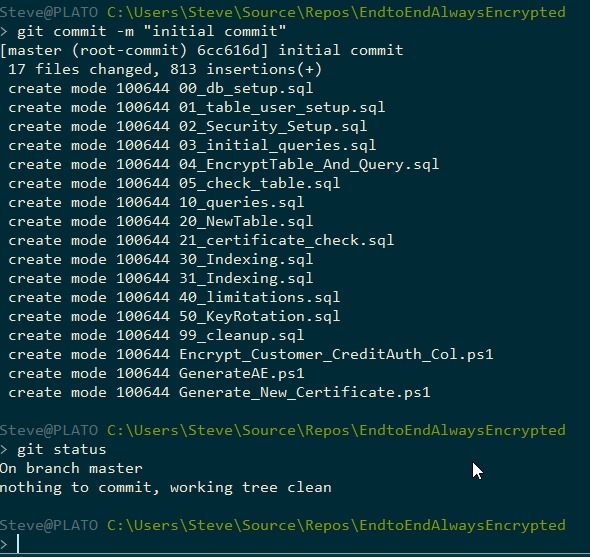
    To commit, use “git commit”. You need a message for the commit. Most GUIs make this easy, and git will pop up a text editor if you want. I prefer the command line, and use the –m parameter with a message. For the first commit, “initial commit” is usually a good message.

    git commit –m “initial commit”

    Once you do this, the status shows clean, which means everything is being tracked by git.

    2020-03-25 11_41_21-Window

    That’s it for getting started. This doesn’t seem like much, but it’s the basis for now tracking code. No more need for me to do something like “00_db_setup_old.sql” or “oo_db_setup_2.sql” for filenames. I can make changes, capture (commit) them, and then easily see what each version looks like.

    I’ll cover more later.

    If you want to see this as a video post, I’ve got it on my Voice of the DBA YouTube playlist here: https://youtu.be/hyyy9obHmw8

  • Copy-SqlJob, a handy dbatools cmdlet

    I really like the dbatools project. This is a series of PowerShell cmdlets that are built by the community and incredibly useful for migrations between SQL Servers, but also for various administrative actions. I have a short series on these items.

    One of the things I’ve often needed to do is move jobs around between instances of SQL Server. I’ll often test a job on one instance, maybe run it for awhile to see if it’s a useful addition to my instance, and then deploy the same job to other instances.

    I do this often with jobs that help each instance manage itself independently. While each new build often includes some standard settings and jobs, I do find that I’ll adjust jobs over time, fix bugs, enhance them, and I’ll need to move the job over. This has usually involved scripting the job on one instance, adding delete code, and then running the script on other instances.

    No longer.

    Enter Copy-SqlJob

    One of the cmdlets in dbatools is Copy-SqlJob, which does what you’d expect. It copies jobs from instance to instance. If you look at the docs, but default it copies all jobs, but I rarely need that. Though I might start using that for new builds along with Copy-SqlDatabase to move my DBA database from machine to machine.

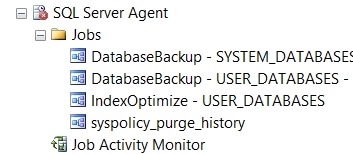
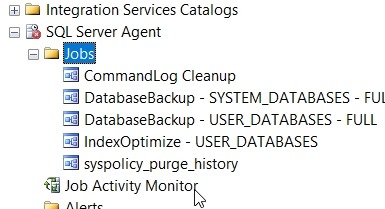
    However, I can copy specific jobs, which is perfect for my purposes. Just put a list of jobs to be copied in a script and run that. Let’s see how this works. On one instance  I have a number of jobs.

    2017-05-01 13_58_50-SQLQuery2.sql - (local)_SQL2016.master (sa (82))_ - Microsoft SQL Server Managem

    Another instance has fewer jobs.

    2017-05-01 13_58_55-SQLQuery2.sql - (local)_SQL2016.master (sa (82))_ - Microsoft SQL Server Managem

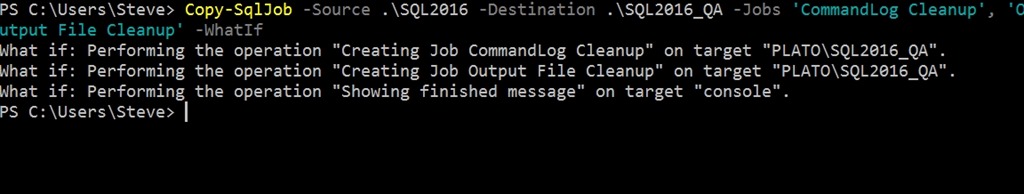
    Let’s move just the CommandLog Cleanup and Output File Cleanup jobs over. I can fire up a PowerShell and go from there. I’ll start with the –WhatIf parameter, which lets me test without moving anything.

    2017-05-01 14_06_19-powershell

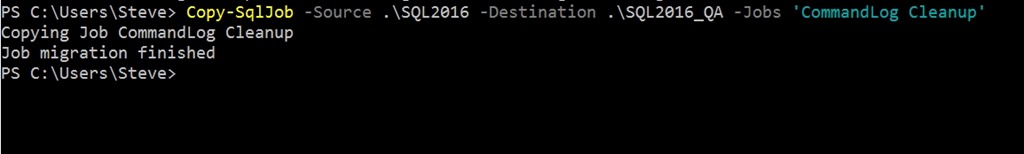
    That’s easy enough. Let’s just move one job for now, the CommandLog Cleanup job.

    2017-05-01 14_07_08-powershell

    And refreshing the second instance:

    2017-05-01 14_07_18-SQLQuery2.sql - (local)_SQL2016.master (sa (82))_ - Microsoft SQL Server Managem

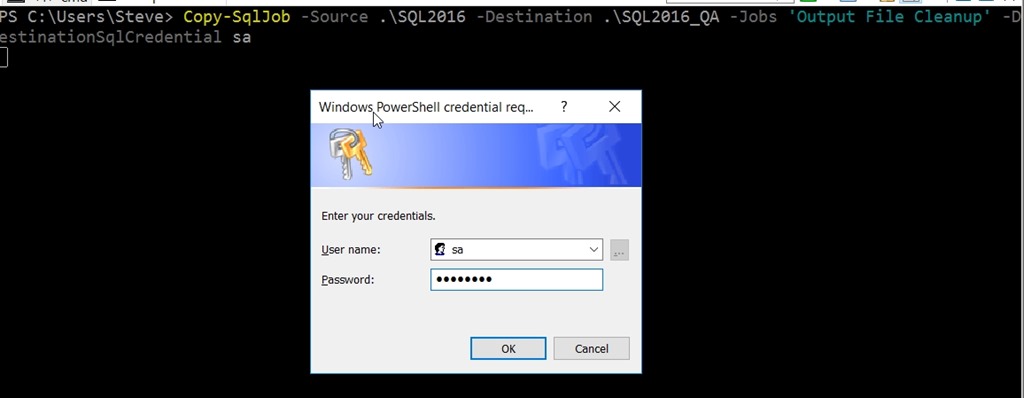
    That’s useful, and it works easily across these instances with Windows Auth. What if I need SQL Auth? I can use SourceSqlCredential and DestinationSqlCredential to specify accounts. I can even have this prompt me for the password:

    2017-05-01 14_09_06-SQLQuery2.sql - (local)_SQL2016.master (sa (82))_ - Microsoft SQL Server Managem

    Once I type it in, the copy works.

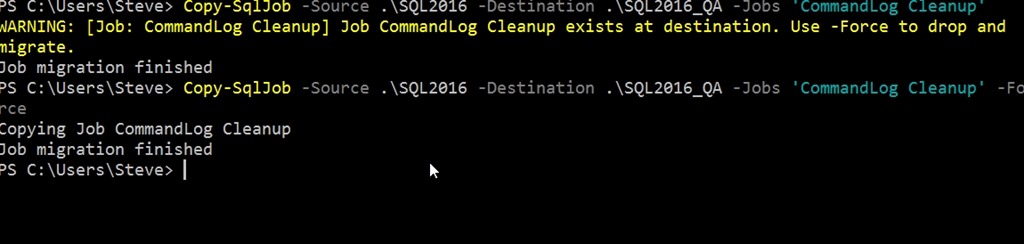
    What if I update a job on the source server, and need to ensure the changes get copied to the destination? I can use –Force. If I don’t, I’ll get a message that the job exists. With the Force parameter, the job gets copied.

    2017-05-01 14_12_10-powershell

    This is a simple, but handy way to move jobs between servers. Many of the dbatools cmdlets are designed for migrations, and this is no exception. You can migrate jobs easily if that’s your requirement.

    I’d urge you to download dbatools and see which of these cmdlets might make your administration of SQL Server easier than you ever expected.