Category: Blog

  • Updating Extended Properties

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as#SQLNewBloggers.

    I wrote recently about adding extended properties. Updating them is very similar. There’s an analogous procedure called sp_updateextendedproperty that changes the value of properties.

    The arguments are again, unintuitive, but the more I work with extended properties, the more comfortable I become. In this case, I have the same name and value, and then the level 0,1, 2 items with both a type and name.

    I highly suggest, however, that you name your parameters, including the names in your calls so programmers running across the T-SQL aren’t depending on position for an understanding of the parameter.

    If I look at the table from the previous post, I can update the value of my property with this code:

    EXEC sys.sp_updateextendedproperty
      @name = 'PKException'
    , @value = 0
    , @level0type = 'schema'
    , @level0name = 'dbo'
    , @level1type = 'table'
    , @level1name = 'SalesHeader_Staging' -- sysname
      ;
    GO


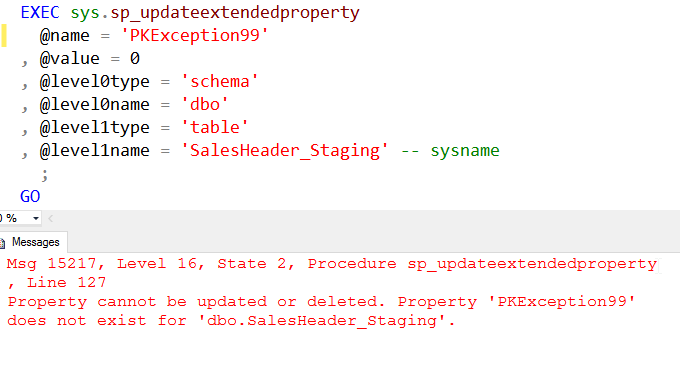
    However my property needs to exist. If I call this procedure with the wrong property, I get an error.

    2015-11-02 17_25_03-Cortana

    This means that you need to be sure that the property exists before you update it. Good code would have the error handling somewhere.

    SQLNewBlogger

    After writing the previous post, this one took only about ten minutes to do the typing. I’d been working with extended properties, so I had the code and just needed to take the screenshot.

    Reference

    A few items from BOL

    sp_updateextendedproperty – https://msdn.microsoft.com/en-us/library/ms186885.aspx

  • Poor Data Modeling – T-SQL Tuesday #72

    tsqltuesdayThis month Mickey Stuewe hosts the T-SQL Tuesday and she has a great topic. Data Modeling is something few people seem to do, especially developers, and it often can go wrong. That’s the topic, and I have a short story.

    T-SQL Tuesday is a monthly blog party, on the second Tuesday of the month. The rules are on Mickey’s blog, and you can read them there, but essentially you write a post every month.

    Or later.

    The Aging Model

    I once worked at company that shall rename nameless. We had a system built before my time which had a hierarchical set of entities. I can’t disclose the exact industry, but imagine that we had a list of items like this:

    • Manufacturers of products
    • Distributors of products
    • Warehouse holding products
    • Vendors selling products.

    In this structure, we have a strict linkage where each item below the next is contained in the item above it. In other words, a manufacturer works with specific distributors and only those distributors. Distributors don’t work with other manufacturers.

    I know this sounds contrived, and it is for a supply chain. However not for the industry in which I worked. So imagine we’re 100 years ago when power was more concentrated with supply chains.

    This resulted in tables like this:

    CREATE TABLE Manufacturers ( manufacturerid INT IDENTITY(1, 1) CONSTRAINT manufacturer_PK PRIMARY KEY ( manufacturerid ) , manufacturername VARCHAR(200) , primarycontactid INT -- ... ); GO CREATE TABLE Distributors ( distributorid INT IDENTITY(1, 1) CONSTRAINT distributor_PK PRIMARY KEY ( distributorid ) , manufacturerid INT CONSTRAINT Distributor_Manufacturer_FK FOREIGN KEY REFERENCES dbo.Manufacturers ( manufacturerid ) , manufacturername VARCHAR(200) , PrimarySalesPersonid INT -- ... ); GO CREATE TABLE Warehouses ( warehouseid INT IDENTITY(1, 1) CONSTRAINT warehouse_PK PRIMARY KEY ( distributorid ) , distributorid INT CONSTRAINT Warehouse_Distributor_FK FOREIGN KEY REFERENCES dbo.Distributors ( distributorid ) , warehouse VARCHAR(200) , regionid INT -- ... ); GO


    Each of these links to the item above it. This means that I might have a Manufacturer  table like this:

    manufacturerid  manufacturername   …

    ————–  —————-  

    1               Acme

    2               Big Product Corp

    With warehouses linked as shown.

    warehouseid  manufacturerid warehousename   …

    ———–  ————– ————-  

    1            1              Denver Central

    2            1              Kansas City East

    3            2              Santa Fe

    4            1              Billings Depot

    This would mean that I used distributors that worked with a warehouse, and their data would be.

    distributorid warehouseid distributorname  …

    ————- ———– ————-  

    1            1            Denver City

    2            1            Denver South

    3            1            Aurora

    4            2            Kansas City Distributors

    5            3            New Mexico Wholesale

    If I wanted to get a list of the distributors that carried a manufacturer’s products, I’d have to join through the warehouse table.

    SELECT manufacturerid , ... FROM dbo.Manufacturers AS m INNER JOIN dbo.Distributors AS d ON d.manufacturerid = m.manufacturerid INNER JOIN dbo.Warehouses AS w ON w.distributorid = d.distributorid ...

    Not a big deal, but we had 5 levels of this appear over time. Which means that queries that might need a higher level had to cross tables in between to join data. These also weren’t narrow tables, with a decent amount of meta data for each entity. Indexing helped, but certainly we needed better rollups of data, and performance suffered as the amount of legacy data grew.

    What’s more, over time, we learned that business changes. A warehouse might start to work with multiple distributors, and our model couldn’t cope.

    Eventually we embarked upon a project that set of link tables between entities, so that we had just IDs in a table that showed linkages where appropriate. This was ongoing when I left, but it was a major disruption and problem for the company.

    I’ve tried to avoid embedding hard relationships based on business contracts in my models. Certainly some FKs make sense, like order details linked to a specific order, but many other relationships aren’t as tightly bound, and it is possible that they will change. It doesn’t cost me a lot in modeling to treat suspect relationships as many:many, and if application development does this from the start, it’s an easy architecture to incorporate in their development.

    Data modeling is always a struggle as we often work with incomplete information because an organization will morph over time. It is, however, worth taking some time to think about the possible ways in which things might change in the future and allow for some flexibility in your model where possible.
  • What is the DLM Maturity Model?

    I’ve written a few posts on the Redgate Software blog to try and show how I see the DLM model, and how we see things at Redgate. We have a lot of developers that work in a similar way when building application software in C#, Java, Python, or other languages, and much of the company is trying to bring more engineering to database development.

    Part of what the DLM maturity model aims to do is help us classify how we progress to a more engineered, repeatable, and reliable way of managing database development. You can read my overview, and then dive into each of the various levels we’ve built. The levels are:

    Some of this is based on the CMMI model from the SEI, and some is based on what application developers are doing with their own continuous delivery mode. Simple Talk has written a What is DLM? article as well, and includes a different view of a maturity mode.

    I think this process becomes more important over time as we depend more on software and the databases behind them, with fewer and fewer tolerances for downtime or human mistakes in the deployment process.

    I’d like to get feedback from people on what they think of this model, and of the idea of engineering better database development. I know many people have built their own process, but far too many of the processes rely on custom scripts that are built and edited for each deployment, sometimes in the middle of the deployment. I think we could actually make database development better if we applied some better structure to our deployment.

    Redgate is working on tools to support this, in a few ways, but this isn’t about Redgate. Rather, it’s about building better software for everyone, whether you use Redgate tools, another vendor’s tools, or build your own. Follow a better engineering process.

    If you’d like to know more about the CMMI model, Alex Nordeen built a fools guide to the framework. It’s easier to read and understand than the CMMI site.

  • Rebooting SQLNewBlogger in November

    I ran into Ed Leighton-Dick last week at the PASS Summit and we were chatting about the SQLNewBlogger challenge he started in April. I enjoyed it and while a number of people started, it seemed like most waned away. I tried to keep the challenge going with my own posts, adding notes to the posts on how much time I spent to give you confidence you could successfully blog yourself.

    Ed wanted to kick off the challenge again, and he did earlier this week. There’s a November SQLNewBlogger challenge, asking you to get four posts done this month. One is due each Tuesday, which means the first was four days ago, on Nov 4.

    Don’t let this discourage you if you didn’t write a post.

    Start now. Write a post today. Look through the ones I’ve written. Heck, write about the same topic I wrote about. Have you written about defining a FK at table create time? If not, write that post now, reference mine, and show how to do it. Give us a sentence or two on why you would do this.

    Write about using the DAC. Write about PowerBI. that one’s still on my list. Ed has ideas as well, and feel free to use one.

    The idea is to just write. Take some time this weekend, reflect on something you did this week, jot some notes, and write a short piece to showcase your knowledge.

    This is your chance to showcase your knowledge for your next employer, or even your review at the end of the year.

    I know I’ve been inspired, knocking out 5 posts this week, which I’ve scheduled each Thursday. I’ll be late to Ed’s challenge, but that’s OK. I’m continuing to write short pieces about my knowledge. In fact, a few changes to a PoSh script today gave me two posts, looking to specific skills I worked on.

    You can do the same. I look forward to you blogging, and seeing your posts appear in the #SQLNewBlogger hashtag on Twitter.