Category: Blog

  • Differences Between xp_readerrolog and sp_readerrorlog: #SQLNewBlogger

    I was creating a question on sp_readerrorlog and realized that this procedure is different from the one it wraps: xp_readerrorlog. This post digs into a few differences.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    The New System Stored Procedure

    For most of my SQL Server career, it’s been a habit to use xp_readerrorlog to query the log. This was code I learned a lot time ago, and it’s worked in every version of SQL Server. Despite being undocumented, as you can see below:
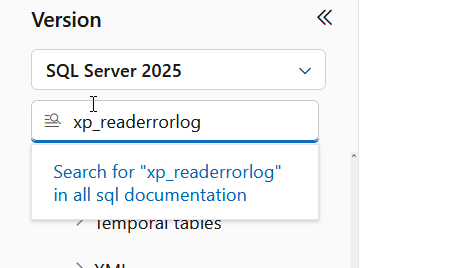
    2026-08_0381

    xp_readerrorlog has been written up by a few people at SQL Server Central, including Nagaraj Venkatesan and Ken Fisher, as well as in some forum posts (one, two). However, it’s not well documented. I usually end up Googling for the parameters as I need them.

    Until now.

    Here are a few differences I’m documenting, so I will hopefully remember them.

    Note: I got a few different results from AI, which were at best incomplete, and sometimes wrong.

    sp_readerrorlog has different permissions. This proc works with anyone that has VIEW SERVER STATE, which is sysadmin, serveradmin, and security admin.  Or with the permission granted.

    xp_readerrlog has extra parameters. Both of them have these parameters:

    1. error log number (0 based)
    2. error log type, 1 – SQL Server, 2 Agent
    3. search value – needs to be NVARCHAR
    4. second search value, NVARCHAR as well

    xp_errorlog adds 5 and 6, and 7.

    1. start time (datetime)
    2. end time (datetime)
    3. sort order (ASC,DESC)

    Those are the main differences I see, and if you want to filter or sort, you need the extended stored procedure, not the wrapper.

    I also learned to be careful of AI, as some of the data wasn’t correct from Google or Claude, so I need to verify what I get back and test how things work.

    SQL New Blogger

    I was investigating something and noticed a difference. This post was about 15 minutes to write, along with some testing of the parameters to verify what worked and what didn’t. That testing will make future posts quicker, as I’ll reuse some code.

    This is a quick example of showing some knowledge, and including the warnings about AI. You can write this post and give someone confidence you’re a good choice for the next person to manage their database servers.

  • A Last Minute Trip to the EU

    My life has some crazy travel stretches for sure. Between speaking, office visits, customer trips, I can be on the road a lot. As it is, I’ve flown across the Atlantic six times this year, and now I’m coming back from a 7th.

    I wasn’t planning on this trip. However, life doesn’t always go as planned and we have to roll with the changes.

    My daughter is heading to Lueven University (KU Leuven) for graduate school. My wife and one of my sons planned to take her and help her get her apartment, bank, etc. set up for school and do a little tourist time. Her other brother decided to go as well, with the plan to leave on 10 Sept and come back the next week.

    I was left out because I have to be in San Diego on Mon, 14 Sept. I have had too many 50 hour trips to other countries, so I was going to stay home.

    However, my wife got injured from a horse and can’t fly. She’s OK, just uncomfortable and flying isn’t an option. We were planning on using her status to take extra clothes, better seats, etc. Without that status, it’s a very expensive trip (or an uncomfortable one). Since we had an award ticket, moving me into her slot (with the same status) works. It also gives the kids someone to lean on.

    So I flew Thur to Brussels, helped get things set, and I’m back home today, making my way to San Diego. The kids were going to Paris today, so they won’t miss me.

    Life in the EU is rough, isn’t it?

    In any case, republished editorial, vacation day taken, and it’s going to be a long day today.

    If you can avoid it, I recommend against 4 days trips to Europe from the US (or the reverse).

  • The Book of Redgate: Hours

    I have said and written this many times: Redgate Software is the type of company I’d want to build if I founded another company. It’s a great place, and one of the things I appreciate is that we value outcomes.

    One of our values is:

    2026-06_0204.

    The text on the next page continues the sentence:

    What you achieve is more important than how long it takes.

    Building software is challenging, and building software that can be sold is difficult. We’ve had lots of successes and some not-successes. However, we work towards building the software and celebrate the achievements.

    However.

    If you’ve built software, you know it usually takes longer than expected and people want it sooner. Many teams know me as the “do it faster” guy. I know software takes time, but I also know that in the business of selling software, we need focus on things that are useful and valued by customers.

    I don’t complain that it takes too long to build everything, but I do press on the focus to get the important things done first, which aren’t always the fun or easy things.

    Ultimately we as a company appreciate when we have something done and working for customers. We don’t go back and lessen the importance of the effort because of the time it took. We do look to see if we can do better in the future, which is something I’d hope most software engineers would do.

    I have a copy of the Book of Redgate from 2010. This was a book we produced internally about the company after 10 years in existence. At that time, I’d been there for about 3 years, and it was interesting to learn a some things about the company. This series of posts looks back at the Book of Redgate 15 years later.

  • PostgreSQL Support in the Data API Builder

    Next week I’m at VS Live in San Diego (register and join me) and one of my talks is on the Data API Builder. I want to show how this gives you REST, GRAPHQL, and MCP access. As a part of the talk, I also wanted to show this working across platforms, so I’m showing this in PostgreSQL as well.

    I’ve been experimenting this in a few ways, but I decided to see how hard it was to add PostgreSQL support. I decided to follow a similar structure as my SQL Server demos, which are all in my GitHub repo.

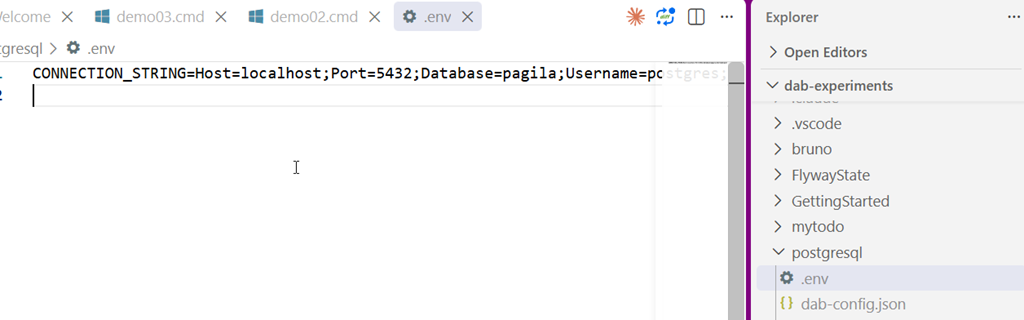
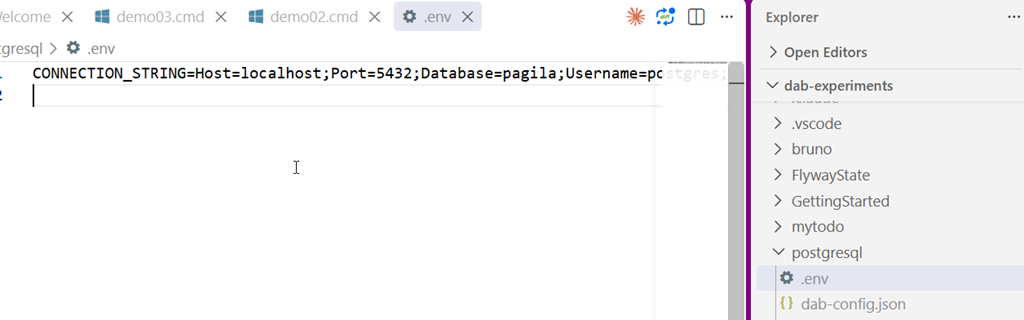
    First, I added a .env file, which has the credentials. THIS IS A DEVELOPMENT structure, and not something you’d deploy from a repo. Secure your production stuff! This is my local file (in .gitignore), but it’s a simple connection string.

    2026-08_0375

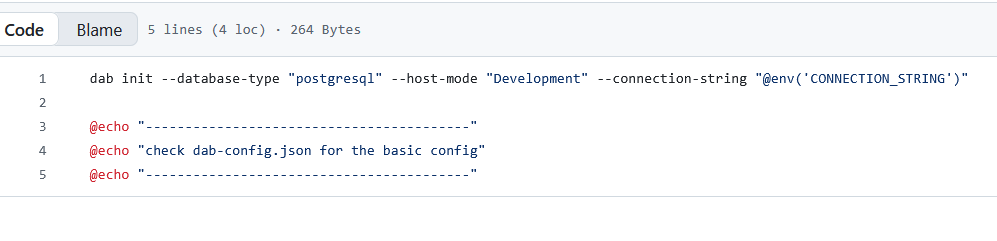
    Next, I copied (well, I guided Claude to do this)  my demo01.cmd and edited it to say the type is “postgresql” instead of SQL Server. The new file went into a separate folder as (demo01.cmd)

    2026-08_0375

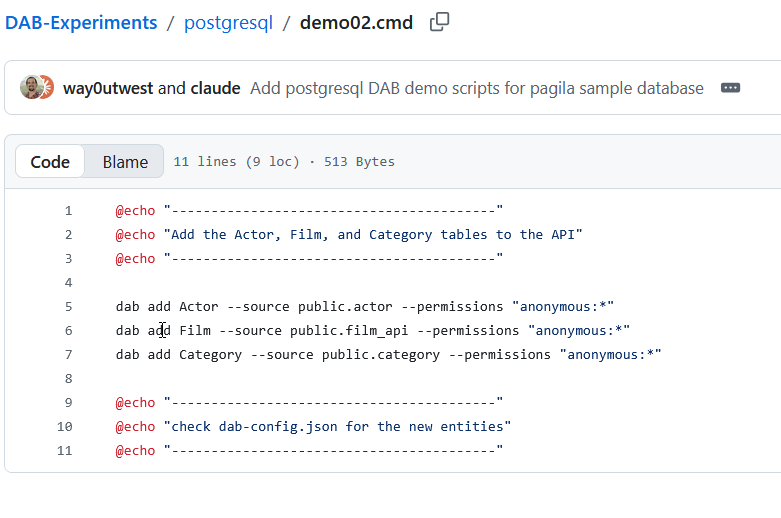
    I had it copy the demo02.cmd and alter this for the PostgreSQL Pagila sample db, which is installed and running on my machine.

    2026-08_0376

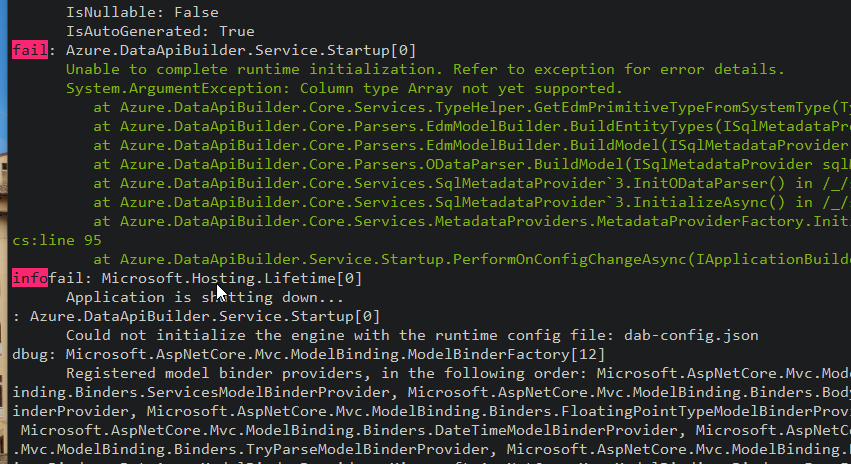
    Note, this errored out at first, with the note that DAB doesn’t support the PostgreSQL array type. I ended up having Claude create a view that skips this column and the column that is a vector type. Hopefully those will be supported soon by DAB.

    2026-08_0373

    Next, dab start, and I had a running API server over my PostgreSQL database in just a few minutes. Here’s my Bruno query of the GraphQL endpoint for Pagila.

    2026-08_0377

    Not enough people are using or trying the Data API Builder. This is truly an easy way to get a usable API over your database without a lot of data access layer work for developers.