Tag: DevOps

  • Encouraging Innovation

    I was working with a client recently and one of the managers said they wanted to encourage innovation inside their organization. That sounded good, but as I thought about it, I wasn’t sure what this means, or if it’s really something that matters. Let’s take a few examples and think about this in a modern organization that builds and operates software.

    If I am a developer, I get a series of requirements or tickets where I have to write code. Perhaps I need to take inputs from a user, query a database, and produce a result. I might write code in C# 7 instead of C#6. Maybe I’d use a lambda instead of creating a new function. Perhaps I decide to ensure I use the stored procedure type with named parameters rather than submitting SQL as a batch. Is that innovative? It might be a better way to write code and improve the quality (or security or maintainability) of the code, but is it innovation?

    Another example. I’m a DBA and I need to run scripts against production. All the DBAs use SSMS, but I decide to change. I store the scripts in a folder and use Flyway to execute them against production with an automated system like Octopus Deploy, which manages the security. Is that innovative or just adopting a more DevOps-y practice?

    Jason Fried says innovation is overrated, which I think is true. At least when that’s an aim or we expect to build something radically different. I know there are sometimes we might come up with something new that our organization hasn’t done, but most of the time work is work. It’s tedious mundane, and it can be very repetitive. That’s why the urge to do and try something new pervades most development organizations.

    I do think that you can regularly innovate in your workplace. You might not create something that’s never been done anywhere in the world, but you might get people in your org to try something new. To adopt a new technique or habit, to create higher quality code with a small change. That’s the type of innovation that I like to see and foster. That’s what DevOps encourages, experimentation and learning. It’s also what I think my examples above show. It’s innovation in this particular space, which hopefully makes work more interesting and enjoyable.

    Steve Jones

    Listen to the podcast at Libsyn, Stitcher, Spotify, or iTunes.
  • Slides and Code for SQL Saturday Jacksonville – Architecting Zero Downtime Deployments

    The code from my talk today at SQL Saturday Jacksonville is available in GitHub in a repo: Zero Downtime

    There is a description in the readme, but you can open the DBClient folder and the VS solution for ZeroDowntime in there in VS 2019 and run it.

    The SQL Code is numbered in order in the SQL folder.

    If you have questions, please feel free to contact me or submit an issue on GitHub. Please feel free to use this presentation at your own employer or usergroup.

  • Flyway Desktop PoC–Adding a Shadow and Baseline Script

    In the last post, I created a baseline marker for Flyway in each database. This set the version in the dev and QA databases to v1. However, I also need a baseline script, at least the tool asks for one, so this is the process if you have objects in your production or other downstream databases.

    I’ll do this for SQL Server and then PostgreSQL.

    Why do this?

    The main reason to create a baseline script is to note which objects already exist in production. For these objects, I don’t want to track these are changes in their current form.

    For example, if I already have a CountryCodes table in production, when I create a project, I want to tell Flyway Desktop that this table exists in production, so if the dev version matches, don’t add this to scripts. If it doesn’t, then I’ve done something in development and need an ALTER script deployed to prod.

    What was the Other Baseline?

    The first baseline in this post, is a version marker. I hate that this is the case, but both Flyway (pre-Redgate) and Flyway Desktop (evolved from SQL Change Automation), had the concept of a baseline, but these were somewhat different things.

    Flyway Baseline – The initial version of the database. Don’t deploy any scripts that are <= to this version.

    Flyway Desktop Baseline – A script that has the structure and code of all objects that exist in the target database(s).

    We can create a baseline script for Flyway, which looks for a B script, but the baseline command expects that you create this script manually. This is used to populate a new database with the baseline migration script prior to running all other scripts.

    Setting up the Baseline Script

    Flyway Desktop makes it easy to create a baseline script, and in fact, prompts you to do so.

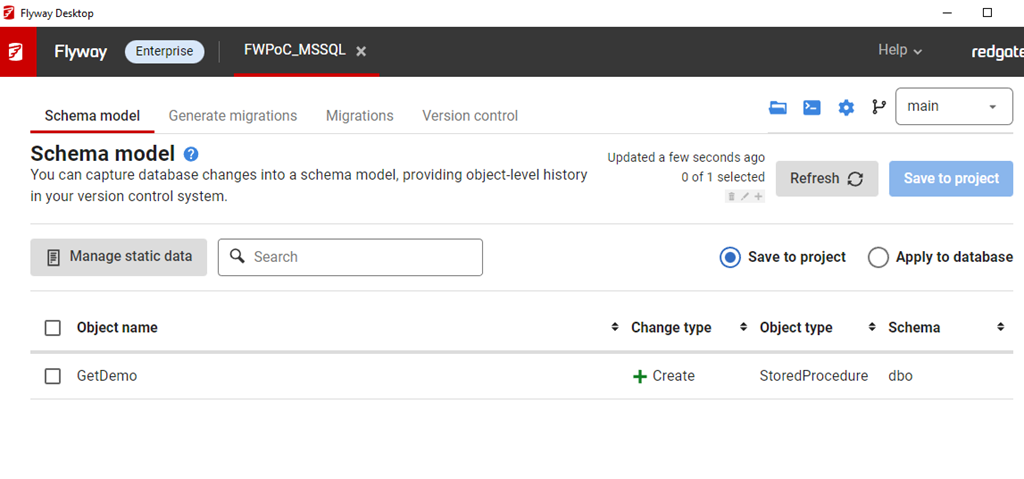
    In my project, if I go to the Schema Model (first) tab, I see there is an object in Development. This was the table I created when I set up the database. The goal is to get this table to other environments.

    2023-04-04 16_10_58-Flyway Desktop

    This table doesn’t exist in QA. I do have the flyway_schema_history table, which was the result of the baseline command.

    2023-04-04 16_15_58-SQLQuery4.sql - ARISTOTLE_SQL2022.FWPoc_1_Dev (ARISTOTLE_Steve (77))_ - Microsof

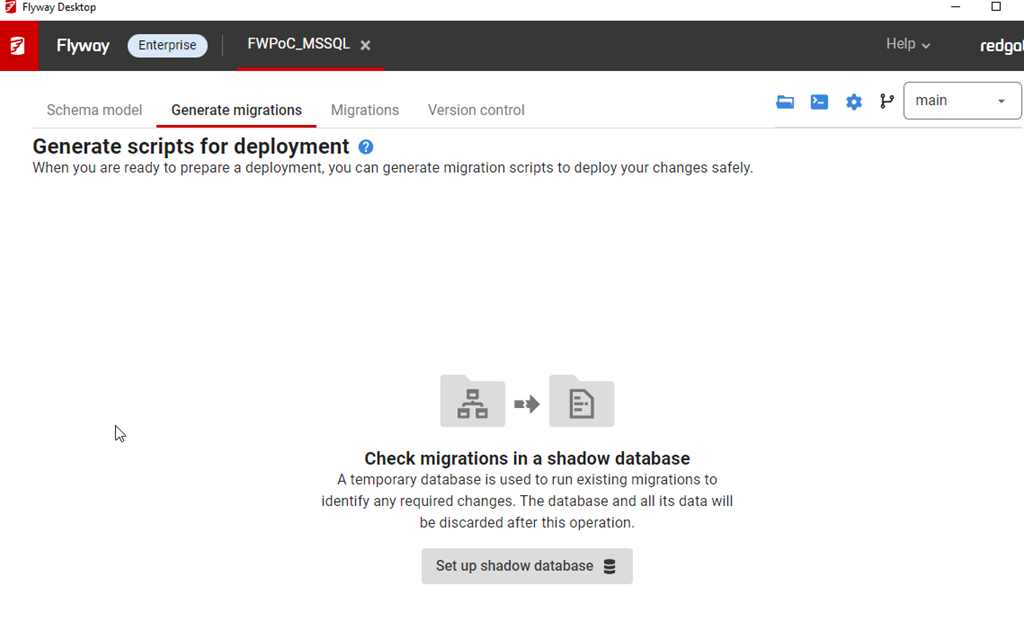
    If I go to the Generate Migrations (second) tab, I see this. The first thing that the tool wants is a Shadow database.

    2023-04-04 16_12_55-Flyway Desktop

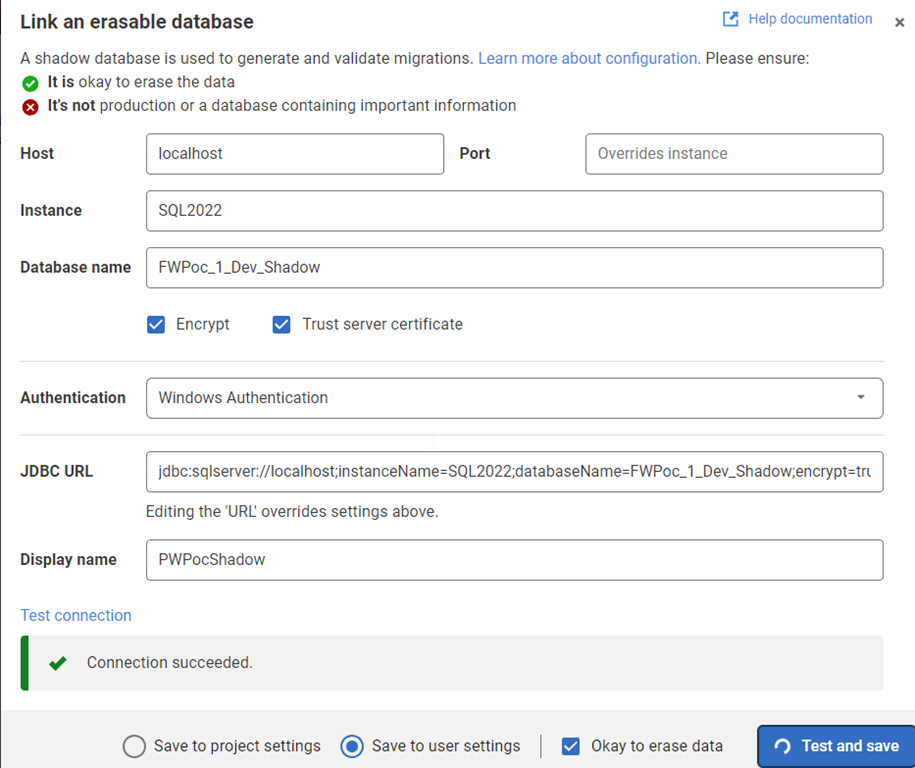
    The shadow is essentially a development V-1 (v minus one) version. This is where I test all migrations, compare the state with development, and then determine what’s changed. This is just a regular database, but I create this outside of Flyway Desktop. For me, I created a database (FWPoc_1_Dev_Shadow) and then clicked Set up shadow database to get this dialog. You can name this anything.

    I enter details, and test the connection before saving this. In general, this ought to be saved to my user settings as I’ll have my own shadow different from other developers. I DO NEED to click the “ok to erase data” box.

    2023-04-04 16_14_09-Flyway Desktop

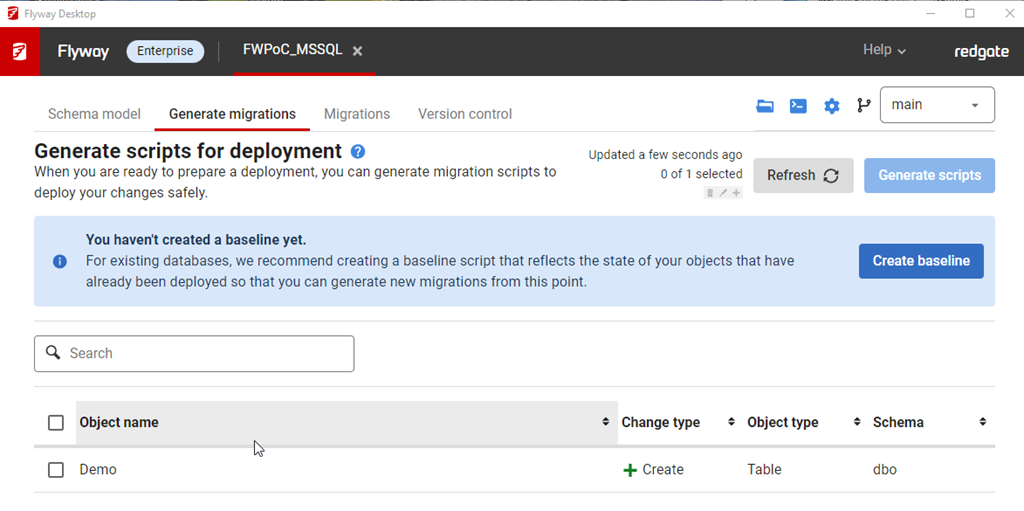
    Once this is done, I now see another prompt on the Generate Migrations tab. Now I need a baseline script. I don’t have anything, but I will click the button.

    2023-04-04 16_14_28-Flyway Desktop

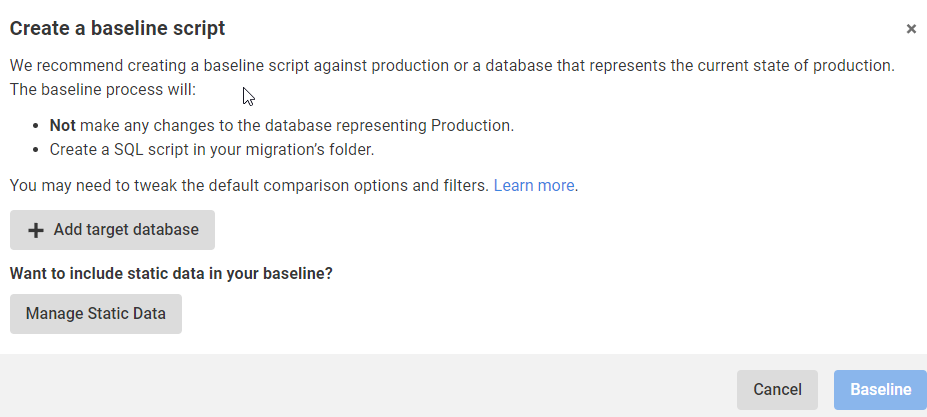
    This gives me a dialog to pick a target database. This target is used to get the initial set of objects to populate in the baseline script. You can use production or a copy (recommended) as the target database.

    2023-04-04 16_14_41-Flyway Desktop

    My QA is the same as prod, so I add that with the proper connection string and then I see the target here for the Baseline. I am ignoring static (or lookup/reference data for now). I’ll click the Baseline button.

    2023-04-04 16_15_25-Flyway Desktop

    This runs and … nothing.

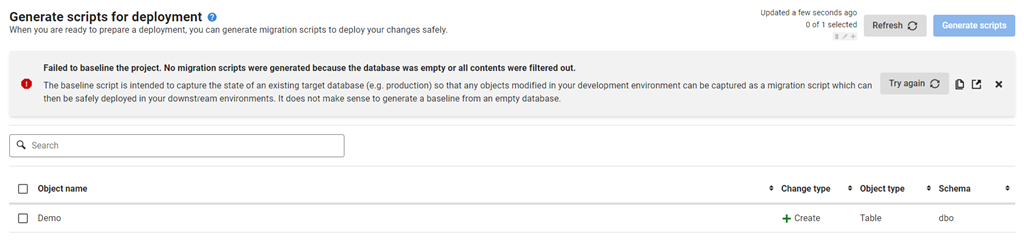
    Which makes sense, as there is nothing in my target database. I actually get an error after this, which tells me that it doesn’t make sense to baseline an empty database.

    2023-04-10 12_38_51-Flyway Desktop

    I wish that were surfaced earlier. In any case, if I close this, I get the same image above, saying I don’t have a baseline. For now, I’ll ignore that.

    Summary

    Not much happened in this post. I added a shadow database, which I’ll use to generate scripts. I tried to baseline, but that errored, as it should. I really don’t need a baseline, so I’ll come back to this later in another format.

    For now, I’ve advanced the SQL Server project. I’ll actually repeat these steps for the PostgreSQL one, but it’s really creating a new database for the shadow and setting a connections string. Everything else looks the same.

    The next post will actually generate a script and deploy this to QA.

  • How Important is Zero Downtime?

    As I work with more and more customers at Redgate, I see some interesting trends. During the pandemic (and prior), we got a lot of questions on zero downtime and how to achieve database DevOps without causing problems. Those are always interesting discussions, and I find many people want magical solutions without having to change the way they work.

    The last year, however, has had more people looking to implement database DevOps and speed up their development, but not a lot of questions or demands for zero downtime during these deployments. I find that interesting as the world depends more and more on computer systems, and the customer base for many organizations may demand access to the systems at any hour of the day or night.

    However, it doesn’t seem that as many people are concerned about small moments of downtime. Does this mean that more organizations aren’t measuring uptime anymore? Perhaps the interruptions caused by software deployments aren’t being counted? Or maybe the application software has gotten better at hiding blips in database access. Perhaps feature flags are catching on as a standard practice, so database deployments are less troublesome.

    I’m not sure what has changed, but it has been noticeable by me that the importance of making changes without downtime has not been a requirement from many customers. Is that the case for many of you reading this? Are you less concerned about downtime? I think one nice thing about the move to the cloud is it’s a little less stable, and perhaps that has lowered some of the expectations of our management. Since it’s out of our control, maybe we shouldn’t be too concerned about the need for retries, either automatic or a customer pressing a button again.

    Let us know today if you feel pressure to get closer to zero downtime, either in your everyday management of databases or during deployments. Or maybe tell us if you’ve gotten so good at your job that no one every notices when you do make changes.

    Steve Jones