Tag: sql server

  • A Really Bad Day

    I was out of town for work one day, literally on the other side of the country, in a car bound for the remote office when my cell phone rang. I had flown into LaGuardia Airport in New York City and needed to drive to Connecticut, to an office just outside of Hartford. The company was paying, and it was more convenient for me to fly into NYC and then take a chartered car to CT.

    I glance at caller ID and it’s a client of mine back in Boulder, CO who I do some occasional SQL Server work for. I answer, thinking that he needs help with some SQL command and I can score some brownie points here without charging him.

    “Steve, I have a problem”

    The words that anyone in technology is loath to hear. Even if you’re being paid by the hour, clients that cause issues are often going to be more trouble than the payment is sometimes worth. I much prefer to hear “Steve, we’d like to do x. How can we do that?”

    I ask him to tell me what’s wrong and he said that RAID card was throwing errors on the development server, so he performed a SQL Server backup, copied the backup to a file server and then replaced the RAID card, rebuilding the array. When he went to restore the server, he got an error.

    I am the backup and restore champ, at least of my little world. “Read me the error, “ I say, confident I can solve this for him before we arrive at the office..

    “The media set has 2 media families but only one are provided”

    Uh, oh, I’m thinking, and not because of the poor grammar. This is not good and I’m not going to be able to fix this. Breaking bad news to a client is never fun, even if it’s not your fault. I’ve lost a couple because they were so upset they let me go at some bad news. That’s actually OK with me because if they can’t tell the difference, they are likely to leave me when I least expect it anyway and I’d rather know sooner than later.

    I explain that he must have used two backup files and he needs to add the second one in there. The guy is insistent that he didn’t pick two files when he made the backup and he copied the right one off. He even included the date in the filename (like I showed him) and reads it back to me.

    I know what’s happened. He’s made an inadvertent striped backup, and since the RAID array was blown away, he’s likely lost the other file. I try to keep from laughing as I explain patiently what happened. He’s upset, then he’s confused, then he’s unhappy. I can picture the sad panda face on him from 2,000 miles away as he realizes that he’s not getting this restore to work. The driver must hear it in my voice as well since he’s smirking in the rear view mirror.

    To add misery here, he wasn’t copying backups off this development server to save space on the file servers. He’s lost a few weeks of work now, and he has to break the news to the developers, who likely don’t have backups of their own.

    I sign off, not sure what to do as I get to my destination. It’s a good example of why SQL Server still needs a DBA, or someone with decent DBA skills. Despite the ease with which you can get many things done, not understanding why you do them cause big problems.
  • Jobs for Data Scientists

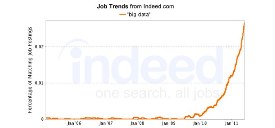
    This is the trend line we like to see for database jobs

    I wrote about data scientists while back, which seems to be a field that involves the analysis of large amounts of data and the tools involved in this work. The definition of this area is a little nebulous, but that hasn’t stopped companies from looking for people to work in this area. There are jobs for data scientists, and perhaps for interesting, there seems to be more and more jobs for people to work with “big data”.

    This article shows a huge trend up in the “big data” keywords in job listings. That makes sense as I think the data growth has far outpaced the ability of tools to work with large datasets. Excel had a problem with large amounts of data until recently, and most of the other tools used are either very expensive or home grown.

    Many of the people subscribing to this newsletter are technical people, those that work to form the computer into a tool that someone else can use to do their job. It’s an interesting job, and one I hope you enjoy, but there are some of you out there that would like to do more with data than just find ways to help others query that data. Perhaps a data scientist is a job that you would like to move into at some point.

    This is an area that I suspect many companies will want to focus more efforts on in the future, and I think that being a DBA who knows how to query data and find patterns gives you a head start on moving into a position that can be challenging, fun, and perhaps most importantly, without much after hours work.

    If you like statistics, patterns, and helping your company actually make use of the information in data, perhaps a data scientist might be the position for you.

    Steve Jones


    The Voice of the DBA Podcasts

  • When Did That Restore Finish?

    I saw this question come across Twitter under the #sqlhelp tag one day and was wondering myself. Someone suggested the default trace, I was thinking msdb.dbo.restorehistory and decided to check.

    First I hit Books Online. It notes that the restore_date column means: Date and time of the restore operation. Can be NULL.

    Very helpful (hopefully you read the sarcasm). This looks like a CS 101 comment, not very helpful and not detailed. Here’s a Connect item for more detail, and here’s one I submitted for clarification.

    OK, time for testing. I first grabbed a copy of AdventureWorks since I assumed it would take at least a minute to restore. I restored a new database as “ADW_3”. It was around a minute and so I checked restorehistory:

    USE msdb
    GO
    SELECT TOP 10 * FROM restorehistory

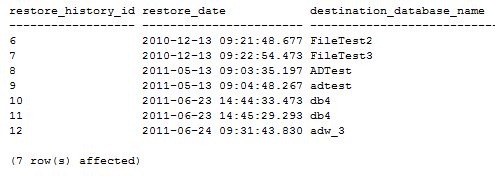
    And I got this:

    restore2

    This was not terribly helpful. At the time I ran this, it was 9:32, so this appears to be the start date/time of the restore.

    Then I checked the default trace: ‘

    SELECT * FROM ::fn_trace_getinfo(0)
    
    SELECT *
    FROM ::fn_trace_gettable('C:\Program Files\Microsoft SQL Server\MSSQL10.MSSQLSERVER\MSSQL\Log\log_54.trc',0)
         INNER JOIN sys.trace_events e
              ON eventclass = trace_event_id
         INNER JOIN sys.trace_categories AS cat
              ON e.category_id = cat.category_id
    WHERE databasename = 'ADW_3'

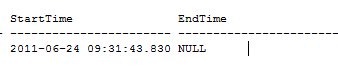
    The first query gets the name of the file, which is put into the second query as the file source and that returned a number of results, of which the interesting ones were:

    restore

    That isn’t terribly helpful either. I was hoping there would be a second event in the default trace, but there isn’t, even 10 minutes later when I checked. (I’m ever optimistic)

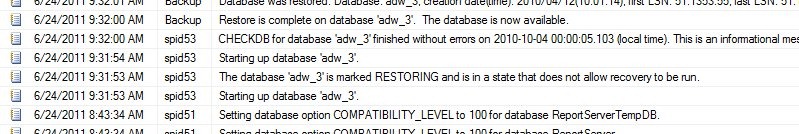
    Then I thought “wouldn’t recovery run in a restored database? Isn’t that in the error log?”, so I decided to check there and found this:

    restore3

    The “starting up datbaase ‘adw_3’ is likely just after the log file is built and corresponds to a tenth of a second after the restore starts. I suspect the files are created first as part of the restore, but not marked in the error log. Then the database is started, and is marked a “restoring” immediately after.

    There is a checkdb informational message, which is the last time that the command was run not on this database, but on the source database that created the backup file (bad, Steve, bad, 8 months old!).

    Last we see that just about 6sec later there is the completed restore message.

    No duration, but you can calculate that based on the “starting up” message.

  • Time for a ROWID?

    Do we need a ROWID structure in all SQL Server tables?

    One of the things I’ve been doing lately is looking forward to future versions of SQL Server. Not SQL 11/Denali, which has CTP 3 out now, but more towards the future. SQL 12 and beyond, and wondering how the platform can advance and incorporate new ideas and knowledge from other areas such as NoSQL or NewSQL. I also have been trying to decide which parts of SQL Server could be improved to be more robust of scalable, or address some failings in the platform.

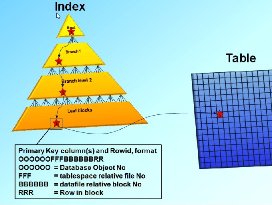
    Our systems seem to be growing larger, and storage seems to cost less all the time. While this doesn’t always result in cost savings, it does mean that we may be ready to increase the page size in SQL Server once again, perhaps growing to 16k or even 64k. If that follows as I/O transfer sizes grow, then is it time to add in a rowid marker of some sort that gives us a unique handle to every row on a page?

    I know this adds some overhead, and in reading about the internals of current pages, that overhead can be significant. However it seems that I find people that regularly have non-unique clustered indexes, or heaps, and could require SQL Server to differentiate the rows internally. With our busses increasing in size and larger sectors on disks, perhaps the overhead isn’t out of the question.

    This would allow for some interesting benefits for replication, with the possibility that any object could be replicated, no matter what the structure. It also might allow us to very efficiently eliminate duplicates and perhaps improve the efficiency of some T-SQL commands.

    What do you think? Is it time for a true ROWID? Time to increase the page size for SQL Server?

    Steve Jones


    The Voice of the DBA Podcasts