Tag: T-SQL

  • T-SQL Tuesday #143 – Short Code

    T-SQL-Tuesday-LogoI’m late, but I wanted to get this out. I started the post, then got distracted with travel to Europe late last week.

    In any case, this month the host for T-SQL Tuesday is John McCormack, with his invite to write about short code examples. It’s a good technical invite, and one that immediately got me thinking about things I do often.

    If you haven’t ever tried a T-SQL Tuesday, set up a blog and put out a post on the topic, this week or whenever you read this.

    Snippets

    I work for Redgate Software, though I’d likely be using SQL Prompt no matter what. I was never thrilled with native intellisense, but SQL Prompt has been great. One of the things I like most about Prompt are the snippets, which let me insert code with a few keystrokes.

    Here’s a quick example. If I type “” in SSMS, I see this:

    2021-10-13 10_52_32-CandidateList

    Prompt detects this as a snippet first, then has other matches. I can hit Tab, and I’ll get this:

    2021-10-13 10_52_46-CandidateList

    I get a quick “top 10” from a table. Often I use SELET * for a quick look at the shape of data.

    However, I can add custom snippets, and one I use often is this:

    WITH myTally(n)
    AS
    (SELECT n = ROW_NUMBER() OVER (ORDER BY (SELECT null))
      FROM (VALUES (1), (2), (3), (4), (5), (6), (7), (8), (9), (10)) a(n)
       CROSS JOIN (VALUES (1), (2), (3), (4), (5), (6), (7), (8), (9), (10)) b(n)
    )
    SELECT *
    FROM myTally

    This is my “tt” snippet, so I can type “tt<Tab> and get this code for a tally table. This s handy in many string manipulation and problem solving situations.

    If I need more than 100 rows, I can easily copy the cross join line, add a new alias, and I have 1000 rows with this:

    WITH myTally(n)
    AS
    (SELECT n = ROW_NUMBER() OVER (ORDER BY (SELECT null))
      FROM (VALUES (1), (2), (3), (4), (5), (6), (7), (8), (9), (10)) a(n)
       CROSS JOIN (VALUES (1), (2), (3), (4), (5), (6), (7), (8), (9), (10)) b(n)
       CROSS JOIN (VALUES (1), (2), (3), (4), (5), (6), (7), (8), (9), (10)) c(n)
    )
    SELECT *
    FROM myTally

    Short, but effective code.

  • Using NULLIF–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    I ran across the NULLIF() function recently, and I realized I’d never used it in code. It’s an interesting function, one that I didn’t think would be useful, but I found a couple places.

    NULLIF Behavior

    This function is essentially short for “return a null if these two values are equal.” There are two parameters you pass in and if they are equal, you get a NULL back. Somewhat strange function, but here are a few examples:

    2021-09-20 15_42_19-SQLQuery2.sql - ARISTOTLE_SQL2017.sandbox (ARISTOTLE_Steve (62))_ - Microsoft SQ

    The interesting one is that 1 and NULL come back with the first value. We can’t determine if NULL is equal to 1, so we assume not.

    Using This Function

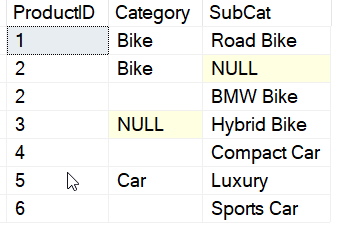
    When would you use this? As I said, I have never thought to use this, but I did find a couple interesting items. A mixture of NULL and a certain value is one place, if you can use the NULL. For example, let’s say I have some data in a table:

    2021-09-20 15_44_46-SQLQuery2.sql - ARISTOTLE_SQL2017.sandbox (ARISTOTLE_Steve (62))_ - Microsoft SQ

    I have some blanks and some NULL values. Suppose I want to query and show the category, but if that is a NULL or blank string, show the SubCat instead. I can do this with a CASE, but that get’s ugly. NULLIF makes this easy to read.

    2021-09-20 15_45_56-SQLQuery2.sql - ARISTOTLE_SQL2017.sandbox (ARISTOTLE_Steve (62))_ - Microsoft SQ

    The other interesting place I thought of here was with aggregates and potentially filtering out some values. Aggregates tend to ignore NULL, so what if I have this data:

    2021-09-20 15_48_24-SQLQuery2.sql - ARISTOTLE_SQL2017.sandbox (ARISTOTLE_Steve (62))_ - Microsoft SQ

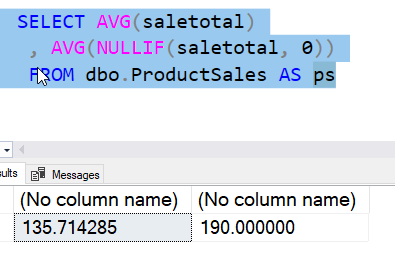
    Suppose I want the average sale, but not with the zero values. Those might be returns, and we don’t want to skew our average. I could use NULLIF to make this easy to code. Notice the short code below and the difference from the straight average:

    2021-09-20 15_49_03-SQLQuery2.sql - ARISTOTLE_SQL2017.sandbox (ARISTOTLE_Steve (62))_ - Microsoft SQ

    I could use CASE, but which is easier to read?

    2021-09-20 15_50_20-SQLQuery2.sql - ARISTOTLE_SQL2017.sandbox (ARISTOTLE_Steve (62))_ - Microsoft SQ

    I think NULLIF is, if you know how the function works.

    SQLNewBlogger

    This was a function I stumbled on and wasn’t sure how to read. I spent about 10-15 minutes searching around the Internet looking for a reason to use this code. I saved the link for them and added it into the post. I spent about 10 minutes creating a little code example and then running it.

    I then wrote this post, which was about 10 minutes, mostly because I used screen shots for code, which were quick to grab and paste in.

    This is a nice example of learning something, understanding how it works, and then thinking where it could be useful.

  • To Inifinity and Beyond With 1=1

    There is one thing that Aaron Bertrand won’t get mad at me for doing and that’s creating an infinite loop with a WHILE (1=1) pattern. He wrote about this recently in a tip, noting that it’s easy to create an infinite loop with code like this, something that never ends well.

    I have purposefully written infinite loops in the past. A long, long time ago Radio Shack would put out TRS-80s on display, and a few of us would type a quick BASIC program to perform some math work on the screen over and over with an infinite loop. It crashed at some point with an overflow, but for a period of time, it would look neat on the screen. Less neat to the salespeople who weren’t always sure how to stop it and demonstrate something else without resetting the machine.

    I’ve also created infinite loops by accident at various jobs. Those experiences have left me a little concerned about any loop that doesn’t have a defined time to end. I usually use a technique similar to Aaron, ensuring the loop ends. If needed, I add a call that can repeat the entire process if more data needs to be updated after the current loop ends.

    There are plenty of people who spotted the error in the code and think they wouldn’t create that problem in their looping code. However, I think few of us work alone on code for an employer, across time. Often someone else comes in to refactor or “improve” our code. The next person that adjusts this loop might join back to the main table and not realize they are creating an infinite loop. You’d hope they’d test this and find the problem, but I continue to see lots of “little fixes” deployed without being tested.

    This is one reason I want a DevOps style process for database code, complete with automated testing. If you write a piece of code, you are responsible for including a test in the pull request so that the CI system can verify your code passes the test. This isn’t a perfect system and it might not prevent all bugs, but at least a test will exist and someone can then check both the code and test and perhaps use the issue as a teaching moment.

    We try and avoid loops in SQL Server, but that isn’t always possible. As with most techniques in programming, we should strive to learn the best ways to use them, know the weaknesses, and avoid building code that has major flaws now. Maybe we also ought to add that we should ensure our code doesn’t lead less experienced developers in the future to make simple mistakes. I’d say the 1=1 looping code does this, and I agree with Aaron; it should be avoided.

    Steve Jones

    Listen to the podcast at Libsyn, Stitcher, Spotify, or iTunes.

  • Delaying Code Execution with Waitfor–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    One of the rarely used commands for me is the WAITFOR command. This is a command that intentionally introduces a delay in the execution of your code. I sometimes use this when I need to pause code for a brief time, but I never remember how this structure works.

    Hopefully this quick post helps me remember this in the future.

    WAITFOR

    This command does what it says; it waits for something. You have two choices here in what to wait for: a period of time or a specific time. The structure of the command is:

    waitfor <type> <time>

    The type can be either of the keywords TIME or DELAY. I often use DELAY, which is a period of time to wait for. When you use TIME, the execution stops until that specific time of day.

    As an example, if I want to pause code for 5 seconds, I use this:

    WAITFOR DELAY ‘00:00:05’

    If I run this in SSMS or ADS, the query time for this will be 5 seconds. The default is ‘hh:mm’, so remember that if you want seconds, you need to include the hours and minutes.

    For time, the parameter is a datetime format, so enter this as the time you would want to start code execution again.

    Practical Usage

    The main place I used this recently was in this code:

    EXEC msdb.dbo.sp_start_job @job_name = ‘Second Job with Two Errors’, @step_name=’Fourth Step’
    WAITFOR DELAY ’00:00:02′

    I was testing some job tracking, and needed a job that failed. It usually runs in less than a second, but without the delay, sometimes the failure isn’t picked up from the job history table.

    This is the type of place, often in testing or in some dependent process, where I want a delay.


    SQLNewBlogger

    This post too my about 10 minutes to write. I couldn’t remember how WAITFOR works, but SQL Prompt helped. As I worked through my testing, I stopped and took 10 minutes to write this up.

    You can do the same thing. Show your example, and how you use it. Be creative and impress someone who might read your blog before they interview you.