Tag: T-SQL

  • 2018 Advent of Code–Day 1

    I enjoy when the Avent of Code comes around each year. I seem to make this a December (or sometimes New Year’s) resolution to get through them all, but life usually gets in the way. In any case, I decided to at least start this year and see how far I get.

    Day 1 – First Puzzle

    This is a simple one, and one that seems to lend itself to T-SQL. We have an input file that looks like:

    +11

    +9

    -10

    -5

    etc.

    This asks us to walk through the file, summing the values together and getting a new value. So the first row ends with 11. The next ends with 20 (11+9). The next is 10 (20-10), and so on. This feels like a simple calc, so let’s get it.

    I wanted to load this with BULK LOAD, so I started with a table:

    CREATE TABLE Day1(rawdata VARCHAR(20))

    I know I’ll need to change this, but let’s make this easy. I use this command to now load my data.

    BULK INSERT dbo.Day1 FROM 'C:\Users\way0u\Source\Repos\AdventofCode\2018\Day1\input.txt'

    Once this is done, I’ll move on. Since I need to get this into some numeric values (this is a math problem), I’ll make another table.

    CREATE TABLE Day1_a(frequency INT)

    Now I move the data.

    INSERT dbo.Day1_a
    (
         frequency
    )
    SELECT CAST(rawdata AS int)
    FROM dbo.Day1
    GO

    That seems to work fine. How do I get the end result? Well, addition doesn’t matter here, so I can do this:

    SELECT SUM(frequency) FROM dbo.Day1_a
    GO

    I get an answer, plug it in, and viola, I’m right. That feels good.

    Day 1 – Second Puzzle

    This one is a little harder. I’m supposed to find out the first time that the end result repeats it’s value. The test cases show this working as follows:

    Value    New result

    0       0
    1       1
    -1      0

    If I walk through this, the 0 repeats. The other test cases show this, but with the large input set, I need to change a few things.

    1. I need to preserve ordering
    2. I need to process this row by row.

    The second item doesn’t mean that I’m looping necessarily, but I need to calculate out the sums as I go and potentially repeat the list.

    To get started, let me modify my Bulk Insert and table to keep the ordering. I created this table.

    CREATE TABLE Day1b(datakey INT IDENTITY(1,1), rawdata VARCHAR(20))

    I then ran BULK INSERT. I got this error:

    2018-12-03 15_24_00-SQLQuery5.sql - dkrSpectre_SQL2017.sandbox (DKRSPECTRE_way0u (53))_ - Microsoft

    I tried a number of items, but nothing really worked. This was a very, very annoying error, and the main solution I saw on Stack Overflow was to add a column to the input file, which I don’t want to do. I initially thought this was a problem with the encoding, but it’s really the identity.

    The best solution was a lower down answer, which was to create a view without the identity.

    CREATE VIEW vDay1b
    AS
    SELECT rawdata
      FROM dbo.Day1b
    GO

    If I run the BULK INSERT to this view, it works fine.

    OK. We’re moving and I have the data in order. Let’s move it to get the integer results we need.

    CREATE TABLE Day1_2
    ( n INT, frequency INT)
    GO
    INSERT Day1_2
      SELECT datakey,
             CAST(rawdata AS INT)
       FROM dbo.Day1b

    If I run a quick query that does a SUM() OVER(), I get a series of results. I can see there are no duplicates here.
    2018-12-03 15_32_29-SQLQuery5.sql - dkrSpectre_SQL2017.sandbox (DKRSPECTRE_way0u (53))_ - Microsoft

    OK, this means I need to repeat the data. I can re-insert data into the table, but that feels inefficient. I ought to be able to group data together.

    Let’s do this by selecting the data as a group, but adding a value to it. I can do that with a cross join. Here’s a short example that illustrates this. Suppose I have a table with the values “Broncos”, “Chiefs”, “Raiders”, “Chargers”, I get select data like this in groups.

    2018-12-03 15_36_36-SQLQuery5.sql - dkrSpectre_SQL2017.sandbox (DKRSPECTRE_way0u (53))_ - Microsoft

    With that in mind, let’s create a tally table and start to duplicate data. I have no idea how many times, but having done the Advent of Code before, I’m guessing 5 groups isn’t enough. Let’s start with 100 repeats.

    One note, I do need to start with 0, so we’ll use a UNION to add the 0 row. We don’t want the 0 row repeated, so we don’t add that to the table.

  • Restarting a Sequence–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    As part of my experiments with the sequence object, I wanted to see what allows me to restart a sequence at a new value. This is useful in a few situations, some of which I want to see in this post.

    Starting Over

    One common scenario might be where I create a sequence and test it a few times, but don’t want those values lost. For example, Suppose I create this sequence and test it a few times.

    CREATE SEQUENCE Counters.TopTen
    START WITH 1
    MAXVALUE 10
    CYCLE
    GO
    SELECT NEXT VALUE FOR Counters.TopTen
    GO
    SELECT NEXT VALUE FOR Counters.TopTen
    GO

    I don’t want the first two values to be removed from the sequence. Instead, I want to get the next number back to 1. I could run 8 more SELECTs to allow the sequence to cycle, but if you’re like me, you’ll end up executing this one too many times and then have to repeat the experience.

    Instead, I can use the ALTER command to fix this.

    ALTER SEQUENCE counters.TopTen RESTART WITH 1

    Of course, I’ll test this with a SELECT, but once I am confident this behaves as expected, I’ll re-run the ALTER again.

    Going Backwards

    One common situation might be a case where an application requests a number of sequence numbers for a situation, but they never get inserted. Suppose I set up an insert statement to load some data in a table, but a key error or some other problem prevents the inserts. I don’t want those values to be lost, so I want to restart numbering.

    As an example, I find that one of my sequences has the value, 41.

    2018-12-05 15_49_08-sequences.sql - dkrSpectre_SQL2017.sandbox (DKRSPECTRE_way0u (65))_ - Microsoft

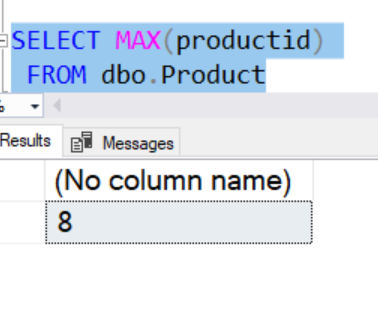
    However, this is because a load of new products failed. The last number used in the table was 8.

    2018-12-05 15_49_29-sequences.sql - dkrSpectre_SQL2017.sandbox (DKRSPECTRE_way0u (65))_ - Microsoft

    In this case, I want to reset the sequence object to 9, so let’s do that.

    ALTER SEQUENCE Counters.Products RESTART WITH 9

    Now I can proceed on loading products into this table, using the sequence object to get the next value.

    SQLNewBlogger

    This was a continuation of a series of posts on the sequence object. As I continued to experiments, I captured the code and some images to use in posts, writing this up as I had time.

    For this post, I took about 10 minutes of experimenting and then another 5-10 trying to sort out some of the experiments into an area. This writeup was about 10 more minutes.

  • The Default Frame for Window Functions

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    This bites me constantly, and I was reminded of this while watching Kathi talk at #SQLintheCity. When you write a Window function, there is an implicit default frame for the windows that you might not be aware of.

    For example, if I have this data:

    create table WindowDemo

    ( groupid int,

    letterid int

    , letter varchar(10))

    GO

    insert WindowDemo

    values

    ( 1, 1, 'A')

    , ( 1, 2, 'B')

    , ( 1, 3, 'C')

    , ( 2, 4, 'D')

    , ( 2, 5, 'E')

    GO

    and I run this code:

    select groupid
    , letterid
    , last_value(letter) over (partition by groupid order by letterid)
    from WindowDemo

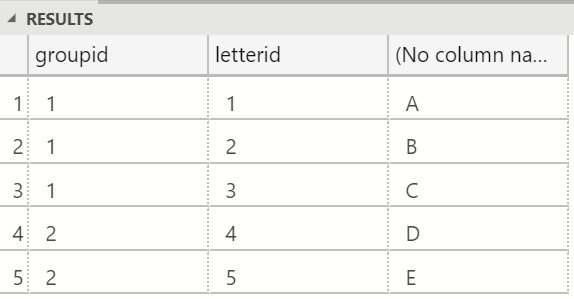
    I get this:

    2018-12-12 15_29_02-● SQLQuery3 - Azure Data Studio

    Not what I expected. I would think the last value for each groupid is the largest letter. Instead,  I have a running total of sorts.

    The Default Framing

    There is a framing clause that I can use after the ORDER BY in the OVER clause. The default frame is RANGE UNBOUNDED PRECEDING AND CURRENT ROW. At least, this is what appears when you include an ORDER BY clause. Many of us do this, but still get confused with the LAST_VALUE() and FIRST_VALUE functions.

    What I really want is a complete set of data, which is either starting from the current row to the end, or  includes all values. If I modify my framing clause, I’ll get what I expect.

    select groupid

    , letterid

    , last_value(letter) over (partition by groupid order by letterid rows between unbounded preceding and unbounded following)

    from WindowDemo

    This gives me:

    2018-12-12 15_36_36-● SQLQuery3 - Azure Data Studio

    That’s what I’d expect for a LAST_VALUE().

    SQLNewBlogger

    This has bitten me a few times, so I decided to write about it. I can show that I solved this issue, which is what my next boss wants to see. The other side effect is that blogging helps me remember how this works.

    This took about 15 minutes, mostly to reproduce the demo that was similar to my issue, but simpler to explain.

  • Basic Sequences–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    I haven’t used sequences much in my work, but I ran into a question recently on how they work, so I decided to play with them a bit.

    Sequences are an object in SQL Server, much like  a table or function. They have a schema, and are numeric values. In fact, the default is a bigint, which I think is both good, and very interesting. Since this will implicitly cast down to an int or other value, that’s good.

    The sequence is created like this:

    CREATE SEQUENCE dbo.SingleIncrement
      AS INT
      START WITH 1
      INCREMENT BY 1;
    GO

    These can be similar to identity values, and in fact, if I make 5 calls to this object, I’ll get the numbers 1-5 returned. Here I’ve made one call.

    2018-12-04 13_19_48-SQLQuery6.sql - dkrSpectre_SQL2017.sandbox (DKRSPECTRE_way0u (55))_ - Microsoft

    This is interesting, as the NEXT VALUE FOR is what accesses the sequence and returns values. I can use this in some interesting ways. For example, if I have to insert values into a table, I can do this:

    CREATE TABLE SequenceTest
    ( SequenceTestKey INT IDENTITY(1,1)
    , SequenceValue INT
    , SomeChar VARCHAR(10)
    )
    GO
    INSERT dbo.SequenceTest
    (
         SequenceValue,
         SomeChar
    )
    VALUES
       (NEXT VALUE FOR dbo.SingleIncrement, 'AAAA')
    , (NEXT VALUE FOR dbo.SingleIncrement, 'BBBB')
    , (NEXT VALUE FOR dbo.SingleIncrement, 'CCCC')
    , (NEXT VALUE FOR dbo.SingleIncrement, 'DDDD')
    , (NEXT VALUE FOR dbo.SingleIncrement, 'EEEE')

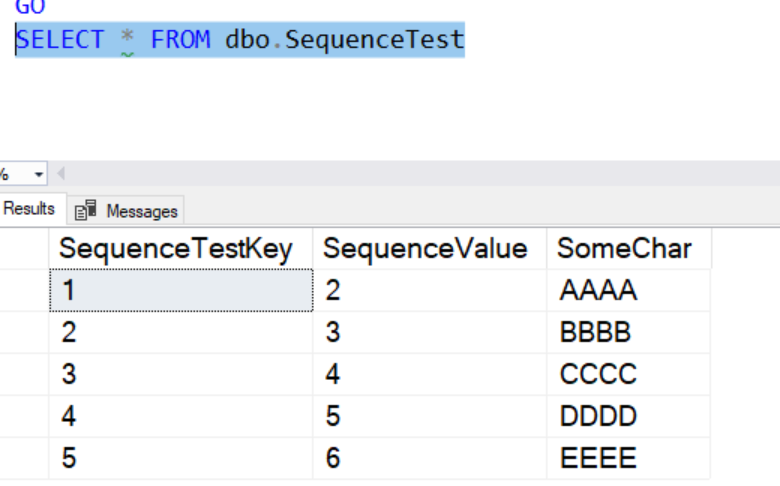
    When I query the table, I see:

    2018-12-04 13_22_50-SQLQuery6.sql - dkrSpectre_SQL2017.sandbox (DKRSPECTRE_way0u (55))_ - Microsoft

    Notice that the sequence number is off by one from the identity. This because I first accessed the sequence above.

    The sequence is independent of a table or columns, unlike the identity. this means, I can keep the sequence numbers going between tables. For example, let’s create another table.

    CREATE TABLE dbo.NewSequenceTest
    ( NewSequenceKey INT IDENTITY(1,1)
    , SequenceValue INT
    , SomeChar VARCHAR(10)
    )
    GO

    Now, we can run some inserts to both tables and see what we get.

    INSERT dbo.NewSequenceTest VALUES (NEXT VALUE FOR dbo.SingleIncrement, 'FFFF')
    INSERT dbo.SequenceTest    VALUES  (NEXT VALUE FOR dbo.SingleIncrement, 'GGGG')
    INSERT dbo.NewSequenceTest VALUES (NEXT VALUE FOR dbo.SingleIncrement, 'HHHH')
    INSERT dbo.SequenceTest    VALUES  (NEXT VALUE FOR dbo.SingleIncrement, 'IIII')
    INSERT dbo.NewSequenceTest VALUES (NEXT VALUE FOR dbo.SingleIncrement, 'JJJJ')

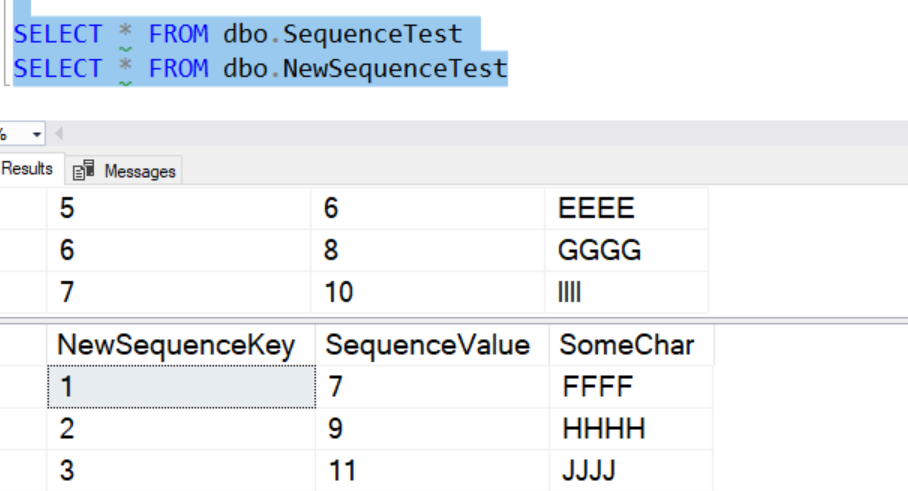
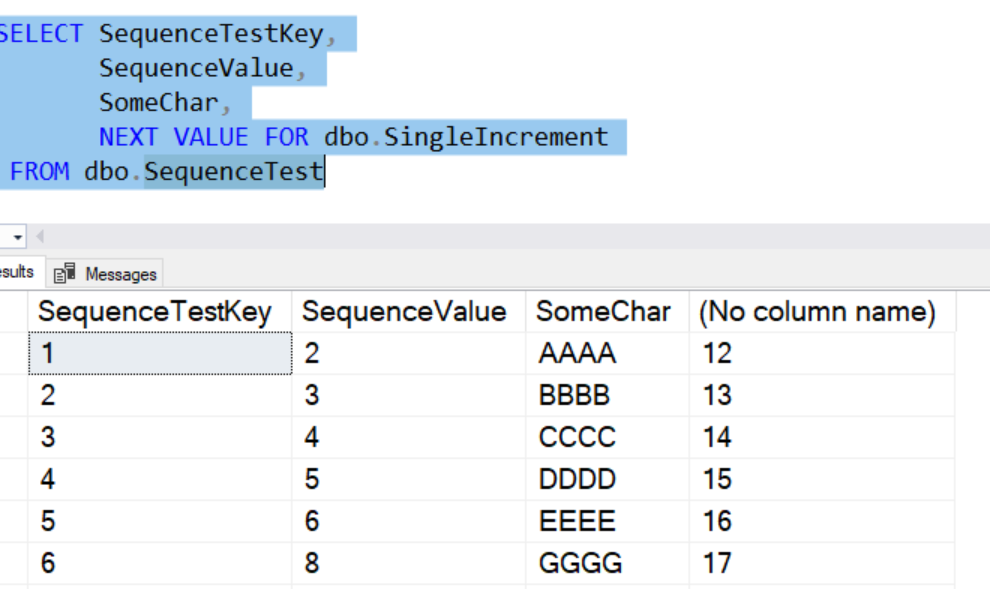
    After running the inserts, I’ll look at both tables. Notice that the values for the sequence are interleaved between the tables. The first insert to the new table has the value, 7, which is the next value for the sequence after running the inserts for the first table.

    2018-12-04 13_27_14-SQLQuery6.sql - dkrSpectre_SQL2017.sandbox (DKRSPECTRE_way0u (55))_ - Microsoft

    In these tests, I’ve used 11 values so far. I can continue to use values, not just for inserts, but elsewhere.

    2018-12-04 13_34_02-SQLQuery6.sql - dkrSpectre_SQL2017.sandbox (DKRSPECTRE_way0u (55))_ - Microsoft

    This behavior is both fun, handy, and useful, but also dangerous. These values get used when I query them, whether the inserts work or not. Here’s a short test to look at this:

    ALTER TABLE dbo.SequenceTest ADD CONSTRAINT SequencePK PRIMARY KEY (SequenceTestKey)
    SELECT NEXT VALUE FOR SingleIncrement
    SET IDENTITY_INSERT dbo.SequenceTest ON
    INSERT dbo.SequenceTest VALUES (NEXT VALUE FOR SingleIncrement, 'ZZZZ')
    SET IDENTITY_INSERT dbo.SequenceTest OFF
    SELECT NEXT VALUE FOR SingleIncrement

    This gives me an error:

    2018-12-04 13_36_52-SQLQuery6.sql - dkrSpectre_SQL2017.sandbox (DKRSPECTRE_way0u (55))_ - Microsoft

    and I can see the last SELECT has the next sequence value.

    2018-12-04 13_36_45-SQLQuery6.sql - dkrSpectre_SQL2017.sandbox (DKRSPECTRE_way0u (55))_ - Microsoft

    There are a lot more to sequences, but I’ve gone on long enough here. This is a good set of basics to experiment further, which I’ll do in future posts.

    SQLNewBlogger

    This post went on longer than expected, and it was more of a 15-20 minute writeup as I set up a couple quick examples, tore them down, and rebuilt them with screenshots for the post.

    This is a place where I can show I’ve started to learn more, and by continuing with other items in this series, I’ll show some regular learning.