Tag: T-SQL

  • LAST_VALUE–The Basics of Framing

    I did some work a 3-4 years ago, learning about the Windowing functions and enjoying them so much I built a few presentations on them. In learning about them, and trying to understand them, I found some challenges, and it took some experimentation to actually understand how the functions work in small data sets.

    I noticed last week that SQLServerCentral had re-run a great piece from Kathi Kellenberger on LAST_VALUE, which is worth the read. There’s a lot in there to understand, so I thought I’d break things down a bit.

    Framing

    The important thing to understand with window functions is that there is a frame at any point in time when the data is being scanned or processed. I’m not sure what the best term to use is.

    Let’s look at the same data set Kathi used. For simplicity, I’ll use a few images of her dataset, but I’ll examine the SalesOrderID. I think that can be easier than looking at the amounts.

    Here’s the base dataset for two customers, separated by CustomerID and ordered by the OrderDate. I’ve included amount, but it’s really not important.
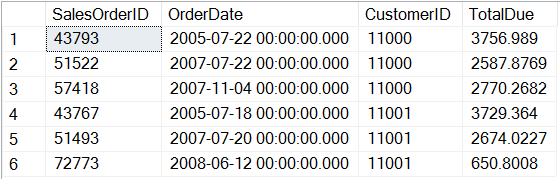
    2016-06-06 13_38_55-Phone

    Now, if I do something like query for LAST_VALUE with a partition of CustomerID and ordered by OrderDate, I get this set. The partition divides the set up into the two customer sets. Without an ORDER BY, these sets would exist as the red set and blue set, but in no particular order. The ORDER BY functions as it does in any query, guaranteeing the same order every time.

    2016-06-06 13_46_36-Movies & TV

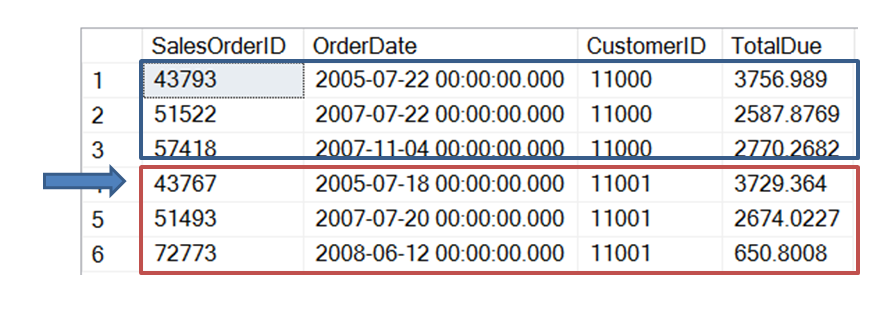
    Now, let’s look at the framing of the partition. I have a few choices, but at any point, I have the current row. So my processing looks like this, with the arrow representing the current row.
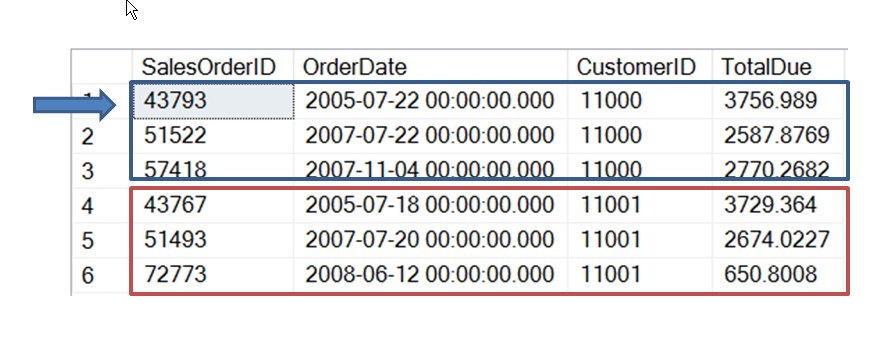
    2016-06-06 13_49_22-Movies & TV

    The next row is this one:

    2016-06-06 13_49_33-Movies & TV

    Then this one (the last one for this customer)
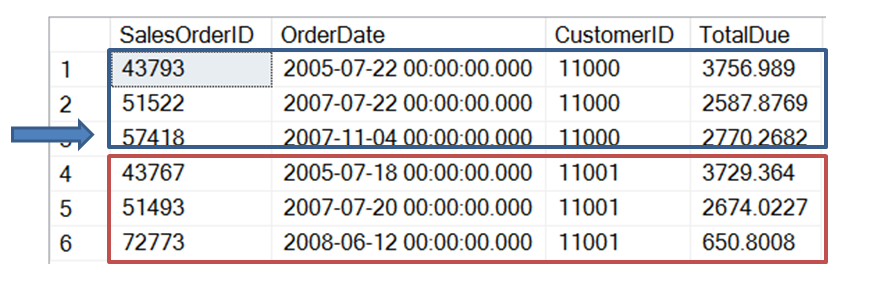
    2016-06-06 13_49_44-Movies & TV

    Then we move to the next customer.

    2016-06-06 13_49_54-Movies & TV

    When I look at any row, if I use “current row” in my framing, then I’m looking at, and including, the current row. The rest of my frame depends on what else I have. I could have UNBOUNDED PRECEEDING and UNBOUNDED FOLLOWING in there.

    If I used UNBOUNDED PRECEEDING and CURRENT ROW, I’d have this frame, in green, for the first row. It’s slightly offset to show the difference.

    2016-06-06 13_53_22-Movies & TV

    However, if I had CURRENT ROW and UNBOUNDED FOLLOWING, I’d have this frame (in green).

    2016-06-06 13_54_21-Movies & TV

    In this last case, the frame is the entire partition.

    What’s the last value? In the first case, the last part of that frame is the current SalesOrderID (43793). That’s the only row in the frame. In the second frame, the last one is 57418, the last row in the frame, and partition.

    What if we move to the next row? Let’s look at both frames. First, UNBOUNDED PRECEEDING and CURRENT ROW.

    2016-06-06 13_56_16-Movies & TV

    Now the frame is the first two rows. In this case, the last value is again the current row (51522). Below, we switch to CURRENT ROW and UNBOUNDED FOLLOWING.

    2016-06-06 13_56_29-Movies & TV

    Now the frame is just the last two rows of the partition and the last value is the same (57418).

    There’s a lot more to the window functions, and I certainly would recommend either Kathi’s book (Expert T-SQL Window Functions in SQL Server) or Itzik’s book (Microsoft SQL Server 2012 High-Performance T-SQL Using Window Functions). Either one will help. We’ve also got some good articles at SQLServerCentral on windowing functions.

  • It’s 2016 RLS for T-SQL Tuesday #79

    tsqltuesdayIt’s T-SQL Tuesday time again. I missed last month, being busy with travel, though I should go ahead and write that post. Maybe that will be next week’s task.

    In this case, Michael J Swart is hosting this month’s blog party and he asks us to write about something to do with SQL Server 2016. Read the rules at his invitation.

    Row Level Security

    I’ve wanted this feature to be easy for a long time. In fact, I’ve implemented a similar system a few times in different applications, but it’s been a cumbersome feature to meet, plus each developer needs to understand how the system works for it to work well. Even in the case where we once used views to hide our RLS, it was a performance issue.

    Microsoft has made things easier with their Row Level Security feature. This was actually released in Azure in 2015, but it’s now available in SQL Server 2016 for every on premise installation as well.

    Essentially for each row, there is some data value that is checked to determine if a user has access. This doesn’t mean a join. This doesn’t mean you write a lot of code. The implementation is simple, and straightforward, and I like it.

    Security Predicate Functions

    The one piece of code you need is an inline table valued function (iTVF) that returns a 1 for the rows that a user should see. You need to have some way to match up a row with a user, and that can be tricky, but if you identify a row, even in another table, you can use it.

    For example, I have this table.

    CREATE TABLE OrderHeader
      (
        OrderID INT IDENTITY(1, 1)
                    PRIMARY KEY
      , Orderdate DATETIME2(3)
      , CustomerID INT
      , OrderTotal NUMERIC(12, 4)
      , OrderComplete TINYINT
      , SalesPersonID INT
      );
    GO

    There’s nothing in this table that really helps me identify a user that is logged into the database. However, I do have a mapping in my SalesPeople table.

    CREATE TABLE SalesPeople
      (
        SalesPersonID INT IDENTITY(1, 1)
                          PRIMARY KEY
      , SalesFirstName VARCHAR(200)
      , SalesLastName VARCHAR(200)
      , username VARCHAR(100)
      , IsManager BIT
      );

    Granted, this could mean some change of code, but perhaps you can somehow use a user name in tables to query AD or other directory and map this to a user name.

    Once I have that mapping, I’m going to create a function. My function will actually look at the SalesPeople table, and map the parameter passed into the function to the value in the table.

    CREATE FUNCTION dbo.RLS_SalesPerson_OrderCheck ( @salespersonid INT )
    RETURNS TABLE
        WITH SCHEMABINDING
    AS
    RETURN
        SELECT
                1 AS [RLS_SalesPerson_OrderCheck_Result]
            FROM
                dbo.SalesPeople sp
            WHERE
                (
                  @salespersonid = sp.SalesPersonID
                  OR sp.IsManager = 1
                )
                AND USER_NAME() = sp.username;
    go

    In the function, I look at the USER_NAME() function and compare that to a value in the table. This is in addition to checking the SalespersonID column.

    I can use a Security Policy to bind this function to my OrderHeader table as shown here:

    CREATE SECURITY POLICY dbo.RLS_SalesPeople_Orders_Policy
      ADD FILTER PREDICATE dbo.RLS_SalesPerson_OrderCheck(salespersonid)
      ON dbo.OrderHeader;

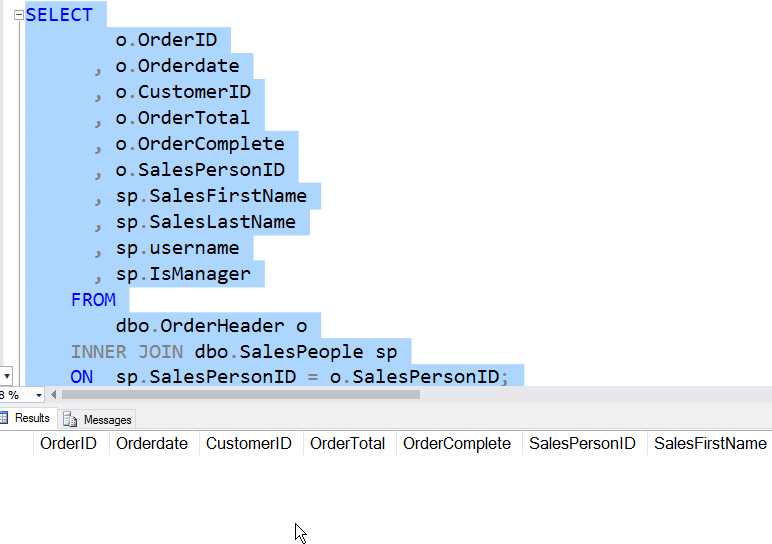
    This sets the function, passing in a column from the OrderHeader table, which is the column I want evaluated in the function.When I now query the OrderHeader table, I get this:

    2016-06-13 11_42_16-Photos

    There is data in the table. However, I don’t get rights by default, even as dbo. My USER_NAME() doesn’t match anything in the table, therefore no SalesPersonID matches. However, for other users, it works.

    2016-06-13 11_42_32-Photos

    There is a lot more to the RLS feature, but I think it’s pretty cool and it’s something that will be highly used in many applications moving forward, especially those multi-tenant systems.

    Go ahead, get the free Developer Edition and play around with RLS.

  • OBJECT_ID()–#SQLNewBlogger


    One of the things that is needed in quite a few functions is the object_id of a particular table/view/procedure/function in SQL Server. For example, I was looking at STATS_DATE recently, and it has this definition.

    STATS_DATE (object_id, stats_id)

    In the past, I’d run something like this:

    DECLARE @i INT
    SELECT @i = object_id
     FROM sys.objects 
     WHERE name = 'SalesOrderHeader'
    SELECT STATS_DATE ( @i , 2)

    Actually, I’d really do this as two batches.

    SELECT * FROM sys.objects WHERE name = 'SalesOrderHeader'
    SELECT STATS_DATE ( 1266103551 , 2)  
    

    I’d run the first, get the ID, and paste it into the second. However I’ve learned that isn’t the best way to do this. In fact, when I started doing  a lot of encryption testing and research, I started to take advantage of functions like OBJECT_ID.

    Now, here’s what I’d do:

    SELECT STATS_DATE ( OBJECT_ID(‘Sales.SalesOrderHeader’) , 2) 

    Simple, easy, and I can do this inline. With SQL Prompt, I’m also pretty quick getting this out. Of course, I do need to remember to include the schema, because this won’t work:

    SELECT STATS_DATE ( OBJECT_ID(‘SalesOrderHeader’) , 2) 

    Three warnings. First, qualify your objects. In this case, I should have used Sales.SalesOrderHeader to be sure I get the correct object. There are people that use schemas with the same object in multiple schemas (etl.SalesOrderHeader, audit.SalesOrderHeaders, etc.).

    Second, the object_id() isn’t guaranteed to be unique across databases. I should have pointed that out.

    SQLNewBlogger

    When I find quick tricks or techniques I use often, I try to make a note and then write about them later. It helps me remember, but it also lets me share things with others.

    Perhaps most important, it shows I’m doing and learning things in my career. Winking smile

  • Quick Tests for a Function

    I was writing a poorly performing UDF the other day and then wanted to replace it with a better performing one. However, I wanted to be sure that the function was the acting the same externally. In other words, does all my code that calls the function work the same?

    It’s a no brainer for me to use tSQLt to do this. I can quickly put together a few tests for my function. In my case, my function was proper casing a string. In this case, I make a class and add a quick test.

    My function is dbo.udfProperCase(@string). This takes a string value and returns a string value. My test needs then only a few variables.

    DECLARE @i VARCHAR(500) = ‘steve’
    , @expected VARCHAR(500) = ‘Steve’
    , @a VARCHAR(500)

    These are my input, my expected, and actual values. The rest of the test is simple.

    EXEC @a = dbo.udfProperCase @input = @i

    EXEC tsqlt.AssertEquals @Expected = @expected, @Actual = @a, @Message = N’single name failure’

    This calls the function, gets the return, and the asserts this is equal to the Expected value. I wrap this in a procedure definition. My complete definition is then:

    EXEC tsqlt.NewTestClass
      @ClassName = N’StringTests’;
    go
    CREATE PROC [StringTests].[test propercase single name]
    AS
    BEGIN
    DECLARE @i VARCHAR(500) = ‘steve’
    , @expected VARCHAR(500) = ‘Steve’
    , @a VARCHAR(500)

    — Act
    EXEC @a = dbo.udfProperCase @input = @i

    — assert
    EXEC tsqlt.AssertEquals @Expected = @expected, @Actual = @a, @Message = N’single name failure’

    END

    That test took me about 2 minutes to write. It’s fairly trivial, but this gives me a happy path test. I easily copied this multiple times, changing the input and Expected values.

    DECLARE @i VARCHAR(500) = ‘steve jones’
    , @expected VARCHAR(500) = ‘Steve Jones’

    and

    DECLARE @i VARCHAR(500) = ‘steve von jones’
    , @expected VARCHAR(500) = ‘Steve von Jones’

    and

    DECLARE @i VARCHAR(500) = ‘J steve Jones’
    , @expected VARCHAR(500) = ‘J Steve Jones’

    That gives me a few items. However I also want to look for issues, so I include a few other items.

    DECLARE @i VARCHAR(500) = ”
    , @expected VARCHAR(500) = ”

    as well as

    DECLARE @i VARCHAR(500) = null

    , @expected VARCHAR(500) = null

    This lets me quickly run a series of tests against my function. While this might not seem like much, they do give me flexibility. If I change the function from a loop to something more like Tony Rogerson’s code, I should get the same results.

    That’s the power of testing. Not so much that this verifies my code is correct, though it does that. Testing provides me the freedom to change code, without worrying I’ve subtlety broken things. I get a complete test run against new code quickly.

    Certainly I could have bugs in code, but I can easily write a new test when I find a bug and include it in my suite of tests to run against the function for the future.

    Testing isn’t that hard, and the more you practice writing tests, the better (and faster) you’ll get at it.