Tag: Azure

  • How Serverless is Working in Azure SQL Database

    When Azure SQL Database introduced the serverless option, I decided to try it. I moved one of my databases to the tier, though I had to move to a vCore model instead of the basic DTU setup. I was nervous, but I did it back in May.

    Since then, I’ve only used the database sparingly, so I haven’t noticed much change, but the billing is lower. In October, the first database I moved over here cost me US$0.35. In fact, the last three months, this has cost me US$6.90
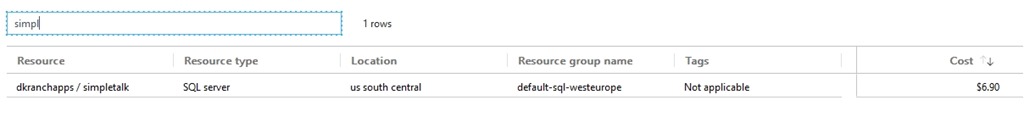
    2019-11-25 11_18_07-Cost Management_ VS_MSDN - Cost analysis - Microsoft Azure

    Let’s compare that with the 3 months until I went serverless. When I look at this, I see US$15.45, which is what I’d expect. About $5 a month.

    2019-11-25 11_20_33-Cost Management_ VS_MSDN - Cost analysis - Microsoft Azure

    On a low usage database, this has certainly saved me money. Would it be different if I used this more? That is harder to determine, and I need to run an experiment with something I use more often. I’ve tried to manage my Azure credits wisely, and with making a few changes across the last six months, I was slightly worried about the cost of this vCore system.

    Last month I did adjust this down to a 1 hour delay before shutting down the system, so if you had a normal vCore database and could cut down on usage during some periods, this certainly might help you.

    The downside? Today I spun up a db, and saw this for about 15 minutes.
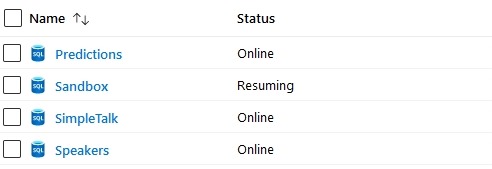
    2019-11-25 10_59_39-SQL databases - Microsoft Azure

    Now great, as this caused me SSMS issues as I tried to connect. More an SSMS issue, but still annoying.

    So far serverless has worked well for some test databases, which is where I think is shines.

  • Put Your Data in a Box

    A few years ago I was attending a keynote talk from one of the scientists that works CERN’s Large HADRON Collider (LHC). The talk was about data and how they deal with a large volume of data from experiments run on the machine. If you’re wondering what large is, the scientist talked about peak experimental data being over 1PB/s. I don’t know how much data you capture, but that’s a lot.

    In fact, it’s so much, that if they tried to analyze all that data, they’d never get around to running experiments. Instead, they depend on some pre-processing of data in sensor hardware as well as some early aggregation to get the data to a manageable level. It’s a good idea, and they have spent a lot of time and effort learning how to do this and still capture meaningful data for their work.

    The capability to remotely process data before sending it on is coming to all of us in a pre-packaged container. The Azure Data Box Edge was announced this week from Microsoft. This is a data processing device that is cloud managed and has FPGAs that you can program. It can run on batteries and is ruggedized for the field. There are more docs at Microsoft on the specifics.

    I don’t know how many companies want this, but I suspect that some who have remote or portable operations might think about it. Certainly if this can gather some data and then upload when a connection is available, it might be a good fit for places that don’t have good network connections and need a device that can handle some adverse conditions. I know sourcing and putting together a system for field offices is a pain. Off the shelf systems don’t always have reliability, and can be finicky to manage remotely.

    Recently I hosted a webinar with Abel Wang, and he talked about AI and ML being technologies whose use will grow dramatically in the next ten years. Perhaps a prediction without merit, but it does seem more and more companies and vendors are putting efforts into finding ways to deploy and operate ML systems. The Data Box Edge has capabilities in that area, which could be useful if you want to locally, and quickly, process data.

    This doesn’t appear to run SQL Server, or it’s not mentioned, but it does seem useful. If you doubt this, I know this is exactly what I would have wanted over a decade ago. I had to install systems in a warehouse to visual inspect some products. We used crude AI-ish systems that were set up to watch evaluation by humans. Eventually, the computer took over part of the job, but with humans randomly verifying its results. Keeping that system running was a pain. A Data Box Edge would have been a much better choice, and I’m sure we would have purchased one.

    There are likely plenty of customers that might be able to use this. It will be interesting to see if Microsoft can find them and sell many of these devices.

    Steve Jones

  • Investigating Azure Databricks

    At SQL Saturday #884 – Pensacola, I dropped into Rodney Ladrum’s session on Azure Databricks (ADB) and the Traditional DBA. I had heard a bit about Databricks, and read a little, but I didn’t really know much more than a rough overview. I’ve heard quite a bit from Microsoft about running Databricks notebooks, but I didn’t necessarily know what that meant.

    I was hoping to learn a bit, and I did. This wasn’t really a Databricks session, but a look at how you might need to manage and work with Databricks as a DBA. This assumes that there are data scientists or other data engineers that need to work with and process data, choosing to do so with R, Python, or Scala, but wanting to use Databricks notebooks.

    I need to learn more, and stumbled on 30 days of Databricks. I can’t get to that right now, but I added a subscription to remind me to come back. Between Rodney’s session showing me the basics of working with this in Azure and the intro video, I know a tiny bit about the technology.

    Databricks is a company and a way of managing and running Spark analysis. Apache Spark is an open source project that implements an analytics engine. However, it’s complex to run, so Datarbricks (the platform) is used to make this easier. Azure Databricks is an implementation of what Databricks sells, under license I assume.

    I know a little more, as there are notebooks that can be executed under the Databricks engine, and the code in here can be bash, R, Python, Scala, probably something else.

    That’s my start. I’ll learn more over time. If I find time.

  • Technology Flows Downstream

    A few years ago, I was listening a session on Azure SQL Data Warehouse at an event. At the time, one of the features I found fascinating was the separation of the storage from the compute portions of the service. We could load a lot of data in the system and pay for the storage, but we could spin up and down compute nodes to essentially scale out query processing to match our workloads. Azure Data Lake has something similar, and I was excited.

    I wasn’t excited about ASDW or ASDL because I don’t really use those platforms in my work, and I don’t have customers to talk to about those. I think they are useful, just not for me. I was, however, impressed with the technology, hoping that it would be coming in the next few years to SQL Server in the box and Azure SQL Database.

    It’s coming in SQL Server 2019, or at least, the start of it. We will get compute nodes, managed by Kubernetes, that will query other storage nodes that scale out I/O access. We also get this with Azure SQL Database in the Hyperscale edition, where there will be query servers and cache servers, designed to scale to infinite, or at least multi-petabyte, ranges

    I wasn’t always sure that the investments in Azure would pay off for the database side of things. It felt like Azure Stack was a natural place to help us manage and deploy SQL databases, and that the contained database work started in 2012 would get pushed by the needs of the Azure cloud, evolving and growing in future versions. We haven’t seen those pieces of technology grow, but I do think technology in other parts of the data platform has flowed to the “regular” OLTP database space.

    The separation of compute and storage really begins with the SQL Server 2019 era release, and I suspect that’s just the first step of how our SQL Server database systems will evolve in the future.

    Steve Jones

    Listen to the podcast at Libsyn.