Tag: T-SQL

  • Computed Columns and UDFs

    I wrote about the basics of computed columns and also using CASE in a computed column recently, but there’s a better way to implement a computation, and reuse the code. You can include a UDF in a computed column.

    UDFs are a great way to encapsulate your code into an object that can be included in stored procedures or even computed columns. The basic definition of a UDF is that it’s a function (as in other languages), but it’s designed to be included in other code, unlike a stored procedure. They’re very similar, but there are a couple types of UDFs:

    * The CLR UDFs can be scalar or table valued.

    For computed columns, you can use a UDF as well. Let me set up a couple tables here and a function. First I’ll set up a table similar to the one on SQLServerCentral that holds user points, add some data, and then create a quick function that calculates the sum of a user’s points.

    CREATE TABLE points
    ( USERID int
    , ItemID int
    , points tinyint
    )
    GO
    INSERT INTO points SELECT 1, 1, 2
    INSERT INTO points SELECT 1, 2, 1
    INSERT INTO points SELECT 1, 3, 1
    INSERT INTO points SELECT 2, 1, 1
    INSERT INTO points SELECT 2, 2, 1
    INSERT INTO points SELECT 2, 3, 2
    INSERT INTO points SELECT 2, 4, 1
    
    CREATE FUNCTION UDF_GetUserPoints
    ( @UserID int
    ) RETURNS int
    AS
    BEGIN
     DECLARE @sum INT
    
     SELECT @sum = SUM( points)
       FROM Points
       WHERE UserID = @UserID
       
    RETURN @Sum
    END
    

    If I run the function by itself, I can get the sum of each user’s point total.

    SELECT dbo.UDF_GetUserPoints(1) AS 'points'
    UNION 
    SELECT dbo.UDF_GetUserPoints(2) AS 'points'
    ------------------------*/
    points
    -----------
    4
    5

    Now let’s go back and set up the user table. I could alter this table if it existed, but in this case I’ll add the points as well as a calculated value for the user’s points. As long as I’m not asking for lots of user’s from this table, this technique is probably OK. Otherwise, I might have a big performance issue. (no SELECT *s from this table)

    CREATE TABLE UserProfile
    ( UserID INT
    , UserName VARCHAR(200)
    , points AS dbo.UDF_GetUserPoints(USerID)
    )
    go
    INSERT INTO userprofile SELECT 1, 'Steve'
    INSERT INTO dbo.UserProfile SELECT 2, 'Andy'
    

    Note that I’m not adding a value for the points column. This is a computed column, so I ignore it in inserts.

    SELECT TOP 10  UserID ,
            UserName ,
            points 
     FROM dbo.UserProfile
    
    UserID      UserName      points
    ----------- ------------- -----------
    1           Steve         4
    2           Andy          5

    Here the values are calculated from the other table, pulled from my UDF in the computed column.

    Not necessarily a great technique, and I would be careful about using this. Since this function is non-deterministic, we can’t persist the values in the table, so this means that any access of this table for the points column would result in the function execution for the row. Potentially a performance issue.

    If you want to see this idea in action, there’s a similar video on UDFs in Computed Columns at SQL Share as well that covers the topic.

    Disclosure: I am a part owner in SQL Share

    .

  • Computed Columns and CASE

    I wrote about computed columns recently, but I didn’t realize that a logical expression could be used here, such as a case statement, and misspoke in this thread on SSC. Fortunately someone corrected me and I decided to blog and test this a bit.

    Why an expression?

    Suppose you had a table like this:

    CREATE TABLE OrderDetail
    ( OrderID INT
    , ProductID INT
    , Qty INT
    , OrderDate DATETIME
    , ShipDate DATETIME
    , STATUS INT
    )
    

    I record orders, but I don’t necessarily have a ship date when the order is placed. There are many cases where a user enters an order and some back end system later calculates a shipdate based on the supply situation, or even waits to update this field when the order ships. It’s entirely possible I have data in this table like this:

    computecol2

    Suppose I then have a status table with these values:

    computecol3

    Here is my logic. If the shipdate is null, then the order has not shipped and is in the status of ordered. If the shipdate is filled in, the order is shipped. If the shipdate is null, and the order date is more than 2 weeks old, the order is late. In our example, if the date is 11/5/2011, then the order #4 is late.

    We can easily join to the Status table to display this for the client, but we are depending on some process running every day to check for late orders. Otherwise how does row 4 get marked as late? When the order is entered, it’s not late, and we certainly don’t want to wait until the client checks on their order status to mark it as late.

    If we had a computed column, we could easily handle this, and display late orders for a report, or even for a other queries. I could change the definition of the status column to be this:

    CREATE TABLE OrderDetail
    ( OrderID INT
    , ProductID INT
    , Qty INT
    , OrderDate DATETIME
    , ShipDate DATETIME
    , STATUS AS CASE
           WHEN shipdate is NULL AND orderdate < DATEADD( dd, -7, GETDATE()) THEN 3 
           WHEN shipdate is NOT NULL THEN 2 
           ELSE 1
       end
     )
    GO

    Now the status I get is based on the other values in the row and is correct, regardless of my application logic.

    NOTE: This is a contrived example, and I don’t like this since I am assuming the status logic doesn’t change. In a real system, I would probably prefer to use the actual status in the column if I did this, as shown here:

    CREATE TABLE OrderDetail
    ( OrderID INT
    , ProductID INT
    , Qty INT
    , OrderDate DATETIME
    , ShipDate DATETIME
    , STATUS AS CASE
           WHEN shipdate is NULL AND orderdate < DATEADD( dd, -7, GETDATE()) THEN 'Late' 
           WHEN shipdate is NOT NULL THEN 'Shipped'
           ELSE 'Ordered'
       end
     )
    

    A Better Example

    A better example of where this might be used would be in the case where I might have a variable calculation. For example, in many Internet businesses in the US, you do not collect sales tax if your product is not being sold inside the state in which your company is located.

    If I sold horse products from my ranch, located in CO, I would have to collect sales tax for sales shipped to CO, but not those shipped elsewhere. So perhaps I’d have a table like this:

    CREATE TABLE OrderDetail
    ( OrderID INT
    , ProductID INT
    , Qty INT
    , Price NUMERIC( 10, 2)
    , St CHAR(2)
    , TaxRate NUMERIC( 12, 4)
    , LineTotal AS CASE
           WHEN st = 'CO' THEN (Qty * price) + (Qty * price * TaxRate) 
           ELSE (Qty * price)
       end
     )
    GO
    INSERT dbo.OrderDetail
            ( OrderID ,
              ProductID ,
              Qty ,
              Price ,
              St ,
              TaxRate
            )
    VALUES  ( 1 , -- OrderID - int
              1 , -- ProductID - int
              10 , -- Qty - int
              10 , -- Price - numeric
              'AZ' , -- St - char(2)
              .1  -- TaxRate - numeric
            )
    INSERT dbo.OrderDetail
            ( OrderID ,
              ProductID ,
              Qty ,
              Price ,
              St ,
              TaxRate
            )
    VALUES  ( 1 , -- OrderID - int
              1 , -- ProductID - int
              10 , -- Qty - int
              10 , -- Price - numeric
              'CO' , -- St - char(2)
              .1  -- TaxRate - numeric
            )
    
    
    SELECT OrderID, qty, Price, St, TaxRate, LineTotal
     FROM dbo.OrderDetail
     

    Useful?

    I’m not sure if computed columns are terribly useful. To me they strike of hard coding logic into a schema that I’m not sure belongs, but if you find them useful, you do have the option of doing so, and including logical expressions with CASE.

  • Basic Computed Columns

    I ran into an issue recently with a computed column, which I’ve rarely used, so I investigated them and wrote this short piece in computed columns, mostly as a reminder for me.

    What’s a computed column?

    You can read the BOL definition, but basically it is a column whose value is based on the values of other columns in a table. By having SQL Server perform the calculation, you prevent errors in the logic, or more likely, get around the chance that some application might forget to perform an update.

    Let’s say I have this simple orderdetail table.

    CREATE TABLE OrderDetail
    ( OrderID INT
    , ProductID INT
    , Qty INT
    , Price NUMERIC(10, 2)
    , LineTotal NUMERIC(10, 2)
    )
    

    If I want to add a simple order to this table, I can do this:

    INSERT dbo.OrderDetail
            ( OrderID ,
              ProductID ,
              Qty ,
              Price ,
              LineTotal
            )
    VALUES  ( 1 , -- OrderID - int
              23 , -- ProductID - int
              10 , -- Qty - int
              8.50 , -- Price - numeric
              85.00  -- LineTotal - numeric
            )
            

    Note that in this case I have to perform the arithmetic of having the line total equal to the price multiplied by the quantity. The math is:

    Linetotal = Qty * Price

    85.00 = 10 * 8.50

    However if I were to make a mistake in the arithmetic and insert $84 instead, or even $8.50, the SQL Server would not catch this.

    Instead, I could use a trigger to calculate this value, but triggers seem to have other overhead and force me to maintain them. Instead I could use a computed column, I can save space by not persisting these columns, or I can persist them and index them if needed.

    In my simple example, I could change my table to be this:

    DROP TABLE dbo.OrderDetail
    go
    
    CREATE TABLE OrderDetail
    ( OrderID INT
    , ProductID INT
    , Qty INT
    , Price NUMERIC(10, 2)
    , LineTotal AS (Qty * Price)
    )
    GO
    INSERT dbo.OrderDetail
            ( OrderID ,
              ProductID ,
              Qty ,
              Price
            )
    VALUES  ( 1 , -- OrderID - int
              23 , -- ProductID - int
              10 , -- Qty - int
              8.50 -- Price - numeric
            )
    go

    The LineTotal value is not stored in the table, which isn’t a big issue in this case. In fact, it means that I am saving a few bytes per row, which could translate into quite a few rows for this table (meaning less pages, less I/O, more chance of this remaining in the buffer pool, etc). The tradeoff is the computation is performed for this result set for every query. Which is better? It depends Winking smile

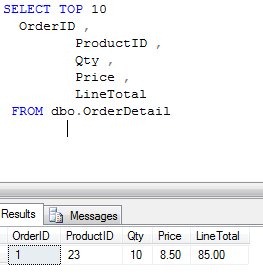
    Notice that I don’t have a value for my computed column in the insert statement, but the results from this version are the same as the previous one:

    computecol

    In fact, if I try the first insert above, which has the LineTotal in it, I get this error:

    Msg 271, Level 16, State 1, Line 1

    The column "LineTotal" cannot be modified because it is either a computed column or is the result of a UNION operator.

    That’s a simple look at computed columns. Are they useful? I’ve never really worried about them, allowing either a stored procedure or the application to handle any logic like this. In general I dislike storing computations, even defined ones like this, but that’s me.

    Use them if they fit your environment.

  • Two Types of Tail Log Backups

    In a recent thread I noted that a tail log backup is essentially a regular log backup, but made with the intention of restoring the database because something is wrong with your data file. Gail Shaw (blog | @SQLIntheWild) pointed out that that’s not quite true. There are two parameters that you need to add to the BACKUP LOG command. Thanks to Gail for the correction, and here’s a little more data.

    There are three options you have with a tail log backup are:

    • WITH NORECOVERY
    • WITH CONTINUE_AFTER_ERROR
    • WITH NO_TRUNCATE

    I covered the third one in doing some practice backing up of the tail log. The second one is noted in Books Online as one that you should use in the event that the database is offline and inaccessible. That will allow you to recover the last log backup (hopefully).

    The first one is recommended as the one you use when the database is going to be restored and you want the end of the log.

    As I mentioned in my previous post, this is a core DBA skill. It is what will allow you to recover a database with zero data loss.