Tag: T-SQL

  • SQL Server Default Backup Directory

    Someone asked me in a webinar how to change the default backup directory. I knew, but realized that I didn’t have a reference and ended up with more explanation than needed if I’d had a post. So here it is:

    If you right click on a server in Management studio and select properties, you get dialog with lots of options.

    serverpropertoes


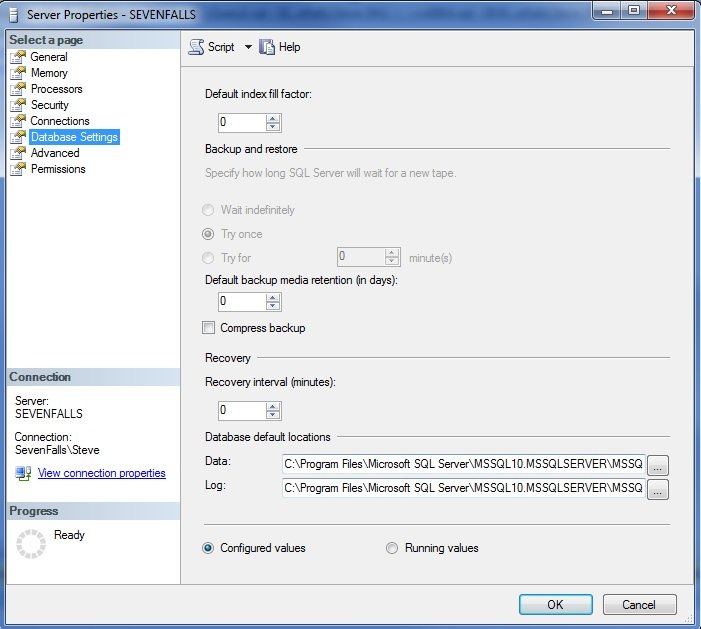
    If you click on the “Database Settings” you get this:

    serverdbsettings

    Note that there is a default path for data files and log files, not not one for backup files.

    serverdbsettings1

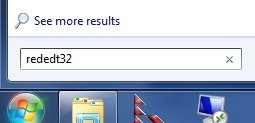
    So how do you change it? In XP or Win 7, click Start and type this right away “regedt32”

    regedior

    That will start the registry editor. You ought to get a UAC box to confirm access, which is fine. Do that and you’ll be in the registry. In the left pane, browse to this path:

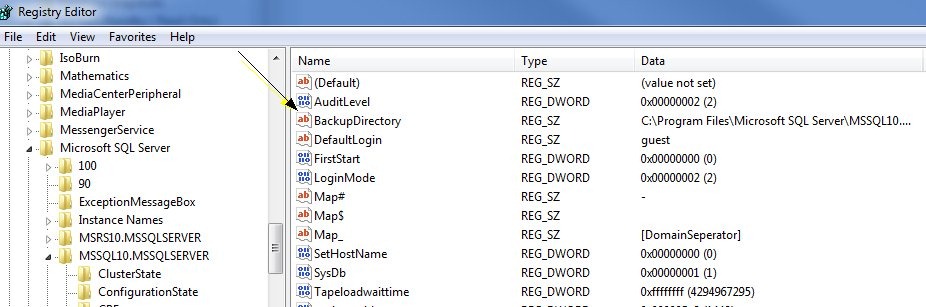
    HKey_LocalMachine\Software\Microsoft\Microsoft SQL Server\MSSQL.1\MSSQLServer”

    Note that the “MSSQL.1” might be different, depending on your instance. For me it’s SSQL10.MSSQLServer.

    backupdir

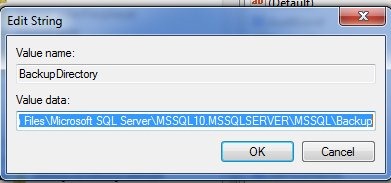
    Note that there’s a “BackupDirectory” key here. You can double click it to change the path:

    backupdir2

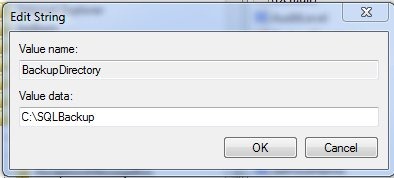
    I changed mine to a new path, c:\sqlbackup. Note that I had to create this folder.

    change path

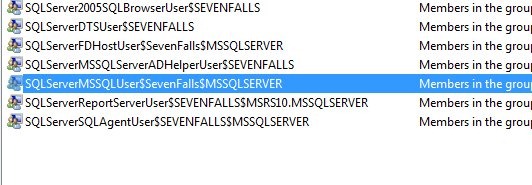
    That’s not enough, however. If you go into your adminstrative tools and find the Computer Management and look for Users and Groups (Select groups), you’ll find groups like this. The name varies, depending on the name of your workstation/server and instance.

    security


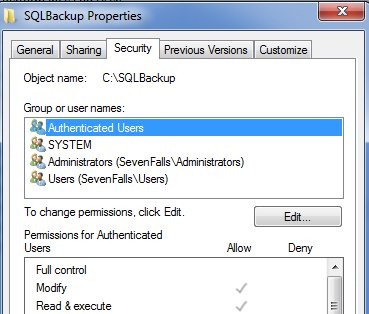
    Once you have this name, I’d copy it and go to your new folder. Right click, select properties, and then the security tab

    sevc1

    As you can see, my group isn’t in here, but this group, with the SQL Server service account in it, needs permissions to this folder. So add them, with modify.


    sec2

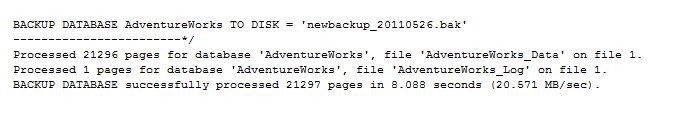
    Is my default changed? I could now run this:

    backup1

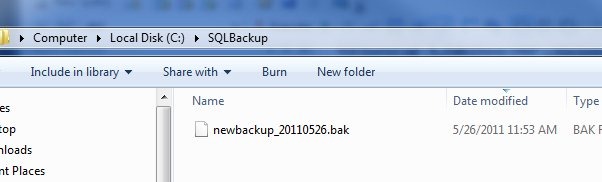
    and I find a file in my new default folder:

    backup2

  • Combinations and Permutations

    I ran into an interesting question from someone asking for all combinations of numbers. The thread was here, and it was confusing at first. However we started to understand what was being asked and eventually the person stopped, realizing that there were too many combinations.

    However at one point there was this quote: I’m looking for combinations, not permutations since the order is unimportant.

    That surprised me since I was thinking of things in the opposite manner. However when I read this article, it made sense: combinations and permutations

    There is a table in the article that cleared it up. I’ve reproduced it here:

    Order does matter Order doesn’t matter

    1 2 3


    1 3 2


    2 1 3

    1 2 3

    2 3 1


    3 1 2


    3 2 1

    The left hand side is permutations, where order matters. The right hand side is combinations, of which there is only one. Order doesn’t matter so 1-2-3 is the same as 1-3-2, which is the same as 3-2-1 and all other orderings.

    This shows mathematical semantics, but those are important in SQL because we do need to talk about combinations and permutations. A CROSS JOIN is normally how we handle combinations, which for three numbers are usually thought of as the way to handle all combinations, but I’m not sure how that works here.

    If I create a quick table:

    CREATE TABLE Combinations
    ( id int) GO INSERT Combinations select 1
    INSERT Combinations select 2
    INSERT Combinations select 3

    and then perform a cross join:

    SELECT a.id, b.id
     FROM Combinations a
       CROSS JOIN dbo.Combinations b

    I get this:

    id          id

    ———– ———–

    1           1

    2           1

    3           1

    1           2

    2           2

    3           2

    1           3

    2           3

    3           3

    Not all combinations. Even if I add in a third result:

    SELECT a.id, b.id, c.id
     FROM Combinations a
       CROSS JOIN dbo.Combinations b
       CROSS JOIN dbo.Combinations c

    id          id          id

    ———– ———– ———–

    1           1           1

    1           2           1

    1           3           1

    1           1           2

    1           2           2

    1           3           2

    1           1           3

    1           2           3

    1           3           3

    2           1           1

    2           2           1

    2           3           1

    2           1           2

    2           2           2

    2           3           2

    2           1           3

    2           2           3

    2           3           3

    3           1           1

    3           2           1

    3           3           1

    3           1           2

    3           2           2

    3           3           2

    3           1           3

    3           2           3

    3           3           3

    However, what about if I limit the result to remove duplicates:

    SELECT a.id, b.id, c.id
     FROM Combinations a
       CROSS JOIN dbo.Combinations b
       CROSS JOIN dbo.Combinations c
    WHERE a.id != b.id
    AND b.id != c.id
    AND a.id != c.id

    That seems to work better:

    id          id          id

    ———– ———– ———–

    1           3           2

    1           2           3

    2           3           1

    2           1           3

    3           2           1

    3           1           2

    However that’s not a great solution. I’ve hardcoded the number of items, and it’s a cumbersome query. I think there has to be a better solution, but it’s probably one that’s beyond my T-SQL skills. If I look at 5 numbers, I get this:

    SELECT a.id 'a', b.id 'b', c.id 'c', d.id 'd', e.id 'e' FROM Combinations a
       CROSS JOIN dbo.Combinations b
       CROSS JOIN dbo.Combinations c
       CROSS JOIN dbo.Combinations d
       CROSS JOIN dbo.Combinations e
    WHERE a.id != b.id
    AND a.id != c.id
    AND a.id != d.id
    AND a.id != e.id
    AND b.id != c.id
    AND b.id != d.id
    AND b.id != e.id
    AND c.id != d.id
    AND c.id != e.id
    AND d.id != e.id
    ORDER BY a, b, c, d

    I get 120 rows. If I look at 5!, that’s 120, so I think I’m correct. I’m not duplicating all the results, nor am I  going to look through them all, but they seem correct and ordered.

    The thing this solution leaves out is the combinations that are less than the total number of items, as asked in the thread. So expanded combinations would be:

    1

    2

    3

    4

    5

    1 – 2

    1 – 3

    1 – 4

    1 – 4

    1 – 2 – 3

    …

    Not worth including those, but I think that would result in a series of UNION queries, which would get really ugly.

    I’ll ask around, but if anyone has an interesting way to solve this that’s cleaner, I’d be interested.

    Update

    Someone posted this, which seems to work wonderfully:

    DECLARE @s VARCHAR(25)
    ,@Iteration Int
    SET @s = ‘ABC’;
    SET @Iteration = LEN(@s);

    WITH E1(N) AS ( –=== Create Ten 1’s
    SELECT 1 UNION ALL SELECT 1 UNION ALL
    SELECT 1 UNION ALL SELECT 1 UNION ALL
    SELECT 1 UNION ALL SELECT 1 UNION ALL
    SELECT 1 UNION ALL SELECT 1 UNION ALL
    SELECT 1 UNION ALL SELECT 1 –10
    ),
    cteTally(N) AS (SELECT ROW_NUMBER() OVER (ORDER BY (SELECT N)) FROM E1
    ),CteCombos AS (
    SELECT CAST(SUBSTRING(@s, N, 1) AS VARCHAR(25)) AS Token,
    CAST(‘.’+CAST(N AS CHAR(1))+’.’ AS VARCHAR(52)) AS Permutation,
    CAST(1 AS INT) AS Iteration
    FROM cteTally WHERE N <= @Iteration
    UNION ALL
    SELECT CAST(Token+SUBSTRING(@s, N, 1) AS VARCHAR(25)) AS Token,
    CAST(Permutation+CAST(N AS CHAR(1))+’.’ AS VARCHAR(52)) AS
    Permutation,
    s.Iteration + 1 AS Iteration
    FROM CteCombos s
    INNER JOIN cteTally n
    ON s.Permutation NOT LIKE ‘%.’+CAST(N AS CHAR(1))+’.%’
    AND s.Iteration < @Iteration
    AND N <= @Iteration
    )
    SELECT Token,Permutation,Iteration
    FROM CteCombos
    WHERE Iteration = @Iteration
    ORDER BY Permutation

    If you alter the variable (abc) to the number of items you need, so “abcde” for 5, this returns the combinations.
  • Duplicate Identity Values?

    Can you have duplicate values in a field with the identity property? Of course, and this does it.

    DROP TABLE dbo.MyTable
    
    CREATE TABLE mytable
    ( id INT IDENTITY(1,1)
    , mychar VARCHAR(10)
    )
    GO
    INSERT mytable SELECT 'A'
    INSERT mytable SELECT 'B'
    INSERT mytable SELECT 'C'
    
    
    SELECT * FROM dbo.MyTable

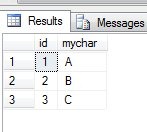
    This returns these values:

    result1

    Then we use Identity_insert

    SET IDENTITY_INSERT dbo.MyTable ON
    GO
    INSERT dbo.MyTable
            ( ID, myChar )
    VALUES  ( 8, -- myID - int
              'H'  -- myChar - varchar(20)
              )
    SET IDENTITY_INSERT dbo.MyTable OFF
    
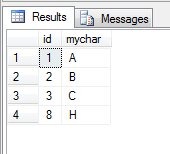
    SELECT * FROM dbo.MyTable

    result2

    Now we reseed and add more values

    DBCC CHECKIDENT('mytable', RESEED, 4)
    
    INSERT mytable SELECT 'E'
    INSERT mytable SELECT 'F'
    INSERT mytable SELECT 'G'
    INSERT mytable SELECT 'H'
    INSERT mytable SELECT 'I'
    
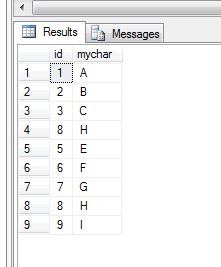
    SELECT * FROM dbo.MyTable

    result3


    You can see that we have two ID rows with “8” in them. Clearly a duplicate.

    Identity doesn’t guarantee uniqueness. If you want that, make a PK or add a unique index.

  • Identity Reseeding

    I love the identity property. I use it in many of my tables, mostly because it gives me a fairly reliable surrogate key that I can use in my tables, especially when testing something. I often do something like this:

    CREATE TABLE MyIdentityTest
    ( id INT IDENTITY(1,1)
    , mychar VARCHAR(10)
    )
    GO
    INSERT MyIdentityTest SELECT 'A'
    INSERT MyIdentityTest SELECT 'B'
    INSERT MyIdentityTest SELECT 'C'
    GO

    In this table, I have these results:

    id          mychar

    ———– ———-

    1           A

    2           B

    3           C

    If I then look to reseed things for some reason, maybe I want to leave a gap somewhere, I can do this:

    SET IDENTITY_INSERT MyIdentityTest ON
    INSERT MyIdentityTest (id, mychar) SELECT 12, 'L'
    GO
    SET IDENTITY_INSERT MyIdentityTest OFF
    GO

    This means my table now looks like this.

    id          mychar

    ———– ———-

    1           A

    2           B

    3           C

    12          L

    If I insert a new value:

    INSERT MyIdentityTest SELECT 'M'
    GO
    

    And now check all the results, I have this:

    SELECT * FROM myidentitytest

    we get

    id          mychar

    ———– ———-

    1           A

    2           B

    3           C

    12          L

    13          M


    Suppose I realized that I had a problem and decided to “fix” my identity values. I can reseed like this, which sets the identity property tracker back to 3.

    DBCC CHECKIDENT(myidentitytest, RESEED, 3)
    go
    INSERT MyIdentityTest SELECT 'D'
    GO

    However look at the results of the insert. It shows 4 instead of 3, which is what I want in this case.

    SELECT * FROM myidentitytest

    id    mychar

    —– ———-

    1     A

    2     B

    3     C

    12    L

    13    M

    4     D

    Quite a few people think that if I set the identity to “3”, I should have 3 as the next value. That’s not the case, and it’s something to be aware of when working with identities. If you are looking to fill gaps or move your seed for some reason (like merge replication), understand that you are inserting the “last” value as your seed, not the “next” one.