I’m off in the UK and buried with other work, so a republish today.
Tag: T-SQL
-
T-SQL Tuesday #106 – Trigger Headaches or Happiness
 Since I took over the T-SQL Tuesday a few months ago, I decided I ought to host again. Especially since I’ve done it twice, but Wayne Sheffield got his third spot last month. Gotta keep up with Mr. Sheffield.
Triggers, for fun and frustration
I’ve been working with SQL Server and T-SQL a long time, and across many jobs, I think I’ve ended up using triggers in 0.01% of my tables or less. They can be a useful and helpful construct, but they can also be problematic and difficult, especially in the age of changing business models and rules.
Since I’ve found triggers to be both helpful and hurtful, I decided to ask you to write about an experience you’ve had with triggers. Either good or bad, but let me know this month what stands out in your mind.
The Rules
As always, the rules for this month are simple.
- Write and publish a post on September 11, 2018, UTC time.
- Include the T-SQL Tuesday logo (you can grab this above) and link your post back to this invitation.
- Leave a comment/pingback on this post for me to use to include you in the roundup
- Have fun.
-
Generating a Constrained Random Date–#SQLNewBlogger
Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.
There have been lots of posts on the topic of generating random values, and some great articles. One of my favorites is Jeff Moden’s Generating Test Data: Part 1 – Generating Random Integers and Floats. Part 2 deals with dates, and that’s actually what I needed, but really I needed part 1.
In my situation, I was helping a customer generate some random data. They had filled a table, Customers, with some data.
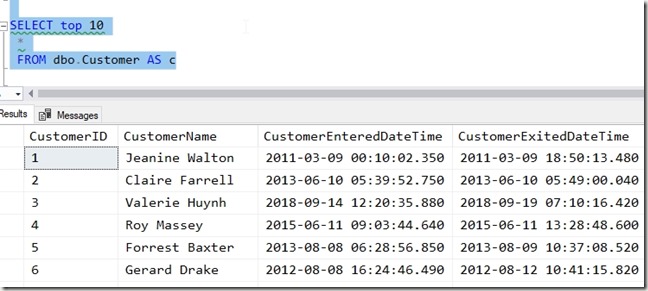
The goal was to populate a child table with some data. The child table had a date column that was supposed to be between the Entered and Exit dates in the Customer table.My update would have a join, obviously, and I can reference the enter and exit date, but how to get a date between them? My first thought was that I wanted a DATEADD() function. Something like this:
UPDATE ce

SET ce.EventTimeStamp = DATEADD( MINUTE, SomeRandomValue, c.CustomerExitedDateTime)), c.CustomerEnteredDateTime)

FROM   dbo.Customer AS c

INNER JOIN dbo.CustomerEvent AS ce

ON ce.CustomerID = c.CustomerID
The trick is what random value to use? If you look through Jeff’s article, you will see that the trick is to use a tally table and the NEWID() function. However, this doesn’t work:
 UPDATE ce

SET ce.EventTimeStamp = DATEADD( MINUTE, NEWID(), c.CustomerEnteredDateTime)

FROM   dbo.Customer AS c

INNER JOIN dbo.CustomerEvent AS ce

ON ce.CustomerID = c.CustomerID

;
What I need to do is convert the GUID to a number. In this case, I added CHECKSUM around it, again, as in Jeff’s article. Then use ABS() to enclose this to get all positive numbers.
 UPDATE ce

SET ce.EventTimeStamp = DATEADD( MINUTE, ABS(CHECKSUM((NEWID())))), c.CustomerEnteredDateTime)

FROM   dbo.Customer AS c

INNER JOIN dbo.CustomerEvent AS ce

ON ce.CustomerID = c.CustomerID

;
This gives me values, but they aren’t constrained. What I need to do is limit the upper random value so that the end time doesn’t exceed the Customer.CustomerExitDateTime for that row.
To do this, I can constraint a large set of numbers to some value with the modulo function. This will limit what values can appear. The basic script is this:
UPDATE ce

SET ce.EventTimeStamp = DATEADD( MINUTE, ABS(CHECKSUM((NEWID())))) % 10, c.CustomerEnteredDateTime)

FROM   dbo.Customer AS c

INNER JOIN dbo.CustomerEvent AS ce

ON ce.CustomerID = c.CustomerID

;
This would give me values between 1 and 0 minutes after the start time, but this doesn’t mean these values won’t be after the exit time. This is also an unrealistic window if most of the time the enter and exit times vary by hours.
What I did instead was to use the difference between the enter and exit times, with DATEDIFF() as my modulo function. That gives me:
WITH myTally (n)

AS

-- SQL Prompt formatting off

(SELECT n = ROW_NUMBER() OVER (ORDER BY (SELECT null))
  FROM (VALUES (1), (2), (3), (4), (5), (6), (7), (8), (9), (10)) a(n)
   CROSS JOIN (VALUES (1), (2), (3), (4), (5), (6), (7), (8), (9), (10)) b(n)

)

UPDATE ce

SET ce.EventTimeStamp = DATEADD( MINUTE, ABS(CHECKSUM((NEWID()))) % (DATEDIFF(MINUTE, c.CustomerEnteredDateTime, c.CustomerExitedDateTime)), c.CustomerEnteredDateTime)

FROM   dbo.Customer AS c

INNER JOIN dbo.CustomerEvent AS ce

ON ce.CustomerID = c.CustomerID

;
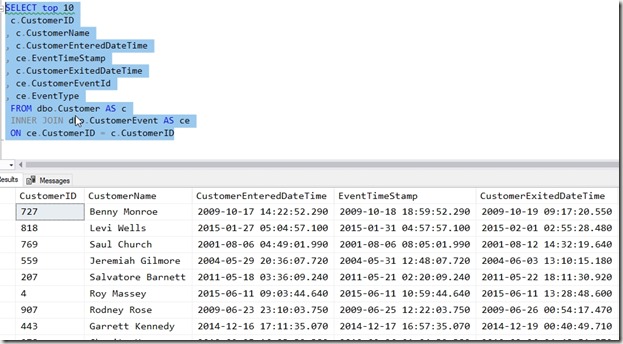
I run this, and I get the table updated with a random set of values.
SQLNewBlogger
This was a problem in my daily work. It was a customer, but it could easily be an internal query problem. I spent about 10 minutes grabbing screen shots and taking apart the query I’d built.
You can do this, too. Show us your mind working with the solutions you write in your own blog.
-
Remember the Default Window
I ran across a question recently from a user about why they had strange results from a windowing query. This is better explained with an example, so let’s look at one.
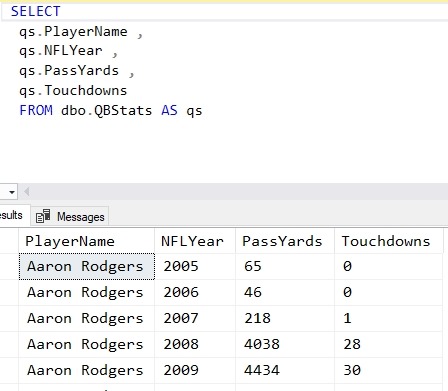
I have some data in a table. This is NFL data, and a sample of it looks like this:
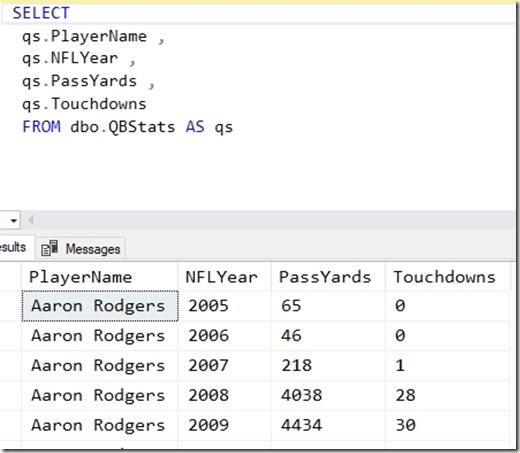
What I want to do is compare the passing yards each year with the most current value for that player, showing the plus or minus. This means that for Aaron Rodgers, who threw for 1675 yards in 2017, I’d want to show this for the first few years of his career:
  PlayerName  NFLYear PassYards Most Recent Yards Difference

------------- ------- --------- ----------------- -----------

Aaron Rodgers 2005    65        1675              -1610

Aaron Rodgers 2006    46        1675              -1629

Aaron Rodgers 2007    218       1675              -1457

Aaron Rodgers 2008    4038      1675              2363
This shows
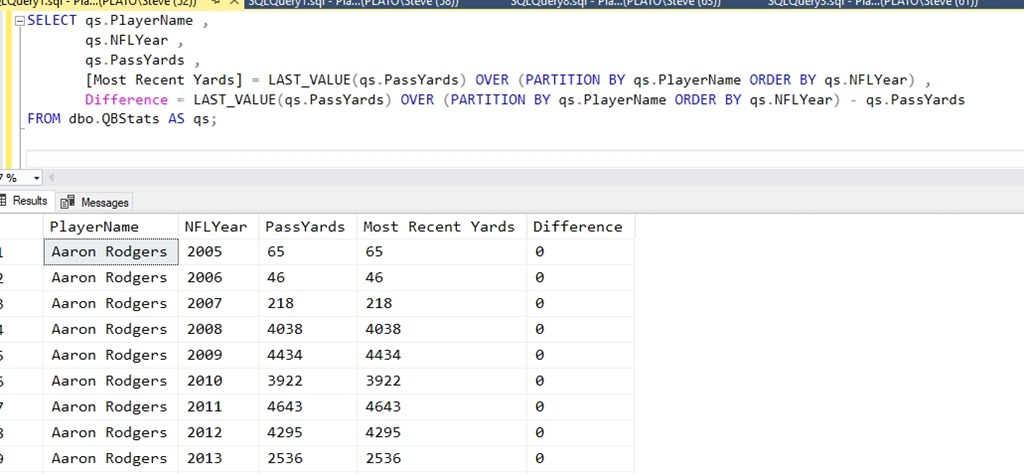
me an easy view of the years where he was better in his career than he is now. Last year was likely a down year because of injury, but we’ll see this year.In any case, if I run this query using LAST_VALUE() for the final year of his career, I don’t get the right results.
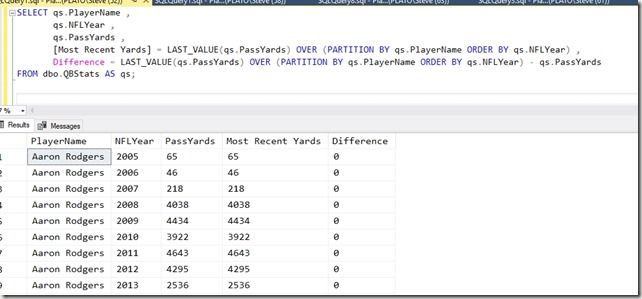
It seems as though in every row, I’m getting the current row as the last value, not the last value of the partition. My partition is by player, so I should only have a window for each player. In this case, I should have the years 2005-2017 for Aaron Rodgers. My ordering is by year, so the last value should be 1675.
Why isn’t it?
The reason has to do with the framing. As the window is consumed, the default values for the framing are between
- start – unbounded preceding
- end – current row
That means the first row for 2005 has the range of 2005-2005. The preceding rows are this row, and the current row is this row. For 2006, we have the first row as 2005 and the current row as 2006. The last value in this case is 46.
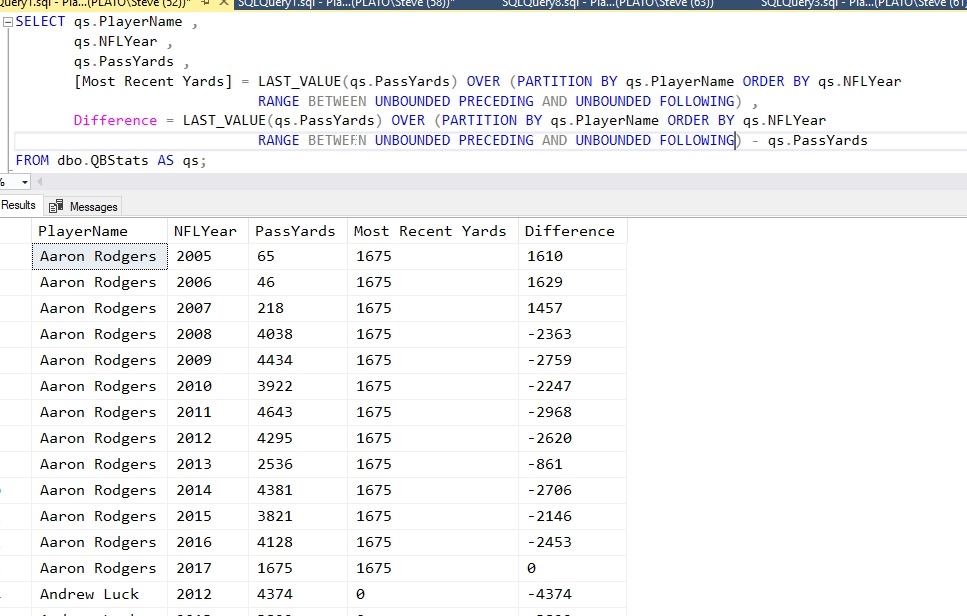
What we need to do is specify the entire window if we want that. In this case, we could use the current row as the start, but we certainly need the unbounded following rows.
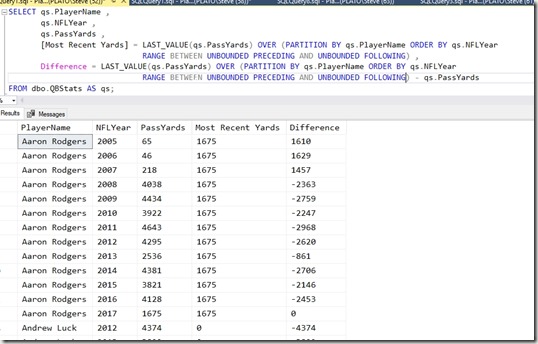
This is a common mistake when writing window queries. I’d recommend you always include the partition and the framing to avoid any issues.