Author: way0utwest

  • The Cost of Multiple Platforms

    I ran into an interesting post that noted the modern data platform can have a bunch of different systems underlying it. The example might be that your “software” could use PostgreSQL, MongoDB, Cassandra, Clickhouse, and something NewSQL (Spanner, CockroachDB, etc,). Some of you might think that’s not reality, but keep in mind that for a lot of your organizations, the “software” is what the customer uses. I’m sure my bank has multiple systems behind the mobile app I use to pay for things, move money, check balances, etc. I would guess there is some DB/2, SQL Server, and some analytics or No/NewSQL stuff in there. Hidden as different applications that make up the “app”, but they are still in there from my perspective as a user of the app.

    No one intentionally designs software like this, but we still see it. They might not even have 5 or 6 platforms in their organization, but almost none of the customers I work with have less than 3. Somehow, somewhere, someone added a PostgreSQL server to an Oracle/SQL Server environment. MongoDB crept in when someone thought it was a better store than DB/2 or MySQL. An article written about how Facebook or Spotify or some other high tech company used Cassanda or Snowflake inspired a developer to add that to their toolbelt and build it into their application.

    And the ease with which the cloud makes experimentation quick and cheap causes a spread of your database estate.

    There’s a cost to having all these systems. Either an organization hires separate sets of experts to manage Ops, or they try and train lots of individuals to run multiple systems. It can be done, but those lightly trained people who have to focus on remembering the differences between SQL Server, PostgreSQL, and MongoDB will work slower. They’ll solve problems with a higher MTTR. Even if they have a single pain of glass, like Redgate Monitor, they still won’t be as effective as the number of platforms grow. It’s just human nature. And if you hire separate teams, that’s a cost as well.

    Heck, I’m a pretty good DBA and a good volleyball coach, but I get confused. When I got voluntold to manage DB/2 systems in addition to SQL Server, I got less done every day. When I coached two volleyball teams at the same time, I was less effective with each. It’s hard to keep focused on multiple similar things. Add in the complexity of not only separate paradigms, but different ways to manage things in the cloud or on-premises and the operational cost is high.

    I’m not sure it exceeds any licensing cost or the cost of limiting what platforms developers can use. I would argue only allowing 1-2 platforms just makes you more efficient and your staff more effective.

    However.

    That’s not the world. Even if I mandated that, often some external even changes my world. Companies get bought and integrated. New COTS software is needed, and it will, of course, run only on a database platform we don’t run.

    There’s a serious operational cost to adding new platforms that few consider. Even if they did, I’m not sure anything would change.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.
  • PostgreSQL Support in the Data API Builder

    Next week I’m at VS Live in San Diego (register and join me) and one of my talks is on the Data API Builder. I want to show how this gives you REST, GRAPHQL, and MCP access. As a part of the talk, I also wanted to show this working across platforms, so I’m showing this in PostgreSQL as well.

    I’ve been experimenting this in a few ways, but I decided to see how hard it was to add PostgreSQL support. I decided to follow a similar structure as my SQL Server demos, which are all in my GitHub repo.

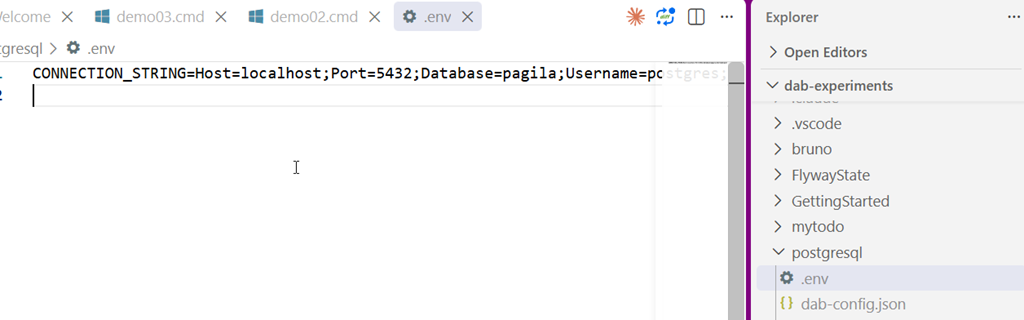
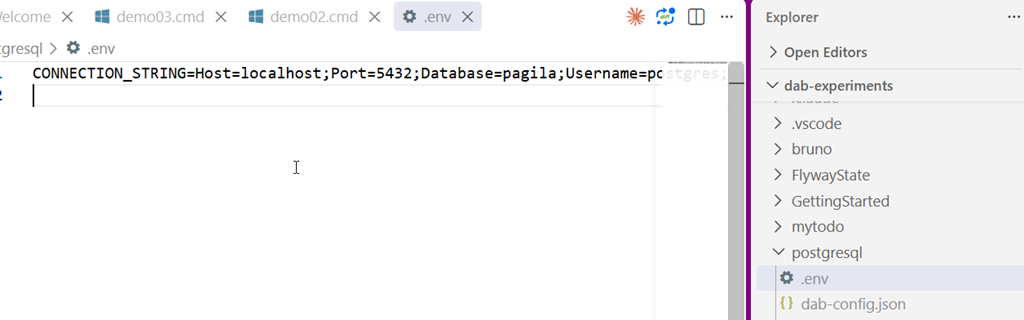
    First, I added a .env file, which has the credentials. THIS IS A DEVELOPMENT structure, and not something you’d deploy from a repo. Secure your production stuff! This is my local file (in .gitignore), but it’s a simple connection string.

    2026-08_0375

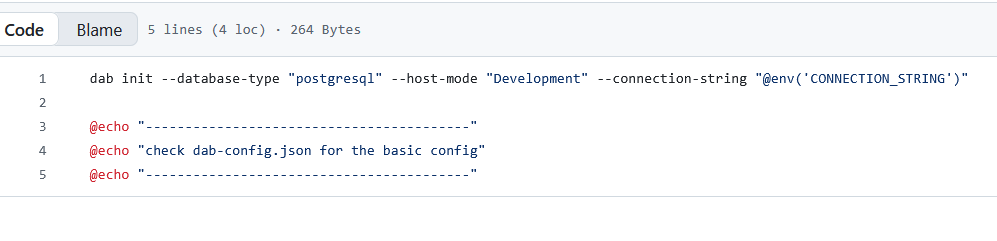
    Next, I copied (well, I guided Claude to do this)  my demo01.cmd and edited it to say the type is “postgresql” instead of SQL Server. The new file went into a separate folder as (demo01.cmd)

    2026-08_0375

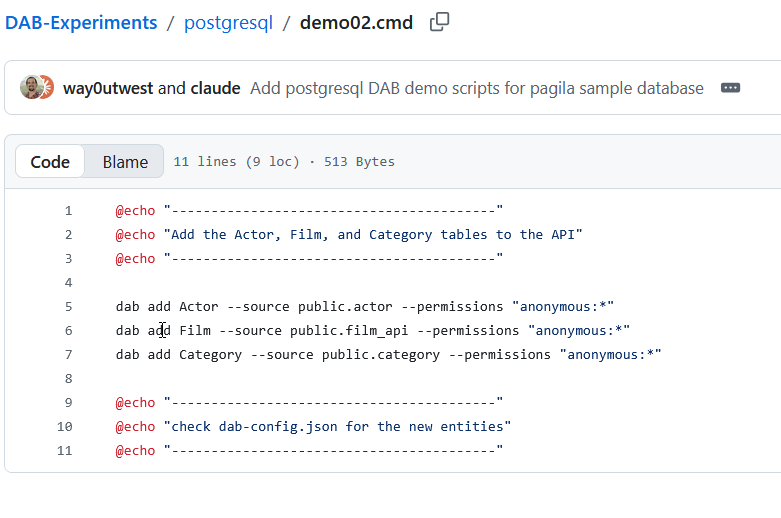
    I had it copy the demo02.cmd and alter this for the PostgreSQL Pagila sample db, which is installed and running on my machine.

    2026-08_0376

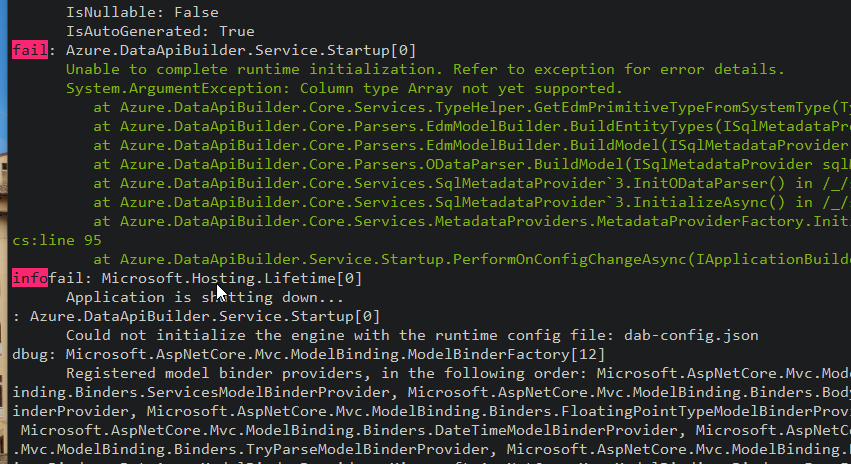
    Note, this errored out at first, with the note that DAB doesn’t support the PostgreSQL array type. I ended up having Claude create a view that skips this column and the column that is a vector type. Hopefully those will be supported soon by DAB.

    2026-08_0373

    Next, dab start, and I had a running API server over my PostgreSQL database in just a few minutes. Here’s my Bruno query of the GraphQL endpoint for Pagila.

    2026-08_0377

    Not enough people are using or trying the Data API Builder. This is truly an easy way to get a usable API over your database without a lot of data access layer work for developers.

  • T-SQL Tuesday #202: 100 Hours

    It’s time for T-SQL Tuesday again and this is a great prompt to start writing. I might have written about this before, but it’s a story that sticks with me. It’s a memorable one, and it was quite the outage, one that lasted for weeks.

    Thanks to Marlon for this invite on unforgettable outages..

    T-SQL Tuesday is the monthly blog party, and if you want to participate, feel free to write on a blog, Linked In, or anywhere else and link your post to the invite. If you’d like to host, ping me. You need to write an invite and a recap. I’m always looking for people to host, so jump in and join the party.

    New Year’s Eve

    I was a relatively new hire, a former intern, at a large electrical utility in Virginia. I worked as a network admin at a nuclear power plant in Surrey, VA. I showed up at work on New Year’s Eve at 5:00pm. We were planning on deploying a new database server running SQL Server, along with a new application to track radiation exposure for workers. This was a mandated change to our tracking, which needed to go live at midnight. I was supposed to be a bystander, helping developers from our internal group implement the server and then take over administration for the future.

    New hardware had arrived, and we had installed OS/2 1.3 already. This was the “hot” new OS to us and to the plant, which would run SQL Server 4.2, a real database. Instead of the previous BTrieve database on our Novell network. The developers installed SQL Server, showed us how to add logins and users, and we verified this was running. The devs then went into the plant (with escorts) to install their software on various machines with radiation badge readers. These machines were the “clients” that connected to the new database server to look up user names, verify their total exposure, and record new exposures.

    We finished installations well before midnight and then went to eat some food. At midnight, we turned the old system off, and the new one went live. This was accomplished by stopping one application on the client machines and running a new one. A nuclear plant is busy, with people constantly moving in and out of spaces where they could be exposed outside the reactor. We saw workers getting badges, logging the device to their account and then entering the plant. Quick and easy.

    After 30 minutes or so, some workers would return from the plant, run the app, log in and have their badge scanned, recording their exposure. Many were 0 rads, but a few might have picked up minor exposure.

    Then the crash. Once we started getting a little busy, with 5 or so people logging in the application stopped responding. I worked with the devs in the server room, where we saw the new OS/2 server hung. We rebooted it, thinking something went wrong.

    This happened again.

    And again, and again.

    We ended up seeing either the entire server hung, or SQL Server not accepting connections. In the v4.2 version, we didn’t have a Dedicated Administrator Connection, when the server was hung, we could only see external, OS-level counters. Our network staff (4 of us) stayed until around 4am, at which point my boss sent a few people home. They had families, so he and I remained behind. We alternately caught naps and were on call to reboot the server. Sometime during the morning the plant rolled most people back to paper, manually tracking workers and exposure on cards, one per worker. We kept one machine on to keep testing. That worked, but when a second client was added, the server kept hanging.

    My boss and I stayed, trying all our tricks, reading lots of OS/2 and SQL Server  docs, and trying to help developers figure things out. The plant wasn’t that busy on Jan 1, but busy enough that their system kept freezing up. Lots of arguments amongst our staff, our managers, and the software development group. I stayed overnight, rebooting servers, napping in the server room (a cold room) with a hat and coat. When the “normal” day started on Jan 2 and coworkers showed up, I went home.

    I returned late afternoon to relieve the other staff, working through the night again, mostly rebooting a server and trying to find a cause. I learned about the “probe” user, which was a backdoor account used for accessing data. I never found a reason why the application didn’t work as expected, other than the developers didn’t really test with multiple clients.

    In any case, it didn’t matter. I worked 100 hours that week, from Dec 31-Jan  6. Since I was being paid hourly, I was happy to do so. My partner, less happy.  I continued working over 80 hours every week that month. The developers stabilized things enough for the system to be used, but it still was rebooted every few hours. Since the plant runs 24×7, that meant the 5 or 6 of us needed to ensure someone was there all night long.

    A profitable month (and the next), but a hard one.And an unforgettable outage.

  • Labor Day 2026: Fun on the Ranch

    It’s Labor Day in the US and I’m not working. Not for Redgate, at least. I’m not even traveling today, which is something that happens all too often on holidays.

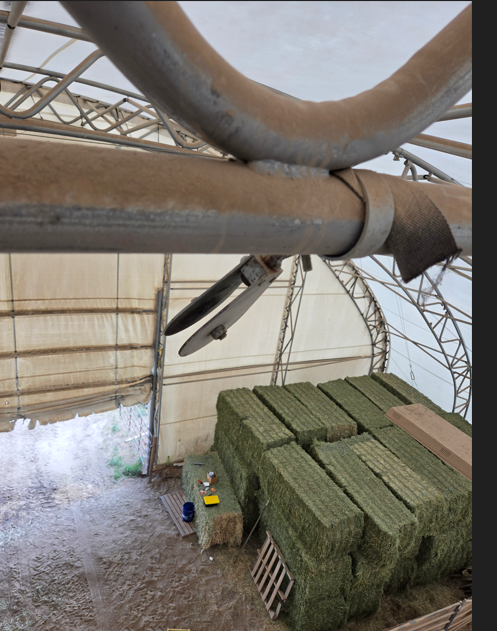
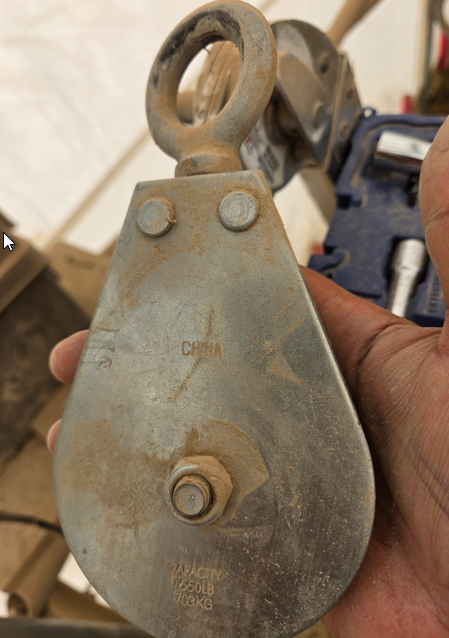
    Today I’m going to be working on the ranch, catching up on a few things. I was up in the air last week, trying to replace a pulley. The bolt in this pulley sheared off. Both ends and the nuts were still there, somewhat rusted to the side. The wheel and middle were on the ground.

    2026-08_0307

    This lasted 15 years, which is good. Bad that this was 30ft in the air at the top of a building. And I was it Scotland when it broke.

    2026-08_0338

    My daughter secure the door, so she could get hay out. I had to rent a lift last week as this couldn’t wait until Labor Day. We had a spare and I ordered another one as well. I got up in the air and unbolted this and replaced it with a new one.

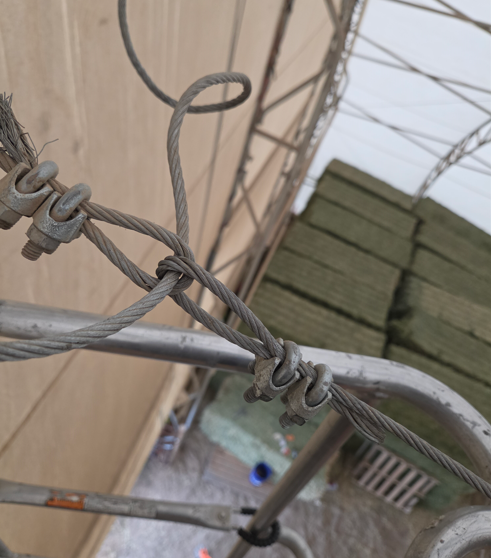
    While I was up there, I took the opportunity to replace the lifting cable. This had broken near the bottom a few years ago and I added a new section, but it didn’t go up and down smoothly. Since I had the lift, I was up here, undoing the stays for the cable on the left and then running it down 30ft to the bottom of the door.

    2026-08_0308

    My daughter had noticed part of the upper cable was also worn, so I ended up replacing that since I had the lift. My wife also asked that we tighten down the straps on this end of the building, as they were looser than others. We replaced the roof last year, and if you want to see part of this, I have a video of us pulling this section over the frame.

    It was a long, hard 24 hours of having the lift and being up in the air for 8-9 hours while working on a Saturday afternoon and Sunday morning.

    I’m sure I have something else in store for today just as hard. It’s a wild life for a database professional who lives on a ranch.