Tag: security

  • The #MS_DatabaseConnector## Role: #SQLNewBlogger

    I had seen these roles in various instances, but never dug into the new Fixed Server roles added to SQL Server. They are supposed to help ensure the principle of least privilege is followed.

    In this post, I look at one of these, the ##MSDatabaseConnector## role.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    Users and Logins

    This role is a new one that contains very narrow permissions. It allows a login to connect to any database without requiring a user account mapping. Typically if I create a login for “Steve”, I also create a User in a database that maps here. The convention for most people is to create a user “Steve” that links to the login “Steve”. Typically this is with code like:

    CREATE LOGIN [Steve]
    WITH PASSWORD = N'asdfasdf' MUST_CHANGE,
         DEFAULT_DATABASE = [master],
         CHECK_EXPIRATION = ON,
         CHECK_POLICY = ON;
    GO
    USE [sandbox];
    GO
    USE [Westwind];
    GO
    USE [AdventureWorks];
    GO
    CREATE USER [Steve] FOR LOGIN [Steve];

    NOTE: This isn’t the real password.

    Note 2: Don’t use passwords like this

    NOTE 3: Don’t skip the checks.

    Here I am mapping a user to a login, and while the name is the same, these are different objects. If I want the user, Steve, to have access to objects in AdventureWorks, I need to grant rights, or add the user to a Role.

    I could also do this:

    USE [sandbox] GO CREATE USER [Stephan] FOR LOGIN [Steve] GO


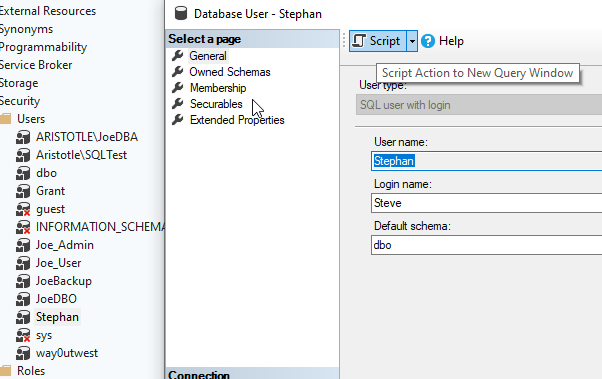
    In the Sandbox database, there is no User Steve. Instead, you can see below from SSMS that there is a different user here. My database has no “Steve” in the users, but “Stephan” is mapped to the login Steve.
    2026-09_0090

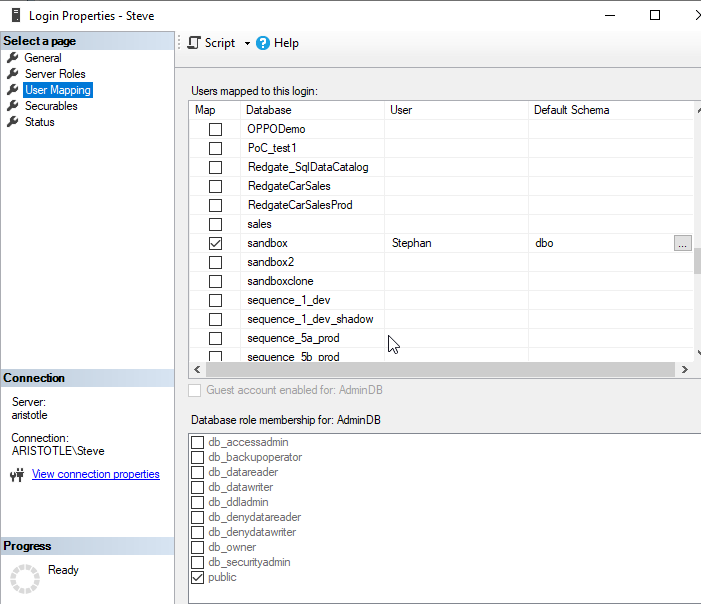
    The Login properties shows this as well.
    2026-09_0091

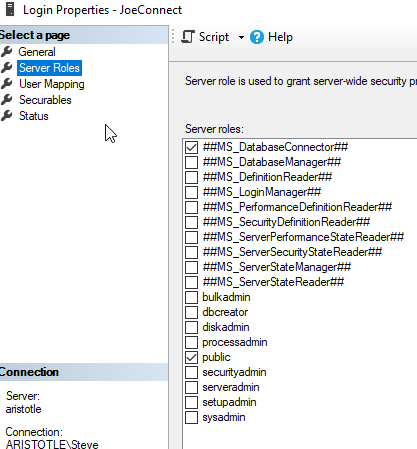
    I added a new user with this fixed server role, and no other database mappings. Here is the server role:
    2026-09_0093

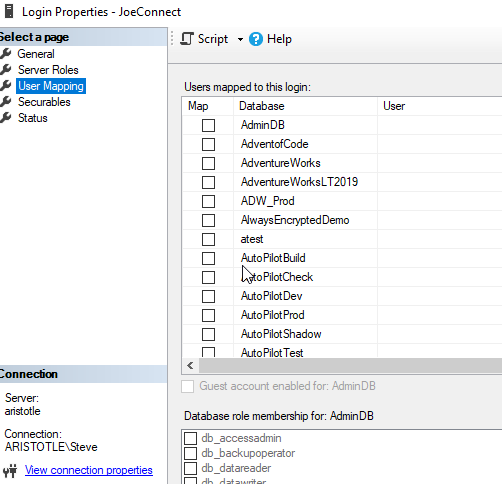
    And the user mappings (trust me these are all blank)
    2026-09_0094

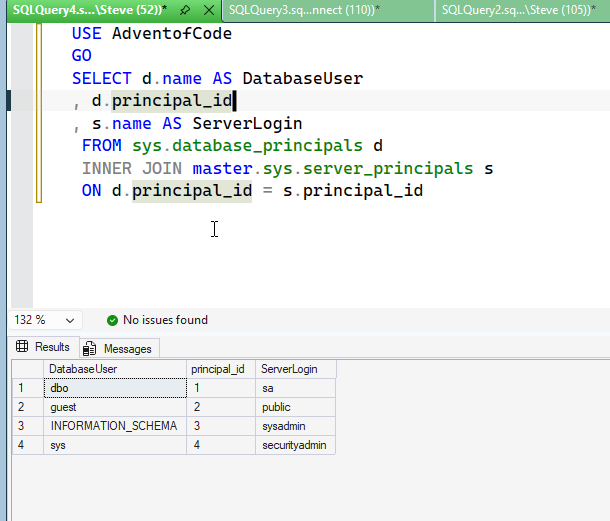
    I then logged in with this user to the AdventofCode database. As you can see, there are no users here for this login.
    2026-09_0095

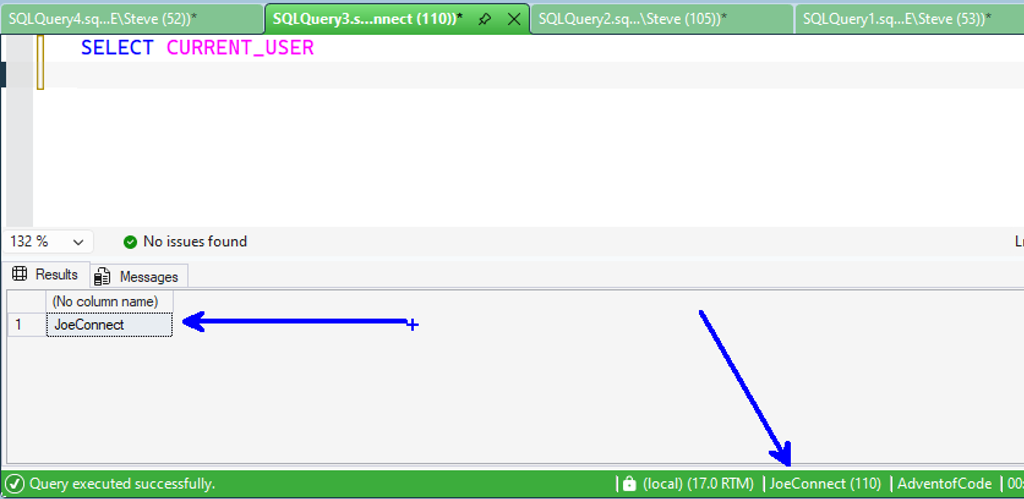
    The login can connect, however, and I see the current user as the login name.
    2026-09_0097

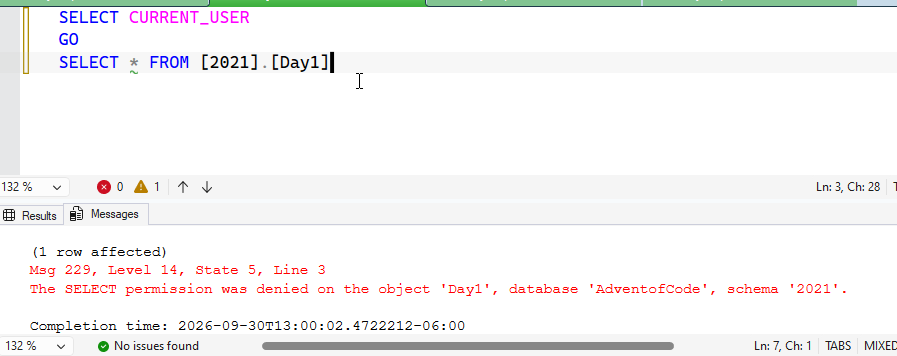
    What can the user do? Well, he can’t access this table, 2021.Day1.
    2026-09_0098

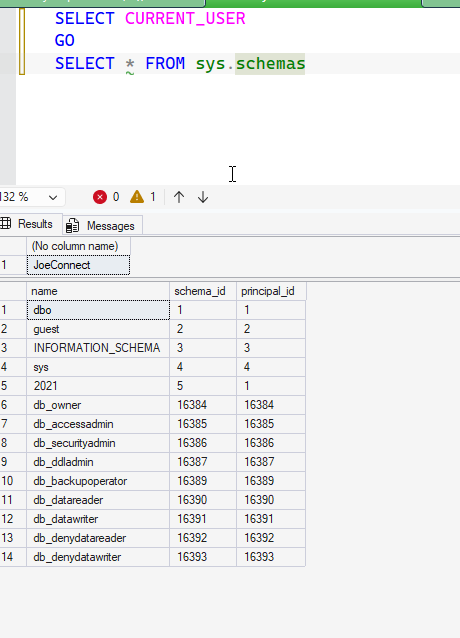
    He can access schemas, which I saw with SQL Prompt Intellisense. That makes sense as the sys.schemas dmv is open to the public.
    2026-09_0099

    I granted rights to public for one table.
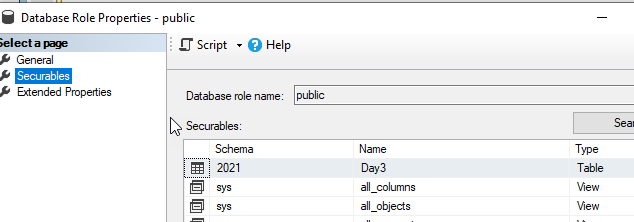
    2026-09_0100

    The login (or user with public) can query this.
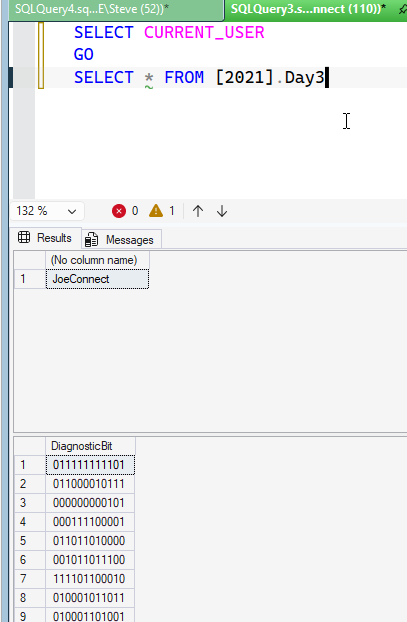
    2026-09_0112

    If I check permissions for the login, I don’t see anything in the database other than basic things: connect, view CEK, view DMK.
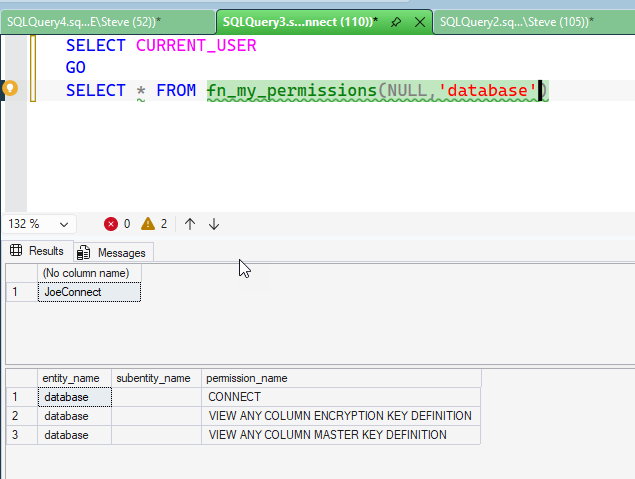
    2026-09_0113

    This is interesting. It’s like a pseudo-user has been created for this session, mapped to the login. I’m not sure if this is correct or intended, but it’s what I’ve observed.

    I don’t know how useful this permission is, though I’m sure someone has a use case where they want something like a monitoring system, or maybe a pen-test available to check what a public user can see in every database.

    SQL New Blogger

    While I was investigating this role, over the course of testing a few things in 10-15 minutes, I sketched this post. I then spent another 20 minutes capturing some code and screenshots to see how things work.

    This is a good post of evaluating how things work and better understanding the system. I could use this as guidance, and perhaps tell an AI whether this role is useful or not. Or to avoid it.

    Write your own post, maybe even using AI to help you learn about this role or others. Those skills will help you in the future and you can showcase them for others.
  • AI Is Improving Security

    I was updating the SQL Server build lists the other day. I typically get a notification from Microsoft when new builds are released. This is something that happens every month as a new CU appears. For SQL Server 2022, we get a CU every other month since it’s still in mainstream support. Older versions just get these security patches. Since SQL Server 2025 is new, we’re getting a CU a month, which will slow down next year. However, I’ve also seen this for most versions:

    • Oct 2026 – GDR
    • Sep 2026 – GDR
    • Jul 2026 – GDR
    • May 2026 – GDR
    • Apr 2026 – GDR
    • Mar 2026 – GDR

    That’s a lot of out-of-band patches. In the last decade of SQL Server, there have been relatively few GDRs. Often the main CU comes a day or two later (or a month later for older versions). If you react and start to plan patching, you might find yourself trying to decide if you apply CU9+GDR or wait for CU10, or do both.

    There have been few GDRs in the last , but before that, relatively few: three in 2025, two in 2024, and two in 2023. I suspect that AI is being used to discover bugs in existing software, and this is forcing Microsoft to perform remediation work. Brent posted a similar thing, noticing a large number of security fixes and speculating that AI is finding issues.

    That’s good, right?

    Or is it? If Microsoft can find security issues, can’t malicious actors? Including nation-state-sponsored hackers? I’m not even sure that Microsoft is finding most of these, as there are lots of CVE issues, which can be discovered by anyone and sent to Microsoft. This might be to obtain a bug bounty payment, as Microsoft and other vendors will pay security researchers.

    Or it could be that a hacker finds an issue and exploits it. A customer then notices an issue and reports a problem to support. Microsoft realizes there is a vulnerability, works on a fix and reports the issue to the CVE database.

    AI is great for security, as it can scan software and look for known issues. We have decades of security bugs that have to be included in the frontier LLM training, so using AI to scan your code is a good idea. I am sure code scanning tools are adding AI review to their systems. I’m also sure those vendors are worried you’ll use AI on your own to scan code and find your own issues.

    You can do that, but ensuring your AI does a good job scanning isn’t necessarily easy. Or fast. Deterministic systems, like SonarQube and Flyway can find code issues quickly, in a deterministic fashion, and likely with less cost than AI. That’s not to say AI doesn’t have a place, but it’s likely an out-of-pipeline review that takes place less often than every CI build.

    Security is a constant battle, and it’s hard. The age of AI makes it easier and harder (and more expensive) to manage security, but I think that’s a good thing. We’re seeing lots of vulnerabilities, but also more patches. Perhaps the better outcome is that there is more awareness and focus on security from vendors who now know if they don’t scan their code carefully, someone else will. Perhaps someone they don’t want finding issues.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.

  • Smart AI Agents and Data Security

    I don’t know if Anthropic, OpenAI, or Google have really spent a lot of time and effort on security around their models. I know they talk about it (Anthropic, OpenAI, Google), but in practice, I’m not sure the researchers and testers are being as careful as the marketing and management of those companies want you to think.

    Gemini broke into three companies during a security test. Claude escaped a test environment and breached three organizations. OpenAI had breaches of Hugging Face and other sites, so perhaps this is the most powerful model, as it exceeded the “rule of three.” In all these cases, the agents weren’t doing anything amazing. These were acting the same as most malicious or bored human hackers who might find or guess credentials and take advantage of them. In some sense, this points to the generally poor state of security in the world.

    On the other hand, it could be that these high-tech organizations aren’t equipped to secure systems from the rapid, capable digital fingers of agents powered by a model. If they can’t, then to what extent can we be expected to secure internal AI agents in our organizations?

    For those of us who secure and manage data assets, do we think that our systems are well secured? Do we think our legitimate users, to whom we’ve granted access, are securing their credentials? What is the likelihood that we’ll have an internal breach from an agent that’s asked to find some data and discovers a) unsecured credentials in a file or repo, b) finds production data it can access in a non-production, less secure system, c) a backup of a database not protected that the agent can restore, or d) some other hole?

    I do think AI has a lot of potential, but it operates in a somewhat slapdash, reckless fashion. I’m not convinced most vendors (or models or software incorporating AI) will provide robust and comprehensive security controls. Even if they do, how many of us will know how to implement them well? Heck, we see developers and DBAs mess up SQL Server security on a regular basis, and I think that’s a simple system to configure.

    I’m excited by AI and also terrified of the possibilities.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.

  • Differences Between xp_readerrolog and sp_readerrorlog: #SQLNewBlogger

    I was creating a question on sp_readerrorlog and realized that this procedure is different from the one it wraps: xp_readerrorlog. This post digs into a few differences.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    The New System Stored Procedure

    For most of my SQL Server career, it’s been a habit to use xp_readerrorlog to query the log. This was code I learned a lot time ago, and it’s worked in every version of SQL Server. Despite being undocumented, as you can see below:

    2026-08_0381

    xp_readerrorlog has been written up by a few people at SQL Server Central, including Nagaraj Venkatesan and Ken Fisher, as well as in some forum posts (one, two). However, it’s not well documented. I usually end up Googling for the parameters as I need them.

    Until now.

    Here are a few differences I’m documenting, so I will hopefully remember them.

    Note: I got a few different results from AI, which were at best incomplete, and sometimes wrong.

    sp_readerrorlog has different permissions. This proc works with anyone that has VIEW SERVER STATE, which is sysadmin, serveradmin, and security admin.  Or with the permission granted.

    xp_readerrlog has extra parameters. Both of them have these parameters:

    1. error log number (0 based)
    2. error log type, 1 – SQL Server, 2 Agent
    3. search value – needs to be NVARCHAR
    4. second search value, NVARCHAR as well

    xp_errorlog adds 5 and 6, and 7.

    1. start time (datetime)
    2. end time (datetime)
    3. sort order (ASC,DESC)

    Those are the main differences I see, and if you want to filter or sort, you need the extended stored procedure, not the wrapper.

    I also learned to be careful of AI, as some of the data wasn’t correct from Google or Claude, so I need to verify what I get back and test how things work.

    SQL New Blogger

    I was investigating something and noticed a difference. This post was about 15 minutes to write, along with some testing of the parameters to verify what worked and what didn’t. That testing will make future posts quicker, as I’ll reuse some code.

    This is a quick example of showing some knowledge, and including the warnings about AI. You can write this post and give someone confidence you’re a good choice for the next person to manage their database servers.